In order to remain competitive in the market, our company has been keeping researching and developing of the new GH-600 exam questions. We are focused on offering the most comprehensive GH-600 study materials which cover all official tests. Now, we have launched some popular GH-600 training prep to meet your demands. And you will find the quality of the GH-600 learning quiz is the first-class and it is very convenient to download it.
| Section | Weight | Objectives |
|---|---|---|
| Perform evaluation, error analysis, and tuning | 15-20% | - Evaluate agent performance
|
| Prepare agent architecture and SDLC processes | 15-20% | - Define boundaries between planning, reasoning, and action
|
| Manage memory, state, and execution | 10-15% | - Control execution flow
|
| Implement tool use and environment interaction | 20-25% | - Manage execution environments
|
| Orchestrate multi-agent coordination | 15-20% | - Coordinate multiple agents
|
| Implement guardrails and accountability | 10-15% | - Implement governance controls
|
simulation tests of our GH-600 learning materials have the functions of timing and mocking exams, which will allow you to adapt to the exam environment in advance and it will be of great benefit for subsequent exams. After you complete the learning task, the system of our GH-600 test prep will generate statistical reports based on your performance so that you can identify your weaknesses and conduct targeted training and develop your own learning plan. For the complex part of our GH-600 Exam Question, you may be too cumbersome, but our system has explained and analyzed this according to the actual situation to eliminate your doubts and make you learn better.
NEW QUESTION # 53 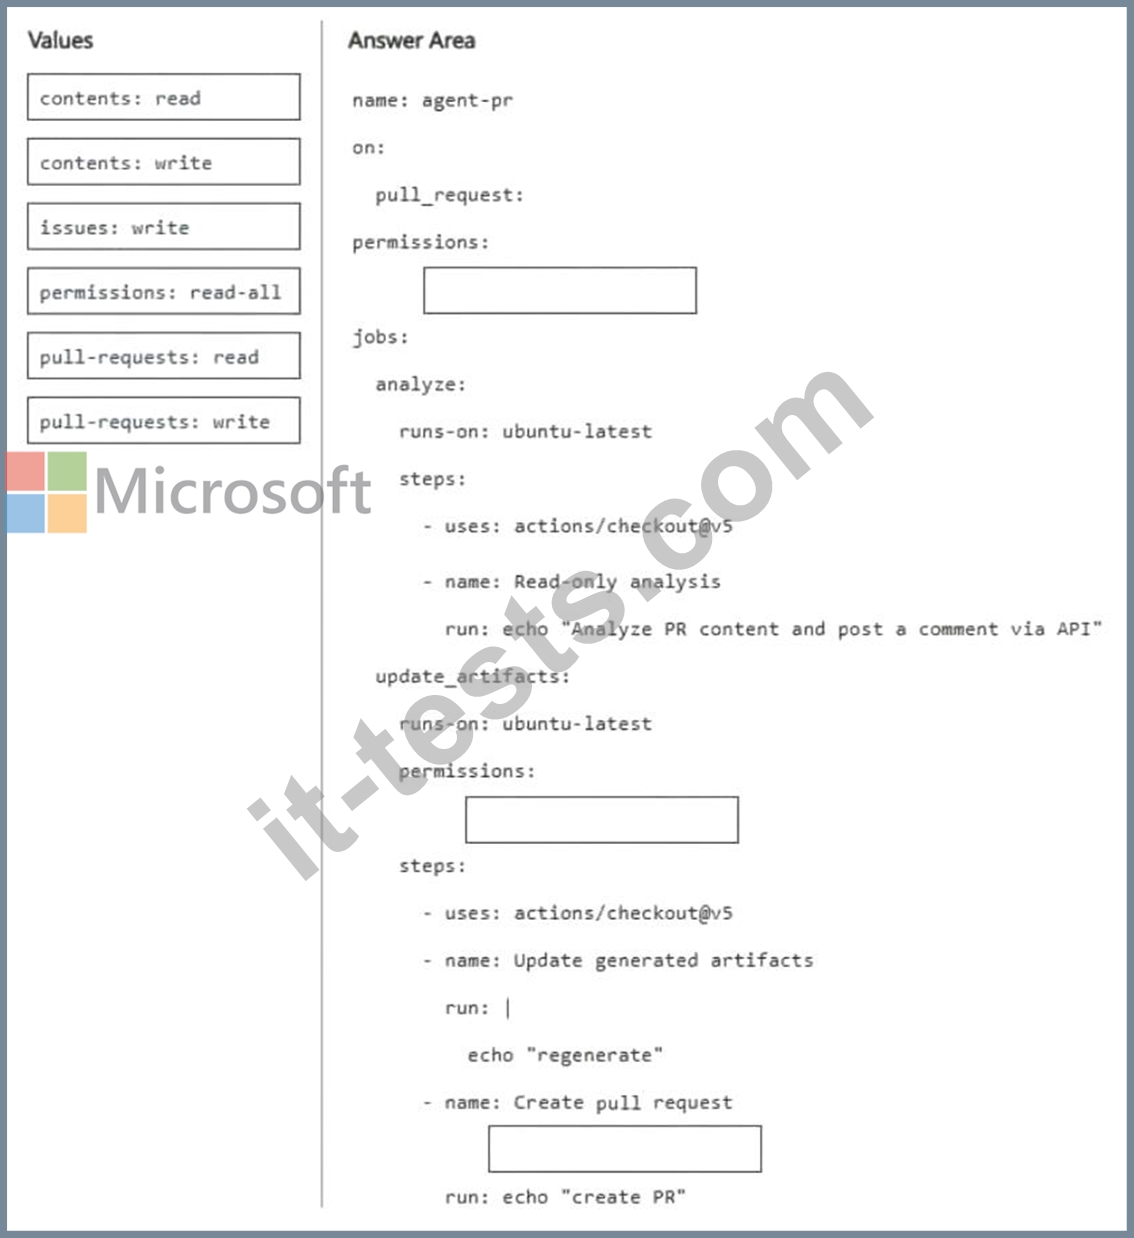
Answer:
Explanation: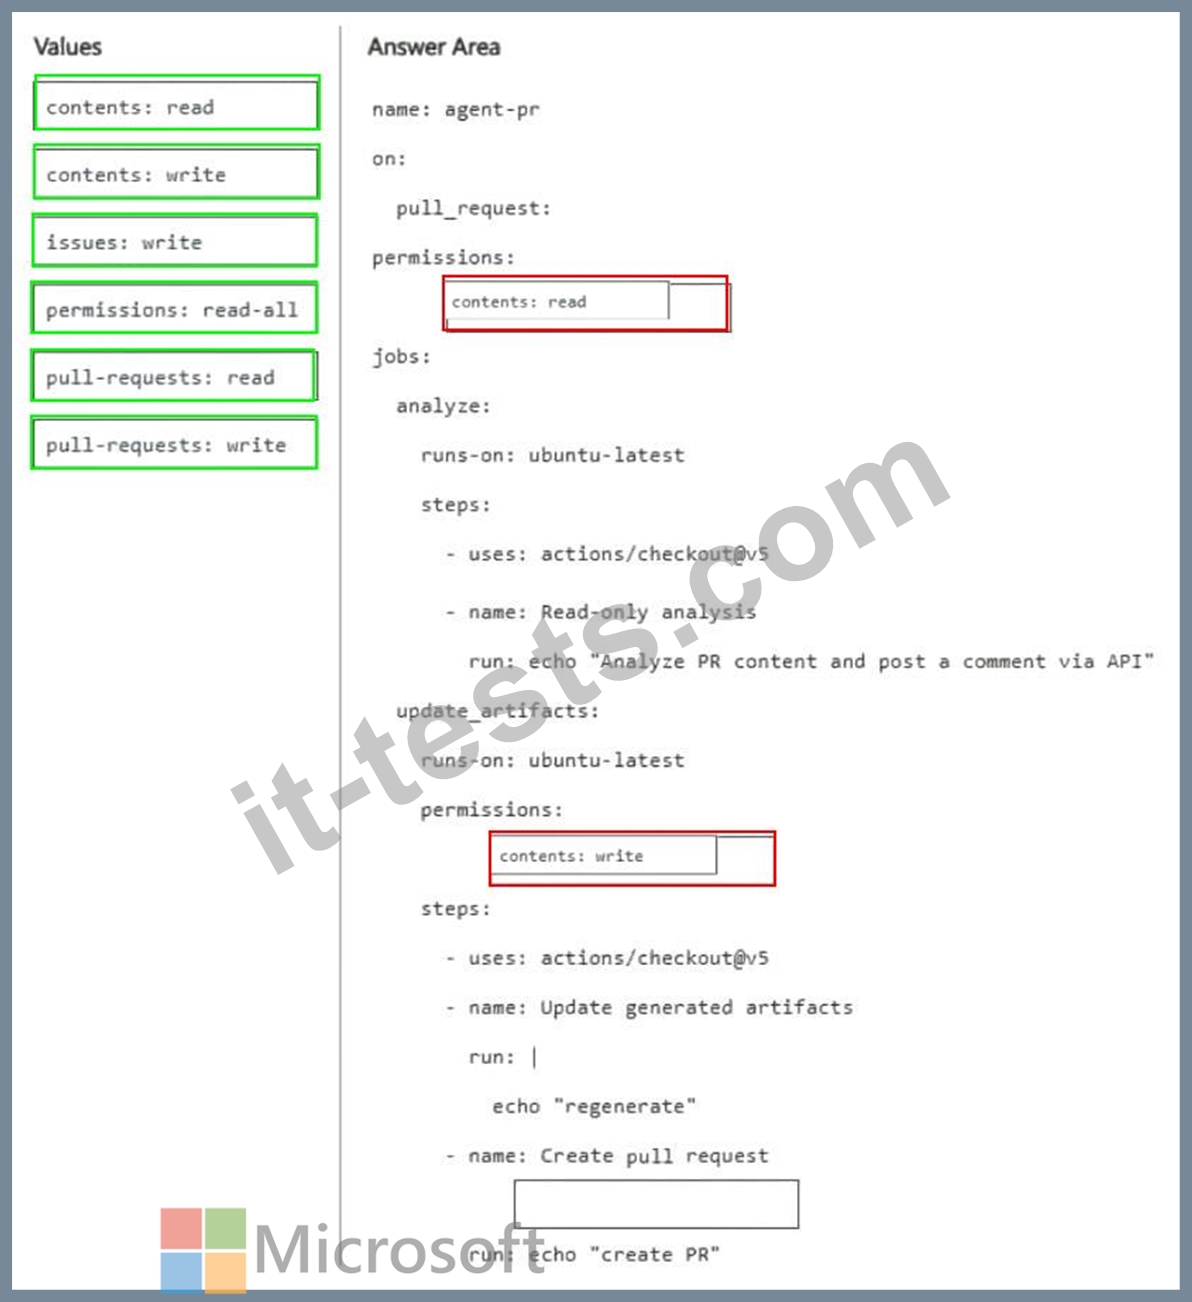
NEW QUESTION # 54
Drag and Drop Question
You have a GitHub Enterprise Cloud Organization that uses the GitHub Copilot coding agent to resolve issues asynchronously.
When an issue is assigned to GitHub Copilot, the agent creates a draft pull request, but your team cannot always tell whether the agent is actively working, has completed its session, or is awaiting workflow approval.
Which execution context does each signal indicate? To answer, drag the appropriate context to the correct signals. Each signal may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.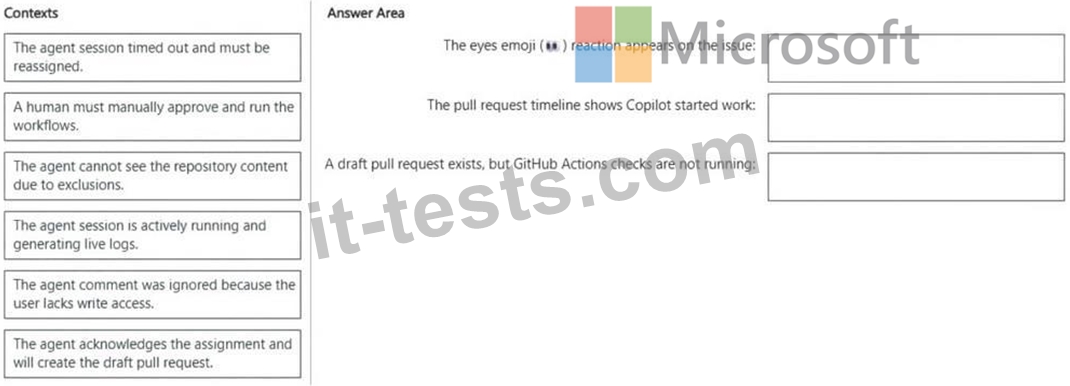
Answer:
Explanation: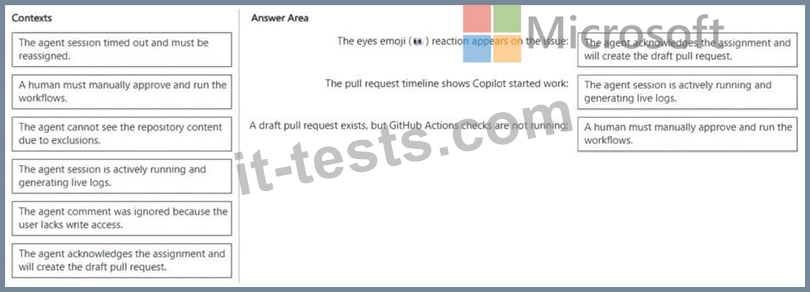
Explanation:
Box 1: The agent acknowledges the assignment and will create the draft pull request.
When an issue is assigned to the GitHub Copilot coding agent, the eyes emoji reaction indicates that the agent has acknowledged the task and is actively starting work in the background.
Box 2: The agent session is actively running and generating live logs.
The signal indicating that "the pull request timeline shows Copilot started work" means that the agent session is actively running and generating live logs.
When a pull request timeline shows that Copilot started work, it indicates that the execution context is actively working.
Actively working: Indicated when the pull request timeline explicitly logs that Copilot started work or updates the PR body with a list of in-progress sub-tasks.
Box 3: A human must manually approve and run the workflow.
When a draft pull request exists but GitHub Actions checks are not running, it indicates that the execution context is awaiting workflow approval.
Reference:
https://docs.github.com/en/copilot/how-tos/copilot-on-github/use-copilot-agents/kick-off-a-task
NEW QUESTION # 55
You are about to start a complex refactoring task in the GitHub Copilot CLI.
Before Copilot makes any changes, you need to review and agree on the approach.
What should you do first?
Answer: C
Explanation:
The first action you should take is to switch to Agent mode or use the Plan agent to review, edit, and approve a detailed step-by-step Markdown plan before any code is modified.
Use the Plan Agent: If available in your environment, trigger the plan phase so Copilot scans your codebase in a read-only state to outline its entire approach first.
Review the Proposed Plan: Carefully inspect the resulting Markdown structure to catch any architectural issues or wrong directions before the "doing" phase begins.
Utilize edit Mode Intentionally: Alternatively, if you prefer granular control over file adjustments rather than a fully autonomous agent workflow, opt for edit mode. This allows you to specifically select the target files and describe the natural language updates manually.
Reference:
https://aidevme.com/think-before-you-build-github-copilots-plan-agent-in-visual-studio-structured-ai-assisted-development/
NEW QUESTION # 56
You have a GitHub repository that uses three GitHub Copilot coding agents named agent1, agent2, and agent3.
During structured evaluation runs, agent1 frequently returns Markdown narratives instead of a machine-parsable result.
You need to ensure that agent1 consistently returns only a predefined JSON structure without affecting the output of the other agents.
Which file should you modify?
Answer: B
Explanation:
The required change concerns one agent's behavior, making its custom agent profile the appropriate scope. The file .github/agents/agent1.agent.md defines instructions for agent1. Its Markdown instruction body can specify the required JSON structure, mandatory properties, allowed values, and prohibition of explanatory prose or Markdown fences.
Repository-wide instructions apply more broadly and could alter the behavior of agent2 and agent3, contrary to the requirement. The setup workflow prepares the execution environment rather than defining the agent's response contract. A file under .github/instructions uses instruction applicability rules; naming it after an agent does not automatically bind it exclusively to that agent.
The evaluation finding should be converted into a precise behavioral requirement and tested against representative inputs. For example, checks should distinguish valid JSON from text containing a JSON fragment and should reject missing fields or unexpected properties.
An agent instruction improves adherence but is not a mathematical guarantee of schema compliance. Production consumers should validate the returned object before using it. Relevant curriculum topics are revising instructions based on evaluation results and specifying expected output constraints.
Reference:
NEW QUESTION # 57
You have a GitHub Copilot coding agent named Orchestrator that runs a multi-phase workflow by using the following subagents:
- Explorer gathers context by using read-only tools.
- Modifier applies focused edits.
You are adding a new agent named Summarizer that generates a concise summary after modifications are complete. Summarizer includes the following YAML frontmatter.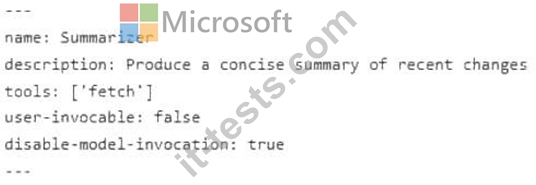
The Orchestrator agent lists all three agents in its agents property.
After adding the Summarizer agent, Orchestrator successfully runs Explorer and Modifier but fails to run Summarizer.
What is a possible cause of the failure?
Answer: B
Explanation:
The primary reason for this failure is the disable-model-invocation: true setting in the Summarizer's YAML frontmatter.In the GitHub Copilot Agent configuration framework, when an orchestrator agent automates a multi-agent workflow, it relies on the base LLM model to agentically trigger and delegate tasks to its subagents.
Blocks Subagent Delegation: Setting disable-model-invocation: true instructs GitHub Copilot to completely prevent the model from automatically invoking or calling this agent as a subagent.
Requires Manual Intervention: When this property is true, the agent can only be triggered via a direct manual request by the user (such as explicitly picking it from a chat menu or a slash command). Because user-invocable is also set to false, it becomes completely unreachable in this workflow.
Contradicts Orchestration: Even though Orchestrator explicitly registers Summarizer in its agents property, the underlying model respects the disable-model-invocation: true safety/routing block and refuses to spin up the subagent loop for it.
Reference:
https://docs.github.com/en/copilot/how-tos/copilot-sdk/features/custom-agents
NEW QUESTION # 58
......
It-Tests customizable practice exams (desktop and web-based) help students know and overcome their mistakes. The customizable Microsoft GH-600 practice test means that the users can set the GitHub Agentic AI Developer (GH-600) Dumps and time according to their needs so that they can feel the real-based GH-600 exam scenario and learn to handle the pressure.
GH-600 Free Vce Dumps: https://www.it-tests.com/GH-600.html