BONUS!!! Download part of PDFVCE DP-800 dumps for free: https://drive.google.com/open?id=1ylKHJQyXIvcDKNIIyZh5IPGQnbWI3w8z
If you are having the same challenging problem, do not worry, PDFVCE is here to help. Our direct and dependable Developing AI-Enabled Database Solutions Exam Questions in three formats will surely help you pass the Microsoft DP-800 Certification Exam. Because this is a defining moment in your career, do not undervalue the importance of our Microsoft DP-800 exam dumps.
| Section | Objectives |
|---|---|
| Monitor, troubleshoot, and maintain solutions | - Monitoring database health and performance - Troubleshooting data pipeline issues |
| Integrate AI capabilities with database systems | - Use Azure AI services with database workloads - Implement AI-assisted data processing |
| Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
>> DP-800 Reliable Exam Simulations <<
So rest assured that with the Developing AI-Enabled Database Solutions (DP-800) practice questions you will not only make the entire DP-800 exam dumps preparation process and enable you to perform well in the final Developing AI-Enabled Database Solutions (DP-800) certification exam with good scores. To provide you with the updated Microsoft DP-800 Exam Questions the Microsoft offers three months updated Developing AI-Enabled Database Solutions (DP-800) exam dumps download facility, Now you can download our updated DP-800 practice questions up to three months from the date of Developing AI-Enabled Database Solutions (DP-800) exam purchase.
NEW QUESTION # 66
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.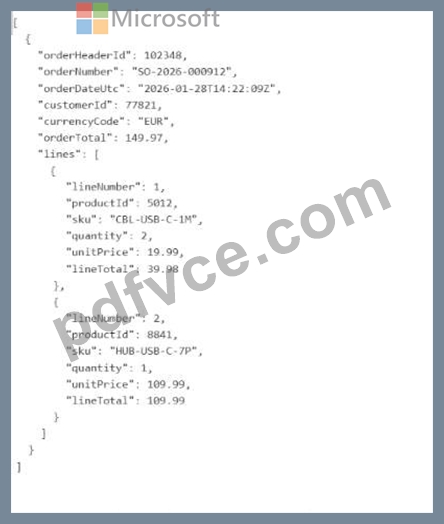
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.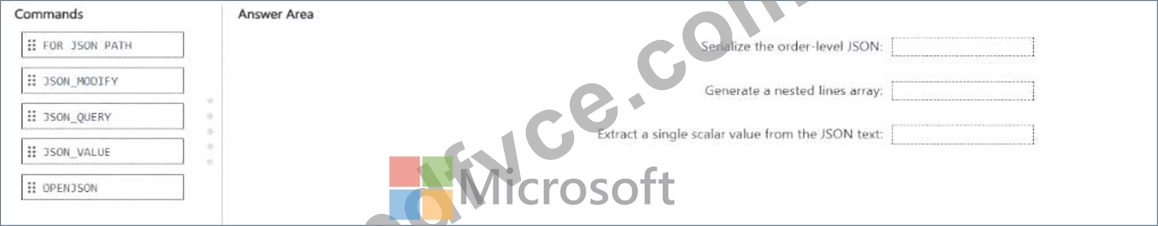
Answer:
Explanation: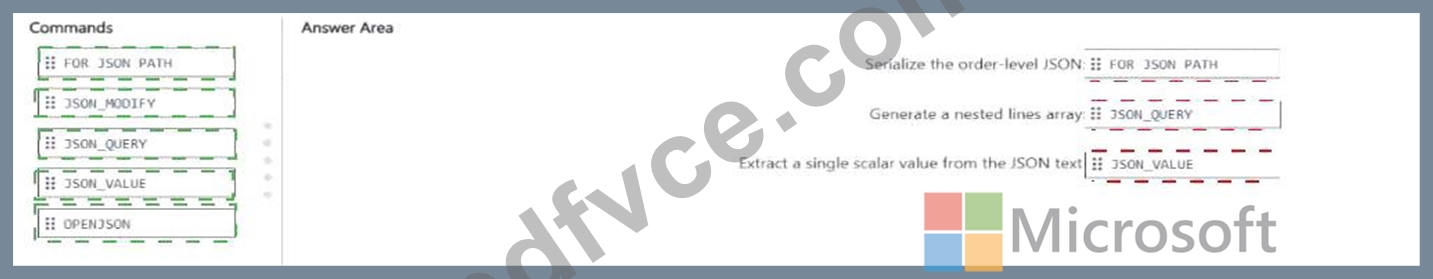
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 67
You have a GitHub Enterprise subscription.
Your team is developing an Azure SQL dataset solution from a locally cloned GitHub repository by using Microsoft Visual Studio Code and GitHub Copilot Chat.
A mix of GitHub Copilot instructions is configured at different levels, including organization-wide, repository- wide, agent-specific, and personal.
Based on the GitHub Copilot instruction precedence rules, which instructions will take precedence over the others?
Answer: C
NEW QUESTION # 68
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.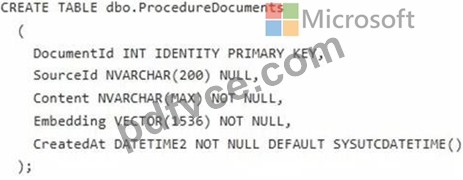
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.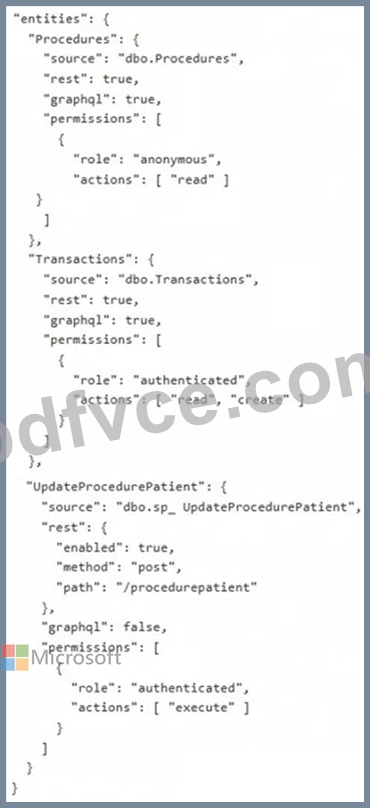
Hotspot Question
You create an SDK-style SQL database project in Microsoft Visual Studio Code named Database.sqlproj and add the project to a GitHub repository.
You need to configure a GitHub Actions workflow to support the planned changes for DB1.
How should you complete the workflow? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.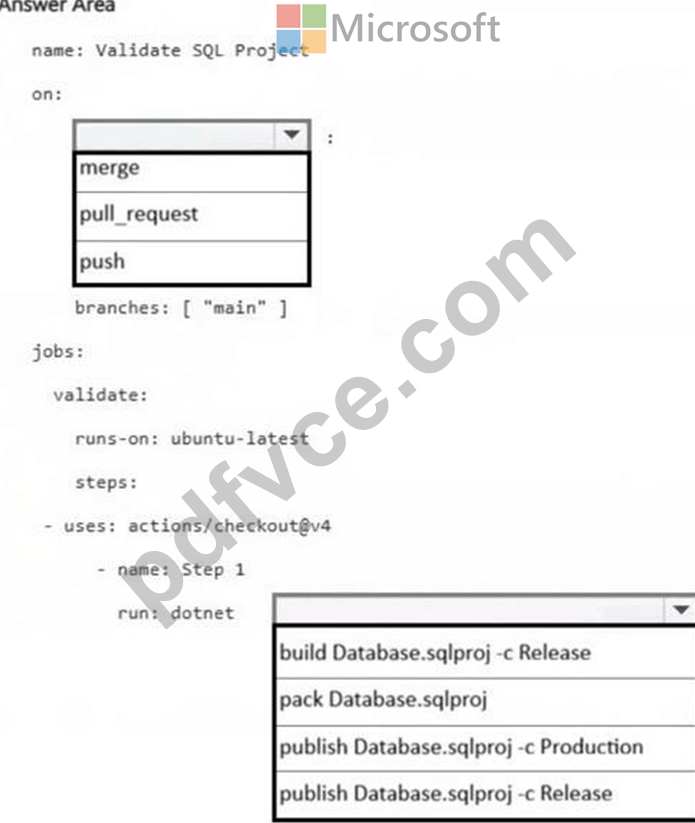
Answer:
Explanation: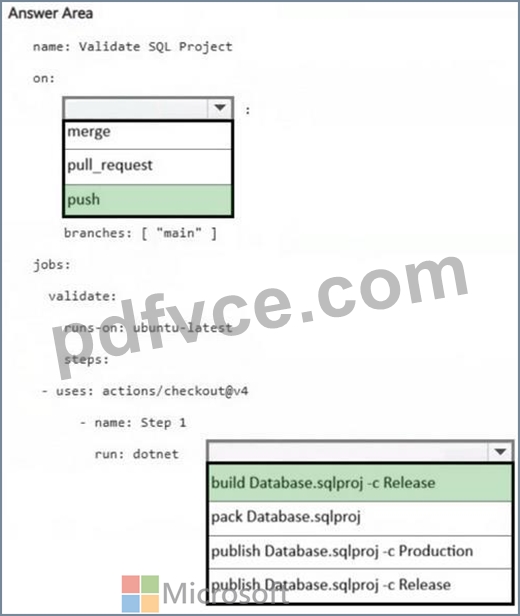
NEW QUESTION # 69
You have an Azure SQL table that contains the following data.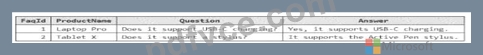
You need to retrieve data to be used as context for a large language model (LLM). The solution must minimize token usage.
Which formal should you use to send the data to the LLM?
Answer: B
Explanation:
The correct choice is Option A because it provides the relevant semantic context the LLM needs while avoiding an unnecessary field that would add tokens without improving answer quality.
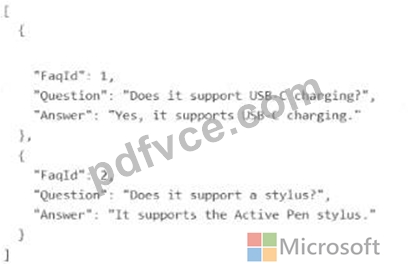
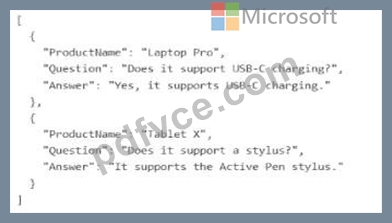
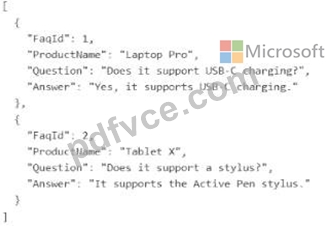
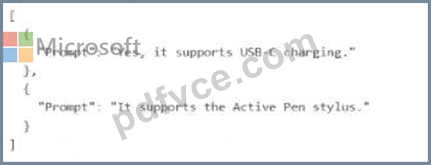
For LLM grounding and RAG-style context, Microsoft guidance emphasizes mapping and sending the fields that contain text pertinent to the use case . In this FAQ scenario, the useful context is the ProductName , the Question , and the Answer . Those three fields help the model understand both the subject domain and the actual Q & A pair. By contrast, FaqId is just a technical identifier and generally adds no semantic value for response generation, so including it wastes tokens.
That is why Option A is better than the others:
* Option A keeps the meaningful text fields and removes the low-value identifier.
* Option B is too minimal because it includes only the answer text as Prompt, which strips away the product and question context the LLM may need for accurate grounding.
* Option C keeps FaqId but omits ProductName, which can be important disambiguating context.
* Option D includes everything, but that does not minimize token usage because it keeps the unnecessary FaqId.
NEW QUESTION # 70
You have a database named DB1. The schema is stored in a Git repository as an SDK-style SQL database project.
You have a GitHub Actions workflow that already runs dotnet build and produces a database artifact.
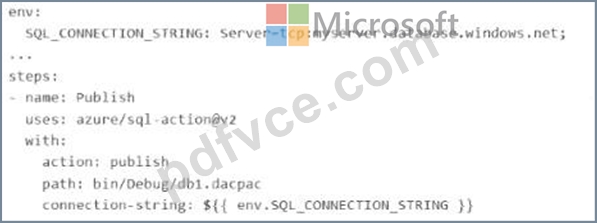
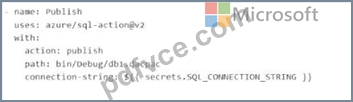
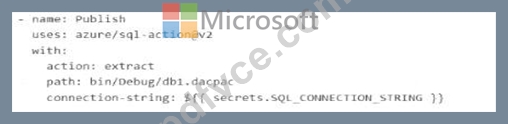
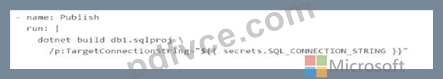
You need to add a deployment step that publishes the dacpac file to an Azure SQL database by using the secrets stored in GitHub repository secrets What should you include in the workflow?
Answer: B
Explanation:
The correct workflow step is Option C because it uses the Azure SQL GitHub Action to publish a .dacpac file and reads the connection string from GitHub repository secrets , which is exactly what the requirement asks for. Microsoft's Azure SQL GitHub Actions guidance shows using azure/sql-action@v2 with a connection string stored in secrets and a DACPAC path for deployment.
The key parts that make C correct are:
* uses: azure/sql-action@v2
* action: publish
* path: bin/Debug/db1.dacpac
* connection-string: ${{ secrets.SQL_CONNECTION_STRING }}
That matches the documented publish pattern for deploying a DACPAC to Azure SQL Database from GitHub Actions. Microsoft and the Azure SQL action documentation both describe Publish as the deployment action for applying a DACPAC to a target database, while Extract is used to create a DACPAC from an existing database, not deploy one.
Why the other options are incorrect:
* A uses an environment variable defined inline with a visible connection string rather than using GitHub repository secrets , which does not meet the requirement.
* B uses action: extract, which would create a DACPAC from a database instead of publishing the existing DACPAC artifact.
* D passes a target connection string to dotnet build, but the question says the workflow already runs dotnet build and produces a database artifact . The missing step is the deployment/publish step, not another build step. Microsoft's SQL project automation guidance separates build the DACPAC from publish the DACPAC .
NEW QUESTION # 71
......
In actuality, the test center around the material is organized flawlessly for self-review considering the way that the competitors who are working in Microsoft working conditions don't get the sufficient opportunity to go to classes for Developing AI-Enabled Database Solutions certification. Thusly, they need to go for self-study and get the right test material to fire scrutinizing up for the Developing AI-Enabled Database Solutions (DP-800) exam. By utilizing Microsoft DP-800 dumps, they shouldn't stress over any additional assistance with that.
100% DP-800 Correct Answers: https://www.pdfvce.com/Microsoft/DP-800-exam-pdf-dumps.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by PDFVCE: https://drive.google.com/open?id=1ylKHJQyXIvcDKNIIyZh5IPGQnbWI3w8z