Implementing Data Engineering Solutions Using Azure Databricks has introduced practice test (desktop and web-based) for the students so they can practice anytime in an easy way. The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice tests are customizable which means the students can set the time and questions according to their needs. The DP-750 Practice Tests have unlimited tries so that the users don't make extra mistakes when giving it the next time. Candidates can access the previously given tries from the history and avoid making mistakes in the final examination.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Prepare and process data | 30–35% | - Ingest and transform data
|
| Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
Many people want to be the competent people which can excel in the job in some area and be skillful in applying the knowledge to the practical working in some industry. But the thing is not so easy for them they need many efforts to achieve their goals. Passing the test DP-750 Certification can make them become that kind of people and if you are one of them buying our DP-750 study materials will help you pass the DP-750 test smoothly with few efforts needed.
NEW QUESTION # 62
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: D
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 63
You use Databricks Asset Bundles to manage two jobs and an app.
You need to deploy the bundle to development and production environments. The solution must meet the following requirements
* Deploy the app to both environments.
* Deploy only one job to development.
* Minimize administrative effort.
What should you use?
Answer: A
Explanation:
The correct answer is D - a targets node in databricks.yml.
Databricks Asset Bundles use a single databricks.yml to define all resources (jobs, apps, pipelines) once, and a targets node to define per-environment overrides. Within the development target, you can use the include
/exclude mechanism or resource-level overrides to deploy only one of the two jobs. The app and the second job are deployed to both environments through the shared resource definition.
Option B (separate databricks.yml files per environment) works technically but means duplicating the shared resource definitions across files - any change to a shared resource requires edits in multiple places, which is exactly the administrative overhead the question wants to avoid.
Option A (resources node) defines resources globally across all targets - it doesn't provide environment- specific filtering. Option C (variables node) parameterises values like cluster sizes or paths but doesn't control which resources are deployed to which environment.
Reference: https://learn.microsoft.com/en-us/azure/databricks/dev-tools/bundles/deployment-modes
NEW QUESTION # 64
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have 500 GB of sales data stored as multiple CSV files in cloud storage.
You plan to load the data into a Delta table.
You need to ingest the bulk data by using a solution that meets the following requirements:
* Minimize how long it takes to implement the solution.
* Minimize the amount of custom code required.
What should you use?
Answer: C
Explanation:
COPY INTO provides a concise SQL-based mechanism for loading files from cloud storage directly into a Delta table. It requires substantially less custom code than constructing a Spark ingestion application and is suitable for a straightforward bulk load of multiple CSV files. COPY INTO is also retryable and idempotent:
it tracks files already loaded into the target table and skips them during later executions, helping prevent accidental duplication. Auto Loader is optimized primarily for incremental and continuously arriving files and normally requires a streaming or triggered pipeline. Apache Spark read APIs require additional code for reading, transforming, tracking, and writing the files. Manually uploading 500 GB would be inefficient and operationally unsuitable. Therefore, COPY INTO best satisfies both implementation-speed and minimal-code requirements. Microsoft Learn
NEW QUESTION # 65
You have an Azure Databticks workspace that is enabled for Unity Catalog and contains a catalog named catalog1.
You have a group named group!
You plan to create a schema named schema1 in catalog1.
You need to ensure that group1 meets the following requirements:
* Can create tables in schema1
* Can modify and query tables
* Cannot grant permissions for the schema and its objects
How should you complete the SQL statements? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.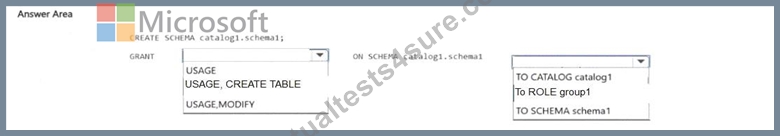
Answer:
Explanation: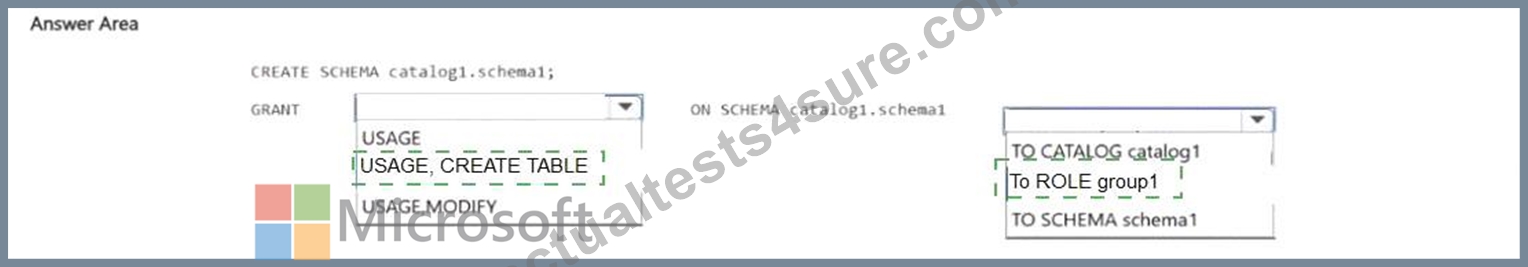
Explanation:
The correct SQL grants group1 the ability to work within the schema without delegating that ability to anyone else:
GRANT USE SCHEMA ON schema1 TO group1 - required as a prerequisite to access any object inside the schema.
GRANT CREATE TABLE ON SCHEMA schema1 TO group1 - allows creating new tables.
GRANT SELECT, MODIFY ON SCHEMA schema1 TO group1 - SELECT for queries, MODIFY for INSERT/UPDATE/DELETE operations.
Crucially, MANAGE is NOT granted. In Unity Catalog, MANAGE is what allows a principal to grant and revoke privileges on the schema and its objects. Leaving it out means group1 can do all the data work but cannot redistribute those permissions - precisely what the requirement 'Cannot grant permissions for the schema and its objects' demands.
Reference: https://learn.microsoft.com/en-us/azure/databricks/data-governance/unity-catalog/manage- privileges/privileges
NEW QUESTION # 66
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named Orders.
You load the Orders table into an Apache Spark DataFrame named df.
You need to create a DataFrame that excludes rows where the order amount is null.
Solution: You run the following expression.
df.filter(df.order_amount.isNotNull())
Does this meet the goal?
Answer: A
Explanation:
The correct answer is A - Yes.
df.filter(df.order_amount.isNotNull()) is the correct PySpark pattern for excluding null rows. The isNotNull() method is a Column method that returns True for every row where order_amount has a value and False for rows where it is null. Spark ' s filter keeps only the rows where the condition evaluates to True, producing a DataFrame with all null order_amount rows removed.
This works correctly because isNotNull() is explicitly null-aware - unlike the != None comparison in Q52, it doesn ' t rely on Python equality semantics. Under the hood it maps to the SQL expression order_amount IS NOT NULL, which is unambiguous in both SQL and Spark.
Both df.filter(df.order_amount.isNotNull()) and df.dropna(subset=[ ' order_amount ' ]) produce identical results. The choice between them is stylistic - isNotNull() reads more explicitly as a filter condition, while dropna is more compact when handling multiple columns.
Reference: https://learn.microsoft.com/en-us/azure/databricks/pyspark/basics
NEW QUESTION # 67
......
To pass the Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam you need to prepare well with the help of top-notch DP-750 exam questions which you can download from Actualtests4sure platform. On this platform, you will get valid, updated, and real Actualtests4sure DP-750 Dumps for quick exam preparation.
DP-750 Lead2pass Review: https://www.actualtests4sure.com/DP-750-test-questions.html