While buying Databricks-Certified-Professional-Data-Engineer training materials online, you may pay more attention to money safety. If you choose Databricks-Certified-Professional-Data-Engineer learning materials of us, we can ensure you that your money and account safety can be guaranteed. Since we have professional technicians check the website every day, therefore the safety can be guaranteed. In addition, Databricks-Certified-Professional-Data-Engineer Training Materials of us are high quality, they contain both questions and answers, and it’s convenient for you to check answers after practicing. We have online chat service stuff, if you have any questions about Databricks-Certified-Professional-Data-Engineer learning materials, you can have a conversion with us.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Topic 2: Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Topic 3: Debugging and Deploying | 10% | - CI/CD and DevOps practices - Troubleshooting pipelines and errors - Deployment using bundles, CLI, and APIs |
| Topic 4: Data Modelling | 6% | - Delta Lake table design - Medallion Architecture implementation - Schema design and management |
| Topic 5: Ensuring Data Security and Compliance | 10% | - Compliance standards implementation - Access control and permissions - Data encryption and masking |
| Topic 6: Data Ingestion & Acquisition | 7% | - Schema inference and evolution - Connecting to diverse data sources - Auto Loader and streaming ingestion |
| Topic 7: Data Governance | 7% | - Unity Catalog management - Policy enforcement - Data lineage and metadata tracking |
| Topic 8: Cost & Performance Optimisation | 13% | - Cluster configuration and scaling - Query optimization and caching - Storage optimization (partitioning, Z-order, indexing) |
| Topic 9: Data Transformation, Cleansing, and Quality | 10% | - Handling missing or inconsistent data - Data validation and quality checks - Standardization and normalization |
| Topic 10: Developing Code for Data Processing using Python and SQL | 22% | - Data transformation and aggregation - Batch and incremental processing logic - Integration with Databricks APIs and tools |
>> Valid Databricks-Certified-Professional-Data-Engineer Test Preparation <<
Our team of professionals and experts has prepared Databricks-Certified-Professional-Data-Engineer vce dumps by keeping the vigilant eyes on the current exam information and exam requirements. In case you failed exam with our Databricks-Certified-Professional-Data-Engineer study guide we will get you 100% money back guarantee and you can contact our support if you have any questions about our Databricks-Certified-Professional-Data-Engineer Real Dumps. We will be your support when you need us anytime.
NEW QUESTION # 99
An external object storage container has been mounted to the location/mnt/finance_eda_bucket.
The following logic was executed to create a database for the finance team: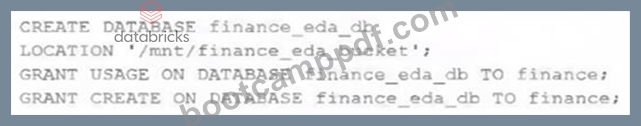
After the database was successfully created and permissions configured, a member of the finance team runs the following code: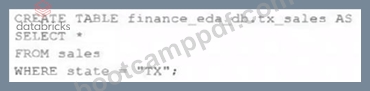
If all users on the finance team are members of thefinancegroup, which statement describes how thetx_sales table will be created?
Answer: D
Explanation:
Explanation
https://docs.databricks.com/en/lakehouse/data-objects.html
NEW QUESTION # 100
A data engineer is creating a daily reporting job. There are two reporting notebooks-one for weekdays and one for weekends. An "if/else condition" task is configured as {{job.start_time.is_weekday}} == true to route the job to either the weekday or weekend notebook tasks. The same job would be used across multiple time zones.
Which action should a senior data engineer take upon reviewing the job to merge or reject the pull request?
Answer: B
Explanation:
Comprehensive and Detailed Explanation From Exact Extract of Databricks Data Engineer Documents:
Databricks parameter templates like {{job.start_time.is_weekday}} evaluate in UTC time by default, not in local workspace or regional time zones. Therefore, when jobs are configured to run across different time zones, relying on is_weekday using UTC may cause scheduling and task routing mismatches (for example, triggering the weekday notebook in one region while it's still the weekend locally).
Databricks recommends adjusting conditional logic or pipeline parameters explicitly to handle time zone conversions if business requirements depend on local times. Because the engineer's configuration does not account for this behavior, a senior data engineer should reject the pull request and suggest time-zone-aware logic before merging.
NEW QUESTION # 101
You are asked to create a model to predict the total number of monthly subscribers for a specific magazine.
You are provided with 1 year's worth of subscription and payment data, user demographic data, and 10 years
worth of content of the magazine (articles and pictures). Which algorithm is the most appropriate for building
a predictive model for subscribers?
Answer: A
NEW QUESTION # 102
A data engineer has created a transactions Delta table on Databricks that should be used by the analytics team.
The analytics team wants to use the table with another tool that requires Apache Iceberg format.
What should the data engineer do?
Answer: B
Explanation:
Delta Lake introducedDelta Universal Format (Delta UniForm), which allowsseamless interoperability between Delta Lake and Apache Iceberg. This means a Delta table can beconverted into an Iceberg table while maintaining Delta capabilities.
Explanation of Each Option:
* (A) Require the analytics team to use a tool that supports Delta table
* Incorrect:While Delta Lake is widely used, requiring the team to change toolsis not a flexible or scalable solution.
* (B) Enable uniform on the transactions table to 'iceberg' so that the table can be read as an Iceberg table
* Incorrect:
* The uniform featuremust be enabled after conversion.
* You cannotdirectly enable uniformwithout firstconverting the table.
* (C) Create an Iceberg copy of the transactions Delta table which can be used by the analytics team
* Incorrect:
* Creating a separate Iceberg copy wouldduplicate storage and increase maintenance complexity.
* This is not necessary whenDelta UniForm allows direct compatibility with Iceberg.
* (D) Convert the transactions Delta table to Iceberg and enable uniform so that the table can be read as a Delta table
* Correct:
* The best approach is toconvert the existing Delta table to Icebergusing the Databricks Delta to Iceberg migration tools.
* After conversion,enabling uniform ensures the table remains accessible in both Delta and Iceberg formats.
Conclusion:
The best practice forinteroperability between Delta and Icebergis toconvert the Delta table to Iceberg and enable uniform, ensuringcross-compatibilitywithout data duplication.Thus,Option (D) is the correct answer.
References:
* Delta UniForm for Apache Iceberg - Databricks Documentation
* Convert Delta to Iceberg - Databricks
NEW QUESTION # 103
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: A
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 104
......
Professionals have designed this Databricks Databricks-Certified-Professional-Data-Engineer exam dumps product for the ones who want to clear the Databricks-Certified-Professional-Data-Engineer test in a short time. Success in the Databricks Databricks-Certified-Professional-Data-Engineer exam questions helps you get a good salary job in a reputed company. BootcampPDF Databricks Databricks-Certified-Professional-Data-Engineer Study Material is available in three formats. These formats have Databricks-Certified-Professional-Data-Engineer real dumps so that the applicants can memorize them and crack the Databricks-Certified-Professional-Data-Engineer certification test with a good score.
Instant Databricks-Certified-Professional-Data-Engineer Access: https://www.bootcamppdf.com/Databricks-Certified-Professional-Data-Engineer_exam-dumps.html