Investing in a Developing AI-Enabled Database Solutions (DP-800) certification is essential for professionals looking to advance their careers and stay competitive in the job market. With our actual Microsoft DP-800 questions PDF, DP-800 practice exams along with the support of our customer support team, you can be confident that you are getting the best possible DP-800 Preparation material for the test. Download Real DP-800 questions today and start your journey to success.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Implement AI capabilities in database solutions | 25-30% | - Build intelligent search and retrieval
|
| Topic 2: Design and develop database solutions | 35-40% | - Develop database solutions
|
| Topic 3: Secure, optimize, and deploy database solutions | 35-40% | - Secure database solutions
|
>> DP-800 Reliable Test Question <<
All questions in our Microsoft DP-800 pass guide are at here to help you prepare for the certification exam. We have developed our learning materials with accurate Microsoft DP-800 exam answers and detailed explanations to ensure you pass test in your first try. Our PDF files are printable that you can share your Microsoft DP-800 free demo with your friends and classmates.
NEW QUESTION # 86
You have a SQL database in Microsoft Fabric that contains a nvarchar (max) column named MessageText. An ID is always contained within the first paragraph of MessageText.
You need to write a Transact-SQL query that uses REGEXP_SUBSTR to extract the ID from MessageText.
What should you include in the query?
Answer: D
Explanation:
To extract an ID (e.g., alphanumeric) from the first paragraph of an nvarchar(max) column in Microsoft Fabric using STRING_ESCAPE, use STRING_SPLIT or CHARINDEX to isolate the first paragraph, apply STRING_ESCAPE, and a regex pattern.
Note: T-SQL does not natively support a REGEXP_SUBSTR function like Oracle/Snowflake. The solution below uses STRING_ESCAPE followed by pattern matching via PATINDEX and SUBSTRING to extract a typical alphanumeric ID.
Reference:
https://learn.microsoft.com/en-us/sql/t-sql/queries/contains-transact-sql
NEW QUESTION # 87
Case Study 2 - Fabrikam
Existing Environment
Azure Environment
Fabrikam has a single Azure subscription in the East US 2 Azure region. The subscription contains an Azure SQL database named DB1. DB1 contains the following tables:
* Patients
* Employees
* Procedures
* Transactions
* UsefulPrompts
* ProcedureDocuments
You store a column master key as a secret in Azure Key Vault.
You have an on-premises application named TransactionProcessing that uses a hard-coded username and password in a connection string to access DB1.
Problem Statements
Users report that after executing a long-running stored procedure named sp_UpdateProcedureForPatient, updates to the underlying data are sometimes inconsistent.
Requirements
Planned Changes
Fabrikam plans to manage all changes to Azure SQL Database objects by using source control in GitHub. Every pull request submitted to production will be validated before it can be merged.
Deployments must use the Release configuration.
Security Requirements
Fabrikam identifies the following security requirements:
* The TransactionProcessing application must use a passwordless connection to DB1.
* The Employees table contains two columns named TaxID and Salary that must be encrypted at rest.
* Auditors must have a tamper-evident history of transactions with cryptographic proof of changes to the employee data.
Database Performance Requirements
Records accessed by using sp_UpdateProcedureForPatient must NOT be changed by other transactions while the stored procedure runs.
AI Search, Embeddings, and Vector Indexing
Fabrikam identifies the following AI-related requirements:
* Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
* Users must be able to query the data in DB1 by using prompts in Copilot in Microsoft Fabric.
* The UsefulPrompts table will store prompts that doctors can use to help diagnose patient illness by connecting to an Azure OpenAI endpoint.
Development Requirements
Fabrikam identifies the following development requirements:
* Provide the functionality to retrieve all the transactions of a given patient between two dates, showing a running total.
* Expose a Data API builder (DAB) configuration file to enable Azure services to perform the following operations over a REST API:
- Read data from the procedures table without authentication.
- Read and insert data into the Transactions table once authenticated.
- Execute the sp_UpdateProcedurePatient stored procedure.
* Provide the functionality to retrieve a list of the names of patients who underwent medical procedures during the last 30 days.
* Information for each medical procedure will be stored in a table. The table will be used with a large language model (LLM) for user querying and will have the following structure.
DAB
You create a DAB configuration file that meets the development requirements for DB1 and includes the following entities.
You implement ProcedureDocuments to support the planned changes.
When users consume data through the Retrieval Augmented Generation (RAG) pattern, they experience data retrieval delays.
You need to improve the data retrieval performance and reduce the number of tokens per retrieval.
What should you implement?
Answer: B
Explanation:
Scenario: Fabrikam identifies the following AI-related requirements: Queries to the ProcedureDocuments table must use Reciprocal Rank Fusion (RRF).
To remedy data retrieval delays in a Retrieval Augmented Generation (RAG) pattern using Reciprocal Rank Fusion (RRF) on an Azure SQL Database table, you should use embeddings.
In a RAG architecture, retrieval delays often stem from inefficient or computationally heavy search processes. While RRF is excellent for merging results from multiple sources (like combining keyword and vector searches), the core of the speed problem typically lies in how the initial data is indexed and retrieved.
Role of Embeddings
Vector Search Acceleration: Embeddings convert text into high-dimensional vectors. Azure SQL Database can perform similarity searches on these vectors much faster than complex semantic text matching.
Hybrid Search Synergy: RRF is most effective when it fuses results from a keyword search (fast) and a vector search (powered by embeddings). Using embeddings ensures that the "semantic" side of the retrieval is streamlined.
Pre-computation: Since embeddings are generated once during ingestion, the retrieval phase only requires a distance calculation (e.g., Cosine Similarity), which is significantly faster than real- time natural language parsing during each query.
Reference:
https://pratikbarjatya.medium.com/unlocking-the-power-of-language-with-retrieval-augmented- generation-rag-14123cc275e6
NEW QUESTION # 88
What challenge does AI introduce to SQL systems?
Answer: C
Explanation:
AI may generate incorrect answers and requires strong governance and validation.
NEW QUESTION # 89
You are developing an Azure SQL solution by using Microsoft Visual Studio 2026. The solution uses a GitHub repository.
You plan to use GitHub Copilot Chat to access the GitHub repository tools by connecting to the GitHub MCP Server.
You need to configure Visual Studio to support the planned configuration. The solution must rely on OAuth to access the MCP server.
What should you create?
Answer: D
NEW QUESTION # 90
You have an Azure Al Search service and an index named hotels that includes a vector Held named DescriptionVector.
You query hotels by using the Search Documents REST API.
You add semantic ranking to the hybrid search query and discover that some queries return fewer results than expected, and captions and answers are missing.
You need to complete the hybrid search request to meet the following requirements:
* Include more documents when ranking.
* Always include captions and answers.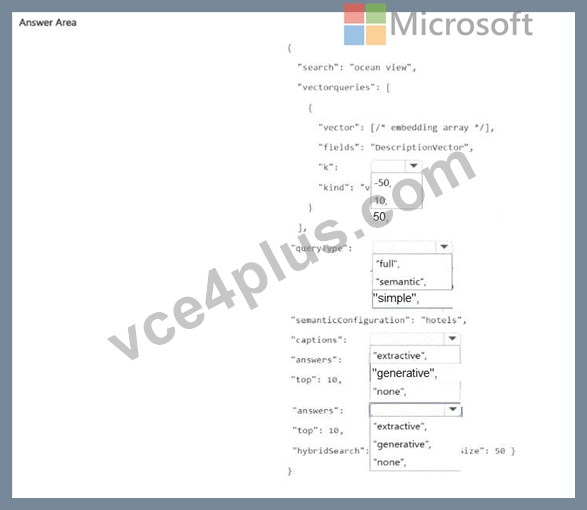
Answer:
Explanation: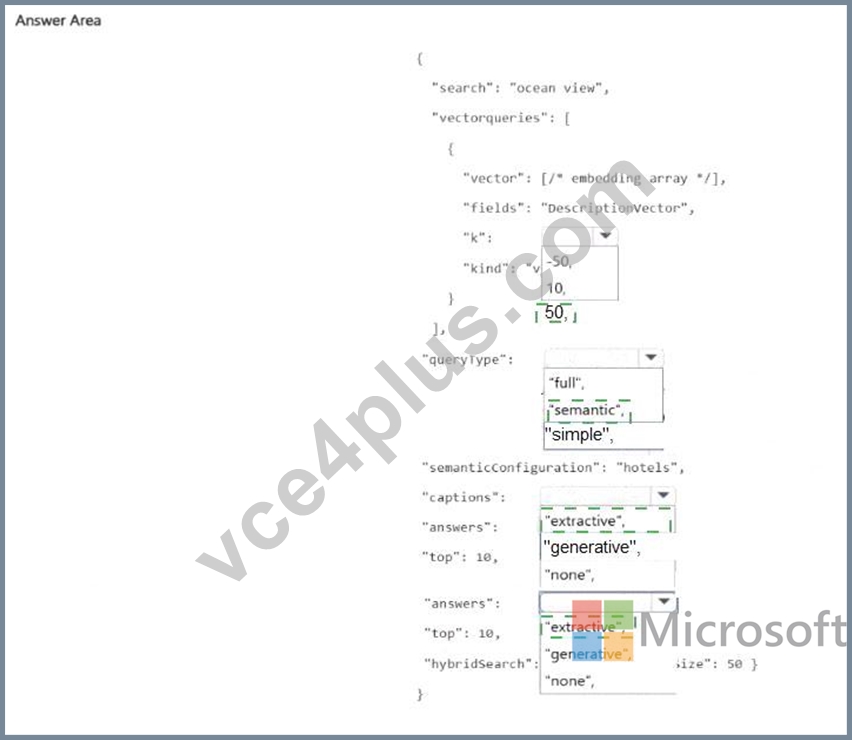
Explanation: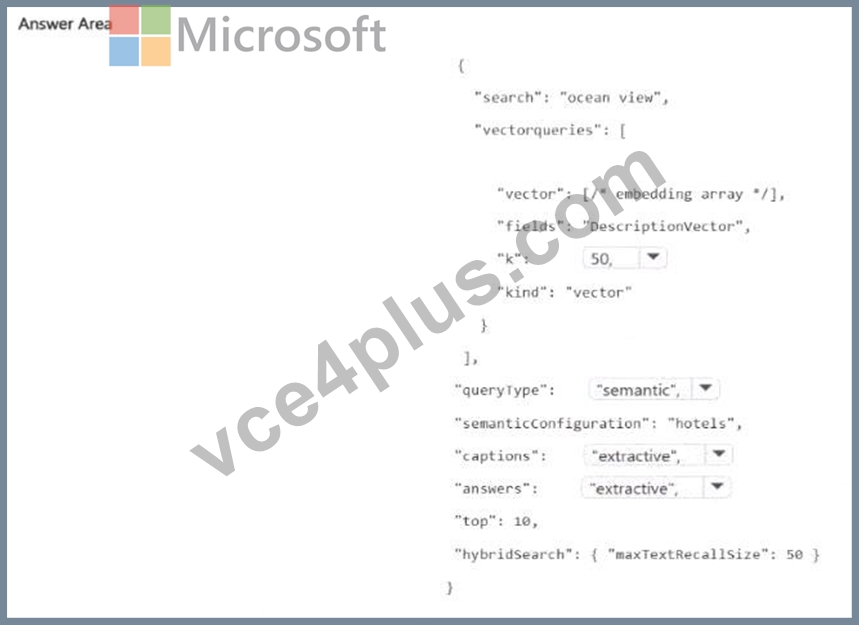
These are the correct selections for a hybrid query that uses semantic ranking in Azure AI Search.
Use k = 50 because Microsoft explicitly recommends that when you combine semantic ranking with vector queries , you should set k to 50 so the semantic ranker has enough candidates to rerank. If you use a smaller value such as 10, semantic ranking can receive too few inputs, which is exactly why some queries return fewer results than expected.
Use queryType = " semantic " because captions and answers are only available on semantic queries.
Microsoft documents that captions is valid only when the query type is semantic, and semantic answers are returned only for semantic queries.
Use captions = " extractive " because semantic captions are extractive passages pulled from the top-ranked documents. Microsoft's REST documentation states that the valid captions option here is extractive and that it defaults to none if not specified.
Use answers = " extractive " because semantic answers in Azure AI Search are extractive, not generated.
Microsoft documents that semantic answers are verbatim passages recognized as answers and the REST API lists extractive as the answer-return option.
NEW QUESTION # 91
......
We promise you that if you fail to pass your exam after using DP-800 exam materials, we will give you refund. We are pass guarantee and money back guarantee. Moreover, DP-800 training materials cover most of knowledge points for the exam, and you can master the major knowledge points as well as improve your professional ability after practicing. DP-800 Exam Materials contain both questions and answers, and it’s convenient for you to have a quickly check after practicing. We also have online and offline chat service, if you have any questions about DP-800 exam dumps, you can consult us.
DP-800 New Test Materials: https://www.vce4plus.com/Microsoft/DP-800-valid-vce-dumps.html