One of the advantages of our DP-750 study material is that it has various versions. There are includes PDF, APP and Practice exam software. Every version has their feature. DP-750 PDF can download as a document in your smart devices and lug it along with you, it makes your DP-750 prepare more convenient. DP-750 App is unlimited use of equipment, support for any electronic device, but also support offline use, while the Practice exam software creates is like an actual test environment for your DP-750 Certification Exam. The software also sets up time and mock examination functions. You can set a timer for simulation tests to help you complete our DP-750 Practice in an effective time, which will help you adjust the speed and vigilance in real exams.
| Section | Weight | Objectives |
|---|---|---|
| Set up and configure an Azure Databricks environment | 15-20% | - Create and configure Azure Databricks workspaces
|
| Secure and govern Unity Catalog objects | 15-20% | - Implement governance and security
|
| Prepare and process data | 30-35% | - Ingest and transform data
|
| Deploy and maintain data pipelines and workloads | 30-35% | - Manage production workloads
|
If you prefer to have your practice online, then you can choose us. DP-750 PDF version is printable and you can print them into hard one and take some notes on them. In addition, DP-750 exam dumps have free demo for you to have a try, so that you can have a deeper understanding of what you are going to buy. You can receive your download link and password within ten minutes for DP-750 Exam Dumps. We have online and offline chat service stuff for DP-750 exam materials, and if you have any questions, you can have a conversation with us, and we will give you reply as soon as we can.
NEW QUESTION # 11
What ensures failure recovery in Databricks Structured Streaming?
Answer: B
Explanation:
Checkpointing stores streaming state and progress, allowing recovery after failures without data loss or duplication. Auto scaling adjusts compute resources but does not ensure reliability.
Partition pruning improves query performance. Broadcast joins optimize joins but are unrelated to recovery.
NEW QUESTION # 12
You have an Azure Databricks workspace named Workspace1. You create a compute cluster named Cluser1 that will be used to ingest data.
You need to install the required libraries on Cluster 1. The solution must use Unity Catalog for access control.
What should you do?
Answer: C
Explanation:
The correct answer is B. The %pip install command (or pip3 in a terminal context) creates an isolated, per- session library environment in notebooks, which is the Unity Catalog-compatible approach. Unity Catalog workspaces require cluster access mode set to 'Shared' or 'Single User,' and %pip installs work seamlessly within those modes without requiring cluster restarts.
Option A (custom dependency script) introduces extra maintenance work for every environment change - exactly what the question says to avoid. Option C installs libraries at the cluster level and requires a manual restart, which disrupts other users sharing the cluster and bypasses the per-notebook isolation model that Unity Catalog recommends. Option D uploads libraries to the Workspace file system (legacy DBFS approach), which is being deprecated in favour of Unity Catalog Volumes for library storage.
Reference: https://learn.microsoft.com/en-us/azure/databricks/libraries/notebooks-python-libraries
NEW QUESTION # 13
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Tabid.
Table! is written by batch jobs every hour and is queried frequently by filtering two columns named Customerld and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area NOTE: Each correct selection is worth one point.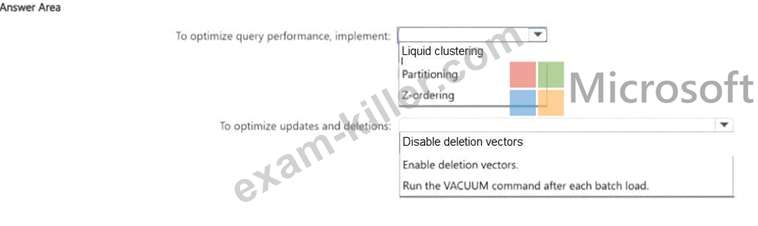
Answer:
Explanation: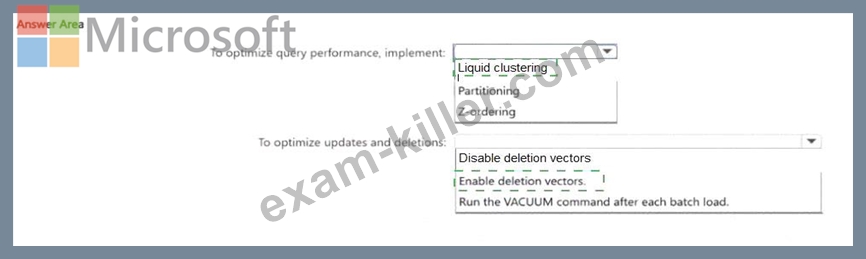
Explanation:
Two features work together to keep performance consistent and update costs low:
OPTIMIZE with ZORDER BY (CustomerId, EventDate). Z-Ordering co-locates rows with the same CustomerId and EventDate values in the same Parquet files. When a query filters on those columns, the Delta engine uses file statistics to skip files that can't possibly contain matching rows (data skipping). As the table grows, skipping scales proportionally - query time stays consistent.
Deletion Vectors (delta.enableDeletionVectors = true). When a row is updated or deleted, instead of rewriting the entire Parquet file, Delta marks the affected row in a small companion deletion vector file. This dramatically reduces write amplification for the frequent compliance-driven updates and deletions the question describes. Actual file rewrites are deferred to the next OPTIMIZE run.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta/data-skipping
NEW QUESTION # 14
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: B
Explanation:
You should enable schema evolution to resolve this problem. In Lakeflow Spark Declarative Pipelines (SDP)-formerly known as Delta Live Tables (DLT)-schema evolution automatically updates the schema of your managed Delta tables when new columns are detected in the source data.
Prevents Pipeline Failures: By default, Delta Lake applies strict schema enforcement to prevent bad or mismatched data from corrupting your tables. When the source data layout changes (e.g., column creep), the pipeline will throw a runtime error and fail the write operation.
Automates Ingestion Flexibility: Activating schema evolution allows Delta Lake to automatically adapt by adding the new columns to the target managed table layout dynamically, eliminating manual intervention or explicit ALTER TABLE operations.
Reference:
https://learn.microsoft.com/en-us/azure/databricks/ldp/unity-catalog
NEW QUESTION # 15
You have an Azure Databricks workspace that contains a Delta table named Customer.
A job named Job1 performs frequent upserts into Customer.
You discover that Job1 has created many small Parquet files in Customer, and the small files are degrading query performance.
You need to improve query performance for the current data already stored in Customer. The solution must not affect the travel for the Customer table.
What should you do?
Answer: D
Explanation:
The OPTIMIZE command performs bin-packing compaction, combining the Customer table's existing small Parquet files into fewer, larger files. This reduces file-open overhead and improves data-skipping efficiency without changing the logical table contents. Enabling optimized writes affects future write operations but does not compact the small files already stored. VACUUM removes unreferenced data files that are older than the configured retention threshold; it does not reorganize active small files and can restrict time-travel availability. Reducing delta.deletedFileRetentionDuration changes how long obsolete files remain available and can directly reduce the time-travel window, contrary to the requirement. OPTIMIZE is therefore the correct operation for improving the physical layout of current data while preserving Delta table semantics and history. Microsoft Learn
NEW QUESTION # 16
......
Before you decide to get the DP-750 exam certification, you may be attracted by the benefits of DP-750 credentials. Get certified by DP-750 certification means you have strong professional ability to deal with troubleshooting in the application. Besides, you will get promotion in your job career and obtain a higher salary. If you want to pass your Microsoft DP-750 Actual Test at first attempt, DP-750 pdf torrent is your best choice. The high pass rate of DP-750 vce dumps can give you surprise.
Exam DP-750 Cost: https://www.exam-killer.com/DP-750-valid-questions.html