P.S. Free 2026 Snowflake SPS-C01 dumps are available on Google Drive shared by Exam4Tests: https://drive.google.com/open?id=1auZ-frn1GITgAGRQfQ77JqPJsiRkR9Zb
Eliminates confusion while taking the Snowflake SPS-C01 certification exam. Prepares you for the format of your SPS-C01 exam dumps, including multiple-choice questions and fill-in-the-blank answers. Comprehensive, up-to-date coverage of the entire Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) certification curriculum. Snowflake SPS-C01 practice questions are based on recently released SPS-C01 exam objectives.
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API for Python | 30% | - Reading and writing data - Working with Semi-structured data - DataFrame creation and manipulation - Establishing connections and session management - User-Defined Functions (UDFs) and Stored Procedures |
| Performance Optimization and Best Practices | 20% | - Caching strategies - Debugging and explain plans - Vectorized UDFs - Query pushdown and optimization - Minimizing data transfer - Warehouse sizing for Snowpark |
| Data Transformations and DataFrame Operations | 35% | - Complex data pipelines - Using built-in functions - Persisting transformed data - Filtering, Aggregating, and Joining DataFrames - Window functions |
| Snowpark Concepts | 15% | - Transformations vs. Actions - Snowpark DataFrames and query plans - Snowpark architecture and core concepts - Stored procedures and conditional logic - Snowpark Sessions and connection management - Client-side vs. Server-side execution |
The advent of our Snowflake SPS-C01 study guide with three versions has helped more than 98 percent of exam candidates get the certificate successfully. Rather than insulating from the requirements of the Snowflake Certified SnowPro Specialty - Snowpark SPS-C01 Real Exam, our SPS-C01 practice materials closely co-related with it.
NEW QUESTION # 69
A data engineering team is developing a Snowpark application to process large volumes of data'. They aim to leverage session parameters for fine-grained control over query execution and resource allocation. Which of the following methods is the MOST efficient and secure way to set session parameters, ensuring that sensitive information like warehouse size and query timeouts are dynamically adjusted based on the workload without hardcoding values in the application?
Answer: A
Explanation:
Option E is the most efficient and secure because it allows for a combination of pre-configured parameters from a secure source (like a configuration file) and dynamic overrides based on the specific workload. This ensures that the application can adapt to different processing needs without exposing sensitive information or hardcoding values. Account level parameters are too broad (D), Direct SQL execution is inefficient (A), Environment Variables are less secure (B), and CLI is not dynamic for in-application session settings (C).
NEW QUESTION # 70
You are tasked with creating a Snowpark stored procedure that needs to access a secret stored in Snowflake's Secret Managen The secret contains credentials required to connect to an external API. Which of the following steps are necessary to correctly and securely access and use the secret within your Snowpark stored procedure? (Select all that apply)
Answer: A,B,D
Explanation:
Options A, B, and D are the correct steps. First, the executing role needs 'USAGE on the secret. Second, session.get_secret('secret_name')' is the correct method to access the secret value within the procedure. The stored procedure must be created with EXECUTE AS CALLER for it to use the caller's permissions (which include access to the secret). Option C is incorrect because storing secrets directly in the code is a security risk. Option E is incorrect because Creating a UDF is unneccessary, stored procedures are capable of accessing secret manager directly with provided right access.
NEW QUESTION # 71
You have a Snowpark DataFrame named 'products_df' with columns 'product_id' (INT), 'product_name' (VARCHAR), and 'price' (FLOAT). You want to create a new DataFrame called 'discounted_products df that includes all columns from 'products_df' plus a new column named 'discounted_price', which is calculated as the original price minus a discount percentage specified by the variable 'discount_rate' (e.g., 0.1 for 10%). The 'discount_rate' is stored in the database table named 'discount_table'. You want to load the rate to variable. Choose the correct ways to achieve this. (Select all that apply)





Answer: A,C,D
Explanation:
Options A, B and D provide valid ways to fetch 'discount_rate' as a single numerical value. And fetch the data and gets the first value from the first row. Similarly, gets the data and return the first row. However, Option C does not have LIMIT 1 and will not work. Option E fetches one row as one array, thus requires rate[0] to compute discounted_price.
NEW QUESTION # 72
You have a Snowpark DataFrame named 'customer df containing customer data, including sensitive information like credit card numbers in a column named 'credit card'. You need to persist this data to a Snowflake table named 'secure_customers'. What is the MOST secure and efficient way to achieve this, ensuring that the 'credit card' column is never exposed in plain text during the persistence process and also optimized for subsequent analytical queries?
Answer: C
Explanation:
Applying a masking policy to the column AFTER persisting ensures that the data is protected at rest and dynamically masked based on the user's role/permissions. This approach minimizes the risk of exposing sensitive data during the transformation and persistence process. Using UDF encryption adds complexity and potential performance overhead. Dropping the column loses the data, and the temporary table approach exposes the unencrypted data temporarily.
NEW QUESTION # 73
You have a Snowpark DataFrame containing customer data'. You need to create a stored procedure that accepts the DataFrame and a list of column names as input and returns a new DataFrame containing only the specified columns. Which of the following approaches correctly implement this functionality and handles data types effectively (Select all that apply)?
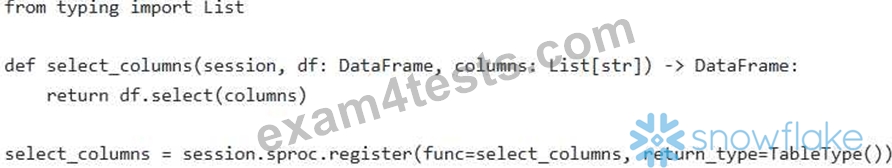
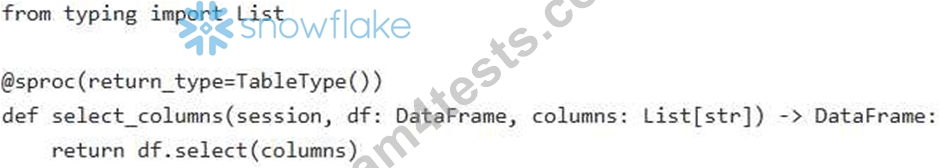
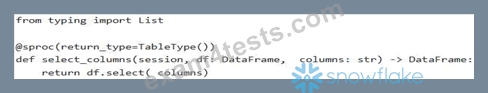
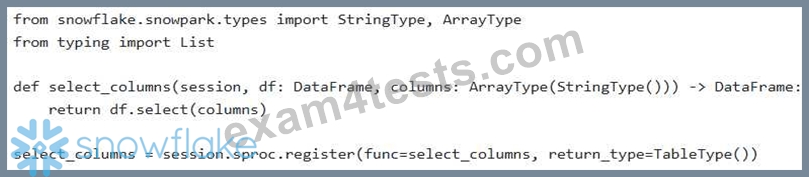
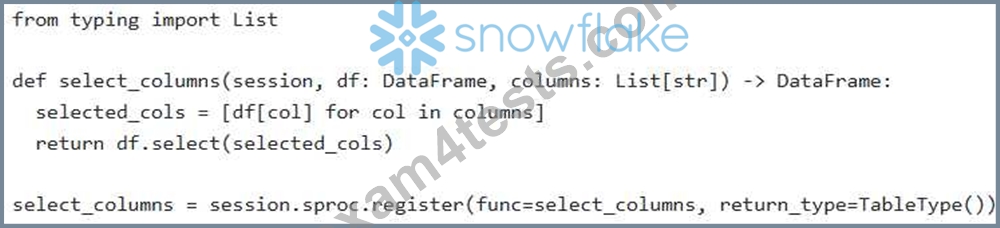
Answer: A,E
Explanation:
Options B and E are correct. Option B correctly registers the function 'select_columnS as a stored procedure using "session.sproc.register'. Option E properly constructs the DataFrame by dynamically selecting columns by using 'df[col]'. Option A although syntactically correct may not perform as expected. Option C is incorrect because it attempts to use 'ArrayType' for a standard Python List, which is incompatible. Option D uses columns: str' which makes column as Tuple object instead of List object.
NEW QUESTION # 74
......
Nowadays, our learning methods become more and more convenient. Advances in technology allow us to learn freely on mobile devices. However, we understand that some candidates are still more accustomed to the paper, so our SPS-C01 study materials provide customers with a variety of versions to facilitate your learning process: the PDF, Software and APP online. These three versions of our SPS-C01 Practice Engine can provide you study on all conditions. Come and buy our SPS-C01 exam guide!
New SPS-C01 Test Tutorial: https://www.exam4tests.com/SPS-C01-valid-braindumps.html
What's more, part of that Exam4Tests SPS-C01 dumps now are free: https://drive.google.com/open?id=1auZ-frn1GITgAGRQfQ77JqPJsiRkR9Zb