P.S. Free 2026 Microsoft DP-100 dumps are available on Google Drive shared by PDFVCE: https://drive.google.com/open?id=1fuB6Z4bgKSxc-45tItatY-JHZgPAwSIg
PDFVCE is a leading platform in this area by offering the most accurate DP-100 exam questions to help our customers to pass the exam. And we are grimly determined and confident in helping you. With professional experts and brilliant teamwork, our DP-100 practice materials have helped exam candidates succeed since the beginning. To make our DP-100 simulating exam more precise, we do not mind splurge heavy money and effort to invite the most professional teams into our group.
The Microsoft DP-100 test is associated with the Microsoft Certified: Azure Data Scientist Associate certificate. It is a recently launched certification by Microsoft trying to impart the knowledge of concepts related to machine learning techniques. As a rule, earners are known to have industry-standard expertise related to evaluation and deployment models for building ML solutions. Apart from grating this noteworthy designation, the Microsoft DP-100 Exam will also help the test-taker to gain some ACE college credits.
Now we can say that the Microsoft DP-100 exam practice questions are real, valid, and updated as per the Designing and Implementing a Data Science Solution on Azure exam syllabus. So rest assured that with the Microsoft DP-100 Exam Practice test questions you can ace your exam preparation quickly and be ready to perform well in the final Microsoft DP-100 certification exam.
Microsoft DP-100 exam, also known as Designing and Implementing a Data Science Solution on Azure, is a certification exam for professionals who wish to demonstrate their skills in designing and implementing data science solutions on Azure. DP-100 Exam is part of Microsoft's Azure certification program and is targeted towards data scientists, machine learning engineers, and other professionals involved in data science.
NEW QUESTION # 172
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You are creating a new experiment in Azure Machine Learning Studio.
One class has a much smaller number of observations than tin- other classes in the training set.
You need to select an appropriate data sampling strategy to compensate for the class imbalance.
Solution: You use the Principal Components Analysis (PCA) sampling mode.
Does the solution meet the goal?
Answer: B
Explanation:
Instead use the Synthetic Minority Oversampling Technique (SMOTE) sampling mode.
Note: SMOTE is used to increase the number of underepresented cases in a dataset used for machine learning. SMOTE is a better way of increasing the number of rare cases than simply duplicating existing cases.
Incorrect Answers:
The Principal Component Analysis module in Azure Machine Learning Studio (classic) is used to reduce the dimensionality of your training data. The module analyzes your data and creates a reduced feature set that captures all the information contained in the dataset, but in a smaller number of features.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/principal-component-analysis
NEW QUESTION # 173
You have a Python data frame named salesData in the following format: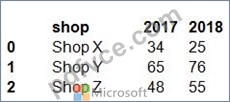
The data frame must be unpivoted to a long data format as follows: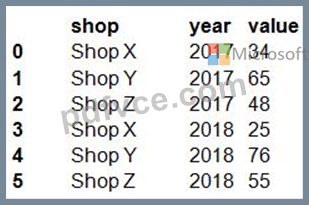
You need to use the pandas.melt() function in Python to perform the transformation.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.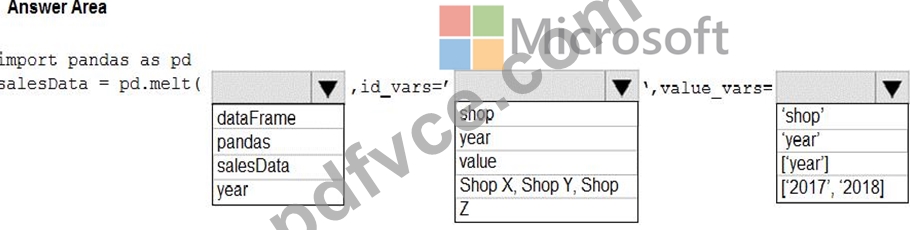
Answer:
Explanation: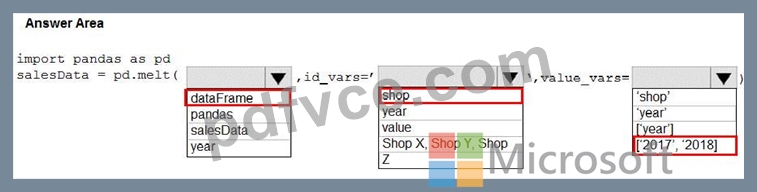
Explanation:
Box 1: dataFrame
Syntax: pandas.melt(frame, id_vars=None, value_vars=None, var_name=None, value_name='value', col_level=None)[source] Where frame is a DataFrame Box 2: shop Paramter id_vars id_vars : tuple, list, or ndarray, optional Column(s) to use as identifier variables.
Box 3: ['2017','2018']
value_vars : tuple, list, or ndarray, optional
Column(s) to unpivot. If not specified, uses all columns that are not set as id_vars.
Example:
df = pd.DataFrame({'A': {0: 'a', 1: 'b', 2: 'c'},
... 'B': {0: 1, 1: 3, 2: 5},
... 'C': {0: 2, 1: 4, 2: 6}})
pd.melt(df, id_vars=['A'], value_vars=['B', 'C'])
A variable value
0 a B 1
1 b B 3
2 c B 5
3 a C 2
4 b C 4
5 c C 6
References:
https://pandas.pydata.org/pandas-docs/stable/reference/api/pandas.melt.html
NEW QUESTION # 174
You create an Azure Machine Learning workspace. You use the Azure Machine Learning Python SDK v2 to create a compute cluster.
The compute cluster must run a training script. Costs associated with running the training script must be minimized.
You need to complete the Python script to create the compute cluster.
How should you complete the script? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.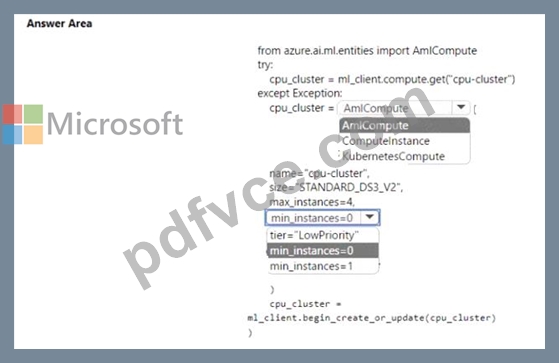
Answer:
Explanation: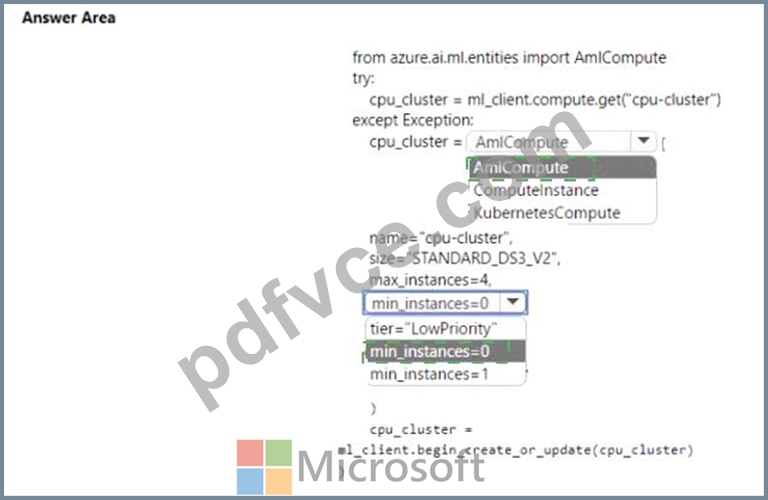
Explanation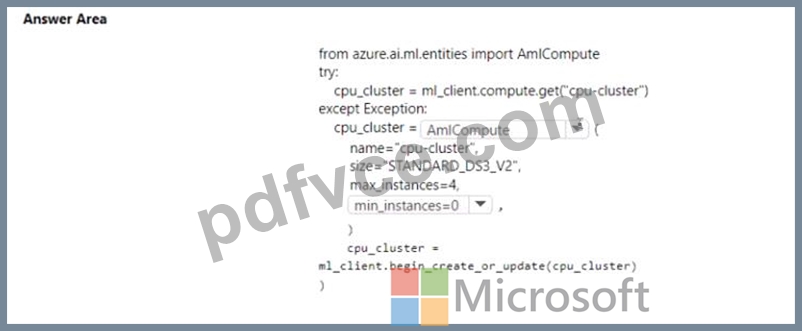
NEW QUESTION # 175
You register a model that you plan to use in a batch inference pipeline.
The batch inference pipeline must use a ParallelRunStep step to process files in a file dataset. The script has the ParallelRunStep step runs must process six input files each time the inferencing function is called.
You need to configure the pipeline.
Which configuration setting should you specify in the ParallelRunConfig object for the PrallelRunStep step?
Answer: A
Explanation:
node_count is the number of nodes in the compute target used for running the ParallelRunStep.
Reference:
https://docs.microsoft.com/en-us/python/api/azureml-contrib-pipeline-steps/azureml.contrib.pipeline.steps.parall
NEW QUESTION # 176
You have a model with a large difference between the training and validation error values.
You must create a new model and perform cross-validation.
You need to identify a parameter set for the new model using Azure Machine Learning Studio.
Which module you should use for each step? To answer, drag the appropriate modules to the correct steps.
Each module may be used once or more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.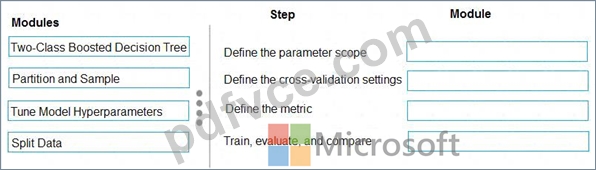
Answer:
Explanation: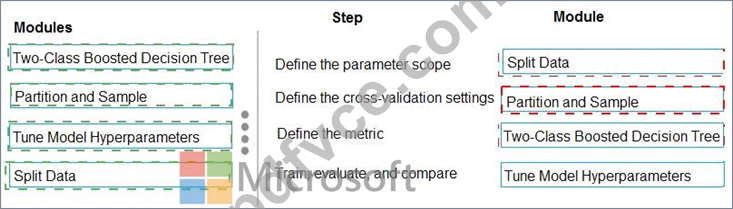
Explanation: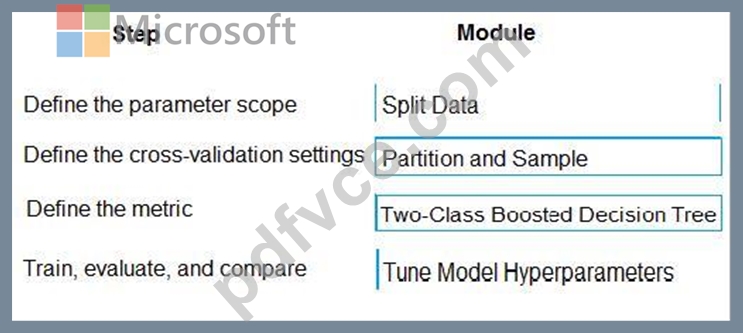
Box 1: Split data
Box 2: Partition and Sample
Box 3: Two-Class Boosted Decision Tree
Box 4: Tune Model Hyperparameters
Integrated train and tune: You configure a set of parameters to use, and then let the module iterate over multiple combinations, measuring accuracy until it finds a "best" model. With most learner modules, you can choose which parameters should be changed during the training process, and which should remain fixed.
We recommend that you use Cross-Validate Model to establish the goodness of the model given the specified parameters. Use Tune Model Hyperparameters to identify the optimal parameters.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/partition-and-sample
NEW QUESTION # 177
......
Exam DP-100 Tests: https://www.pdfvce.com/Microsoft/DP-100-exam-pdf-dumps.html
BONUS!!! Download part of PDFVCE DP-100 dumps for free: https://drive.google.com/open?id=1fuB6Z4bgKSxc-45tItatY-JHZgPAwSIg