P.S.GoShikenがGoogle Driveで共有している無料の2026 Google Professional-Machine-Learning-Engineerダンプ:https://drive.google.com/open?id=1OO_E487OV2MlJnc-lcUgadmH7uyTqJVv
GoShikenの参考資料に疑問があって、躊躇うなら、あなたは我々のサイトで問題集のサンプルをダウンロードして無料で試すことができます。Professional-Machine-Learning-Engineer資料のサンプルによって、この問題集はあなたにふさわしいなら、あなたは安心で問題集を購入することができます。Professional-Machine-Learning-Engineer資料を使用したら、あなたは後悔しませんと信じています。
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Exam Format: | Case study, Multiple choice, Multiple select |
| Available Languages: | English, Japanese |
| Real Exam Qty: | Approximately 50–60 questions |
| Exam Duration: | 120 minutes |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Google Cloud Professional Data Engineer Google Cloud Associate Cloud Engineer Google Cloud Professional Cloud Architect |
| Exam Price: | $200 USD |
| Recommended Training: | Google Cloud Skills Boost - Machine Learning Engineer Path Vertex AI Documentation |
| Exam Registration: | Google Cloud Certification Portal Kryterion Webassessor |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online proctored exam or in-person testing via Kryterion test centers. |
| Pre Condition: | No formal prerequisites required, but 3+ years of industry experience in ML/AI and familiarity with Google Cloud Platform are strongly recommended. |
| Official Syllabus URL: | https://cloud.google.com/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer独学書籍 <<
GoogleのProfessional-Machine-Learning-Engineer試験トレントを購入した後、10分以内にできるだけ早く製品をお届けすることを保証します。 そのため、長時間待つ必要がなく、配達時間や遅延を心配する必要はありません。 Professional-Machine-Learning-Engineer準備トレントをすぐにオンラインでお客様に転送します。このサービスは、GoShikenのProfessional-Machine-Learning-Engineerテストブレインダンプが人々の心をつかむ理由でもあります。 さらに、Professional-Machine-Learning-Engineerトレーニングガイドで20〜30時間だけ学習すれば、Google Professional Machine Learning Engineer試験に自信を持って合格することができます。
Googleのプロフェッショナル機械学習エンジニア認定試験は、世界的に認められた資格であり、世界中で職業的な信頼性を高める証明書となります。この試験は、機械学習エンジニア、データサイエンティスト、インターネット・オブ・シングス(IoT)アーキテクト、ソフトウェアエンジニア、またはAIコンサルタントなど、多様な職種に対するプロフェッショナルの準備を支援します。要するに、この認定は、スキルの拡大と獲得した専門知識の検証の優れた機会であり、認定された経験のない候補者と比較して同じポジションに応募する際に優位性を得ることができます。
質問 # 87
You have been asked to develop an input pipeline for an ML training model that processes images from disparate sources at a low latency. You discover that your input data does not fit in memory. How should you create a dataset following Google-recommended best practices?
正解:C
質問 # 88
You need to use TensorFlow to train an image classification model. Your dataset is located in a Cloud Storage directory and contains millions of labeled images Before training the model, you need to prepare the dat a. You want the data preprocessing and model training workflow to be as efficient scalable, and low maintenance as possible. What should you do?
正解:B
質問 # 89
You are building a linear model with over 100 input features, all with values between -1 and 1. You suspect that many features are non-informative. You want to remove the non-informative features from your model while keeping the informative ones in their original form. Which technique should you use?
正解:A
解説:
L1 regularization, also known as Lasso regularization, adds the sum of the absolute values of the model's coefficients to the loss function1. It encourages sparsity in the model by shrinking some coefficients to precisely zero2. This way, L1 regularization can perform feature selection and remove the non-informative features from the model while keeping the informative ones in their original form. Therefore, using L1 regularization is the best technique for this use case.
References:
* Regularization in Machine Learning - GeeksforGeeks
* Regularization in Machine Learning (with Code Examples) - Dataquest
* L1 And L2 Regularization Explained & Practical How To Examples
* L1 and L2 as Regularization for a Linear Model
質問 # 90
You trained a text classification model. You have the following SignatureDefs: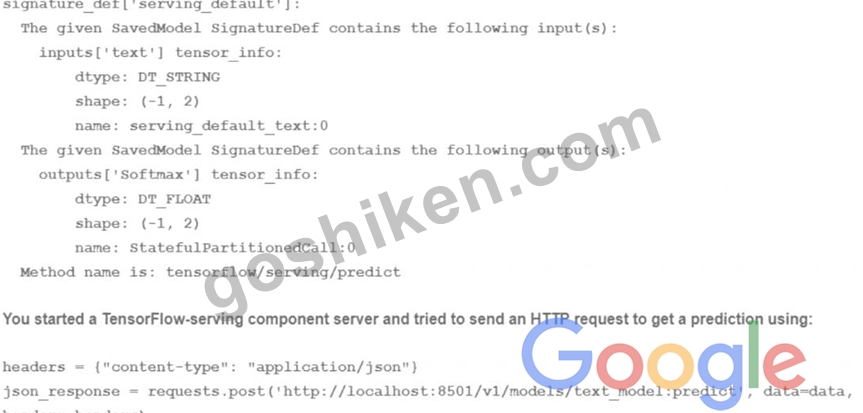
What is the correct way to write the predict request?
正解:C
解説:
A predict request is a way to send data to a trained model and get predictions in return. A predict request can be written in different formats, such as JSON, protobuf, or gRPC, depending on the service and the platform that are used to host and serve the model. A predict request usually contains the following information:
* The signature name: This is the name of the signature that defines the inputs and outputs of the model. A signature is a way to specify the expected format, type, and shape of the data that the model can accept and produce. A signature can be specified when exporting or saving the model, or it can be automatically inferred by the service or the platform. A model can have multiple signatures, but only one can be used for each predict request.
* The instances: This is the data that is sent to the model for prediction. The instances can be a single instance or a batch of instances, depending on the size and shape of the data. The instances should match the input specification of the signature, such as the number, name, and type of the input tensors.
For the use case of training a text classification model, the correct way to write the predict request is D. data = json.dumps({"signature_name": "serving_default", "instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) This option involves writing the predict request in JSON format, which is a common and convenient format for sending and receiving data over the web. JSON stands for JavaScript Object Notation, and it is a way to represent data as a collection of name-value pairs or an ordered list of values. JSON can be easily converted to and from Python objects using the json module.
This option also involves using the signature name "serving_default", which is the default signature name that is assigned to the model when it is saved or exported without specifying a custom signature name. The serving_default signature defines the input and output tensors of the model based on the SignatureDef that is shown in the image. According to the SignatureDef, the model expects an input tensor called "text" that has a shape of (-1, 2) and a type of DT_STRING, and produces an output tensor called "softmax" that has a shape of (-1, 2) and a type of DT_FLOAT. The -1 in the shape indicates that the dimension can vary depending on the number of instances, and the 2 indicates that the dimension is fixed at 2. The DT_STRING and DT_FLOAT indicate that the data type is string and float, respectively.
This option also involves sending a batch of three instances to the model for prediction. Each instance is a list of two strings, such as ['a', 'b'], ['c', 'd'], or ['e', 'f']. These instances match the input specification of the signature, as they have a shape of (3, 2) and a type of string. The model will process these instances and produce a batch of three predictions, each with a softmax output that has a shape of (1, 2) and a type of float.
The softmax output is a probability distribution over the two possible classes that the model can predict, such as positive or negative sentiment.
Therefore, writing the predict request as data = json.dumps({"signature_name": "serving_default",
"instances": [['a', 'b'], ['c', 'd'], ['e', 'f']]}) is the correct and valid way to send data to the text classification model and get predictions in return.
References:
* [json - JSON encoder and decoder]
質問 # 91
You are building a predictive maintenance model to preemptively detect part defects in bridges. You plan to use high definition images of the bridges as model inputs. You need to explain the output of the model to the relevant stakeholders so they can take appropriate action. How should you build the model?
正解:B
解説:
According to the official exam guide1, one of the skills assessed in the exam is to "explain the predictions of a trained model". TensorFlow2 is an open source framework for developing and deploying machine learning and deep learning models. TensorFlow supports various model explainability methods, such as Integrated Gradients3, which is a technique that assigns an importance score to each input feature by approximating the integral of the gradients along the path from a baseline input to the actual input. Integrated Gradients can help explain the output of a deep learning-based model by highlighting the most influential features in the input images. Therefore, option C is the best way to build the model for the given use case. The other options are not relevant or optimal for this scenario. Reference:
Professional ML Engineer Exam Guide
TensorFlow
Integrated Gradients
Google Professional Machine Learning Certification Exam 2023
Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
質問 # 92
......
Professional-Machine-Learning-Engineer日本語試験対策: https://www.goshiken.com/Google/Professional-Machine-Learning-Engineer-mondaishu.html
さらに、GoShiken Professional-Machine-Learning-Engineerダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1OO_E487OV2MlJnc-lcUgadmH7uyTqJVv