Topexam1年以内にDP-800試験問題の更新を無料で提供し、購入者が1年後にサービス保証を延長したい場合は50%の割引特典を提供します。古いクライアントは、他の試験教材を購入する際に、ある程度の割引を受けています。 DP-800ガイドトレントを頻繁に更新し、理論と実践の最新動向を反映した最新の学習資料を提供します。したがって、DP-800テストガイドを十分にマスターし、試験に合格することができます。メリットを享受しながら、試験に合格することができます。お気軽にDP-800ガイド急流を購入してください!
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
MicrosoftのDP-800認定試験に合格するのは簡単なことではありませんか。TopexamのMicrosoftのDP-800試験トレーニング資料を選ぶなら、一回で認定試験に合格するの可能性は高いです。TopexamのMicrosoftのDP-800試験トレーニング資料は豊富な経験を持っているIT業種の専門家が長年の研究を通じて、作成したものです。その権威性が高いと言えます。Topexamを選ぶなら、絶対に後悔させません。
質問 # 70
You have an Azure SQL database that supports a customer-facing API. The API calls a stored procedure named dbo.GetCustomerOrders thousands of times per hour.
After a deployment that updated indexes and statistics, users report that the API endpoint backed by dbo.GetCustomerOrders is slower. In Query Store, the same query now has two persisted execution plans. During the last hour, the newer plan had a significantly higher average duration and CPU time than the older plan.
You need to restore the previous performance quickly, without changing the API code.
Which Transact-SQL command should you run?
正解:A
解説:
We have encountered plan regression. This often happens after maintenance (like updating statistics) because the query optimizer generates a new execution plan that it thinks is better based on the new data distribution, but it ends up being less efficient in practice.
Since you've already identified the Plan ID for the faster plan and the Query ID from Query Store, you can force the "good" plan immediately using:
EXEC sp_query_store_force_plan @query_id = [YourQueryID], @plan_id = [YourFastPlanID]; Use code with caution.
This tells Azure SQL to ignore the new, slower plan and stick to the one that worked, providing an almost instant fix for your API's performance without requiring a code deployment.
Reference:
https://daxsws.com/blog/real-world-dynamics-365-performance-tuning-scenarios-and-fixes
質問 # 71
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear in the review screen.
You have a SQL database in Microsoft Fabric that contains a table named dbo.Orders.
dbo.Orders has a clustered index, contains three years of data, and is partitioned by a column named OrderDate by month.
You need to remove all the rows for the oldest month. The solution must minimize the impact on other queries that access the data in dbo.Orders.
Solution: Identify the partition number for the oldest month, and then run the following Transact- SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
Does this meet the goal?
正解:A
解説:
Correct:
* Identify the partition number for the oldest month, and then run the following Transact-SQL statement.
TRUNCATE TABLE dbo.Orders
WITH (PARTITIONS (partition number));
The best Transact-SQL statement to remove all rows for the oldest month while minimizing the impact on other queries is TRUNCATE TABLE with a WITH (PARTITIONS (...)) clause.
Why TRUNCATE TABLE ... WITH (PARTITIONS (...)) is Best
Efficiency: TRUNCATE TABLE is a Data Definition Language (DDL) operation that removes data by deallocating the data pages, which is a metadata operation and is very fast, regardless of the amount of data in the partition.
Minimal Logging: It uses less transaction log space compared to a DELETE statement, which logs each row deletion individually.
Low Impact on Concurrency: It performs a quick, partition-specific operation. A row-by-row DELETE would be a long-running transaction and could cause locking and blocking issues for other queries accessing the table.
Data Integrity: Because the table has a clustered index and is partitioned by the same column (aligned indexes), the TRUNCATE PARTITION operation is a fast, partition-level maintenance operation that targets only that specific data subset.
Incorrect:
* : Identify the partition scheme for the oldest month, and then run the following Transact-SQL statement.
ALTER TABLE dbo.Orders
DROP PARTITION SCHEME (partition_scheme_name);
The DROP PARTITION SCHEME statement removes the partition scheme object from the database but does not remove the data itself or free up the space, and it requires all tables to be moved off the scheme first, which is a complex operation. This does not meet the goal of removing the data efficiently.
* Run the following Transact-SQL statement.
DELETE FROM dbo.Orders
WHERE OrderDate < DATEADD(month, -36, SYSUTCDATETIME());
A standard DELETE statement, even with a WHERE clause that uses the partition column, can be a time-consuming, logged operation that causes locking and blocking on the main table, negatively impacting performance.
Reference:
https://stackoverflow.com/questions/63632963/truncate-partition-vs-drop-partition-performace- wise-which-one-is-efficient-an
質問 # 72
You are developing an Azure SQL solution by using Microsoft Visual Studio 2026. The solution uses a GitHub repository.
You plan to use GitHub Copilot Chat to access the GitHub repository tools by connecting to the GitHub MCP Server.
You need to configure Visual Studio to support the planned configuration. The solution must rely on OAuth to access the MCP server.
What should you create?
正解:A
解説:
In this scenario, you need to create an mcp.json file. This file acts as the configuration bridge that tells Visual Studio 2026 and GitHub Copilot Chat how to connect to and communicate with the GitHub MCP Server.
Key Configuration Details
The mcp.json file is typically placed in your solution's root directory or a specific .mcp folder to enable project-specific tools Configuration Steps
1. Create the MCP Configuration File
You must define the connection to the GitHub MCP server so Copilot Chat can interact with your repository tools.
File Name: mcp.json
Location: Usually placed in %AppData%\Microsoft\VisualStudio\2026\mcp.json (or the project root depending on your specific extension settings).
Content:
{
"mcpServers": {
"github": {
"url": "https://api.githubcopilot.com/mcp/",
"auth": "OAuth"
}
}
}
2. Authenticate via OAuth
3. Connect Azure SQL in VS 2026
Reference:
https://www.workato.com/the-connector/mcp-server-tutorial/
質問 # 73
You have an Azure SQL database that contains a table named dbo.Customers. dbo.Customers contains the following columns:
* CustomerId (int)(primary key)
* ProfileJson (nvarchar(max))
You have an application that returns phone numbers in a format of +000 000-000-0000. The phone numbers are stored in ProfileJson.
You need to write a query that returns:
* One row per customer
* A PhoneNUmerals column that contains only the digits
How should you complete the Transact-SQL query? To answer, drag the appropriate values to the correct targets. Each value may be used once, more than once, or not at all. You may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.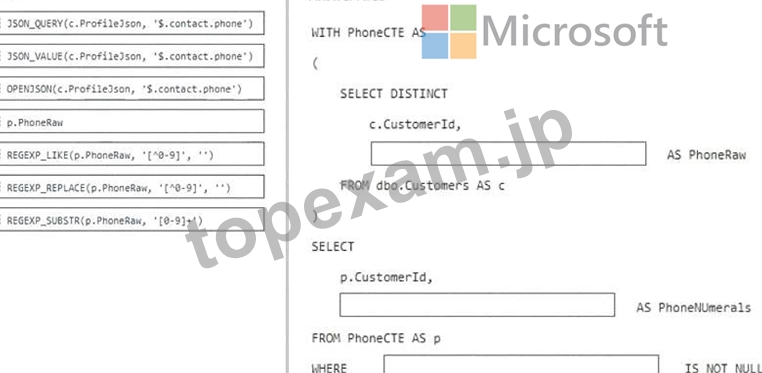
正解:
解説: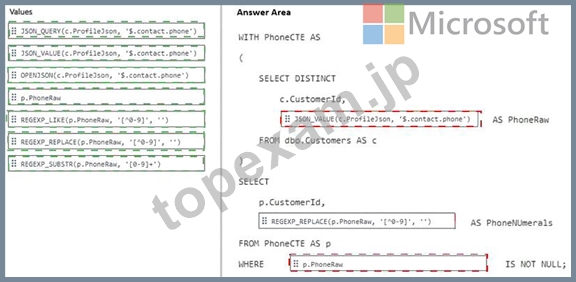
Explanation:
* PhoneRaw extraction # JSON_VALUE(c.ProfileJson, ' $.contact.phone ' )
* PhoneNumerals # REGEXP_REPLACE(p.PhoneRaw, ' [