2026 Latest VCEPrep DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=14CgV-_nBD1qiz_Kcnwrr2mGgVu8Yjfpx
Preparing with outdated DP-600 exam questions results in failure and loss of time and money. You can get success in the exam on first attempt and save your resources with the help of updated exam questions. We offer Microsoft DP-600 real questions to help pupils in getting ready for the exam in a short time. Students who choose VCEPrep will get the latest and updated exam questions they need to prepare for the DP-600 examination in a short time.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Exam Price: | $165 USD |
| Real Exam Qty: | 40-60 |
| Passing Score: | 700/1000 |
| Available Languages: | English, Japanese, Korean, Chinese (Simplified) |
| Exam Duration: | 120 minutes |
| Related Certifications: | Microsoft Certified: Fabric Analytics Engineer Associate |
| Certificate Validity Period: | 1 year |
| Exam Format: | Drag-and-drop, Multiple-choice, Case studies |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or in-person testing center |
| Pre Condition: | Candidates should have foundational knowledge of data concepts, experience with Microsoft Fabric, and proficiency in data transformation and modeling. Familiarity with Power BI is recommended but not required. |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/certifications/exams/dp-600 |
>> DP-600 Latest Dumps Sheet <<
Your opportunity to survey the Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam questions before buying it will relax your nerves. VCEPrep proudly declares that it will not disappoint you in providing the best quality Implementing Analytics Solutions Using Microsoft Fabric (DP-600) study material. The guarantee to give you the money back according to terms and conditions is one of the remarkable facilities of the VCEPrep.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 183
You have a Fabric workspace named Workspace1.
Workspace1 contains multiple semantic models, including a model named Model1. Model1 is updated by using an XMLA endpoint.
You need to increase the speed of the write operations of the XMLA endpoint.
What should you do?
Answer: B
Explanation:
https://learn.microsoft.com/en-us/power-bi/enterprise/service-premium-connect-tools#optimize- semantic-models-for-write-operations-by-enabling-large-models
NEW QUESTION # 184
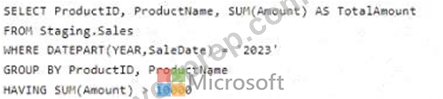
You have a Fabric warehouse that contains a table named Staging.Sales. Staging.Sales contains the following columns.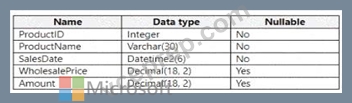
You need to write a T-SQL query that will return data for the year 2023 that displays ProductID and ProductName arxl has a summarized Amount that is higher than 10,000. Which query should you use?
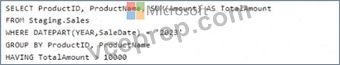
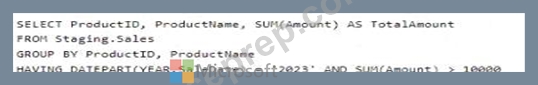
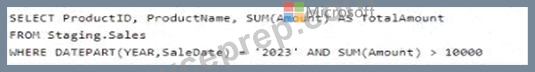
Answer: B
Explanation:
The correct query to use in order to return data for the year 2023 that displays ProductID, ProductName, and has a summarized Amount greater than 10,000 is Option B. The reason is that it uses the GROUP BY clause to organize the data by ProductID and ProductName and then filters the result using the HAVING clause to only include groups where the sum of Amount is greater than 10,000. Additionally, the DATEPART(YEAR, SaleDate) = '2023' part of the HAVING clause ensures that only records from the year 2023 are included.
References = For more information, please visit the official documentation on T-SQL queries and the GROUP BY clause at T-SQL GROUP BY.
NEW QUESTION # 185
You have source data in a CSV file that has the following fields:
* SalesTra nsactionl D
* SaleDate
* CustomerCode
* CustomerName
* CustomerAddress
* ProductCode
* ProductName
* Quantity
* UnitPrice
You plan to implement a star schema for the tables in WH1. Thedimension tables in WH1 will implement Type 2 slowly changing dimension (SCD) logic.
You need to design the tables that will be used for sales transaction analysis and load the source data.
Which type of target table should you specify for the CustomerName, CustomerCode, and SaleDate fields?
To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.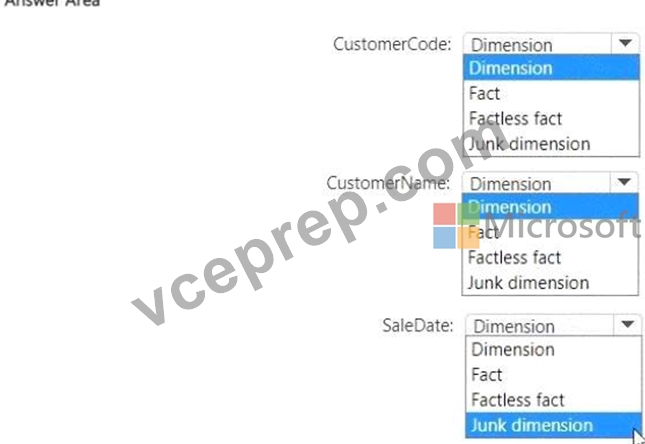
CC
Answer:
Explanation: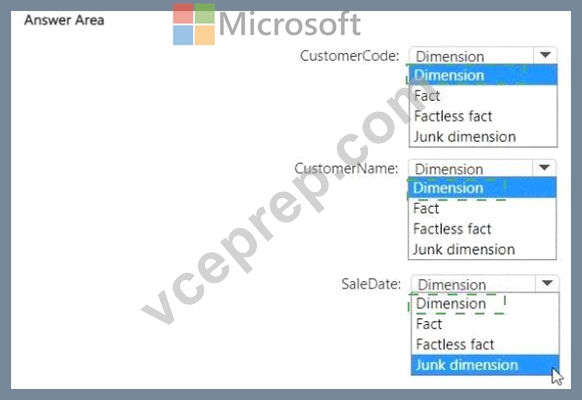
Explanation: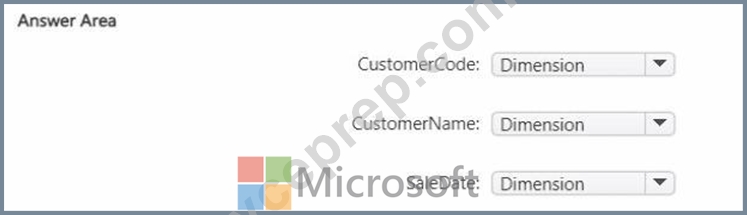
We are designing a star schema for sales transactions. In a star schema:
Dimension tables contain descriptive attributes (e.g., Customer, Product, Date).
Fact tables contain measurable, quantitative data (e.g., SalesTransactionID, Quantity, UnitPrice).
Factless fact tables capture events without numeric measures.
Junk dimensions store miscellaneous low-cardinality attributes.
The requirement says dimension tables will use Type 2 Slowly Changing Dimensions (SCD) # so Customer and Date attributes belong to Dimension tables.
Field-by-field classification
CustomerCode
A business key (natural key) for the customer dimension.
Belongs in the Customer Dimension table.
The Answer:
Dimension.
CustomerName
A descriptive attribute of the customer.
Belongs in the Customer Dimension table.
The Answer:
Dimension.
SaleDate
A time attribute used for analysis.
Belongs in the Date Dimension table.
The Answer:
Dimension.
Final Answer:
CustomerCode # Dimension
CustomerName # Dimension
SaleDate # Dimension
References:
Star schema design for Power BI / Fabric
Slowly Changing Dimensions in data warehousing
# This follows Kimball's star schema best practices.
NEW QUESTION # 186
You have a Fabric workspace that contains a large warehouse.
You plan to create a lakehouse named Lakehousel for a sales dataset. Lakehousel will contain the following tables:
* Sales: Contains sales transactions
* Stores: Contains a unique list of store names and locations
* Loyalty: Contains a list of customers and their preferred stores
* Customers: Contains a unique list of customer names and addresses
* Products: Contains a unique list of available products and their descriptions You need to configure a star schema for Lakehousel.
Which table should you define as the fact table, and which type of relationship should you configure from the Sales table to the Customers table? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.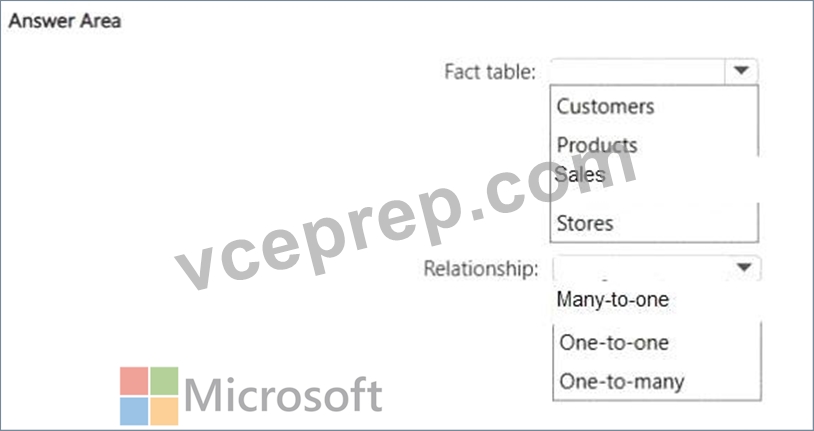
Answer:
Explanation: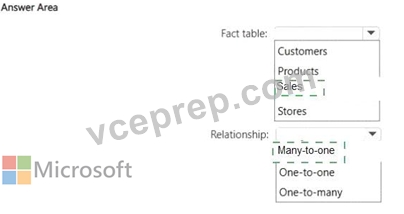
Explanation: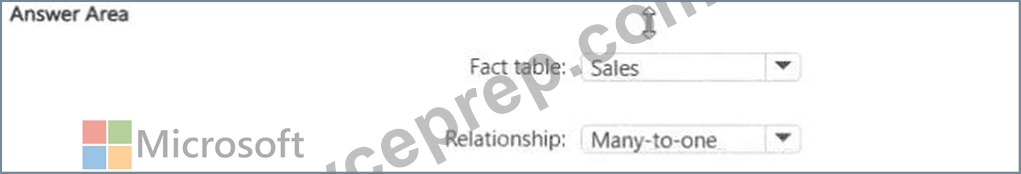
NEW QUESTION # 187
You have a Fabric tenant that contains a warehouse.
You are designing a star schema model that will contain a customer dimension. The customer dimension table will be a Type 2 slowly changing dimension (SCD).
You need to recommend which columns to add to the table. The columns must NOT already exist in the source.
Which three types of columns should you recommend? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
Answer: A,B,E
Explanation:
To create SCD type 2 one needs to add a surrogate key + start/end date beside the other technical attributes.
https://learn.microsoft.com/en-us/training/modules/populate-slowly-changing-dimensions-azure- synapse-analytics-pipelines/3-choose-between-dimension-types
NEW QUESTION # 188
......
DP-600 Reliable Exam Papers: https://www.vceprep.com/DP-600-latest-vce-prep.html
BONUS!!! Download part of VCEPrep DP-600 dumps for free: https://drive.google.com/open?id=14CgV-_nBD1qiz_Kcnwrr2mGgVu8Yjfpx