2026 Latest VCEDumps Databricks-Certified-Data-Engineer-Associate PDF Dumps and Databricks-Certified-Data-Engineer-Associate Exam Engine Free Share: https://drive.google.com/open?id=1WLTHMzWxTiTxux0uMTcdnZ6FWgOR_lL5
Our company will promptly update our Databricks-Certified-Data-Engineer-Associate exam materials based on the changes of the times and then send it to you timely. 99% of people who use our learning materials have passed the exam and successfully passed their certificates, which undoubtedly show that the passing rate of our Databricks-Certified-Data-Engineer-Associate Test Torrent is 99%. If you fail the exam, we promise to give you a full refund in the shortest possible time. So our product is a good choice for you. Choosing our Databricks-Certified-Data-Engineer-Associate study tool can help you learn better. You will gain a lot and lay a solid foundation for success.
| Section | Objectives |
|---|---|
| Productionizing Data Pipelines | - Pipeline deployment and operationalization - Scheduling and monitoring jobs - Databricks Workflows / Jobs orchestration |
| Data Ingestion and ELT Development | - Handling structured and semi-structured data - Data ingestion using Spark SQL and PySpark - ETL patterns and transformations |
| Data Processing and Transformations | - Apache Spark SQL operations (joins, aggregations, filtering) - PySpark DataFrame transformations - Delta Lake fundamentals (tables, transactions, optimization) - User-defined functions (UDFs) |
| Data Governance and Quality | - Unity Catalog basics - Data access control and governance - Data quality concepts and management |
| Databricks Lakehouse Platform Fundamentals | - Workspace, architecture, and core platform concepts - Clusters, notebooks, and basic Databricks environment usage |
>> Databricks Databricks-Certified-Data-Engineer-Associate Valid Exam Dumps <<
We have always been known as the superior after sale service provider, since we all tend to take lead of the whole process after you choose our Databricks-Certified-Data-Engineer-Associate exam questions. So you have no need to trouble about our Databricks-Certified-Data-Engineer-Associate learning guide. Our Databricks-Certified-Data-Engineer-Associate training materials will continue to pursue our passion for better performance and comprehensive service of Databricks-Certified-Data-Engineer-Associate Exam. Our worldwide after sale staff will be online and reassure your rows of doubts as well as exclude the difficulties and anxiety with all the customers. Just let us know your puzzles and we will figure out together.
NEW QUESTION # 192
A Delta table sales_fact is frequently queried with predicates on store_id and transaction_date.
Query performance has degraded because the table contains a very large number of small files.
Which command improves read performance for these query patterns?
Answer: C
Explanation:
OPTIMIZE compacts small files into larger ones, and ZORDER BY co-locates related column values in the same files so data skipping can prune more files for predicates on those columns.
VACUUM only removes unreferenced files and does not improve layout.
NEW QUESTION # 193
A data engineering team has noticed that their Databricks SQL queries are running too slowly when they are submitted to a non-running SQL endpoint. The data engineering team wants this issue to be resolved.
Which of the following approaches can the team use to reduce the time it takes to return results in this scenario?
Answer: C
Explanation:
Option D is the correct answer because it enables the Serverless feature for the SQL endpoint, which allows the endpoint to automatically scale up and down based on the query load. This way, the endpoint can handle more concurrent queries and reduce the time it takes to return results. The Serverless feature also reduces the cold start time of the endpoint, which is the time it takes to start the cluster when a query is submitted to a non-running endpoint. The Serverless feature is available for both AWS and Azure Databricks platforms.
References: Databricks SQL Serverless, Serverless SQL endpoints, New Performance Improvements in Databricks SQL
NEW QUESTION # 194
Which of the following Structured Streaming queries is performing a hop from a Silver table to a Gold table?
Answer: D
Explanation:
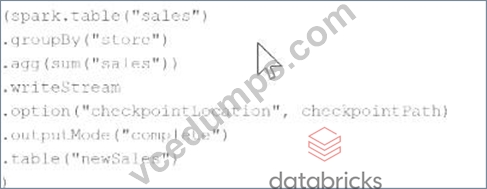
The best practice is to use " Complete " as output mode instead of " append " when working with aggregated tables. Since gold layer is work final aggregated tables, the only option with output mode as complete is option E.
NEW QUESTION # 195
Which query is performing a streaming hop from raw data to a Bronze table?
Answer: B
Explanation:
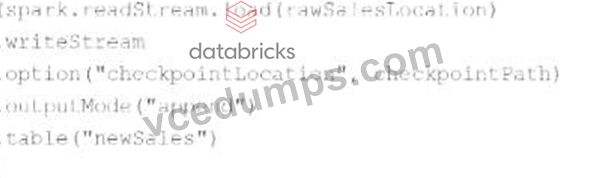
The query performing a streaming hop from raw data to a Bronze table is identified by using the Spark streaming read capability and then writing to a Bronze table. Let's analyze the options:
* Option A: Utilizes .writeStream but performs a complete aggregation which is more characteristic of a roll-up into a summarized table rather than a hop into a Bronze table.
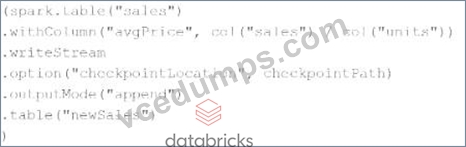
* Option B: Also uses .writeStream but calculates an average, which again does not typically represent the raw to Bronze transformation, which usually involves minimal transformations.
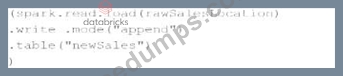
* Option C: This uses a basic .write with .mode("append") which is not a streaming operation, and hence not suitable for real-time streaming data transformation to a Bronze table.
* Option D: It employs spark.readStream.load() to ingest raw data as a stream and then writes it out with .writeStream, which is a typical pattern for streaming data into a Bronze table where raw data is captured in real-time and minimal transformation is applied. This approach aligns with the concept of a Bronze table in a modern data architecture, where raw data is ingested continuously and stored in a more accessible format.
References:Databricks documentation on Structured Streaming: Structured Streaming in Databricks
NEW QUESTION # 196
A data engineering team is designing the Gold layer in their Unity Catalog-governed lakehouse for downstream BI and analytics users. The team wants to expose business-ready metrics with fast query performance and consistent definitions, while keeping the transformation logic in Spark notebooks. Which type of Gold layer object meets this requirement?
Answer: C
Explanation:
A materialized view stores precomputed Gold-layer aggregations, providing BI tools with fast queries and centrally defined, consistent business results while allowing the transformation logic to remain in Databricks notebooks.
NEW QUESTION # 197
......
Our technician will check the update of Databricks-Certified-Data-Engineer-Associate exam questions every day, and we can guarantee that you can get a free update service from the date of purchase. Once you have any questions and doubts about the Databricks-Certified-Data-Engineer-Associate exam questions we will provide you with our customer service before or after the sale, you can contact us if you have question or doubt about our Databricks-Certified-Data-Engineer-Associate Exam Materials and the professional personnel can help you solve your issue about using Databricks-Certified-Data-Engineer-Associate study materials.
Latest Databricks-Certified-Data-Engineer-Associate Examprep: https://www.vcedumps.com/Databricks-Certified-Data-Engineer-Associate-examcollection.html
P.S. Free & New Databricks-Certified-Data-Engineer-Associate dumps are available on Google Drive shared by VCEDumps: https://drive.google.com/open?id=1WLTHMzWxTiTxux0uMTcdnZ6FWgOR_lL5