P.S. Free & New Certified-Data-Engineer-Professional dumps are available on Google Drive shared by PassTorrent: https://drive.google.com/open?id=16E95Voive5WDlJU8Og_MTllRJ3uZRCso
We even guarantee our customers that they will pass Databricks Certified-Data-Engineer-Professional exam easily with our provided study material and if they failed to do it despite all their efforts they can claim a full refund of their money (terms and conditions apply). The third format is the desktop software format which can be accessed after installing the software on your Windows computer or laptop. The Databricks Certified Data Engineer Professional (Certified-Data-Engineer-Professional) has three formats so that the students don't face any serious problems and prepare themselves with fully focused minds.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Cost and Performance Optimization | ~13% | - Leverage system tables and observability tools - Optimize queries, clusters, and storage |
| Topic 2: Streaming Workloads and Change Data Capture | ~11% | - Implement reliable streaming pipelines - Apply AUTO CDC APIs and exactly-once semantics |
| Topic 3: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 4: CI/CD, Testing, and Deployment | ~6% | - Deploy with Declarative Automation Bundles, CLI, and REST API - Implement testing and deployment pipelines |
| Topic 5: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 6: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Topic 7: Developing Code for Data Processing using Python and SQL | ~22% | - Implement scalable Python/SQL code and project structures - Manage dependencies, libraries, and UDFs - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Topic 8: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 9: Data Transformation, Cleansing, and Quality | ~12% | - Apply advanced Spark transformations - Enforce data quality and quarantine bad data |
>> Dumps Certified-Data-Engineer-Professional Download <<
We have full confidence of your success in exam. It is ensured with 100% money back guarantee. Get the money you paid to buy our exam dumps back if they do not help you pass the exam. To know the style and quality of exam Certified-Data-Engineer-Professional Test Dumps, download the content from our website, free of cost. These free brain dumps will serve you the best to compare them with all available sources and select the most advantageous preparatory content for you. We are always efficient and give you the best support. You can contact us online any time for information and support for your exam related issues. Our devoted staff will respond you 24/7.
NEW QUESTION # 107
A junior developer complains that the code in their notebook isn't producing the correct results in the development environment. A shared screenshot reveals that while they're using a notebook versioned with Databricks Repos, they're using a personal branch that contains old logic. The desired branch named dev-2.3.9 is not available from the branch selection dropdown.
Which approach will allow this developer to review the current logic for this notebook?
Answer: D
Explanation:
This is the correct answer because it will allow the developer to update their local repository with the latest changes from the remote repository and switch to the desired branch. Pulling changes will not affect the current branch or create any conflicts, as it will only fetch the changes and not merge them. Selecting the dev-2.3.9 branch from the dropdown will checkout that branch and display its contents in the notebook.
NEW QUESTION # 108
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
Answer: A
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 109
Which of the following is true of Delta Lake and the Lakehouse?
Answer: C
Explanation:
Delta Lake automatically collects statistics on the first 32 columns of each table, which are leveraged in data skipping based on query filters. Data skipping is a performance optimization technique that aims to avoid reading irrelevant data from the storage layer. By collecting statistics such as min/max values, null counts, and bloom filters, Delta Lake can efficiently prune unnecessary files or partitions from the query plan. This can significantly improve the query performance and reduce the I/O cost.
NEW QUESTION # 110
The following table consists of items found in user carts within an e-commerce website.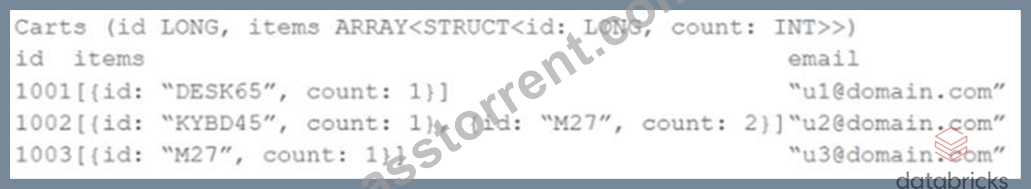
The following MERGE statement is used to update this table using an updates view, with schema evolution enabled on this table.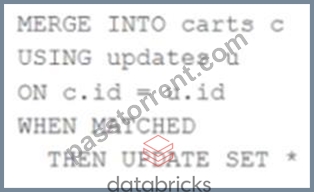
How would the following update be handled?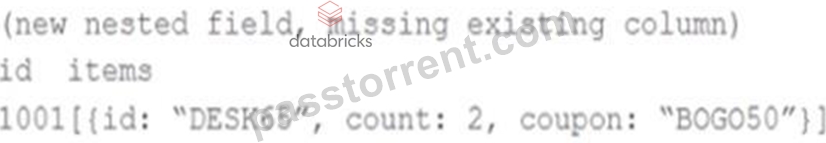
Answer: B
Explanation:
With schema evolution enabled in Databricks Delta tables, when a new field is added to a record through a MERGE operation, Databricks automatically modifies the table schema to include the new field. In existing records where this new field is not present, Databricks will insert NULL values for that field. This ensures that the schema remains consistent across all records in the table, with the new field being present in every record, even if it is NULL for records that did not originally include it.
NEW QUESTION # 111
A data engineer wants to join a stream of advertisement impressions (when an ad was shown) with another stream of user clicks on advertisements to correlate when impression led to monitizable clicks.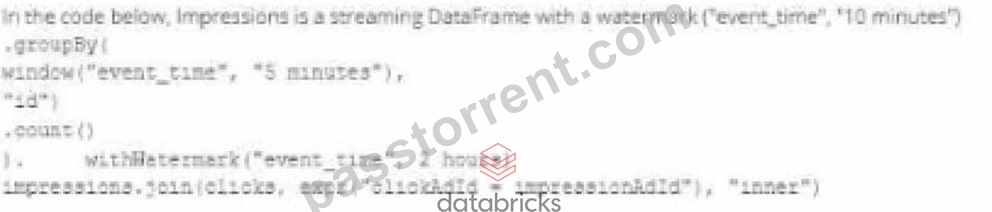
Which solution would improve the performance?




Answer: D
Explanation:
When joining a stream of advertisement impressions with a stream of user clicks, you want to minimize the state that you need to maintain for the join. Option A suggests using a left outer join with the condition that clickTime == impressionTime, which is suitable for correlating events that occur at the exact same time. However, in a real-world scenario, you would likely need some leeway to account for the delay between an impression and a possible click. It's important to design the join condition and the window of time considered to optimize performance while still capturing the relevant user interactions. In this case, having the watermark can help with state management and avoid state growing unbounded by discarding old state data that's unlikely to match with new data.
NEW QUESTION # 112
......
With the help of the Certified-Data-Engineer-Professional practice exam questions and preparation material offered by PassTorrent, you can pass any Certified-Data-Engineer-Professional certifications exam in the first attempt. You don’t have to face any trouble, and you can simply choose to do a selective Certified-Data-Engineer-Professional brain dumps to pass the exam. We offer guaranteed success with Certified-Data-Engineer-Professional Questions on the first attempt, and you will be able to pass the Certified-Data-Engineer-Professional exam in short time. You can always consult our Certified-Data-Engineer-Professional certified professional support if you are facing any problems.
Trustworthy Certified-Data-Engineer-Professional Exam Content: https://www.passtorrent.com/Certified-Data-Engineer-Professional-latest-torrent.html
2026 Latest PassTorrent Certified-Data-Engineer-Professional PDF Dumps and Certified-Data-Engineer-Professional Exam Engine Free Share: https://drive.google.com/open?id=16E95Voive5WDlJU8Og_MTllRJ3uZRCso