P.S. Kostenlose 2026 Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsfragen sind auf Google Drive freigegeben von PrüfungFrage verfügbar: https://drive.google.com/open?id=1wL4LeApIh6--Nrfq8ZhTHUUC6q9NP3jk
Zurzeit ist Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung eine sehr populäre Prüfung. Wollen die Databricks-Certified-Professional-Data-Engineer Zeritifizierungsprüfung ablegen? Tatsächlich ist diese Prüfung sehr schwierig. Aber es bedeutet nicht, dass Sie diese Prüfung mit guter Note bestehen können. Wollen Sie die Methode, die Databricks-Certified-Professional-Data-Engineer Prüfung sehr leicht zu bestehen, kennenzulernen? Das ist Databricks Databricks-Certified-Professional-Data-Engineer dumps von PrüfungFrage.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Delta Lake | 20-25% | - Delta Lake fundamentals
|
| Topic 2: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 3: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Topic 4: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Topic 5: Data Ingestion | 15-20% | - Streaming ingestion
|
>> Databricks-Certified-Professional-Data-Engineer Lerntipps <<
Sie können jetzt Databricks Databricks-Certified-Professional-Data-Engineer Zertifikat erhalten. Unser PrüfungFrage bietet die neue Version von Databricks Databricks-Certified-Professional-Data-Engineer Prüfung. Sie brauchen nicht mehr, die neuesten Schulungsunterlagen von Databricks Databricks-Certified-Professional-Data-Engineer zu suchen. Weil Sie die besten Schulungsunterlagen von Databricks Databricks-Certified-Professional-Data-Engineer gefunden haben. Benutzen Sie beruhigt unsere Databricks-Certified-Professional-Data-Engineer Schulungsunterlagen. Sie werden sicher die Databricks Databricks-Certified-Professional-Data-Engineer Zertifizierungsprüfung bestehen.
47. Frage
A transactions table has been liquid clustered on the columns product_id, user_id, and event_date.
Which operation lacks support for cluster on write?
Antwort: D
Begründung:
Delta Lake'sLiquid Clusteringis an advanced feature that improves query performance by dynamically clustering data without requiring costly compaction steps like traditional Z-ordering.
When performing writes to aLiquid Clusteredtable, some write operations automatically maintain clustering, while othersdo not.
Explanation of Each Option:
* (A) spark.writestream.format('delta').mode('append') (Correct Answer)
* Reason:Streaming writes (writestream) donotsupportLiquid Clusteringbecause streaming data arrives in micro-batches.
* Since Liquid Clustering needs efficient global reorganization of files, streaming append operations don't provide sufficient data volume at a time to be effectively clustered.
* Delta Lake documentation states that Liquid Clustering is only supported for batch writes.
* (B) CTAS and RTAS statements
* Reason:CREATE TABLE AS SELECT (CTAS) and REPLACE TABLE AS SELECT (RTAS) are batch operationsand can enforce Liquid Clustering.
* These operations create or replace a table based on a query result, and since they are batch-based, Liquid Clustering applies.
* (C) INSERT INTO operations
* Reason:INSERT INTOis supportedfor Liquid Clustering because it is a batch operation.
* While it may not be as efficient as MERGE or COPY INTO, clustering is applied upon execution.
* (D) spark.write.format('delta').mode('append')
* Reason:Batch append operationsare supportedfor Liquid Clustering.
* Unlike streaming append, batch writes allow the optimizer to re-cluster data efficiently.
Conclusion:
Sincestreaming append operations do not support Liquid Clustering, option(A)is the correct answer.
References:
* Liquid Clustering in Delta Lake - Databricks Documentation
48. Frage
The data engineering team maintains the following code:
Assuming that this code produces logically correct results and the data in the source tables has been de- duplicated and validated, which statement describes what will occur when this code is executed?
Antwort: B
Begründung:
The provided PySpark code performs the following operations:
* Reads Data from silver_customer_sales Table:
* The code starts by accessing the silver_customer_sales table using the spark.table method.
* Groups Data by customer_id:
* The .groupBy( " customer_id " ) function groups the data based on the customer_id column.
* Aggregates Data:
* The .agg() function computes several aggregate metrics for each customer_id:
* F.min( " sale_date " ).alias( " first_transaction_date " ): Determines the earliest sale date for the customer.
* F.max( " sale_date " ).alias( " last_transaction_date " ): Determines the latest sale date for the customer.
* F.mean( " sale_total " ).alias( " average_sales " ): Calculates the average sale amount for the customer.
* F.countDistinct( " order_id " ).alias( " total_orders " ): Counts the number of unique orders placed by the customer.
* F.sum( " sale_total " ).alias( " lifetime_value " ): Calculates the total sales amount (lifetime value) for the customer.
* Writes Data to gold_customer_lifetime_sales_summary Table:
* The .write.mode( " overwrite " ).table( " gold_customer_lifetime_sales_summary " ) command writes the aggregated data to the gold_customer_lifetime_sales_summary table.
* The mode( " overwrite " ) specifies that the existing data in the
gold_customer_lifetime_sales_summary table will be completely replaced by the new aggregated data.
Conclusion:
When this code is executed, it reads all records from the silver_customer_sales table, performs the specified aggregations grouped by customer_id, and then overwrites the entire gold_customer_lifetime_sales_summary table with the aggregated results. Therefore, option D accurately describes this process: " The gold_customer_lifetime_sales_summary table will be overwritten by aggregated values calculated from all records in the silver_customer_sales table as a batch job. " References:
PySpark DataFrame groupBy
PySpark Basics
49. Frage
A junior data engineer on your team has implemented the following code block.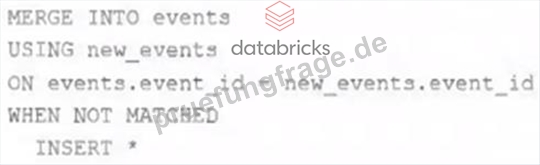
The viewnew_eventscontains a batch of records with the same schema as theeventsDelta table.
Theevent_idfield serves as a unique key for this table.
When this query is executed, what will happen with new records that have the sameevent_idas an existing record?
Antwort: C
Begründung:
Explanation
This is the correct answer because it describes what will happen with new records that have the same event_id as an existing record when the query is executed. The query uses the INSERT INTO command to append new records from the view new_events to the table events. However, the INSERT INTO command does not check for duplicate values in the primary key column (event_id) and does not perform any update or delete operations on existing records. Therefore, if there are new records that have the same event_id as an existing record, they will be ignored and not inserted into the table events. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Append data using INSERT INTO" section.
50. Frage
The data engineering team maintains the following code: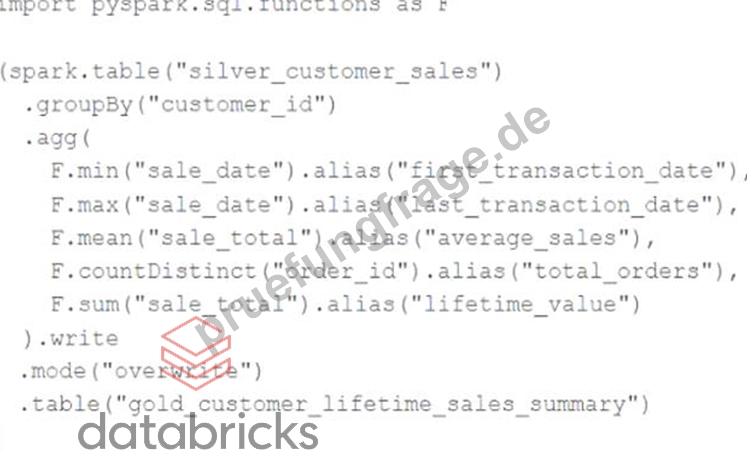
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Antwort: C
Begründung:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids.
The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. References:
* https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
* https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
51. Frage
A data engineering team is configuring access controls in Databricks Unity Catalog . They grant the SELECT privilege on the sales catalog to the analyst_group, expecting that members of this group will automatically have SELECT access to all current and future schemas, tables, and views within the catalog.
What describes the privilege inheritance behavior in Unity Catalog?
Antwort: C
Begründung:
In Unity Catalog, privileges are non-cascading -meaning that granting a privilege (like SELECT) on a catalog does not automatically grant the same privilege on contained objects (schemas, tables, or views). Each object type has its own independent access control hierarchy.
According to the Databricks access control documentation: "Privileges do not automatically cascade from catalog to schema or table levels." Administrators must explicitly grant privileges on each level if users need access across objects. This design ensures tighter governance and least-privilege enforcement. Therefore, option B correctly describes Unity Catalog's privilege model, while A and D incorrectly imply automatic inheritance.
52. Frage
......
Um Sie beim Kauf der Databricks Databricks-Certified-Professional-Data-Engineer Prüfungssoftware beruhigt zu lassen, wenden wir die gesicherteste Zahlungsmittel an. Paypal ist das größte internationale Zahlungssystem. Und wir bewahren sorgfältig Ihre persönliche Informationen. Wenn Sie Fragen über die Databricks Databricks-Certified-Professional-Data-Engineer Prüfungsunterlagen oder Interesse an anderen Prüfungssoftwaren haben, könnten Sie diret mit uns online kontaktieren oder uns E-Mail schicken. Wir tun unser Bestes, um Ihnen bei der Databricks Databricks-Certified-Professional-Data-Engineer Prüfung zu helfen.
Databricks-Certified-Professional-Data-Engineer Testengine: https://www.pruefungfrage.de/Databricks-Certified-Professional-Data-Engineer-dumps-deutsch.html
Außerdem sind jetzt einige Teile dieser PrüfungFrage Databricks-Certified-Professional-Data-Engineer Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1wL4LeApIh6--Nrfq8ZhTHUUC6q9NP3jk