DOWNLOAD the newest iPassleader DP-800 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1x50mVaTsazK_ggblVjC7-tdREe7_jUEF
Nowadays in this talented society DP-800 professionals are very popular, but the IMicrosoft area are also very competitive. So many Microsoft professionals through passing difficult DP-800 Certification exams to stabilize themselves. iPassleader is websites specifically provide convenience for candidates participating in the DP-800 certification exams.
| Section | Objectives |
|---|---|
| Develop and manage database solutions | - Optimize performance and scalability - Ensure security and compliance of data solutions |
| Design and implement data solutions | - Implement data storage and data processing solutions - Design database solutions using Azure data services |
| Integrate AI capabilities with database systems | - Implement AI-assisted data processing - Use Azure AI services with database workloads |
| Monitor, troubleshoot, and maintain solutions | - Troubleshooting data pipeline issues - Monitoring database health and performance |
>> DP-800 Certification Dump <<
The iPassleader Developing AI-Enabled Database Solutions (DP-800) PDF dumps file is a collection of real, valid, and updated DP-800 practice questions that are also easy to install and use. The DP-800 PDF dumps file can be installed on a desktop computer, laptop, and even on your smartphone devices. Just download iPassleader Developing AI-Enabled Database Solutions in DP-800 PDF Questions on your desired device and start Microsoft DP-800 exam dumps preparation today.
NEW QUESTION # 73
You have an Azure SQL database named SalesDB that contains tables named Sales.Orders and Sales.
OrderLines. Both tables contain sales data
You have a Retrieval Augmented Generation (RAG) service that queries SalesDB to retrieve order details and passes the results to a large language model (ILM) as JSON text. The following is a sample of the JSON.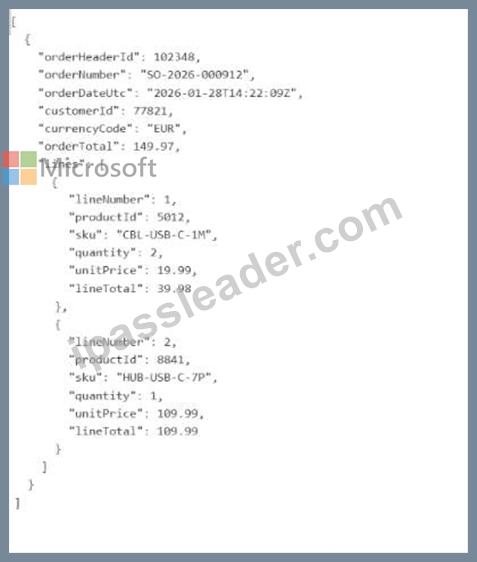
You need to return one 1SON document per order that includes the order header fields and an array of related order lines. The LIM must receive a single JSON array of orders, where each order contains a lines property that is a JSON array of line Items.
Which transact-SQL commands should you use to produce the required JSON shape from the relational tables? To answer, drag the appropriate commands to the correct operations. Each command may be used once, more than once, or not at all. Vou may need to drag the split bar between panes or scroll to view content.
NOTE: Each correct selection is worth one point.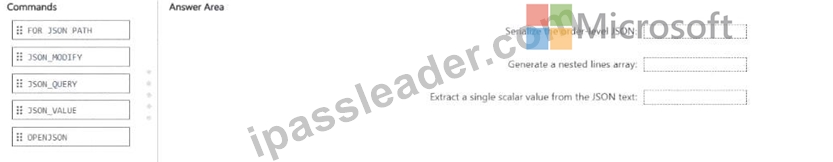
Answer:
Explanation: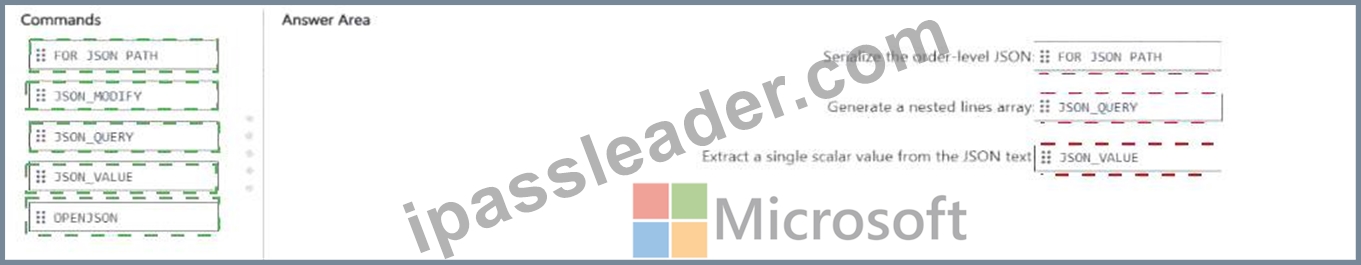
Explanation:
* Serialize the order-level JSON : FOR JSON PATH
* Generate a nested lines array : JSON_QUERY
* Extract a single scalar value from the JSON text : JSON_VALUE
The correct mapping is based on how SQL Server and Azure SQL JSON functions are designed to shape relational data into JSON for AI and RAG scenarios.
To serialize the order-level JSON , use FOR JSON PATH . Microsoft documents that FOR JSON PATH gives you full control over the JSON output shape and formats the result as an array of JSON objects . It is the standard way to turn relational query results into the JSON structure needed by downstream consumers such as APIs and LLM-based RAG services. It also supports nested output through subqueries and aliases.
To generate a nested lines array , use JSON_QUERY . Microsoft explains that JSON_QUERY returns a JSON object or array from JSON text, and it is used when you want to preserve a JSON fragment instead of treating it as plain text. In this scenario, the nested lines property must be emitted as a proper JSON array inside each order document, so JSON_QUERY is the correct command to embed that array in the final JSON shape.
To extract a single scalar value from the JSON text , use JSON_VALUE . Microsoft explicitly states that JSON_VALUE extracts a scalar value from a JSON string, while JSON_QUERY is for objects or arrays. So whenever the requirement is to pull out one property such as an order number, currency code, or customer ID from JSON text, JSON_VALUE is the correct function.
The unused commands are not the best fit here:
* OPENJSON is primarily for parsing JSON into rows and columns, not for shaping relational tables into nested output.
* JSON_MODIFY is for updating JSON text, not generating the required output structure.
So the drag-and-drop answers are:
* Serialize the order-level JSON # FOR JSON PATH
* Generate a nested lines array # JSON_QUERY
* Extract a single scalar value from the JSON text # JSON_VALUE
NEW QUESTION # 74
You have an SDK-style SQL database project stored in a Git repository. The project targets an Azure SQL database.
The CI build fails with unresolved reference errors when the project ieferences system objects.
You need to update the SQL database project to ensure that dotnet build validates successfully by including the correct system objects in the database model for Azure SQL Database.
Solution: Add the Microsoft.SqlServer.Dacpacs.Mastet NuGet package to the project.
Does this meet the goal?
Answer: A
Explanation:
The package named Microsoft.SqlServer.Dacpacs.Master is the generic master system DACPAC package, but the question requires the correct system objects for Azure SQL Database . Microsoft's system-objects documentation distinguishes platform-specific system references, and for Azure SQL Database the correct package is the Azure-specific master DACPAC , not the generic master package.
So adding Microsoft.SqlServer.Dacpacs.Master does not meet the goal for an Azure SQL Database- targeted SDK-style project. The expected package is the Azure-specific one.
NEW QUESTION # 75
You have an Azure subscription. The subscription contains an Azure SQL database named SalesDB and an Azure App Service app named sales-api. sales-api uses virtual network integration to a subnet named vnet- prod/subnet-app and reads from SalesDB You need to configure authentication and network access to meet the following requirements:
* Ensure that sales-api connects to SalesDB by using passwordless authentication.
* Ensure that all the database traffic remains within the subscription.
The solution must minimize administrative effort
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.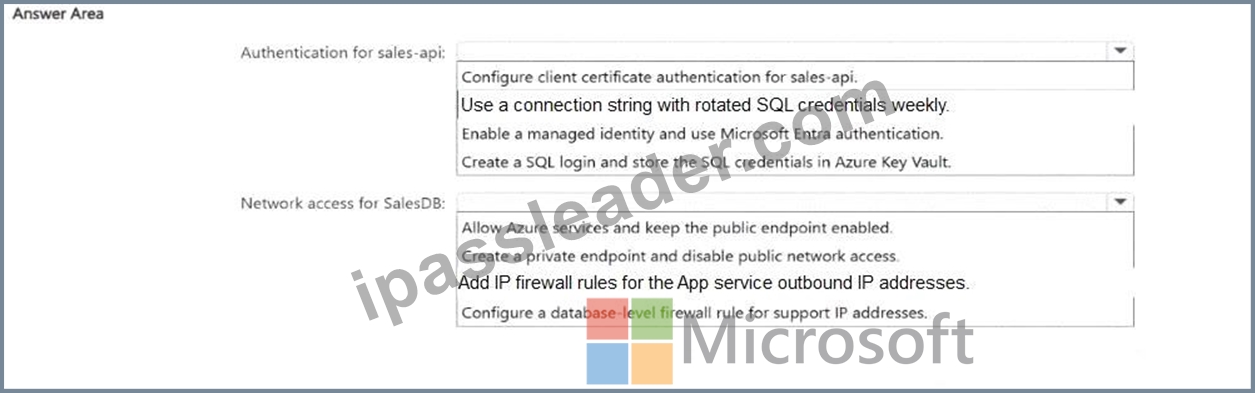
Answer:
Explanation: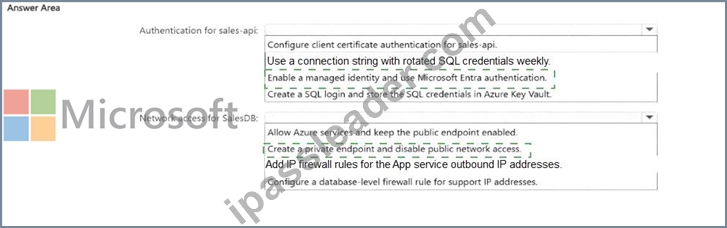
Explanation: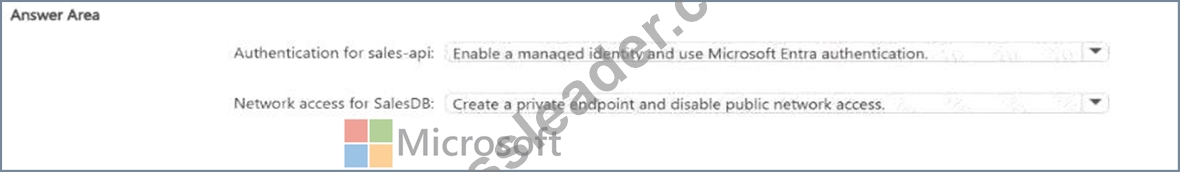
For authentication , the correct choice is Enable a managed identity and use Microsoft Entra authentication . Azure App Service supports managed identity, and Microsoft documents this as the recommended way to connect to Azure SQL Database without passwords or secrets . This minimizes administrative effort because there are no SQL passwords to rotate, store, or manage.
For network access , the correct choice is Create a private endpoint and disable public network access .
Microsoft documents that when public network access is disabled , Azure SQL Database only accepts connections through private endpoints . That keeps the database traffic on Azure private networking rather than exposing it through the public endpoint. Microsoft also notes that simply adding a private endpoint does not disable public access by itself, so disabling public network access is part of the correct configuration.
The other options are weaker:
* Rotated SQL credentials or storing SQL logins in Key Vault still use passwords and create more admin overhead.
* Allowing Azure services, adding outbound IP firewall rules, or database firewall rules still rely on the public endpoint , so they do not best satisfy the requirement that database traffic remain within the subscription.
NEW QUESTION # 76
You have a GitHub Actions workflow that builds and deploys an Azure SQL database. The schema is stored in a GitHub repository as an SDK-style SQL database project.
Following a code review, you discover that you need to generate a report that shows whether the production schema has diverged from the model in source control.
Which action should you add to the pipeline?
Answer: B
Explanation:
Microsoft documents that DriftReport creates an XML report showing changes that have been made to the registered database since it was last registered . That is the action intended to detect whether the production schema has diverged from the expected model baseline in your deployment workflow.
This is different from DeployReport , which shows the changes that would be made by a publish action . In other words:
* DriftReport answers: Has the deployed database drifted from the registered state/model?
* DeployReport answers: What changes would be applied if I published now?
The other options are not the right fit:
* Extract creates a DACPAC from an existing database, not a drift analysis report.
* Script generates a deployment script, not a schema-drift report.
So to generate a report that shows whether production has diverged from the model in source control , add:
SqlPackage.exe /Action:DriftReport
NEW QUESTION # 77
Hotspot Question
You have a SQL database in Microsoft Fabric that contains the following functions:
- A multi-statement table-valued function (TVF) named
Sales.mstvf_OrderStatus() that returns order status information
- A scalar user-defined function (UDF) named dbo.ufn_GetTaxMultiplier
(@TaxAmt money, @StateCode char(2)) that returns a numeric multiplier
used in tax calculations
Reporting queries frequently join Sales.mstvf_OrderStatus() to a table named Sales.SalesOrderHeader and return large result sets. A performance review shows that the queries produce inconsistent execution plans.
During a code review, a developer discovers that the following Transact-SQL statement produced an error.
EXEC @ret = ufn_GetTaxMultiplier @TaxAmt = 100.00, @StateCode = 'WA';
For each of the following statements, select Yes if the statement is true. Otherwise, select No.
NOTE: Each correct selection is worth one point.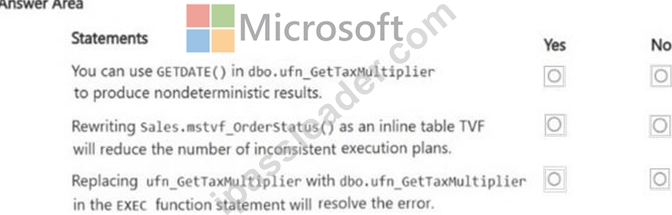
Answer:
Explanation: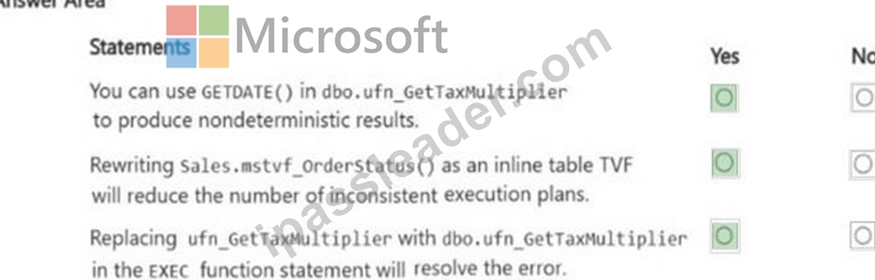
NEW QUESTION # 78
......
Where there is life, there is hope. Never abandon yourself. You still have many opportunities to counterattack. If you are lack of knowledge and skills, our DP-800 study materials are willing to offer you some help. Actually, we are glad that our study materials are able to become you top choice. In the past ten years, we always hold the belief that it is dangerous if we feel satisfied with our DP-800 Study Materials and stop renovating. Luckily, we still memorize our initial determination.
DP-800 Reliable Dumps: https://www.ipassleader.com/Microsoft/DP-800-practice-exam-dumps.html
P.S. Free & New DP-800 dumps are available on Google Drive shared by iPassleader: https://drive.google.com/open?id=1x50mVaTsazK_ggblVjC7-tdREe7_jUEF