2Pass4sure has created a real Databricks Certified Professional Data Engineer Exam, Databricks-Certified-Professional-Data-Engineer exam questions in three forms: Databricks Databricks-Certified-Professional-Data-Engineer pdf questions file is the first form. The second and third formats are Web-based and desktop Databricks Databricks-Certified-Professional-Data-Engineer practice test software. Databricks-Certified-Professional-Data-Engineer pdf dumps file will help you to immediately prepare well for the actual Databricks Databricks Certified Professional Data Engineer Exam. You can download and open the Databricks PDF Questions file anywhere or at any time. Databricks-Certified-Professional-Data-Engineer Dumps will work on your laptop, tablet, smartphone, or any other device. You will get a list of actual Databricks Databricks-Certified-Professional-Data-Engineer test questions in Databricks Databricks-Certified-Professional-Data-Engineer pdf dumps file. Practicing with Web-based and desktop Databricks-Certified-Professional-Data-Engineer practice test software you will find your knowledge gap.
| Section | Weight | Objectives |
|---|---|---|
| Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
| Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Data Ingestion | 15-20% | - Streaming ingestion
|
| Delta Lake | 20-25% | - Delta Lake fundamentals
|
>> Databricks-Certified-Professional-Data-Engineer Actual Exams <<
Our Databricks-Certified-Professional-Data-Engineer exam torrent is available in PDF, software, and online three modes, which allowing you to switch learning materials on paper, on your phone or on your computer, and to study anywhere and anytime with the according version of Databricks-Certified-Professional-Data-Engineer practice test. Before you purchase the system, Databricks-Certified-Professional-Data-Engineer Practice Test provides you with a free trial service, so that customers can fully understand our system before buying; after the online payment is successful, you can receive mail from customer service in 5 to 10 minutes, and then immediately begin to learn Databricks-Certified-Professional-Data-Engineer training prep.
NEW QUESTION # 98
A security analytics pipeline must enrich billions of raw connection logs with geolocation data. The join hinges on finding which IPv4 range each event's address falls into.
Table 1: network_events (≈ 5 billion rows)
event_id ip_int
42 3232235777
Table 2: ip_ranges (≈ 2 million rows)
start_ip_int end_ip_int country
3232235520 3232236031 US
The query is currently very slow:
SELECT n.event_id, n.ip_int, r.country
FROM network_events n
JOIN ip_ranges r
ON n.ip_int BETWEEN r.start_ip_int AND r.end_ip_int;
Which change will most dramatically accelerate the query while preserving its logic?
Answer: C
Explanation:
Comprehensive and Detailed Explanation from Databricks Documentation:
The query joins billions of rows (network_events) with millions of rows (ip_ranges) using a range predicate (BETWEEN). Unlike equality joins (=), range joins are not efficiently handled by broadcast or sort-merge joins because:
* Broadcast Join (D): Effective for small tables but only for equality joins. Since this query uses a range condition, broadcast will not reduce the complexity of scanning billions of records across non-equality conditions.
* Sort-Merge Join (C): Works for ordered joins but is inefficient on range conditions. Sorting billions of records adds excessive overhead and will not resolve the bottleneck.
* Increasing Shuffle Partitions (A): Only spreads out shuffle work but does not address the fundamental inefficiency of range-based lookups at scale.
Range Joins in Spark (RANGE_JOIN hint):
Databricks provides range join optimizations specifically for conditions such as BETWEEN. By applying a RANGE_JOIN hint, Spark can build optimized data structures (such as interval indexes or partition pruning strategies) that map billions of input rows to ranges much faster. This avoids brute-force scans and unnecessary shuffle costs.
Thus, Option B is the correct solution because:
* It leverages range-join optimization, which is purpose-built for queries joining massive event logs to smaller lookup tables with IP ranges.
* This ensures Spark can evaluate billions of rows against millions of ranges with optimized matching logic, drastically improving query performance while preserving correctness.
NEW QUESTION # 99
The data science team has created and logged a production using MLFlow. The model accepts a list of column names and returns a new column of type DOUBLE.
The following code correctly imports the production model, load the customer table containing the customer_id key column into a Dataframe, and defines the feature columns needed for the model.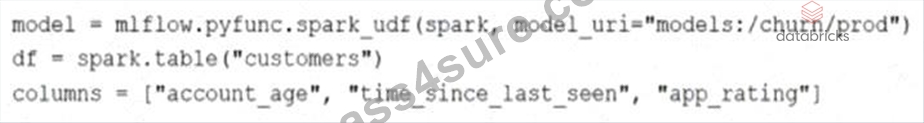
Which code block will output DataFrame with the schema'' customer_id LONG, predictions DOUBLE''?
Answer: D
Explanation:
Given the information that the model is registered with MLflow and assuming predict is the method used to apply the model to a set of columns, we use the model.predict() function to apply the model to the DataFrame df using the specified columns. The model.predict() function is designed to take in a DataFrame and a list of column names as arguments, applying the trained model to these features to produce a predictions column. When working with PySpark, this predictions column needs to be selected alongside the customer_id to create a new DataFrame with the schema customer_id LONG, predictions DOUBLE.
References:
MLflow documentation on using Python function models: https://www.mlflow.org/docs/latest/models.
html#python-function-python
PySpark MLlib documentation on model prediction: https://spark.apache.org/docs/latest/ml-pipeline.
html#pipeline
NEW QUESTION # 100
A nightly job ingests data into a Delta Lake table using the following code: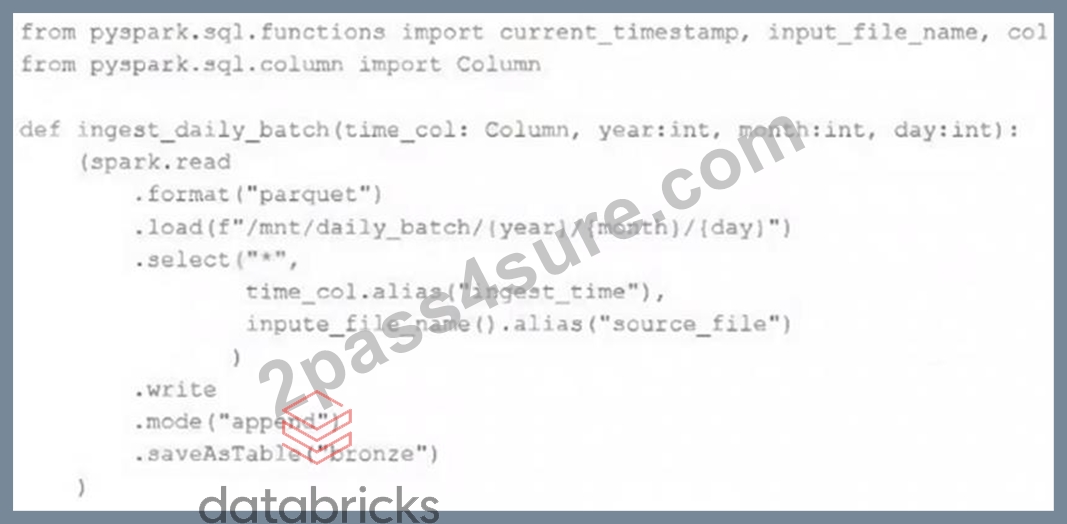
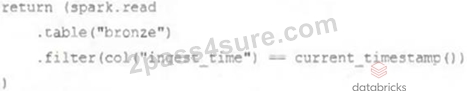
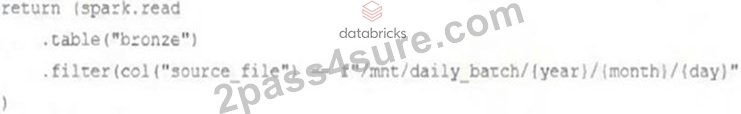
The next step in the pipeline requires a function that returns an object that can be used to manipulate new records that have not yet been processed to the next table in the pipeline.
Which code snippet completes this function definition?
def new_records():
Answer: E
Explanation:
Explanation
https://docs.databricks.com/en/delta/delta-change-data-feed.html
NEW QUESTION # 101
The data engineering team maintains the following code: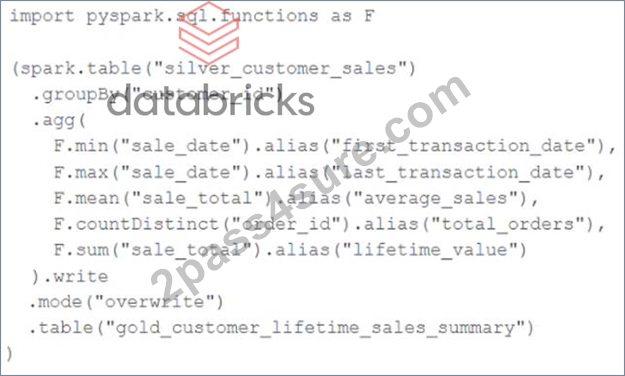
Assuming that this code produces logically correct results and the data in the source table has been de-duplicated and validated, which statement describes what will occur when this code is executed?
Answer: D
Explanation:
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed. Reference:
https://docs.databricks.com/spark/latest/dataframes-datasets/introduction-to-dataframes-python.html
https://docs.databricks.com/spark/latest/dataframes-datasets/transforming-data-with-dataframes.html
https://docs.databricks.com/spark/latest/dataframes-datasets/aggregating-data-with-dataframes.html
NEW QUESTION # 102
A junior data engineer is working to implement logic for a Lakehouse table named silver_device_recordings.
The source data contains 100 unique fields in a highly nested JSON structure.
The silver_device_recordings table will be used downstream for highly selective joins on a number of fields, and will also be leveraged by the machine learning team to filter on a handful of relevant fields, in total, 15 fields have been identified that will often be used for filter and join logic.
The data engineer is trying to determine the best approach for dealing with these nested fields before declaring the table schema.
Which of the following accurately presents information about Delta Lake and Databricks that may Impact their decision-making process?
Answer: C
Explanation:
Delta Lake, built on top of Parquet, enhances query performance through data skipping, which is based on the statistics collected for each file in a table. For tables with a large number of columns, Delta Lake by default collects and stores statistics only for the first 32 columns. These statistics include min/max values and null counts, which are used to optimize query execution by skipping irrelevant data files. When dealing with highly nested JSON structures, understanding this behavior is crucial for schema design, especially when determining which fields should be flattened or prioritized in the table structure to leverage data skipping efficiently for performance optimization.References: Databricks documentation on Delta Lake optimization techniques, including data skipping and statistics collection (https://docs.databricks.com/delta/optimizations/index.html).
NEW QUESTION # 103
......
2Pass4sure offers 100% secure online purchase at all the time. We offer payments through Paypal-one of the most trusted payment providers which can ensure the safety shopping for Databricks-Certified-Professional-Data-Engineer study torrent. Besides, before you choose our material, you can try our Databricks-Certified-Professional-Data-Engineer free demo questions to check if it is valuable for you to buy our Databricks-Certified-Professional-Data-Engineer practice dumps. You will get the latest and updated study dumps within one year after your purchase. So, do not worry the update and change in the actual test, you will be confident in the real test with the help of our Databricks-Certified-Professional-Data-Engineer training torrent.
Databricks-Certified-Professional-Data-Engineer Valid Dumps Demo: https://www.2pass4sure.com/Databricks-Certification/Databricks-Certified-Professional-Data-Engineer-actual-exam-braindumps.html