BTW, DOWNLOAD part of TopExamCollection Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1S5OG1PVSHgiAUZ9yIQUo8IVWIJ8V0k4A
You can become more competitive force in the job hunting market and you can also improve your ability in the process of getting a certificate. Professional-Data-Engineer study materials of us will help you get the certificate successfully. With experienced experts to compile Professional-Data-Engineer study materials, they are high-quality and accuracy, and you can pass the exam just one time. Moreover, we offer you free demo, and you can have a try before buying Professional-Data-Engineer Exam Dumps, so that you can have a better understanding of what you are going to buy.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Data Engineer Exam |
| Exam Number: | Professional-Data-Engineer |
| Available Languages: | English, Japanese |
| Real Exam Qty: | 40 - 50 |
| Related Certifications: | Google Cloud Associate Cloud Engineer Google Cloud Professional Data Analyst Google Cloud Professional Cloud Architect |
| Passing Score: | 700 / 1000 |
| Exam Duration: | 120 minutes |
| Exam Price: | USD 200 (plus tax where applicable) |
| Exam Format: | Multiple select, Multiple choice |
| Certificate Validity Period: | 2 years |
| Recommended Training: | Official Exam Guide Google Cloud Professional Data Engineer Learning Path |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Data-Engineer Sample Questions |
| Exam Way: | Online-proctored or onsite-proctored |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience, including 1+ year designing and managing Google Cloud data solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/data-engineer |
>> Google Professional-Data-Engineer Valid Test Cram <<
Do you want to try our free demo of the Professional-Data-Engineer study questions? Your answer must be yes. So just open our websites in your computer. You will have easy access to all kinds of free trials of the Professional-Data-Engineer practice materials. You can apply for many types of Professional-Data-Engineer Exam simulation at the same time. Once our system receives your application, it will soon send you what you need. Please ensure you have submitted the right email address. And you will have the demos to check them out.
The Google Professional-Data-Engineer exam consists of multiple-choice questions and requires candidates to demonstrate their knowledge of various data engineering concepts and technologies. The questions are designed to test the candidate's ability to analyze data, transform data, and implement data processing solutions using Google Cloud Platform's tools and services. Professional-Data-Engineer Exam is two hours long, and candidates must achieve a passing score of 70% or higher to earn the certification.
NEW QUESTION # 419
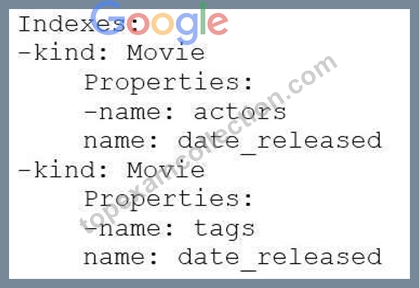
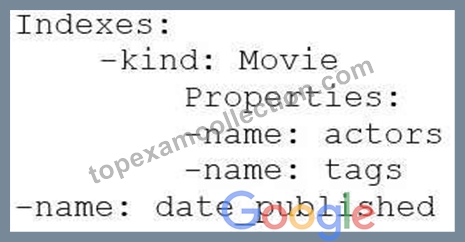
You are deploying a new storage system for your mobile application, which is a media streaming service. You decide the best fit is Google Cloud Datastore. You have entities with multiple properties, some of which can take on multiple values. For example, in the entity 'Movie'the property 'actors'and the property 'tags' have multiple values but the property 'date released' does not. A typical query would ask for all movies with actor=<actorname>ordered by date_releasedor all movies with tag=Comedyordered by date_released. How should you avoid a combinatorial explosion in the number of indexes?
Answer: B
NEW QUESTION # 420
You are building a model to make clothing recommendations. You know a user's fashion preference is likely to change over time, so you build a data pipeline to stream new data back to the model as it becomes available.
How should you use this data to train the model?
Answer: C
NEW QUESTION # 421
You are building a streaming Dataflow pipeline that ingests noise level data from hundreds of sensors placed near construction sites across a city. The sensors measure noise level every ten seconds, and send that data to the pipeline when levels reach above 70 dBA. You need to detect the average noise level from a sensor when data is received for a duration of more than 30 minutes, but the window ends when no data has been received for 15 minutes What should you do?
Answer: D
Explanation:
The key requirements for the windowing strategy are:
A window groups data for a specific sensor.
A window should contain data spanningat least30 minutes ("duration of more than 30 minutes" implies activity for this period).
A window for a sensorendswhen no data has been received from that sensor for 15 minutes (this is a gap).
This scenario perfectly describessession windows.
Session Windows:Session windows group elements (per key, e.g., per sensor ID) that arrive within a certain
"gap duration" of each other. A new session starts if data for a key arrives after the gap duration has passed since the last data point for that key.
In this case, if data stops arriving for a sensor for 15 minutes, the current session for that sensor closes. This matches "the window ends when no data has been received for 15 minutes." The "duration of more than 30 minutes" requirement is a condition you would applyafterthe session window closes. You'd calculate the duration of the data within the closed session window and only compute the average if that session's duration (span of event times within it) exceeds 30 minutes. Session windows themselves don't have a fixed duration; their duration is determined by data activity and the gap.
Let's analyze why other options are less suitable:
A (Hopping windows with a 15-minute window, and a thirty-minute period):Hopping windows have a fixed size and a fixed period. They create overlapping windows. This doesn't align with the dynamic nature of sessions ending based on inactivity. A 30-minute period with a 15-minute window means windows like [0:00-
0:15], [0:15-0:30], [0:30-0:45]. If activity is continuous, a 30-minute activity span would be covered, but the window closing is not based on a 15-minute gap of inactivity.
B (Tumbling windows with a 15-minute window and a fifteen-minute .withAllowedLateness operator):
Tumbling windows are fixed-size, non-overlapping windows. .withAllowedLateness deals with late data arriving for a window that has already passed its end time, not with defining the window based on activity gaps.
C (Session windows with a 30-minute gap duration):This would mean a session ends only if there's a 30- minute gap of inactivity. The requirement is a 15-minute gap.
Therefore, session windows with a 15-minute gap duration (Option D) correctly model the requirement for windows to close after 15 minutes of inactivity from a sensor. The subsequent filtering for sessions lasting more than 30 minutes is a downstream operation.
Reference:
Apache Beam Programming Guide > Windowing > Windowing functions > Session windows. "Session windowing assigns elements to windows that represent sessions of activity. A session window starts when the first element arrives for a key. If another element arrives for that key within the specified gap duration, that element is included in the existing session window. If an element arrives after the gap duration, a new session window starts for that element... Session windows are useful for data that is irregularly distributed with respect to time, such as user activity data." This directly matches the sensor data behavior: data arrives when noise is high, and a period of no data for 15 minutes should close the analysis window for that sensor.
NEW QUESTION # 422
Your infrastructure includes a set of YouTube channels. You have been tasked with creating a process for sending the YouTube channel data to Google Cloud for analysis. You want to design a solution that allows your world-wide marketing teams to perform ANSI SQL and other types of analysis on up-to-date YouTube channels log dat a. How should you set up the log data transfer into Google Cloud?
Answer: D
Explanation:
storage bucket as a final destination.
NEW QUESTION # 423
Which of the following statements about Legacy SQL and Standard SQL is not true?
Answer: D
Explanation:
You do not set a query language for each dataset. It is set each time you run a query and the default query language is Legacy SQL.
Standard SQL has been the preferred query language since BigQuery 2.0 was released.
In legacy SQL, to query a table with a project-qualified name, you use a colon, :, as a separator. In standard SQL, you use a period, ., instead.
Due to the differences in syntax between the two query languages (such as with project- qualified table names), if you write a query in Legacy SQL, it might generate an error if you try to run it with Standard SQL.
Reference:
https://cloud.google.com/bigquery/docs/reference/standard-sql/migrating-from-legacy-sql
NEW QUESTION # 424
......
Reliable Professional-Data-Engineer Test Experience: https://www.topexamcollection.com/Professional-Data-Engineer-vce-collection.html
DOWNLOAD the newest TopExamCollection Professional-Data-Engineer PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1S5OG1PVSHgiAUZ9yIQUo8IVWIJ8V0k4A