試験の準備方法-完璧なDY0-001前提条件試験-有効的なDY0-001受験体験

さらに、Pass4Test DY0-001ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=1KahBfAib7UdJlJXmyAHHIJixkwdgzGTQ
初心者でも経験豊富な人でも、Pass4Test学習教材は、長年にわたる試験概要の変化と業界の傾向に基づいて編集された専門家にとって最適な選択です。 DY0-001テストトレントは、学習の効率を向上させるのに役立つだけでなく、レビュー時間を最大数か月から1か月、さらには2週間または3週間に短縮するのにも役立ちます。 最大の改善を得る。 そして、DY0-001試験問題により、CompTIA、あなたのCompTIA DataAI Certification Exam成功が保証されます。
CompTIA DY0-001 認定試験の出題範囲:
| トピック | 出題範囲 |
|---|
| トピック 1 | - Specialized Applications of Data Science: This section of the exam measures skills of a Senior Data Analyst and introduces advanced topics like constrained optimization, reinforcement learning, and edge computing. It covers natural language processing fundamentals such as text tokenization, embeddings, sentiment analysis, and LLMs. Candidates also explore computer vision tasks like object detection and segmentation, and are assessed on their understanding of graph theory, anomaly detection, heuristics, and multimodal machine learning, showing how data science extends across multiple domains and applications.
|
| トピック 2 | - Machine Learning: This section of the exam measures skills of a Machine Learning Engineer and covers foundational ML concepts such as overfitting, feature selection, and ensemble models. It includes supervised learning algorithms, tree-based methods, and regression techniques. The domain introduces deep learning frameworks and architectures like CNNs, RNNs, and transformers, along with optimization methods. It also addresses unsupervised learning, dimensionality reduction, and clustering models, helping candidates understand the wide range of ML applications and techniques used in modern analytics.
|
| トピック 3 | - Operations and Processes: This section of the exam measures skills of an AI
- ML Operations Specialist and evaluates understanding of data ingestion methods, pipeline orchestration, data cleaning, and version control in the data science workflow. Candidates are expected to understand infrastructure needs for various data types and formats, manage clean code practices, and follow documentation standards. The section also explores DevOps and MLOps concepts, including continuous deployment, model performance monitoring, and deployment across environments like cloud, containers, and edge systems.
|
| トピック 4 | - Modeling, Analysis, and Outcomes: This section of the exam measures skills of a Data Science Consultant and focuses on exploratory data analysis, feature identification, and visualization techniques to interpret object behavior and relationships. It explores data quality issues, data enrichment practices like feature engineering and transformation, and model design processes including iterations and performance assessments. Candidates are also evaluated on their ability to justify model selections through experiment outcomes and communicate insights effectively to diverse business audiences using appropriate visualization tools.
|
| トピック 5 | - Mathematics and Statistics: This section of the exam measures skills of a Data Scientist and covers the application of various statistical techniques used in data science, such as hypothesis testing, regression metrics, and probability functions. It also evaluates understanding of statistical distributions, types of data missingness, and probability models. Candidates are expected to understand essential linear algebra and calculus concepts relevant to data manipulation and analysis, as well as compare time-based models like ARIMA and longitudinal studies used for forecasting and causal inference.
|
>> DY0-001前提条件 <<
CompTIA DY0-001受験体験 & DY0-001受験対策解説集
弊社のDY0-001問題集はIT業界で有名で、ブランドになっています。DY0-001問題集はすごく人気がある商品で、どこでも広告を掲載する必要がないです。従って、多くの受験者は弊社のDY0-001問題集を選びました。なぜ彼らがDY0-001問題集を選ぶかというと、弊社のDY0-001問題集は高品質で、便利で、勉強しやすいからです。弊社のDY0-001問題集を買う人は全部DY0-001試験にいい成績で合格しました。
CompTIA DataAI Certification Exam 認定 DY0-001 試験問題 (Q71-Q76):
質問 # 71
A data analyst is analyzing data and would like to build conceptual associations. Which of the following is the best way to accomplish this task?
- A. POS
- B. n-grams
- C. TF-IDF
- D. NER
正解:B
解説:
# n-grams (bigrams, trigrams, etc.) are sequences of N words used to analyze co-occurrences and build conceptual or contextual associations between terms in natural language processing (NLP). This helps in understanding the semantic structure of language and is ideal for finding relationships between words.
Why the other options are incorrect:
* B: NER (Named Entity Recognition) identifies entities like names or dates; it doesn't focus on conceptual associations.
* C: TF-IDF scores term importance relative to documents, not associations.
* D: POS (Part of Speech) tagging identifies word roles (noun, verb, etc.), not direct associations.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.3:"n-gram analysis is useful for discovering common patterns and associations in unstructured text data."
* Natural Language Processing with Python (NLTK Book), Chapter 3:"N-grams help capture collocations and associations between words that often co-occur, essential for understanding context."
-
質問 # 72
A data scientist is building a proof of concept for a commercialized machine-learning model. Which of the following is the best starting point?
- A. Model selection
- B. Literature review
- C. Hyperparameter tuning
- D. Model performance evaluation
正解:B
解説:
Before diving into selecting or tuning models, a literature review grounds the proof of concept in existing research and best practices, ensuring the approach aligns with state-of-the-art methods and the problem's domain requirements.
質問 # 73
A data scientist trained a model for departments to share. The departments must access the model using HTTP requests. Which of the following approaches is appropriate?
- A. Use the File Transfer Protocol.
- B. Create an endpoint.
- C. Utilize distributed computing.
- D. Deploy containers.
正解:B
解説:
Exposing the model behind an HTTP endpoint (for example, a REST API) allows other departments to send requests and receive predictions directly over HTTP. The other options don't inherently provide a request-response interface for sharing a model.
質問 # 74
A data scientist has built a model that provides the likelihood of an error occurring in a factory. The historical accuracy of the model is 90%. At a specific factory, the model is reporting a likelihood score of 0.90. Which of the following explains a confidence score of 0.90?
- A. Running this model for all known factory issues, it is expected the model will identify 90 out of 100 known factory issues.
- B. Running this model 100 times within a factory it is expected the model will predict error 90 out of 100times the model is ran.
- C. Running this model on 100 samples of factories, a certain model performance is expected for 90 out of the 100 samples.
- D. Running this model 100 times on a factory, it is expected the model will predict 90 out of 100 factory errors.
正解:B
解説:
# A likelihood score of 0.90 indicates the model's confidence that an error will occur in this particular instance. Interpreted probabilistically, it means that if this scenario happened 100 times, the model would expect an error in 90 of those cases.
Why the other options are incorrect:
* A: Confuses confidence with recall or precision.
* B: Refers to model sampling performance, not instance-level prediction.
* C: Implies a prediction of actual factory errors - not the model's forecast probability.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"A confidence score in a classification model indicates the model's belief in the outcome of a specific prediction."
-
質問 # 75
The following graphic shows the results of an unsupervised, machine-learning clustering model:
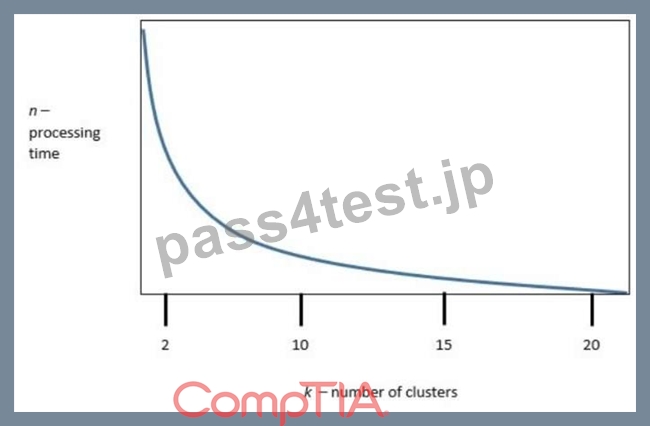
k is the number of clusters, and n is the processing time required to run the model. Which of the following is the best value of k to optimize both accuracy and processing requirements?
正解:D
解説:
# The graph represents a classic "elbow curve," which is often used in clustering (e.g., k-means) to help determine the optimal number of clusters. The point where the curve starts to level off (the "elbow") reflects the best trade-off between model accuracy and processing efficiency.
In this graph, the elbow visually occurs around k = 10. Beyond that, the processing time continues to decrease, but the marginal gain in clustering quality (or drop in processing time) diminishes.
Why the other options are incorrect:
* A: k = 2 underfits the data - too few clusters.
* C & D: k = 15 or 20 provides minimal additional benefit in processing but may overcomplicate the model.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 4.2:"The elbow method identifies the optimal number of clusters where the rate of improvement drops significantly."
-
質問 # 76
......
私たちのDY0-001研究ブレーンダンプは、この点でユーザーの需要を満たすのに非常に優れている可能性があり、ユーザーが学習したことを継続的に統合する良い環境で読み書きできるようにします。 DY0-001準備ガイドは高品質です。当社のウェブサイトのDY0-001学習クイズバンクおよび教材は、選択したトピックに基づいて最新の質問と回答を検索します。 この選択は、あなたのキャリア全体の突破口となるので、DY0-001スタディガイドの高い品質と正確性に驚かされるでしょう。
DY0-001受験体験: https://www.pass4test.jp/DY0-001.html
- 権威のあるDY0-001前提条件 - 合格スムーズDY0-001受験体験 | 更新するDY0-001受験対策解説集 🙇 Open Webサイト▷ www.mogiexam.com ◁検索➽ DY0-001 🢪無料ダウンロードDY0-001シュミレーション問題集
- DY0-001赤本合格率 👫 DY0-001資格勉強 😌 DY0-001シュミレーション問題集 🟦 “ www.goshiken.com ”に移動し、➡ DY0-001 ️⬅️を検索して無料でダウンロードしてくださいDY0-001赤本合格率
- DY0-001試験指導資料、DY0-001最新練習問題、DY0-001オンライン試験模擬 👴 { DY0-001 }を無料でダウンロード✔ jp.fast2test.com ️✔️ウェブサイトを入力するだけDY0-001対応問題集
- DY0-001問題数 😯 DY0-001勉強ガイド 🥽 DY0-001試験復習 🍵 【 www.goshiken.com 】から「 DY0-001 」を検索して、試験資料を無料でダウンロードしてくださいDY0-001試験過去問
- DY0-001過去問無料 🐹 DY0-001日本語復習赤本 🤎 DY0-001復習過去問 ⬛ サイト➽ www.jpexam.com 🢪で✔ DY0-001 ️✔️問題集をダウンロードDY0-001試験過去問
- DY0-001過去問無料 🏇 DY0-001関連合格問題 🍲 DY0-001認定試験トレーリング 💰 ✔ DY0-001 ️✔️を無料でダウンロード“ www.goshiken.com ”ウェブサイトを入力するだけDY0-001勉強ガイド
- 一番優秀なDY0-001前提条件 - 合格スムーズDY0-001受験体験 | 素敵なDY0-001受験対策解説集 😨 今すぐ➤ www.goshiken.com ⮘を開き、( DY0-001 )を検索して無料でダウンロードしてくださいDY0-001勉強ガイド
- DY0-001シュミレーション問題集 🥕 DY0-001認定試験トレーリング 🪕 DY0-001試験過去問 📈 最新⮆ DY0-001 ⮄問題集ファイルは⮆ www.goshiken.com ⮄にて検索DY0-001試験復習
- DY0-001試験過去問 👊 DY0-001認定試験トレーリング 📔 DY0-001関連合格問題 📚 ▶ www.mogiexam.com ◀サイトにて最新【 DY0-001 】問題集をダウンロードDY0-001認定試験トレーリング
- 権威のあるDY0-001前提条件 - 合格スムーズDY0-001受験体験 | 更新するDY0-001受験対策解説集 ☯ 「 www.goshiken.com 」サイトで⮆ DY0-001 ⮄の最新問題が使えるDY0-001問題数
- 更新するDY0-001|高品質なDY0-001前提条件試験|試験の準備方法CompTIA DataAI Certification Exam受験体験 🌅 ☀ www.jpexam.com ️☀️から簡単に➡ DY0-001 ️⬅️を無料でダウンロードできますDY0-001的中関連問題
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, connect.garmin.com, www.flirtic.com, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, anoj.in.net, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
無料でクラウドストレージから最新のPass4Test DY0-001 PDFダンプをダウンロードする:https://drive.google.com/open?id=1KahBfAib7UdJlJXmyAHHIJixkwdgzGTQ