P.S. Free 2026 Microsoft AI-103 dumps are available on Google Drive shared by DumpsValid: https://drive.google.com/open?id=1j7PgFczuipkAptgLFTinrYvNwvkiZ3Nw
Cease to struggle and you cease to live. Only by continuous learning can we not be surpassed by others. Many people do not like to study and think that learning is a very vexing thing. This kind of cognition makes their careers stagnate. AI-103 test question will change your perception. AI-103 learning dumps aim to help students learn easily and effectively that has been developed over many years by many industry experts. For the online version, unlike other materials that limit one person online, AI-103 learning dumps does not limit the number of concurrent users and the number of online users. You can practice anytime, anywhere, practice repeatedly, practice with others, and even purchase together with othersAI-103 learning dumps make every effort to help you save money and effort, so that you can pass the exam with the least cost.
| Section | Weight | Objectives |
|---|---|---|
| Implement computer vision solutions | 10-15% | - Analyze visual content
|
| Implement text analysis and information extraction solutions | 10-15% | - Analyze and extract information
|
| Implement agentic solutions | 20-25% | - Manage agent operations
|
| Plan and manage Azure AI solutions | 25-30% | - Manage AI solution lifecycle
|
| Implement generative AI solutions | 25-30% | - Optimize and evaluate models
|
>> AI-103 Latest Test Answers <<
The Microsoft AI-103 Dumps PDF File material is printable, enabling your off-screen study. This format is portable and easily usable on smart devices including laptops, tablets, and smartphones. Microsoft AI-103 dumps team of professionals keeps an eye on content of the Microsoft AI-103 Exam and updates its product accordingly. Our pdf is a very handy format for casual and quick preparation of the Microsoft certification exam.
NEW QUESTION # 70
You have a Microsoft Foundry agent that grounds responses from an Azure AI Search index containing:
* Searchable text fields for product names and product codes.
* A vector field containing embeddings for product descriptions.
You need users to query by exact product names or codes and by natural-language product descriptions.
Answer: C
Explanation:
Configure hybrid search , which executes full-text and vector queries within the same Azure AI Search request. The full-text component searches the product-name and product-code fields through the lexical index, providing the precision required for exact or near-exact identifiers. Microsoft specifically identifies product codes and other specialized terms as scenarios that frequently perform better with keyword search.
The vector component compares the embedding of the user's natural-language query with the embeddings stored for product descriptions. This retrieves semantically similar products even when the query and indexed description do not share the same literal words. Azure AI Search runs the full-text and vector searches in parallel and combines their result sets by using Reciprocal Rank Fusion, returning one unified ranking to the Foundry agent.
Keyword-only search would preserve exact matching but perform poorly for conceptual or paraphrased descriptions. Vector-only search supports semantic similarity but can miss precise product codes and rare identifiers. Semantic search alone reranks text-search results using language understanding; it does not replace the vector query required to use the existing embedding field.
Study Guide alignment: configure semantic, hybrid, and vector search for grounding, choose an appropriate retrieval method, and connect retrieval pipelines to agent tools .
NEW QUESTION # 71
You have a Microsoft Foundry project that contains an agent.
The agent accepts user-uploaded screenshots and uses a multimodal chat model.
Some screenshots contain potentially malicious embedded text.
You need to prevent a prompt injection attack and ensure that third-party content is treated as lower trust.
How should you configure prompt shields for document attacks? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.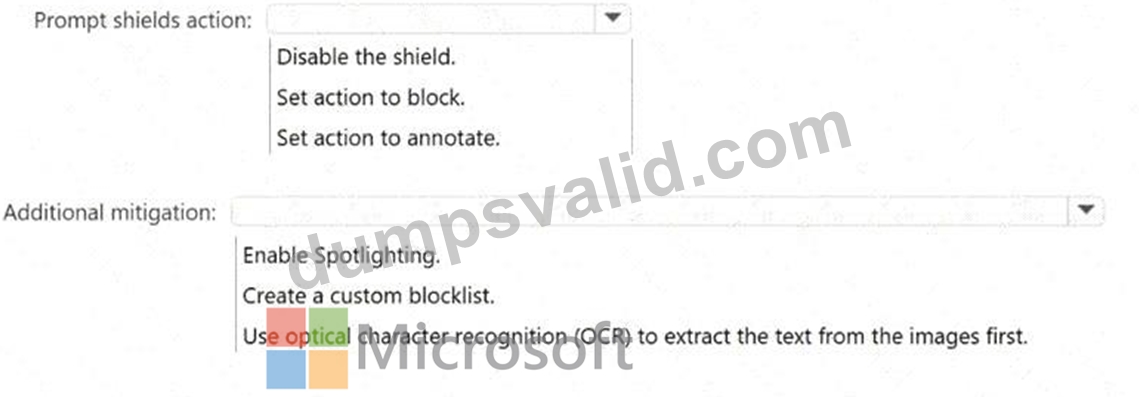
Answer:
Explanation: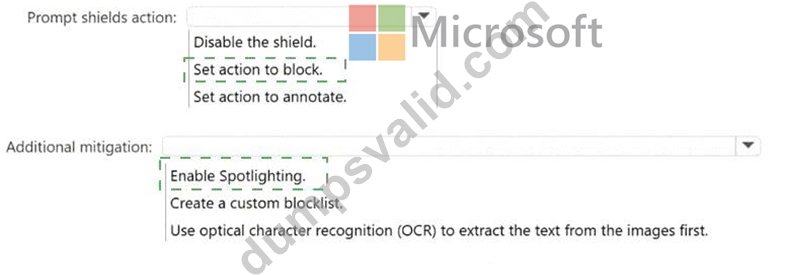
Explanation:
Prompt shields action: Set action to block.
Additional mitigation: Enable Spotlighting.
The correct configuration is to set the Prompt Shields document attack action to block and enable Spotlighting . Prompt Shields in Microsoft Foundry are designed to detect attempts to manipulate model behavior through adversarial input. Microsoft distinguishes document attacks from direct user prompt attacks:
document attacks are malicious instructions embedded in third-party content such as documents, webpages, emails, or other externally supplied material. In this scenario, the embedded text inside uploaded screenshots is third-party content and can attempt to override the agent's instructions. Setting the action to block prevents detected document-attack content from being processed normally, which is required because the goal is prevention rather than passive logging or annotation.
Spotlighting is the additional mitigation because it marks or transforms document content so the model treats it as lower trust than system and user instructions. Microsoft's Foundry guidance describes Spotlighting as a Prompt Shields subfeature that helps protect against indirect or embedded document attacks by tagging input documents with special formatting to indicate lower trust. A custom blocklist is insufficient for unknown attacks, and OCR alone only extracts the malicious text; it does not mitigate prompt injection. Reference topics: Prompt Shields, document attacks, guardrails, Spotlighting, multimodal safety, and prompt injection defense.
NEW QUESTION # 72
You need to ensure that Agent1Dev Team can access Agent1. The solution must meet the security and compliance requirements.
How should you complete the Python code? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.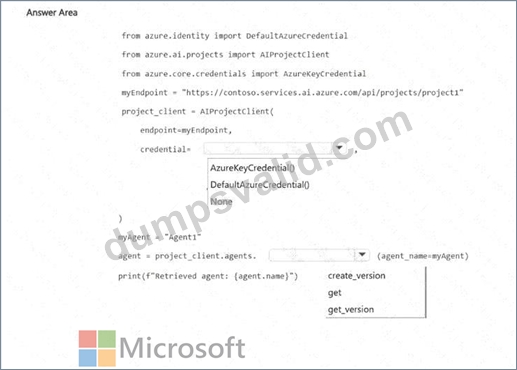
Answer:
Explanation: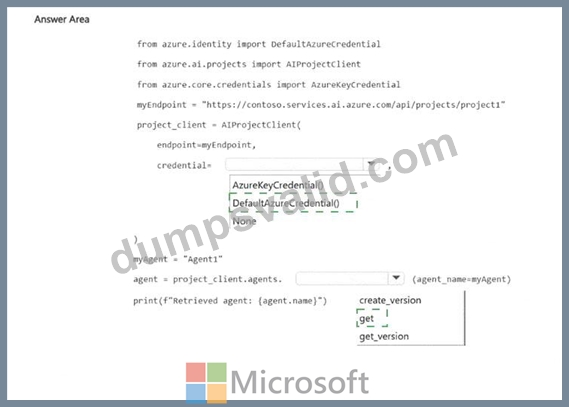
Explanation:
credential = DefaultAzureCredential()
agent = project_client.agents.get(agent_name=myAgent)
The correct authentication option is DefaultAzureCredential() because the case study states that API keys must not be used to access Foundry-deployed models and that Contoso developers must authenticate to Microsoft Foundry resources by using Microsoft Entra authentication. It also states that access to Project1 must be assigned to Agent1Dev Team by using the security group SC_Agent1_Dev . Microsoft Foundry authentication guidance recommends Microsoft Entra ID for production workloads because it supports least- privilege RBAC, per-principal auditing, and keyless authentication. AzureKeyCredential() would violate the no-API-key requirement, and None would not provi de a valid credential.
The correct agent operation is get because the task is to access an existing agent named Agent1, not create a new version or retrieve a specific published version. Microsoft Foundry SDK examples show AIProjectClient created with DefaultAzureCredential() and then using project agent operations to create, retrieve, or interact with agents by name. To meet the compliance requirement, the group SC_Agent1_Dev must also be granted the appropriate project-scoped Foundry role, such as Foundry User, for Project1. Reference topics: Microsoft Entra authentication, Foundry RBAC, AIProjectClient, and project agent access.
NEW QUESTION # 73
You have a Microsoft Foundry project that contains a Retrieval Augmented Generation (RAG) chat solution used by customer support agents.
You are adding an automated pre-production evaluation step to a CI/CD pipeline named Pipeline1. The evaluation will run against a labeled test dataset that contains support questions and the expected grounding context.
You need to ensure that Pipeline1 fails if unsupported content or a retrieval mismatch exceeds a defined threshold:
- responses include claims not supported by the retrieved source
content
- retrieved source content does not align with the labeled expected
context
Which two built-in evaluators should you use in Pipeline1? Each correct answer presents pat of the solution.
NOTE: Each correct selection is worth one point.
Answer: C,D
Explanation:
The Groundedness Evaluator evaluator validates that the model's responses include only claims supported by the retrieved source content It flags ungrounded content or hallucinations. If the average score drops below your defined threshold, it triggers a pipeline failure.
The correct additional built-in evaluator appropriate for the pipeline is Retrieval (specifically, the RetrievalEvaluator or DocumentRetrievalEvaluator).
A standard RAG evaluation pipeline assesses both the generator (the LLM producing the answer) and the retriever (the search system pulling documentation). The CI/CD requirements specify two distinct failure thresholds:
Responses including claims not supported by the retrieved source content: This checks for model hallucinations and is handled by the Groundedness Evaluator.
Retrieved source content not aligning with the labeled expected context: This explicitly measures the performance of your search step against your ground-truth data. The built-in Retrieval evaluator maps to this requirement. It computes metrics like context recall to ensure your system successfully retrieves the exact reference documents specified in your labeled test dataset Reference:
https://learn.microsoft.com/en-us/microsoft-365/copilot/extensibility/evaluations-cli-evaluators
NEW QUESTION # 74
You have a Microsoft Foundry project that contains an agent.
The agent uses Azure AI Search for Retrieval Augmented Generation (RAG).
You plan to ingest and index PDF product manuals.
You need to build a solution that supports semantic similarity matching. The solution must ensure that the agent retrieves relevant data when user questions use different wording than the product manuals.
Which indexing approach should you use?
Answer: D
Explanation:
Vector search is the correct indexing and retrieval type to use for this solution.
Vector search versus semantic ranking
While both features help bridge the gap between different wordings, vector search is specifically designed at the indexing and retrieval layer to handle semantic similarity matching by converting text into mathematical vectors (embeddings) based on conceptual meaning. Semantic ranking is a secondary re-ranking layer applied after initial retrieval to improve precision, but it cannot function as the primary indexing method on its own.
Reference:
https://www.scribd.com/document/866453317/Agentforce-Specialist
NEW QUESTION # 75
......
To get better condition of life, we all need impeccable credentials of different exams to prove individual’s capacity. However, weak AI-103 practice materials may descend and impair your ability and flunk you in the real exam unfortunately. And the worst condition is all that work you have paid may go down the drain for those AI-103 question torrent lack commitments and resolves to help customers. The practice materials of the exam with low quality may complicate matters of the real practice exam. So, you must know about our AI-103 question torrent.
AI-103 Training Materials: https://www.dumpsvalid.com/AI-103-still-valid-exam.html
BONUS!!! Download part of DumpsValid AI-103 dumps for free: https://drive.google.com/open?id=1j7PgFczuipkAptgLFTinrYvNwvkiZ3Nw