Laden Sie die neuesten Fast2test DP-100 PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1IRtiycDezacBZI7ukzBR8zuf0sK0xs2P
Haben Sie Microsoft DP-100 Dumps von Fast2test benutzt? Diese Dumps beinhalten die aktualisierten Prüfungsfragen, die auch alle mögliche Prüfungsfragen in der aktuellen Prüfung vorhanden sind. Es kann Ihnen garantieren, nur einmal die Microsoft DP-100 Prüfung zu bestehen. Diese Dumps kann Ihnen helfen, unglaubliche Ergebnisse zu bekommen. Wenn Sie in der Microsoft DP-100 Prüfung durchgefallen sind, geben wir Ihnen voll Geld zurück. Deshalb müssen Sie sorglos diese Dumps benutzen. Sie können den Erfolg erreichen, wenn Sie die Prüfungsunterlagen von Fast2test benutzen.
| Section | Objectives |
|---|---|
| Topic 1: Deploy and consume models | - Deploy models to endpoints - Monitor deployed models and endpoints |
| Topic 2: Optimize and manage models | - Improve model performance - Track experiments and manage model lifecycle |
| Topic 3: Design and prepare a machine learning solution | - Plan and configure Azure Machine Learning workspace - Manage compute and data assets - Select appropriate Azure services for machine learning workloads |
| Topic 4: Train machine learning models | - Train models using Azure Machine Learning - Tune hyperparameters and evaluate models |
| Topic 5: Explore and analyze data | - Ingest and prepare data for modeling - Perform exploratory data analysis |
>> DP-100 Prüfungsunterlagen <<
Wie viel wissen Sie über Fast2test? Haben Sie Prüfungsfragen und Antworten zur Microsoft DP-100 IT-Zertifizierung von Fast2test benutzt? Oder Haben Sie von anderen die Fast2test Prüfungsunterlagen gehört? Als der professionelle Lieferant der IT-Zertifizierungsprüfungen, ist Fast2test unbedingt die beste Website, die Sie nie gesehen haben. Warum sind wir so zuversichtlich? Weil es keine andere Website wie wir Fast2test gibt, die die besten DP-100 Unterlagen und den besten Service anbieten.
280. Frage
You need to identify the methods for dividing the data according to the testing requirements.
Which properties should you select? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.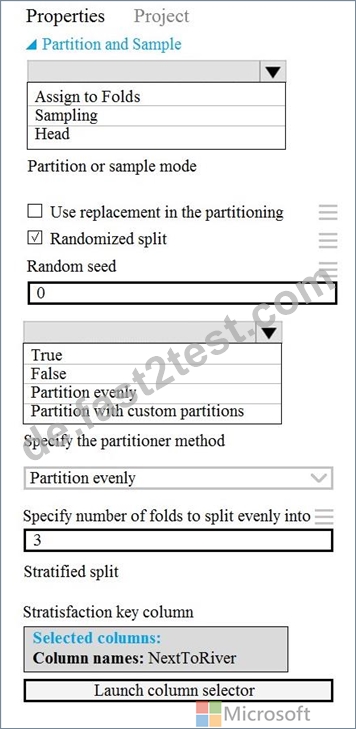
Antwort:
Begründung: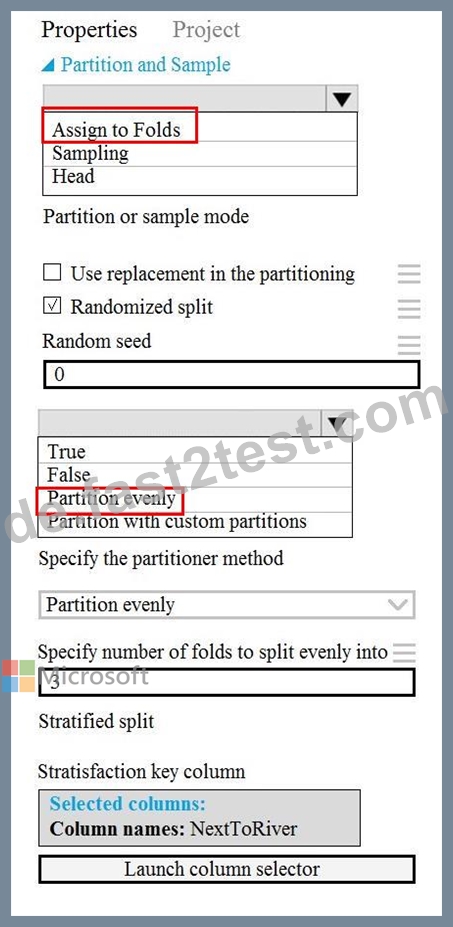
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/algorithm-module-reference/partition-and-sample
281. Frage
Hotspot Question
You monitor an Azure Machine Learning classification training experiment named train.classification on Azure Notebooks.
You must store a table named table as an artifact in Azure Machine Learning Studio during model training.
You need to collect and list the metrics by using MLflow.
How should you complete the code segment? To answer, select the appropriate option in the answer area.
NOTE: Each correct selection is worth one point.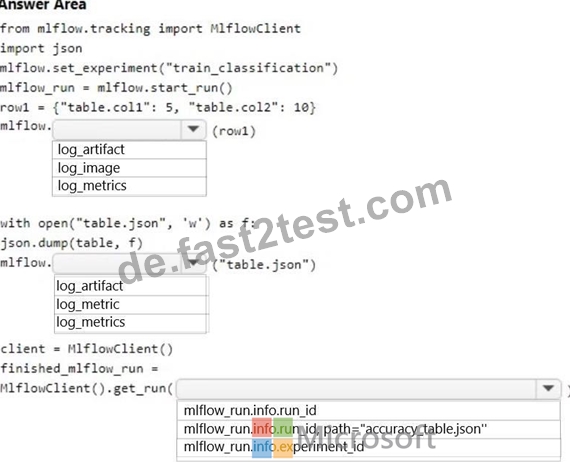
Antwort:
Begründung: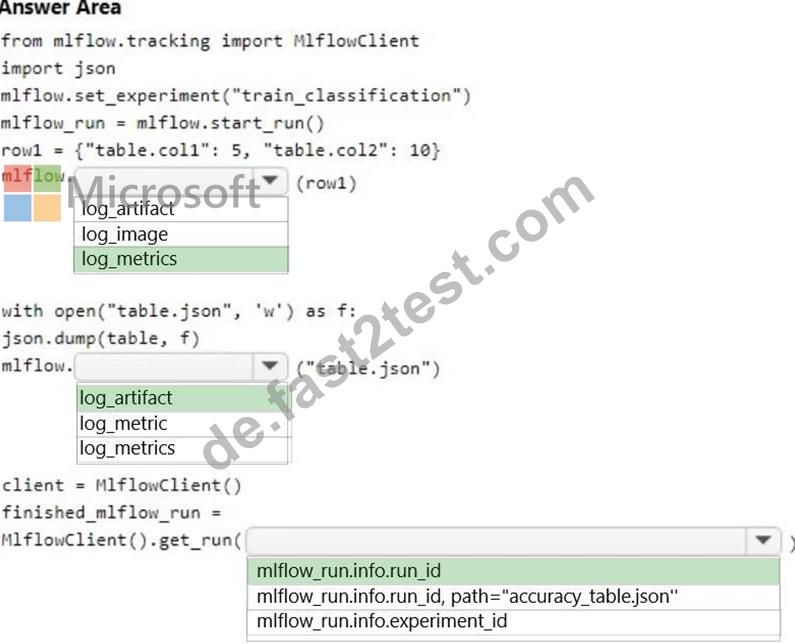
282. Frage
You are evaluating a Python NumPy array that contains six data points defined as follows:
data = [10, 20, 30, 40, 50, 60]
You must generate the following output by using the k-fold algorithm implantation in the Python Scikit-learn machine learning library:
train: [10 40 50 60], test: [20 30]
train: [20 30 40 60], test: [10 50]
train: [10 20 30 50], test: [40 60]
You need to implement a cross-validation to generate the output.
How should you complete the code segment? To answer, select the appropriate code segment in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.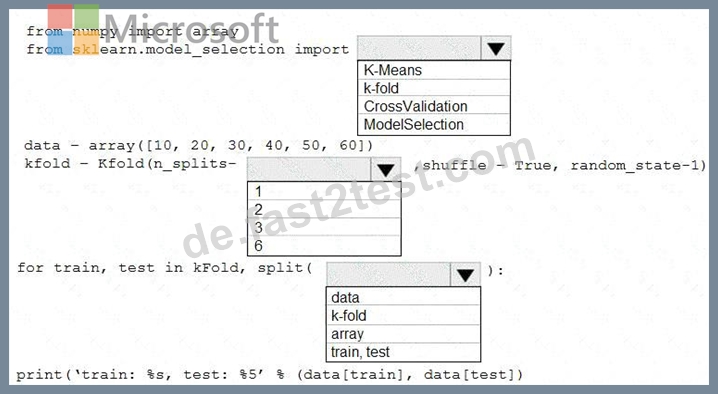
Antwort:
Begründung: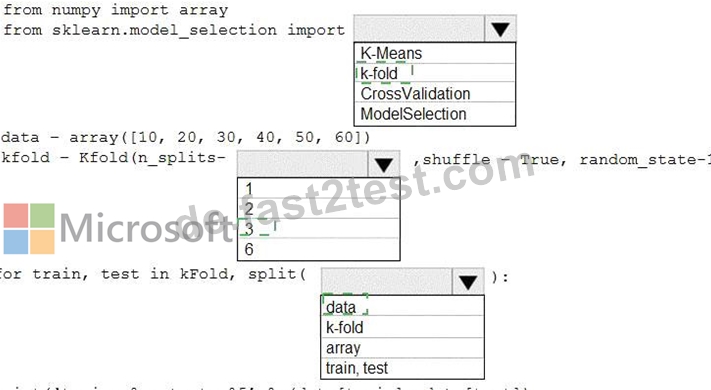
Explanation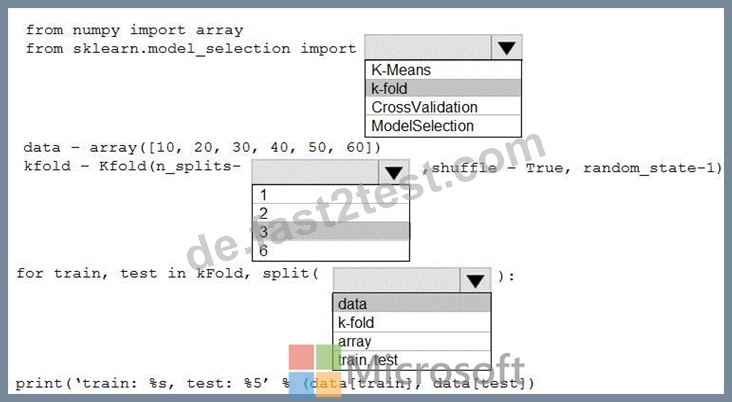
Box 1: k-fold
Box 2: 3
K-Folds cross-validator provides train/test indices to split data in train/test sets. Split dataset into k consecutive folds (without shuffling by default).
The parameter n_splits ( int, default=3) is the number of folds. Must be at least 2.
Box 3: data
Example: Example:
>>>
>>> from sklearn.model_selection import KFold
>>> X = np.array([[1, 2], [3, 4], [1, 2], [3, 4]])
>>> y = np.array([1, 2, 3, 4])
>>> kf = KFold(n_splits=2)
>>> kf.get_n_splits(X)
2
>>> print(kf)
KFold(n_splits=2, random_state=None, shuffle=False)
>>> for train_index, test_index in kf.split(X):
print("TRAIN:", train_index, "TEST:", test_index)
X_train, X_test = X[train_index], X[test_index]
y_train, y_test = y[train_index], y[test_index]
TRAIN: [2 3] TEST: [0 1]
TRAIN: [0 1] TEST: [2 3]
References:
https://scikit-learn.org/stable/modules/generated/sklearn.model_selection.KFold.html
283. Frage
You have several machine learning models registered in an Azure Machine Learning workspace.
You must use the Fairlearn dashboard to assess fairness in a selected model.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.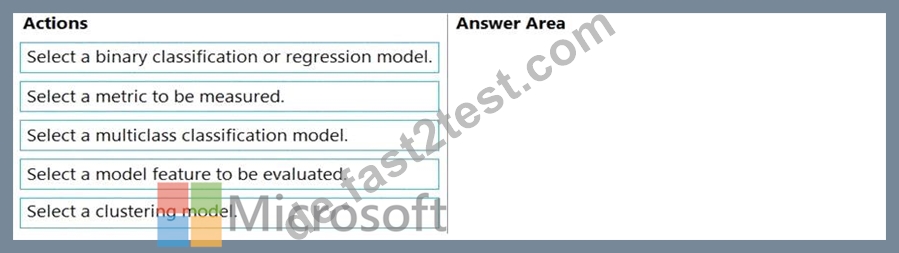
Antwort:
Begründung: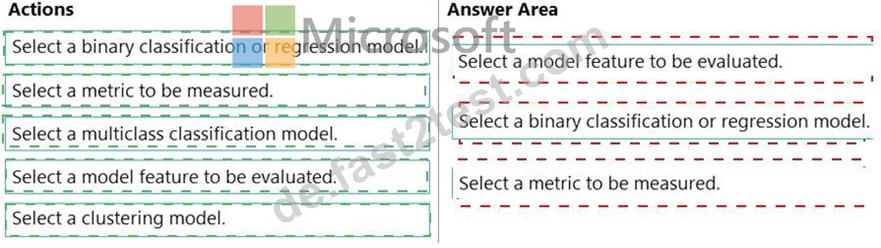
Explanation: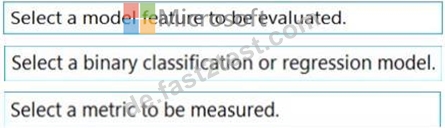
Step 1: Select a model feature to be evaluated.
Step 2: Select a binary classification or regression model.
Register your models within Azure Machine Learning. For convenience, store the results in a dictionary, which maps the id of the registered model (a string in name:version format) to the predictor itself.
Example:
model_dict = {}
lr_reg_id = register_model("fairness_logistic_regression", lr_predictor) model_dict[lr_reg_id] = lr_predictor svm_reg_id = register_model("fairness_svm", svm_predictor) model_dict[svm_reg_id] = svm_predictor Step 3: Select a metric to be measured Precompute fairness metrics.
Create a dashboard dictionary using Fairlearn's metrics package.
Reference:
https://docs.microsoft.com/en-us/azure/machine-learning/how-to-machine-learning-fairness-aml
284. Frage
You create an experiment in Azure Machine Learning Studio. You add a training dataset that contains 10,000 rows. The first 9,000 rows represent class 0 (90 percent).
The remaining 1,000 rows represent class 1 (10 percent).
The training set is imbalances between two classes. You must increase the number of training examples for class 1 to 4,000 by using 5 data rows. You add the Synthetic Minority Oversampling Technique (SMOTE) module to the experiment.
You need to configure the module.
Which values should you use? To answer, select the appropriate options in the dialog box in the answer area.
NOTE: Each correct selection is worth one point.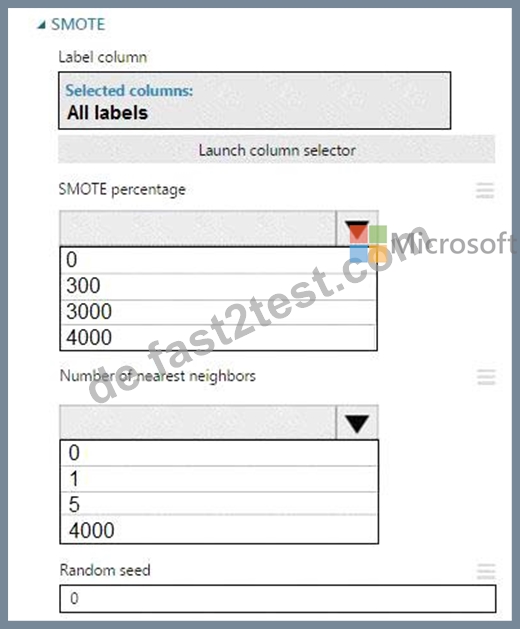
Antwort:
Begründung: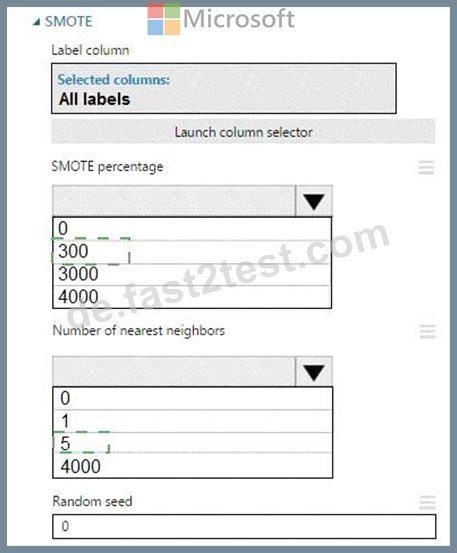
Explanation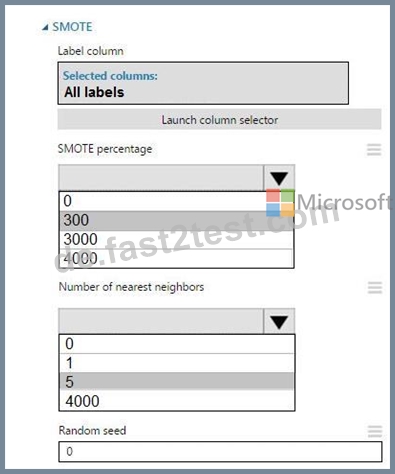
Box 1: 300
You type 300 (%), the module triples the percentage of minority cases (3000) compared to the original dataset (1000).
Box 2: 5
We should use 5 data rows.
Use the Number of nearest neighbors option to determine the size of the feature space that the SMOTE algorithm uses when in building new cases. A nearest neighbor is a row of data (a case) that is very similar to some target case. The distance between any two cases is measured by combining the weighted vectors of all features.
By increasing the number of nearest neighbors, you get features from more cases.
By keeping the number of nearest neighbors low, you use features that are more like those in the original sample.
References:
https://docs.microsoft.com/en-us/azure/machine-learning/studio-module-reference/smote
285. Frage
......
Jedem, der die Prüfungsunterlagen und Software zu Microsoft DP-100 Dumps (Designing and Implementing a Data Science Solution on Azure) von Fast2test nutzt und die IT DP-100 Zertifizierungsprüfungen nicht beim ersten Mal erfolgreich besteht, versprechen wir, die Kosten für das Prüfungsmaterial 100% zu erstatten.
DP-100 Zertifizierungsfragen: https://de.fast2test.com/DP-100-premium-file.html
Übrigens, Sie können die vollständige Version der Fast2test DP-100 Prüfungsfragen aus dem Cloud-Speicher herunterladen: https://drive.google.com/open?id=1IRtiycDezacBZI7ukzBR8zuf0sK0xs2P