Außerdem sind jetzt einige Teile dieser ZertSoft SPLK-2002 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1Kxdf9JIeocDnPuWEq93nV8_uHbTVfonK
Um jeder Splunk SPLK-2002 Prüfungsunterlagen Benutzer einen bequemen Prozess zu haben, bieten wir Ihnen 3 Versionen von Splunk SPLK-2002 Prüfungsunterlagen, nämlich PDF-, Online-, und Software-Version. Eine der Versionen kann für Sie taugen und Ihnen helfen, innerhalb der kürzesten Zeit Splunk SPLK-2002 zu bestehen und die autoritativste internationale Zertifizierung zu erwerben!
Die Splunk SPLK-2002 Prüfung ist darauf ausgelegt, die Fähigkeiten und Kenntnisse von Fachleuten zu testen, die zertifizierte Architekten in Splunk Enterprise werden möchten. Diese Zertifizierung wird weltweit als Zeichen für Expertise bei der Implementierung und Verwaltung von Splunk Enterprise-Implementierungen anerkannt. Die Prüfung umfasst eine Vielzahl von Themen, einschließlich Architekturdesign, Dateninputs und Forwarder-Management, Suche und Berichterstellung sowie Implementierungsmanagement. Ein erfolgreiches Absolvieren der SPLK-2002-Prüfung zeigt ein gründliches Verständnis von Splunk Enterprise und die Fähigkeit, komplexe Splunk-Umgebungen zu entwerfen und zu verwalten.
>> SPLK-2002 Deutsch Prüfungsfragen <<
ZertSoft ist eine Website voller Zuversicht. Die IT-Profis von ZertSoft widmen sich der Studie der vielfältigen IT-Zertifizierungsprüfungen, um die Effektivität der Erfolg der Splunk SPLK-2002 Zertifizierungsprüfungen zu verbessern. Solange Sie einmal ZertSoft Unterlagen probieren, wollen Sie unbedingt sie wieder benutzen, weil wir ZertSoft nicht nur Ihnen die besten Splunk SPLK-2002 Zertifizierungsunterlagen, sondern auch den besten Service anbieten. Wenn Sie irgendwelche Meinungen haben, senden Sie bitte ihre Vorschläge an uns per E-Mail. Wir hoffen, wir helfen Kadidaten Erfolg machen und auch bieten den besten Service.
Die Prüfung testet das Wissen der Kandidaten über die Splunk Enterprise Architektur, Bereitstellungsplanung, Installation, Konfiguration und Optimierung. Kandidaten müssen ein tiefes Verständnis für die Splunk Search Processing Language (SPL), Daten-Onboarding und Datenmanagement haben. Die Prüfung soll die Fähigkeit der Kandidaten bewerten, bewährte Verfahren für Sicherheit, Leistung und Skalierbarkeit von Splunk Enterprise-Umgebungen umzusetzen.
186. Frage
A search head cluster member contains the following in its server .conf. What is the Splunk server name of this member?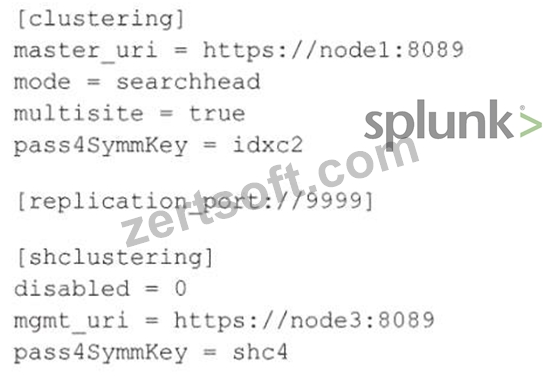
Antwort: D
Begründung:
The Splunk server name of the member can typically be determined by the serverName attribute in the server.
conf file, which is not explicitly shown in the provided snippet. However, based on the provided configuration snippet, we can infer that this search head cluster member is configured to communicate with a cluster master (master_uri) located at node1 and a management node (mgmt_uri) located at node3. The serverName is not the same as the master_uri or mgmt_uri; these URIs indicate the location of the master and management nodes that this member interacts with.
Since the serverName is not provided in the snippet, one would typically look for a setting under the [general] stanza in server.conf. However, given the options and the common naming conventions in a Splunk environment, node3 would be a reasonable guess for the server name of this member, since it is indicated as the management URI within the [shclustering] stanza, which suggests it might be the name or address of the server in question.
For accurate identification, you would need to access the full server.conf file or the Splunk Web on the search head cluster member and look under Settings > Server settings > General settings to find the actual serverName. Reference for these details would be found in the Splunk documentation regarding the configuration files, particularly server.conf.
187. Frage
(What is the best way to configure and manage receiving ports for clustered indexers?)
Antwort: A
Begründung:
According to the Indexer Clustering Administration Guide, the most efficient and Splunk-recommended way to configure and manage receiving ports for all clustered indexers (peer nodes) is through the Cluster Manager (previously known as the Master Node).
In a clustered environment, configuration changes that affect all peer nodes-such as receiving port definitions-should be managed centrally. The correct procedure is to define the inputs configuration file (inputs.conf) within the Cluster Manager's manager-apps directory. Specifically, the configuration is placed in:
$SPLUNK_HOME/etc/manager-apps/_cluster/local/inputs.conf
and then deployed to all peers using the configuration bundle push mechanism.
This centralized approach ensures consistency across all peer nodes, prevents manual configuration drift, and allows Splunk to maintain uniform ingestion behavior across the cluster.
Running splunk enable listen on each peer (Option C) or manually configuring inputs via Splunk Web (Option A) introduces inconsistencies and is not recommended in clustered deployments. Using the deployment-apps path (Option B) is meant for deployment servers, not for cluster management.
References (Splunk Enterprise Documentation):
* Indexer Clustering: Configure Peer Nodes via Cluster Manager
* Deploy Configuration Bundles from the Cluster Manager
* inputs.conf Reference - Receiving Data Configuration
* Splunk Enterprise Admin Manual - Managing Clustered Indexers
188. Frage
In search head clustering, which of the following methods can you use to transfer captaincy to a different member? (Select all that apply.)
Antwort: A,D
Begründung:
Explanation
In search head clustering, there are two methods to transfer captaincy to a different member. One method is to use the Search Head Clustering settings menu from Splunk Web on any member. This method allows the user to select a specific member to become the new captain, or to let Splunk choose the best candidate. The other method is to run the splunk transfer shcluster-captain command from the member that the user wants to become the new captain. This method requires the user to know the name of the target member and to have access to the CLI of that member. Using the Monitoring Console is not a method to transfer captaincy, because the Monitoring Console does not have the option to change the captain. Running the splunk transfer shcluster-captain command from the current captain is not a method to transfer captaincy, because this command will fail with an error message
189. Frage
Which component in the splunkd.log will log information related to bad event breaking?
Antwort: B
Begründung:
Explanation
The AggregatorMiningProcessor component in the splunkd.log file will log information related to bad event breaking. The AggregatorMiningProcessor is responsible for breaking the incoming data into events and applying the props.conf settings. If there is a problem with the event breaking, such as incorrect timestamps, missing events, or merged events, the AggregatorMiningProcessor will log the error or warning messages in the splunkd.log file. The Audittrail component logs information about the audit events, such as user actions, configuration changes, and search activity. The EventBreaking component logs information about the event breaking rules, such as the LINE_BREAKER and SHOULD_LINEMERGE settings. The IndexingPipeline component logs information about the indexing pipeline, such as the parsing, routing, and indexing phases.
For more information, see About Splunk Enterprise logging and [Configure event line breaking] in the Splunk documentation.
190. Frage
Of the following types of files within an index bucket, which file type may consume the most disk?
Antwort: B
Begründung:
Of the following types of files within an index bucket, the rawdata file type may consume the most disk. The rawdata file type contains the compressed and encrypted raw data that Splunk has ingested. The rawdata file type is usually the largest file type in a bucket, because it stores the original data without any filtering or extraction. The bloom filter file type contains a probabilistic data structure that is used to determine if a bucket contains events that match a given search. The bloom filter file type is usually very small, because it only stores a bit array of hashes. The metadata (.data) file type contains information about the bucket properties, such as the earliest and latest event timestamps, the number of events, and the size of the bucket.
The metadata file type is also usually very small, because it only stores a few lines of text. The inverted index (.tsidx) file type contains the time-series index that maps the timestamps and event IDs of the raw data. The inverted index file type can vary in size depending on the number and frequency of events, but it is usually smaller than the rawdata file type
191. Frage
......
SPLK-2002 Fragenpool: https://www.zertsoft.com/SPLK-2002-pruefungsfragen.html
Außerdem sind jetzt einige Teile dieser ZertSoft SPLK-2002 Prüfungsfragen kostenlos erhältlich: https://drive.google.com/open?id=1Kxdf9JIeocDnPuWEq93nV8_uHbTVfonK