The Microsoft world has become so competitive and challenging. To say updated and meet the challenges of the market you have to learn new in-demand skills and upgrade your knowledge. With the Microsoft DP-750 Certification Exam everyone can do this job nicely and quickly. The Implementing Data Engineering Solutions Using Azure Databricks (DP-750) certification exam offers a great opportunity to validate the skills and knowledge.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Prepare and process data | 30–35% | - Optimize and manage data storage
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Manage data sharing and permissions
|
| Topic 3: Deploy and maintain data pipelines and workloads | 30–35% | - Build and orchestrate pipelines
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
>> Exam DP-750 Study Solutions <<
Our DP-750 practice materials are suitable for a variety of levels of users, no matter you are in a kind of cultural level, even if you only have high cultural level, you can find in our DP-750 study materials suitable for their own learning methods. So, for every user of our study materials are a great opportunity, a variety of types to choose from, more and more students also choose our DP-750 Study Materials, then why are you hesitating?
NEW QUESTION # 33
What improves join performance for small lookup tables?
Answer: D
NEW QUESTION # 34
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that writes records to a Delta table named Table1 by using a data quality rule named rule1 You need to meet the following requirements:
* Records that violate rule! must NOT be written to Table1. but the pipeline must continue processing valid records.
* Data engineers must be able to review expectation metrics by using minimal development effort.
What should you do? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.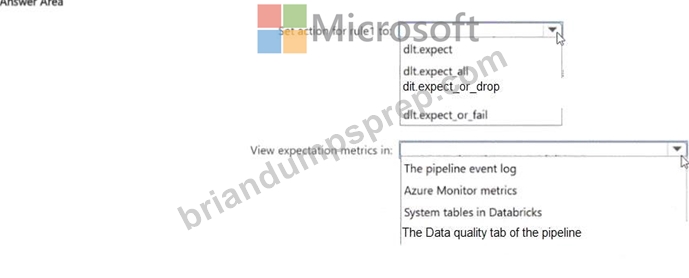
Answer:
Explanation: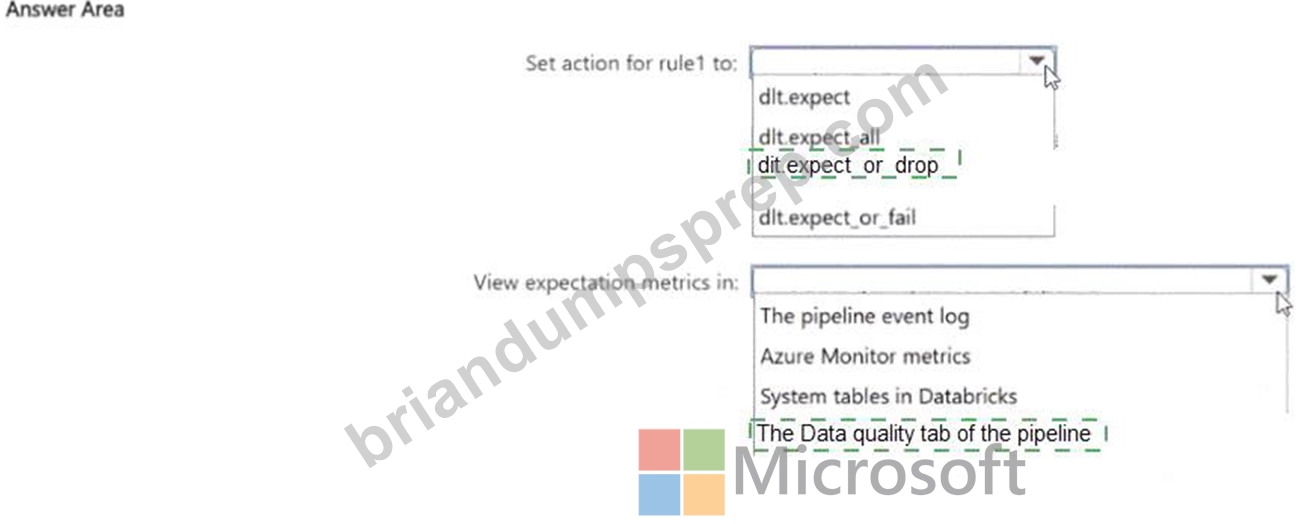
Explanation:
Two things are needed here:
For the rule enforcement: use @dlt.expect_or_drop. This drops any record that violates rule1 before it reaches Table1, while the pipeline continues processing all valid records. The table only ever receives clean data.
For reviewing metrics: the Lakeflow SDP Pipeline UI is the right tool - zero development effort required.
The pipeline graph shows expectation pass/fail counts directly on each table node, and the event log provides a detailed per-batch breakdown of how many records were dropped and why. Data engineers can inspect this at any time without writing additional monitoring queries or connecting external dashboards.
This combination is one of the strongest arguments for SDP over hand-coded Structured Streaming:
expectation observability is built in, not bolted on.
Reference: https://learn.microsoft.com/en-us/azure/databricks/delta-live-tables/expectations
NEW QUESTION # 35
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to recommend a pipeline that ingests files from cloud storage, performs cleansing and enrichment transformations, and writes curated Delta tables for analytics. The solution must minimize development effort and provide built-in monitoring and automatic retries.
What should you include in the recommendation?
Answer: D
Explanation:
The best choice is a Lakeflow Spark Declarative Pipelines (SDP) pipeline.
Low Development Effort: Lakeflow SDP (formerly known as Delta Live Tables or DLT) is a completely declarative ETL framework. You simply define the target schemas and data transformations using standard SQL or Python. Databricks automatically manages the underlying operational complexities, state maintenance, task orchestration, and DAG dependencies for you.
Built-in Quality & Monitoring: It offers out-of-the-box data monitoring capabilities via Expectations, which allow you to specify data cleansing policies (like drop, retain, or fail on bad rows) with zero custom validation code. It also captures complete, automatic end-to-end data lineage and operational stats straight into Unity Catalog.
Built-in Resilience: Infrastructure failure handling and automatic retries are natively managed by the Lakeflow runtime.
Native Storage Ingestion: Using read_files() (Auto Loader) within SDP allows effortless, incremental ingestion of files from cloud object storage directly into curated Delta tables.
Reference:
https://docs.databricks.com/aws/en/ldp/
NEW QUESTION # 36
You have an Azure Databricks workspace named Workspace1 that contains a Git folder linked to a remote Git repository. The Git folder contains a Databricks notebook named Notebook1.
From the main branch, you create a feature branch named Branch1 and commit changes to Notebook1.
Another user commits changes to Notebook1 in main.
When you attempt to merge Branch1 into main, a merge conflict occurs.
You need to ensure that Notebook1 in main includes the changes from both branches.
What should you do?
Answer: A
Explanation:
Branch1 must first incorporate the current changes from main. During that merge, the conflicting sections of Notebook1 can be reviewed and resolved so that the resulting feature-branch version contains the required work from both branches. After committing the resolution, Branch1 can be merged into main normally.
Cloning either branch into another Git folder creates another working copy but does not resolve the conflicting histories. Applying changes directly to main bypasses the controlled feature-branch workflow and risks omitting or overwriting one contributor's work. Resolving the conflict on Branch1 also allows the combined notebook to be tested before updating the shared main branch. Therefore, merging main into Branch1, resolving the conflict, and completing the final merge is the correct workflow.
NEW QUESTION # 37
Which operation guarantees ACID compliance in Delta Lake?
Answer: D
Explanation:
Delta Lake ensures ACID compliance through its transaction log (Delta log). It tracks all changes, enabling consistency, isolation, and rollback capabilities. File append operations alone are not transactional. RDD transformations are low-level and not ACID-aware.
NEW QUESTION # 38
......
The prominent benefits of Implementing Data Engineering Solutions Using Azure Databricks certification exam are validation of skills, updated knowledge, more career opportunities, instant rise in salary, and advancement of the career. Obviously, every serious professional wants to gain all these advantages. With the Microsoft DP-750 Certification Exam, you can achieve this goal nicely and quickly.
Practice DP-750 Engine: https://www.briandumpsprep.com/DP-750-prep-exam-braindumps.html