さらに、Xhs1991 DAA-C01ダンプの一部が現在無料で提供されています:https://drive.google.com/open?id=12L7ojmGEFqafmh_VavYomBfug8oT1DKf
あなたがより少ない時間と労力を置いてSnowflakeのDAA-C01試験を準備するために我々Xhs1991は多くの時間と労力を投資してあなたにソフトウェアを作成します。我々の全額で返金する承諾は話して行動しないわけではない、我々はいくつ自社製品に自信を持っても、あなたに満足させる効果がないなら、我々は速やかに全額で返金します。しかし、我々はSnowflakeのDAA-C01試験のソフトウェアは、あなたの期待に応えると信じて、私はあなたの成功を祈っています!
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Use Built-in Functions and Create UDFs | 10–15% | - Scalar, aggregate, table, system functions - User-Defined Functions (UDFs) |
| Topic 2: Prepare and Load Data | 15–20% | - File formats: CSV, JSON, Parquet, Avro - Data ingestion methods: COPY INTO, stages, Snowpipe - External tables and data validation |
| Topic 3: Perform Predictive Analysis | 5–10% | - Forecasting and predictive modeling - Using Snowflake ML and built-in analytics |
| Topic 4: Prepare and Present Data | 10–15% | - Data visualization and reporting - Align outputs with business requirements - Snowsight dashboards and sharing results |
| Topic 5: Perform Simple Data Transformations for Analysis | 15–20% | - Handling NULLs and structuring datasets - Data cleansing, standardization, type conversion - Views, materialized views, CTEs |
| Topic 6: Build and Troubleshoot Advanced SQL Queries | 20–25% | - Semi-structured data processing - Complex joins, subqueries, window functions - Query optimization and troubleshooting |
| Topic 7: Perform Descriptive and Diagnostic Analysis | 10–15% | - Anomaly detection and root cause analysis - Statistical summarization and trend analysis - Exploratory and ad-hoc analysis |
あなたより優れる人は存在している理由は彼らはあなたの遊び時間を効率的に使用できることです。どのようにすばらしい人になれますか?ここで、あなたに我々のSnowflake DAA-C01試験問題集をお勧めください。弊社Xhs1991のDAA-C01試験問題集を介して、速く試験に合格してDAA-C01試験資格認定書を受け入れる一方で、他の人が知らない知識を勉強して優れる人になることに近くなります。
質問 # 50
A Snowflake data warehouse contains a table 'CUSTOMER TRANSACTIONS with columns 'CUSTOMER ID, 'TRANSACTION DATE', 'AMOUNT', and 'PRODUCT CATEGORY'. Analysts frequently run queries that aggregate transaction amounts by product category for specific customer segments. The following query pattern is common: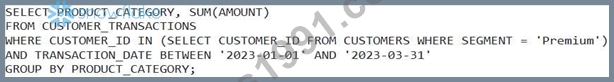
Which of the following strategies, when implemented together, would BEST optimize the performance of this query pattern, considering both result caching and data access patterns?
正解:E
解説:
Clustering 'CUSTOMER TRANSACTIONS' by 'CUSTOMER and 'TRANSACTION DATE improves data access performance by organizing data physically based on the frequently used filter criteria. Creating a materialized view that pre-aggregates the results by PRODUCT CATEGORY, 'CUSTOMER ID', and 'TRANSACTION DATE' allows Snowflake to serve the results directly from the materialized view, significantly reducing the compute cost and improving query performance. Snowflake does not use traditional indexes; clustering provides similar benefits.
質問 # 51
You have a table 'PRODUCTS' with a 'PRICE' column stored as VARCHAR. Some values in this column are valid numerical strings (e.g., '12.99'), while others contain invalid characters (e.g., '12.99USD', 'N/A'). You need to calculate the average price of all valid products. Which of the following approaches ensures that you only consider valid numeric values and handles potential errors effectively? Select all that apply.





正解:A、B
解説:
Option B is correct because it uses a regular expression to explicitly check if the PRICE column contains only valid numeric characters (digits and an optional decimal point) before attempting to cast it to a DECIMAL. 'REGEXP LIKE' ensures that non-numeric values are filtered out, preventing errors during casting, and then 'CAST is used since it is validated by the regular expression check. Option D is also correct because it uses 'CASE statement with 'IS DECIMAL' function that is a user defined function (UDF) for checking if a string can be converted to decimal, and if True, it casts the PRICE to DECIMAL; otherwise, it assigns NULL. The AVG function automatically ignores NULL values, ensuring that only valid numeric values are considered. Option A won't work as DECIMAL' function is not standard, so you will need to create user defined function. 'TO_NUMBER and 'TO_DECIMAL' throws error if it cannot parse which is not ideal. Option E, throws error if column PRICE cannot be converted, where as 'TRY TO DECIMAL' will not throw the error and return NULL.
質問 # 52
A company stores web analytics data in a Snowflake table named 'WEB EVENTS. This table includes a 'USER ID column, a 'TIMESTAMP' column indicating when the event occurred, and a 'EVENT TYPE column that captures the type of event (e.g., 'page_view', 'add_to_cart', 'purchase'). The data analysts want to enrich this data to identify the first and last event times for each user. Which Snowflake features or functions would be MOST appropriate and efficient for achieving this enrichment?
正解:A
解説:
Window functions are the most efficient approach for calculating aggregate values (like minimum and maximum) within partitions (in this case, per user) without requiring self-joins or subqueries. Correlated subqueries can be inefficient for large datasets. Stored procedures with iteration are generally slower than set-based operations. Lateral views are more suitable for exploding array structures, not for finding min/max values. A simple GROUP BY would provide the overall minimum and maximum, not per user.
質問 # 53
Why would a Data Analyst use a dimensional model rather than a single flat table to meet BI requirements for a virtual warehouse? (Select TWO).
正解:A、E
解説:
In the field of data warehousing and business intelligence (BI), choosing the right data model is crucial for long-term maintainability and user accessibility. While a single flat table might seem simple initially, dimensional modeling (typically using Star or Snowflake schemas) provides distinct advantages for enterprise analytics.
1. Scalability and Flexibility (Option C)
Combining all attributes into a single flat table creates a highly rigid structure. Every time a new attribute is added to a dimension (e.g., adding a "Promotion Category" to a product), the entire flat table must be rewritten or altered, which is inefficient for large datasets. Furthermore, flat tables often contain redundant data, leading to "update anomalies" where a change in a dimension attribute must be propagated across millions of rows. A dimensional model separates changing business processes (Facts) from the context of those processes (Dimensions), allowing the schema to scale and evolve independently.
2. Ad-hoc Analysis for Power Users (Option D)
Dimensional models are specifically designed to be intuitive for business users and BI tools. By organizing data into Facts (measurable metrics) and Dimensions (descriptive attributes), power users can easily "slice and dice" data across different hierarchies. For example, a user can quickly run an ad-hoc query to compare "Total Sales" (Fact) by "Store Region" (Dimension) and "Calendar Month" (Dimension). This structure provides a predictable and standardized "language" for the data, making it easier for users to build their own reports without needing a Data Analyst to create a custom flat table for every specific request.
Evaluating the Distractors:
* Option A and E: These are common misconceptions. Modern cloud data warehouses like Snowflake are often highly optimized for wide "flat" tables due to columnar storage and sophisticated pruning. In many cases, a flat table may actually outperform a multi-table join (dimensional model) because it avoids the computational overhead of the join itself.
* Option B: This is factually incorrect. Flat tables are denormalized (repeating data), which generally takes more storage space. Dimensional modeling is a form of normalization that saves space by storing descriptive strings once in a dimension table rather than repeating them for every transaction in a fact table.
質問 # 54
Consider a scenario where you are building a dashboard to monitor the performance of a marketing campaign. The data includes daily ad spend, website conversions, and cost per acquisition (CPA). The stakeholders need to quickly assess whether the campaign is meeting its target CPA. What visualization type would be MOST appropriate to display the current CPA compared to the target CPA, providing a clear and concise view of performance?
正解:C
解説:
A gauge chart is specifically designed to display a single value (the current CPA) in relation to a target value (the target CPA). The color-coded zones provide an immediate indication of whether the campaign is performing well, needs improvement, or is failing. Line charts show trends, bar charts compare averages, and scatter plots show relationships. Pie chart showing CPA percentage against target CPA percentage do not accurately show CPA against target CPA, for better visualization gauge charts would be the preffered option
質問 # 55
......
従来の見解では、DAA-C01練習資料は、実際の試験に現れる有用な知識を蓄積するために、それらに多くの時間を割く必要があります。 ただし、SnowPro AdvancedのSnowPro Advanced: Data Analyst Certification Exam学習に関する質問はその方法ではありません。 以前のDAA-C01試験受験者のデータによると、合格率は最大98〜100%です。 最小限の時間と費用で試験に合格するのに役立つ十分なコンテンツがあります。 SnowPro Advanced準備資料の最新コンテンツで学習できるように、当社の専門家が毎日更新状況を確認し、彼らの勤勉な仕事とDAA-C01専門的な態度が練習資料にSnowPro Advanced: Data Analyst Certification Exam品質をもたらします。 SnowPro Advancedトレーニングエンジンの初心者である場合は、疑わしいかもしれませんが、参照用に無料のデモが提供されています。
DAA-C01技術試験: https://www.xhs1991.com/DAA-C01.html
2026年Xhs1991の最新DAA-C01 PDFダンプおよびDAA-C01試験エンジンの無料共有:https://drive.google.com/open?id=12L7ojmGEFqafmh_VavYomBfug8oT1DKf