P.S.JapancertがGoogle Driveで共有している無料の2026 Snowflake SPS-C01ダンプ:https://drive.google.com/open?id=1JL3s5ZxR8EvAXokhu8jh6szhfVzLCoIx
もし弊社のSnowflakeのSPS-C01「Snowflake Certified SnowPro Specialty - Snowpark」認証試験について問題集に興味があったら、購入するまえにインターネットで弊社が提供した無料な部分問題集をダウンロードして、君の試験に役に立つかどうかのを自分が判断してください。それにJapancertは一年の無料な更新のサービスを提供いたします。
| Section | Weight | Objectives |
|---|---|---|
| Snowpark API and Development | 30% | - Multi-language support
|
| Data Transformations and Operations | 35% | - Advanced operations
|
| Snowpark Concepts and Architecture | 25% | - Session management and connection
|
| Performance and Best Practices | 10% | - Optimization techniques
|
このほど、卒業生であれば、社会人であれば、ずっと「就職難」問題が存在し、毎年、「就職氷河期」といった言葉が聞こえてくる。ブームになるIT技術業界でも、多くの人はこういう悩みがあるんですから、SnowflakeのSPS-C01の能力を把握できるのは欠かさせないない技能であると考えられます。もし我々社のJapancertのSPS-C01問題集を手に入れて、速くこの能力をゲットできます。それで、「就職難」の場合には、他の人々と比べて、あなたはずっと優位に立つことができます。
質問 # 78
You're tasked with loading data representing transactions from a legacy system into Snowflake using Snowpark. The legacy system exports the transaction data as a Python list of tuples, where each tuple contains transaction ID (integer), transaction amount (float), and transaction date (string in 'YYYY-MM-DD' format). The scale of data can be very high and need optimized way to load the data'. Your goal is to create a Snowpark DataFrame from this list of tuples, ensuring the date column is correctly interpreted as a Snowflake Date type. Which of the following approaches would be the most efficient and correct, minimizing data conversion overhead and maximizing Snowpark's capabilities?
正解:A
解説:
Option C is the most efficient and correct way. Correctness : Option C explicitly defines the schema, including the 'DateType' for the transaction date. This ensures that Snowflake correctly interprets the date column without requiring any further casting or conversion. Avoids unnecessary string conversion. Efficiency : By defining the schema upfront, you avoid schema inference during dataframe creation, which can be costly for large datasets. This also avoids the cost of explicit casting after dataframe creation (as in Option A). Maximizing Snowpark Capabilities : Directly using Snowpark API to declare data types takes full advantage of Snowpark capabilities. Option A relies on implicit schema inference, which is not optimal in scenarios with specific data type requirements, and it requires an additional step which can be costly for large data. Option B introduces a dependency on Pandas and involves converting the data to a Pandas DataFrame, then to a Snowpark DataFrame, which creates unnecessary overhead and is not the most efficient approach. Option D, although correct, requires you to create a list of dictionaries, which adds an unneeded step in between and may not be optimized. Option E relies on implicit casting; However, this can lead to failure if date format is wrong.
質問 # 79
You are developing a Snowpark application to analyze customer data'. You need to create a Snowpark DataFrame from a list of dictionaries, where each dictionary represents a customer with 'id', 'name', and 'city' keys. The data should be loaded efficiently. Consider these scenarios: 1 . The input data can sometimes contain missing values (e.g., a customer might not have a city specified). 2. You want to ensure optimal performance when loading the data, as the list can be very large. 3. You need the resulting DataFrame's schema to correctly infer the datatypes based on the input dictionary's values. Which of the following methods and considerations should be used to create a Snowpark DataFrame from a list of dictionaries to meet these requirements?
正解:A、D
解説:
Options B and D are the most appropriate. Providing an explicit schema, including specifying the 'nullable' property and datatypes, offers several advantages: 1. Handles missing values: By explicitly setting 'nullable=True' in the schema for columns that might contain missing values, you ensure that Snowflake correctly handles these as 'NULC. 2. Optimizes Performance: Specifying the schema avoids Snowflake's need to infer it, which can be a performance bottleneck, especially for large datasets. Explicit datatypes also help with storage and processing efficiency. 3. Data Type Control: You can ensure the correct data types are used for each column, preventing potential issues with data type conversions later om Option A relies on automatic schema inference, which can be inefficient and may not always correctly handle missing values or data types as expected. Option C requires explicit casting after DataFrame creation which is less efficient than specifying in the schema initially. Option E can add an unneccessary overhead since converting to Pandas DataFrame and then to Snowpark DataFrame may not be optimized.
質問 # 80
A data engineering team is developing a Snowpark application to process large volumes of data'. They aim to leverage session parameters for fine-grained control over query execution and resource allocation. Which of the following methods is the MOST efficient and secure way to set session parameters, ensuring that sensitive information like warehouse size and query timeouts are dynamically adjusted based on the workload without hardcoding values in the application?
正解:A
解説:
Option E is the most efficient and secure because it allows for a combination of pre-configured parameters from a secure source (like a configuration file) and dynamic overrides based on the specific workload. This ensures that the application can adapt to different processing needs without exposing sensitive information or hardcoding values. Account level parameters are too broad (D), Direct SQL execution is inefficient (A), Environment Variables are less secure (B), and CLI is not dynamic for in-application session settings (C).
質問 # 81
You are developing a Snowpark application to analyze website traffic data'. You have a DataFrame named 'website_logs' with columns 'user_id', 'page_url', and 'timestamp'. You need to create a new DataFrame that contains the count of distinct users who visited each page within a specific time window Consider the following (incomplete) Snowpark Python code: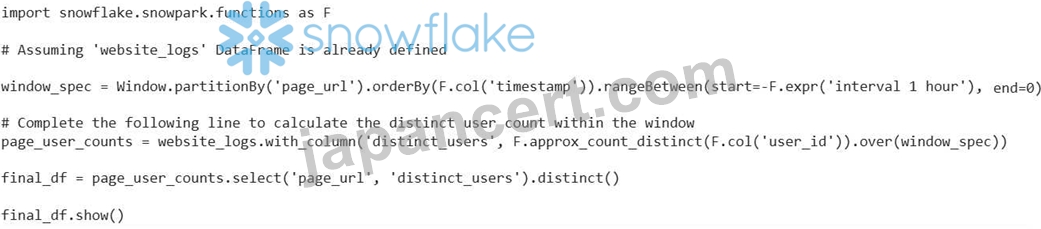
Which of the following code lines, when inserted into the Complete the following line...' comment, will correctly calculate the approximate distinct user count for each page within the specified time window?
正解:C
解説:
The correct code line is 'website_logs.with_column('distinct_users', F.approx_count_distinct('user_id').over(window_spec))'. This uses the function to calculate the approximate distinct count of user IDs within the window defined by 'window_spec' . Option B uses exact count which is less performant. Option A performs an aggregation, which will give a different type of result. Option D uses F.window' which is used for tumbling windows, not sliding windows as requested by the problem.
質問 # 82
You have a Snowpark Python stored procedure 'process_data' that takes a Snowpark DataFrame as input, performs several data transformations using functions defined in a separate Python module 'data utils.py', and returns a transformed DataFrame. The 'data utils.py' file is located in your local directory. You want to register this stored procedure so that it can be called from Snowflake. Which of the following code snippets demonstrate(s) the correct way to register the stored procedure, ensuring that the 'data utils.py' module is available within the Snowpark environment? (Select TWO)





正解:D、E
解説:
Option C correctly specifies the 'data_utils.py' file in the 'imports' parameter of the gsproc' decorator, making it available within the Snowpark environment. It also includes re-importing the 'data_utilS package within the function. Option D specifies the file in the 'imports parameter and uses the '_import_' function to load and use the module, which is a valid approach. Option A would error at runtime because "data_utils' won't be found unless it is in the same file as the stored procedure definition or the user has installed the python packages. Option B contains incorrect usage of 'return_type', and and doesn't account for importing 'data_utils.pV. Option E has the same problem as A as the dependent file 'data_utils.py' has not been imported. The 'stage_location' parameter specifies the stage where the Python file should be uploaded. The two correct ways ensure that the data_utils module will be loaded and accessible in the Snowpark environment.
質問 # 83
......
JapancertはSnowflakeのSPS-C01認定試験について開発された問題集がとても歓迎されるのはここで知識を得るだけでなく多くの先輩の経験も得ます。試験に良いの準備と自信がとても必要だと思います。使用して私たちJapancertが提供した対応性練習問題が君にとってはなかなかよいサイトだと思います。
SPS-C01模擬試験: https://www.japancert.com/SPS-C01.html
P.S. JapancertがGoogle Driveで共有している無料かつ新しいSPS-C01ダンプ:https://drive.google.com/open?id=1JL3s5ZxR8EvAXokhu8jh6szhfVzLCoIx