Certified-Data-Engineer-Professional Free Vce Dumps & Certified-Data-Engineer-Professional PDF Guide

In order to save a lot of unnecessary trouble to users, we have completed our Certified-Data-Engineer-Professional Learning Materials research and development of online learning platform, users do not need to download and install, only need your digital devices have a browser, can be done online operation of the Certified-Data-Engineer-Professional study materials. This kind of learning method is very convenient for the user, especially in the time of our fast pace to get Databricks certification. In addition, our test data is completely free of user's computer memory, will only consume a small amount of running memory when the user is using our product.
| Section | Objectives |
|---|
| Topic 1: Cost & Performance Optimisation | - Cost Optimization
- 1. Understand how Unity Catalog managed tables reduce operational overhead
- Delta Optimization
- 1. Apply data skipping and file pruning techniques
- 2. Use Change Data Feed to address streaming table limitations and improve latency
- 3. Understand deletion vectors and liquid clustering
- Query Performance
- 1. Use Query Profile to identify performance bottlenecks
- 2. Identify inefficient joins and excessive data shuffling
|
| Topic 2: Data Governance | - Metadata and Discoverability
- 1. Create and maintain descriptions and metadata for enterprise data
- Unity Catalog Permissions
- 1. Understand the Unity Catalog permission inheritance model
|
| Topic 3: Data Transformation, Cleansing, and Quality | - Advanced Data Transformation
- 1. Apply window functions, joins, and aggregations to large datasets
- 2. Write efficient Spark SQL and PySpark transformations
- Data Quality
- 1. Apply data quality controls using Lakeflow Spark Declarative Pipelines or Auto Loader
- 2. Develop data quarantining processes for invalid data
|
| Topic 4: Data Sharing and Federation | - Lakehouse Federation
- 1. Configure Lakehouse Federation with appropriate governance
- Delta Sharing
- 1. Configure sharing with external platforms using the open sharing protocol
- 2. Configure Databricks-to-Databricks Sharing
- 3. Share live Lakehouse data with external computing platforms
|
| Topic 5: Developing Code for Data Processing using Python and SQL | - Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDFs
- 2. Design and implement scalable Python project structures optimized for Databricks Asset Bundles
- 3. Manage and troubleshoot third-party library installations and dependencies
- Building and Testing ETL Pipelines
- 1. Use APPLY CHANGES APIs for change data capture
- 2. Create and automate ETL workloads using Jobs through UI, APIs, and CLI
- 3. Develop unit and integration tests for data processing code
- 4. Compare streaming tables and materialized views
- 5. Compare Spark Structured Streaming and Lakeflow Spark Declarative Pipelines
- 6. Build production-ready batch and streaming pipelines using Lakeflow Spark Declarative Pipelines and Auto Loader
- 7. Use control flow operators in pipeline components
- 8. Configure environments, dependencies, memory, and retry behavior
|
| Topic 6: Monitoring and Alerting | - Monitoring
- 1. Use Query Profiler and Spark UI to monitor workloads
- 2. Use Lakeflow Spark Declarative Pipelines event logs for monitoring
- 3. Use system tables for resource, cost, audit, and workload monitoring
- 4. Use Databricks REST APIs and CLI for monitoring jobs and pipelines
- Alerting
- 1. Use SQL Alerts for data quality monitoring
- 2. Configure Lakeflow Jobs notifications for job status and performance issues
|
| Topic 7: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Spark UI, cluster logs, system tables, and query profiles for diagnostics
- 2. Use Lakeflow Spark Declarative Pipelines event logs and Spark UI for debugging
- 3. Analyze errors and remediate failed job runs
- Deploying CI/CD
- 1. Integrate Git-based CI/CD workflows using Databricks Git Folders
- 2. Build and deploy Databricks resources using Databricks Asset Bundles
|
| Topic 8: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest data from message buses and cloud storage
- 2. Build append-only pipelines for batch and streaming data using Delta
- 3. Ingest Delta Lake, Parquet, ORC, Avro, JSON, CSV, XML, Text, and Binary data
|
| Topic 9: Ensuring Data Security and Compliance | - Data Security
- 1. Apply anonymization and pseudonymization techniques
- 2. Use row filters and column masks for sensitive data
- 3. Use ACLs to secure workspace objects and enforce least privilege
- Compliance
- 1. Implement pipelines that detect and mask personally identifiable information
- 2. Develop data purging solutions according to data retention policies
|
| Topic 10: Data Modelling | - Scalable Data Models
- 1. Design and implement scalable data models using Delta Lake
- 2. Understand Liquid Clustering versus partitioning and Z-Ordering
- 3. Optimize data layout using Liquid Clustering
- Dimensional Modelling
- 1. Design dimensional models for analytical workloads
|
>> Certified-Data-Engineer-Professional Free Vce Dumps <<
Certified-Data-Engineer-Professional PDF Guide | Certified-Data-Engineer-Professional Latest Exam Registration
Whether for a student or an office worker, obtaining Certified-Data-Engineer-Professional certificate can greatly enhance the individual's competitiveness in the future career. Try our Certified-Data-Engineer-Professional study materials, which are revised by hundreds of experts according to the changes in the syllabus and the latest developments in theory and practice. Once you choose Certified-Data-Engineer-Professional training dumps, passing the exam one time is no longer a dream.
Databricks Certified Data Engineer Professional Sample Questions (Q169-Q174):
NEW QUESTION # 169
A junior data engineer has manually configured a series of jobs using the Databricks Jobs UI.
Upon reviewing their work, the engineer realizes that they are listed as the "Owner" for each job.
They attempt to transfer "Owner" privileges to the "DevOps" group, but cannot successfully accomplish this task.
Which statement explains what is preventing this privilege transfer?
- A. Other than the default "admins" group, only individual users can be granted privileges on jobs.
- B. A user can only transfer job ownership to a group if they are also a member of that group.
- C. Only workspace administrators can grant "Owner" privileges to a group.
- D. Databricks jobs must have exactly one owner; "Owner" privileges cannot be assigned to a group.
- E. The creator of a Databricks job will always have "Owner" privileges; this configuration cannot be changed.
Answer: D
Explanation:
A job cannot have more than one owner. A job cannot have a group as an owner.
NEW QUESTION # 170
A user wants to use DLT expectations to validate that a derived table report contains all records from the source, included in the table validation_copy.
The user attempts and fails to accomplish this by adding an expectation to the report table definition.
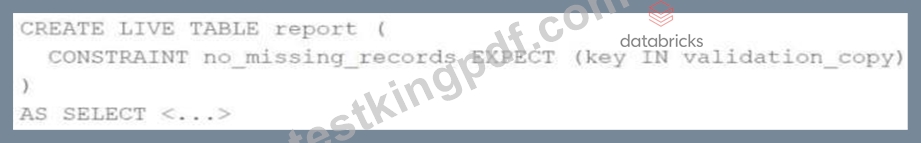
Which approach would allow using DLT expectations to validate all expected records are present in this table?
- A. Define a temporary table that perform a left outer join on validation_copy and report, and define an expectation that no report key values are null
- B. Define a SQL UDF that performs a left outer join on two tables, and check if this returns null values for report key values in a DLT expectation for the report table.
- C. Define a view that performs a left outer join on validation_copy and report, and reference this view in DLT expectations for the report table
- D. Define a function that performs a left outer join on validation_copy and report and report, and check against the result in a DLT expectation for the report table
Answer: C
Explanation:
To validate that all records from the source are included in the derived table, creating a view that performs a left outer join between the validation_copy table and the report table is effective. The view can highlight any discrepancies, such as null values in the report table's key columns, indicating missing records. This view can then be referenced in DLT (Delta Live Tables) expectations for the report table to ensure data integrity. This approach allows for a comprehensive comparison between the source and the derived table.
NEW QUESTION # 171
A faulty IoT sensor in a factory reports a temperature of -500, causing the LDP pipeline to fail the expectation, which only allows values between -100 and 200 degrees Celsius. The data engineer would like to further analyze the faulty data to better understand the reason behind this. How should the data engineer resolve the faulty data while ensuring data quality standards are maintained?
- A. Change the expectation action from fail to warn so that invalid records are included in the output and the pipeline does not fail.
- B. Ignore the error and simply re-run the pipeline, as Databricks will automatically skip the problematic record on the next run.
- C. Remove all expectations form the pipeline to prevent any future failures, regardless of data quality.
- D. Fix the pipeline code and implement a quarantine logic to isolate the faulty data before re-running the pipeline.
Answer: D
Explanation:
Implementing quarantine logic allows invalid records to be isolated for further analysis while keeping them out of trusted datasets. Fixing the pipeline and re-running it ensures the expectation continues to enforce data quality standards, prevents future failures, and enables root-cause analysis of the faulty sensor data without compromising downstream consumers.
NEW QUESTION # 172
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame named preds with the schema "customer_id LONG, predictions DOUBLE, date DATE".
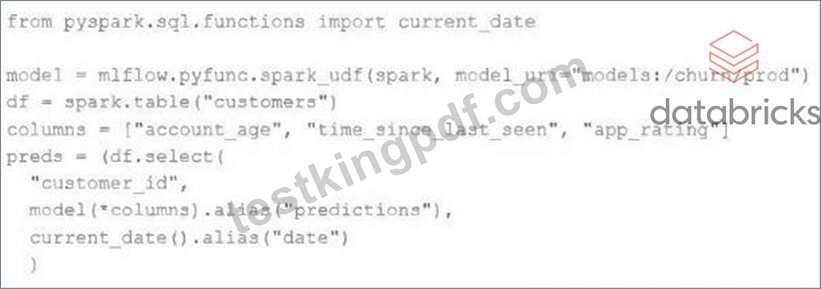
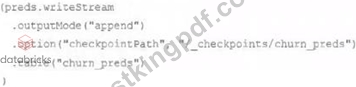
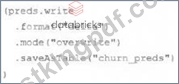
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
- A. preds.write.mode("append").saveAsTable("churn_preds")
- B.
- C. preds.write.format("delta").save("/preds/churn_preds")
- D.
- E.
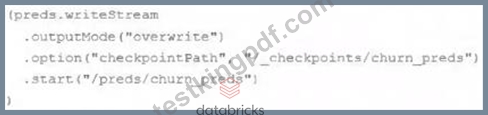
Answer: A
NEW QUESTION # 173
A platform team lead is responsible for automating the individual teams attribution towards SQL Warehouse usage. The requirement is to identify the SQL warehouse usage at the individual user's level and generate a daily report to be shared with an executive team that includes leaders from all business units. How should the platform lead generate an automated report that can be shared daily?
- A. Use the system tables to capture the audit and billing usage data and share the queries with the executive team. This enables the executives to execute the query and see the latest results any time.
- B. Restrict users from running any SQL query unless they provide all the query details so that the attribution can be calculated and shared with the executive team.
- C. Let the users run the SQL query and then directly report the usage to the executives. The ownership of the SQL warehouse usage will be with the individual teams.
- D. Use the system tables to capture the audit and billing usage data and create a dashboard with daily refresh schedules and shared with the executive team.
Answer: D
Explanation:
System tables provide authoritative audit and billing data needed for per-user SQL Warehouse attribution. Creating a dashboard with a scheduled daily refresh automates report generation and ensures executives receive consistent, up-to-date insights without needing to run queries themselves.
NEW QUESTION # 174
......
Our Certified-Data-Engineer-Professional exam training material is organized by high experienced IT workers. Our IT elite team offer new version of Certified-Data-Engineer-Professional Exam real questions gradually, which aims to ensure examinees pass Certified-Data-Engineer-Professional test in one time.
Certified-Data-Engineer-Professional PDF Guide: https://www.testkingpdf.com/Certified-Data-Engineer-Professional-testking-pdf-torrent.html
- Certified-Data-Engineer-Professional Practical Information Ⓜ Certified-Data-Engineer-Professional Free Sample Questions 🍹 Certified-Data-Engineer-Professional New Exam Bootcamp 📧 Go to website [ www.prepawaypdf.com ] open and search for ⮆ Certified-Data-Engineer-Professional ⮄ to download for free 🌹Certified-Data-Engineer-Professional Verified Answers
- 2026 Certified-Data-Engineer-Professional Free Vce Dumps | Newest Certified-Data-Engineer-Professional 100% Free PDF Guide 🤵 Search for ➠ Certified-Data-Engineer-Professional 🠰 on “ www.pdfvce.com ” immediately to obtain a free download 🍀Certified-Data-Engineer-Professional Latest Exam Cram
- 2026 Certified-Data-Engineer-Professional Free Vce Dumps | Newest Certified-Data-Engineer-Professional 100% Free PDF Guide 🏯 ☀ www.testkingpass.com ️☀️ is best website to obtain ▛ Certified-Data-Engineer-Professional ▟ for free download 🎑Certified-Data-Engineer-Professional Latest Exam Cram
- Certified-Data-Engineer-Professional Latest Braindumps 🥰 Certified-Data-Engineer-Professional Valid Exam Blueprint 🚎 Certified-Data-Engineer-Professional Latest Mock Exam 🔈 Go to website ⮆ www.pdfvce.com ⮄ open and search for ☀ Certified-Data-Engineer-Professional ️☀️ to download for free 🗾Certified-Data-Engineer-Professional Valid Dump
- Excellent Web-Based Databricks Certified-Data-Engineer-Professional Practice Exam 🕦 Simply search for ▷ Certified-Data-Engineer-Professional ◁ for free download on “ www.torrentvce.com ” 🥪Certified-Data-Engineer-Professional Dumps PDF
- Certified-Data-Engineer-Professional Practical Information 🏜 Reliable Certified-Data-Engineer-Professional Exam Pattern 🤳 Certified-Data-Engineer-Professional Dumps PDF 😌 Search for ➥ Certified-Data-Engineer-Professional 🡄 and obtain a free download on ➤ www.pdfvce.com ⮘ ☑Certified-Data-Engineer-Professional Reliable Exam Sample
- Certified-Data-Engineer-Professional Valid Exam Blueprint 🧄 Certified-Data-Engineer-Professional Practical Information 🟤 Certified-Data-Engineer-Professional Practical Information 🕊 Search for ⏩ Certified-Data-Engineer-Professional ⏪ and download it for free immediately on ➡ www.testkingpass.com ️⬅️ 🐶Certified-Data-Engineer-Professional Verified Answers
- New Certified-Data-Engineer-Professional Exam Camp 🐂 Certified-Data-Engineer-Professional New Exam Bootcamp ⬛ Certified-Data-Engineer-Professional Free Sample Questions 📦 Search for 《 Certified-Data-Engineer-Professional 》 and download exam materials for free through ( www.pdfvce.com ) ➡Exam Dumps Certified-Data-Engineer-Professional Zip
- Certified-Data-Engineer-Professional Valid Dump 🌐 Certified-Data-Engineer-Professional Prepaway Dumps ♥ Certified-Data-Engineer-Professional Valid Dump 🐜 Search for ➤ Certified-Data-Engineer-Professional ⮘ and obtain a free download on ⮆ www.troytecdumps.com ⮄ 🛕Certification Certified-Data-Engineer-Professional Torrent
- Certified-Data-Engineer-Professional Latest Exam Cram 🐕 Reliable Certified-Data-Engineer-Professional Exam Pattern 🦏 Certified-Data-Engineer-Professional Free Sample Questions 🔥 Immediately open ⮆ www.pdfvce.com ⮄ and search for “ Certified-Data-Engineer-Professional ” to obtain a free download ⏭Certified-Data-Engineer-Professional Free Sample Questions
- Pass Guaranteed 2026 Databricks Certified-Data-Engineer-Professional: First-grade Databricks Certified Data Engineer Professional Free Vce Dumps 🦈 Search for ➥ Certified-Data-Engineer-Professional 🡄 and easily obtain a free download on ▛ www.testkingpass.com ▟ 🦉Certified-Data-Engineer-Professional New Exam Bootcamp
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, learn.csisafety.com.au, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes