BTW, DOWNLOAD part of ITdumpsfree DP-750 dumps from Cloud Storage: https://drive.google.com/open?id=1KG6psciF5TRtALcKKdCpBrxRLAdYd1pV
The DP-750 Exam Questions is of the highest quality, and it enables participants to pass the DP-750 exam on their first try. For successful preparation, it is essential to have good DP-750 exam dumps and to prepare questions that may come up in the exam. ITdumpsfree helps candidates overcome all the difficulties they may encounter in their exam preparation. To ensure the candidates' satisfaction, ITdumpsfree has a support team that is available 24/7 to assist with a wide range of issues.
| Section | Weight | Objectives |
|---|---|---|
| Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Prepare and process data | 30-35% | - Data transformation and modeling
|
| Secure and govern data using Unity Catalog | 15-20% | - Access control and policies
|
Our DP-750 free dumps demo will provide you some basic information for the accuracy of our exam materials. All questions and answers in our DP-750 real dumps are tested by our certified trainers with rich experience and one or two days is enough for you practicing Valid DP-750 Exam Pdf. Our DP-750 dumps torrent contains everything you want to solve the challenge of real exam.
NEW QUESTION # 76
You have an Azure Databricks workspace and a remote Git repository named Repo1. Repo1 contains two branches named main and Branch1.
You are on a development team that works in Repo1.
You commit changes to Branch1 and must merge the changes into main.
Before completing the merge, you need to meet the following requirements:
* Ensure that Branch1 includes the changes committed to main since Branch1 was created.
* Ensure that merge conflicts are detected and resolved.
What should you do first?
Answer: D
Explanation:
The latest remote changes from main must first be retrieved so that the development environment has the current main-branch state. After pulling those updates, main can be merged into Branch1, and any conflicts can be detected and resolved before Branch1 is proposed for integration into main. Immediately merging a stale local copy of main into Branch1 could omit commits added remotely after Branch1 was created. Pulling Branch1 only synchronizes the feature branch and does not retrieve the required main-branch changes.
Creating a pull request before updating and testing Branch1 would defer conflict discovery until later in the integration process. Pulling the latest main changes is therefore the correct first operation in the sequence.
Microsoft Learn
NEW QUESTION # 77
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You plan to run the following PySpark code.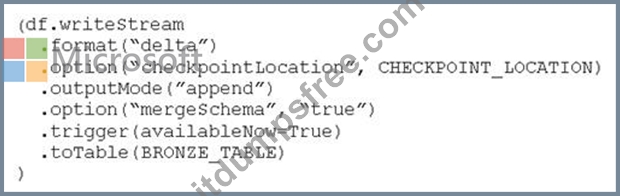
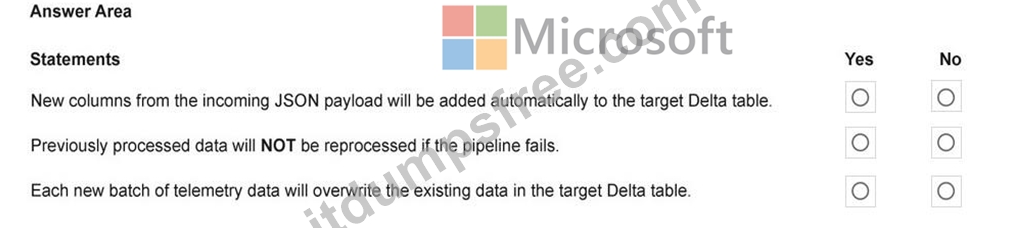
Answer:
Explanation: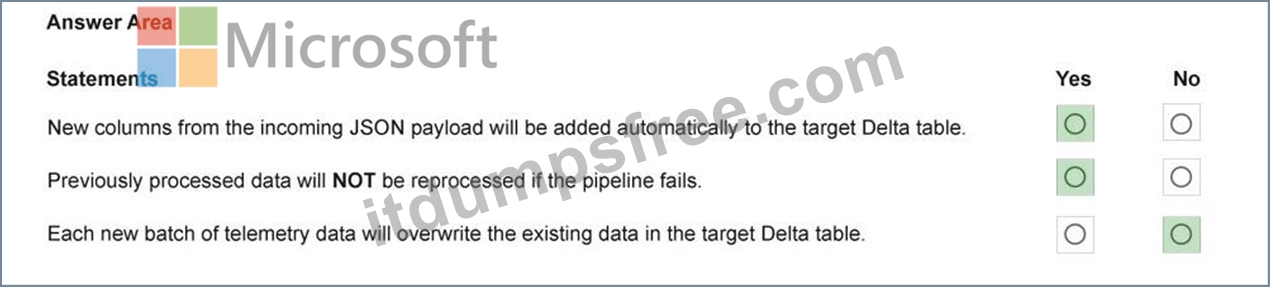
NEW QUESTION # 78
You need to deploy Databricks Asset Bundles to a development environment. The solution must support automated and repeatable deployments across environments. What should you use?
Answer: C
Explanation:
The best option to use is the Databricks CLI.
The Databricks CLI is the core orchestration tool natively designed to validate, deploy, and manage Declarative Automation Bundles (formerly known as Databricks Asset Bundles) across multiple target environments using simple terminal commands like databricks bundle deploy.
Incorrect:
[Not A]
Git folders: Git folders are strictly a mechanism for version control, code syncing, and repository collaboration inside the workspace. While they are highly integrated with bundle development, they cannot directly deploy or provision bundle targets to isolated environments on their own without the CLI.
[Not C]
Databricks SDK for Python: While the Python SDK provides general programmatic access to Databricks APIs, it is not the primary or optimized tool for executing bundle operations. The bundle framework natively relies on the Databricks CLI executable to compile and translate your configurations.
[Not D]
Jobs UI: The Jobs user interface is built for manual interactions. It does not support native bundle multi-environment targeting or automated, repeatable CI/CD pipelines.
Reference:
https://docs.databricks.com/aws/en/dev-tools/bundles/
NEW QUESTION # 79
You have an Azure Databricks workspace that contains a Git folder and uses Azure Repos as the Git provider.
From the main branch, you create a branch named Branch1. You commit changes to Branch1.
You need to incorporate the changes from Branch1 into main. The solution must preserve the commit history in the repository.
Which command should you run?
Answer: D
Explanation:
To incorporate changes from your feature branch into the main branch while keeping every individual commit intact, you must use a fast-forward merge or a standard merge commit.
In the Azure Databricks Git folders UI or via standard Git operations, use the following command:
The Correct Command: git merge <branch-name>
Preserves History: Unlike a squash merge, a standard merge keeps all individual commit messages, authors, and timestamps.
Maintains Timeline: It seamlessly integrates the exact commit graph from your feature branch into the main branch.
Reference:
https://docs.databricks.com/aws/en/repos/git-operations-with-repos
NEW QUESTION # 80
You have an Azure Databricks workspace that contains a Delta table named Customer.
A job named Job1 performs frequent upserts into Customer.
You discover that Job1 has created many small Parquet files in Customer, and the small files are degrading query performance.
You need to improve query performance for the current data already stored in Customer. The solution must not affect the travel for the Customer table.
What should you do?
Answer: A
Explanation:
The OPTIMIZE command performs bin-packing compaction, combining the Customer table's existing small Parquet files into fewer, larger files. This reduces file-open overhead and improves data-skipping efficiency without changing the logical table contents. Enabling optimized writes affects future write operations but does not compact the small files already stored. VACUUM removes unreferenced data files that are older than the configured retention threshold; it does not reorganize active small files and can restrict time-travel availability. Reducing delta.deletedFileRetentionDuration changes how long obsolete files remain available and can directly reduce the time-travel window, contrary to the requirement. OPTIMIZE is therefore the correct operation for improving the physical layout of current data while preserving Delta table semantics and history. Microsoft Learn
NEW QUESTION # 81
......
In this era, everything is on the rise. Do not you want to break you own? Double your salary, which is not impossible. Through the Microsoft DP-750 Exam, you will get what you want. ITdumpsfree will provide you with the best training materials, and make you pass the exam and get the certification. It's a marvel that the pass rate can achieve 100%. This is indeed true, no doubt, do not consider, act now.
DP-750 Latest Exam Forum: https://www.itdumpsfree.com/DP-750-exam-passed.html
P.S. Free & New DP-750 dumps are available on Google Drive shared by ITdumpsfree: https://drive.google.com/open?id=1KG6psciF5TRtALcKKdCpBrxRLAdYd1pV