We value every customer who purchases our DP-750 test material and we hope to continue our cooperation with you. Our DP-750 test questions are constantly being updated and improved so that you can get the information you need and get a better experience. Our DP-750 test questions have been following the pace of digitalization, constantly refurbishing, and adding new things. I hope you can feel the DP-750 Exam Prep sincerely serve customers. We also attach great importance to the opinions of our customers. As long as you make reasonable recommendations for our DP-750 test material, we will give you free updates to the system's benefits. The duration of this benefit is one year, and DP-750 exam prep look forward to working with you.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Deploy and maintain data pipelines and workloads | 30–35% | - Monitor, troubleshoot, and maintain workloads
|
| Topic 2: Secure and govern Unity Catalog objects | 15–20% | - Implement data governance and security
|
| Topic 3: Prepare and process data | 30–35% | - Ingest and transform data
|
| Topic 4: Set up and configure an Azure Databricks environment | 15–20% | - Select and configure compute resources
|
>> Latest DP-750 Practice Materials <<
The desktop Microsoft DP-750 practice exam software has all specifications of the web-based format. It is offline software that enables users to go through the Selling Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam without having any internet connection. Windows computers support the desktop Implementing Data Engineering Solutions Using Azure Databricks (DP-750) practice exam software.
NEW QUESTION # 71
You have an Azure Databricks workspace that uses Unity Catalog.
You have a Lakeflow Spark Declarative Pipelines (SDP) pipeline that ingests data into a managed Delta table named Table1. Table1 is used for analytics.
New columns are added to the source data, causing pipeline failures during writes to Table1.
You need to prevent the pipeline failures. The solution must ensure that schema changes are detected and handled.
What should you do?
Answer: C
Explanation:
Schema evolution allows the target Delta table to incorporate compatible new source columns instead of failing when the incoming schema changes. This is the appropriate response to additive schema drift and avoids manually rebuilding tables whenever the source evolves. Creating a separate table for every schema version would fragment the dataset and increase operational effort. Disabling schema enforcement removes valuable protection against incompatible or corrupt data rather than handling legitimate evolution safely. Row filters operate on records and cannot remove an unexpected column from the incoming schema. With schema evolution enabled, the pipeline can detect new fields, update the target schema, and continue processing while retaining Delta Lake's transactional guarantees. The solution therefore supports changing source data without sacrificing the managed-table architecture.
NEW QUESTION # 72
You have an Azure Databricks workspace named Workspace1 that contains a cluster named Cluster1.
You need to enable a user named User1 to install a Maven package on all the nodes of Cluster1. The solution must follow the principle of least privilege.
What should you do?
Answer: A
Explanation:
Installing a Maven package on every node requires changing Cluster1's library configuration. The CAN MANAGE permission grants the cluster-level management capabilities required to add or remove libraries without giving User1 broader control over the entire workspace or Azure resource group. CAN RESTART allows a user to restart the cluster but does not provide sufficient authority to change its library configuration.
Assigning the Azure Contributor role would grant excessive control over the resource group and does not represent the appropriate Databricks object-level permission. Making User1 a workspace administrator would provide substantially more privileges than necessary. Granting CAN MANAGE directly on Cluster1 therefore satisfies the operational requirement while limiting User1's authority to the specific compute resource that must be modified.
NEW QUESTION # 73
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a Delta table named db1.sales_orders.
db1.sales_orders is updated nightly and has change data feed (CDF) enabled.
You need to ingest all the changes from the db1.sales_orders table, including inserts, updates, and deletes, into a downstream pipeline.
How should you complete the PsySpark code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.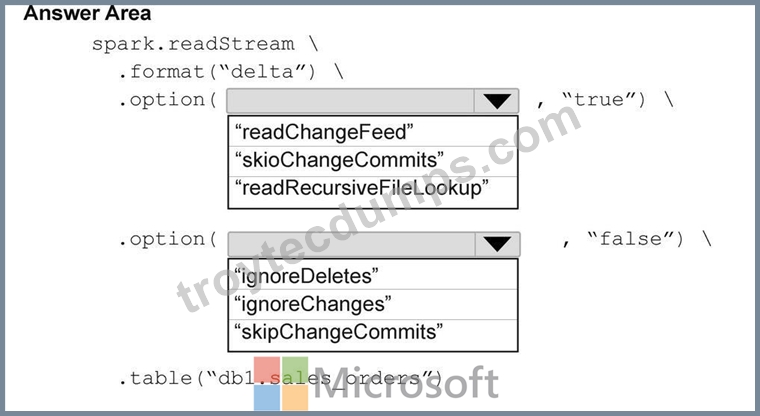
Answer:
Explanation: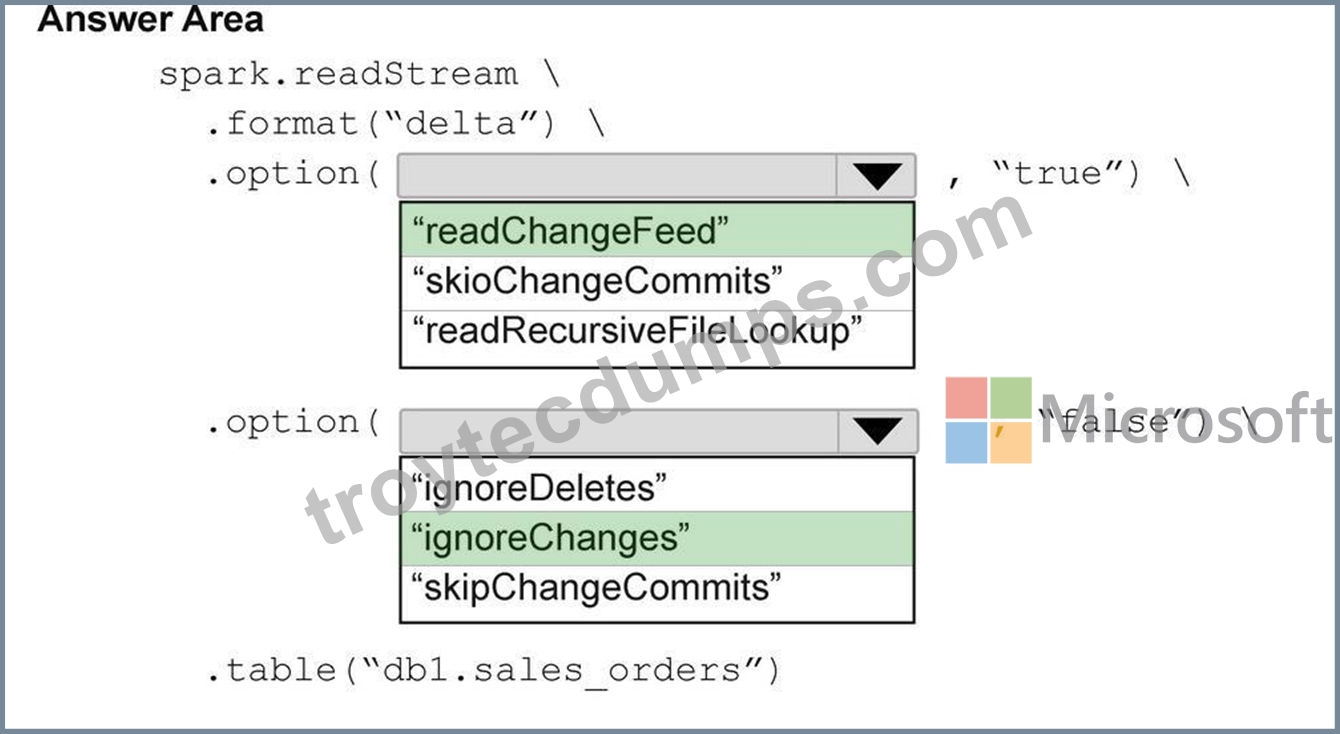
NEW QUESTION # 74
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1. Job1 contains multiple tasks.
Failures of non-critical tasks must be logged but must NOT trigger notifications. Notifications must be triggered only when critical tasks have failed, and Job1 has completed You need to configure the job alerting behavior.
What should trigger a notification?
Answer: C
Explanation:
The correct answer is B - a job failure.
The requirement draws a clear line: non-critical task failures should be logged silently; notifications should only fire when a critical failure causes the whole job to stop. Configuring the alert on 'Job Failure' achieves this precisely - the notification triggers when the job itself reaches a Failed terminal state, which only happens when at least one critical task has failed and the job cannot complete.
Option A (task failure) would send a notification for every task-level failure, including non-critical ones.
That's exactly the noise the question wants to avoid. Option C (job success) would never alert on failures at all. Option D (task success) confirms completion but doesn't catch failures.
Setting alerting at the job level rather than the task level is also simpler to configure - you don't need to mark individual tasks as critical or non-critical in the notification settings.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/alerts
NEW QUESTION # 75
You need to develop the task logic for a new job in Lakeflow Jobs that processes telemetry data.
Each task must contain only the appropriate logic for its step in the pipeline. The solution must support the planned changes and meet the data ingestion and processing requirements.
What should you do?
Answer: D
Explanation:
The correct answer is D. Breaking the pipeline into separate tasks for ingestion, cleansing, and curation is the foundation of well-designed Lakeflow Jobs pipelines. Each task should own one responsibility - when a task does too much, debugging a failure becomes a hunt through unrelated code, and retry logic becomes expensive because you re-execute work that already succeeded.
Contoso's planned changes explicitly call for 'a clear execution order and dependencies' and 'orchestrate multi- step ingestion and transformation workflows.' Separate tasks map directly to those goals: Lakeflow Jobs tracks each task's status independently, so if cleansing fails, ingestion doesn't re-run.
Option A bundles everything into one notebook, which means a curation bug forces a full re-ingestion. Option B copies logic three times - any future change must be applied in triplicate, which is a maintenance hazard.
Option C forces everything through SQL MERGE, which is the wrong tool for raw-event ingestion and doesn't address cleansing or schema drift.
Reference: https://learn.microsoft.com/en-us/azure/databricks/jobs/
Topic 1, Contoso Case Study
Overview
Contoso has a single Azure Databricks workspace named Workspace1 in the West US Azure region.
Workspace1 is enabled for Unity Catalog.
Workspace1 contains all-purpose clusters for both development and production workloads.
The company's Azure environment contains:
* In the West US, Central US, and East US Azure regions, Azure event hubs that stream telemetry data and an Azure Data Lake Storage Gen2 account in each region for each hub
* A single Azure SQL database in the West US region that hosts enterprise resource planning (ERP) data
* An Azure Database for PostgreSQL server in the West US region that stores operational maintenance data Company information Contoso, Inc. is a renewable energy provider that operates solar and wind farms across North America.
Data Environment
Contoso ingests the following operational and business data:
* Telemetry data: More than 40,000 loT sensors across 28 sites emit JSON telemetry events every few seconds. Each site sends the events to the nearest event hub, which writes the data into the corresponding Data Lake Storage Gen2 account. These files frequently experience schema drift.
* Maintenance logs: Maintenance systems generate historical repair logs, daily incremental updates, technician notes, and unstructured attachments that are stored in the Data Lake Storage Gen2 accounts.
* Operational maintenance data: Structured operational maintenance data is stored on the Azure Database for PostgreSQL server.
* External weather data: Hourly weather forecasts are retrieved from a REST API and written to the Data Lake Storage Gen2 accounts.
* ERP data: Daily CSV extracts of 50 to 100 GB contain equipment metadata, work orders, and purchase order information.
Problem Statements
The company's existing analytics environment has several issues:
Ingestion
* Telemetry pipelines fall behind during peak loads.
* Telemetry ingestion fails when schema drift occurs.
* Streaming pipelines reprocess events after a pipeline restarts.
Compute
* Production and development workloads run on the same all-purpose clusters.
* Production and development workloads do NOT support autoscaling or workload isolation.
Governance
* The ERP data is duplicated across systems and development teams.
* Naming conventions are inconsistent across development teams, regions, and products.
* Ownership of the loT sensors changes over time, and analysts must track the full history of the ownership.
* Occasionally, equipment manufacturers must correct data-entry mistakes in equipment names. Historical values are NOT required.
Pipeline operations
* Pipelines lack resiliency, alerting, and centralized scheduling.
Planned Changes
Contoso plans to implement the following changes:
* Implement scalable data pipeline orchestration.
* Create a managed analytics catalog in Unity Catalog.
* Implement a consistent approach to creating curated datasets.
* Establish a centralized governance model across ingestion, cleansed, and curated layers.
* Grant data engineers access to the ERP tables by using minimal development effort.
* Adopt a compute strategy that isolates production workloads and supports autoscaling.
* Adopt a slowly changing dimension (SCD) approach to address current data modeling issues.
Technical Requirements
Contoso identifies the following environment and compute requirements:
* Ensure that production ingestion workloads run on compute clusters that can scale automatically during telemetry spikes.
* Provide fast and consistent performance for business intelligence (Bl) workloads.
* Prevent development activity from affecting production pipelines.
* Production ingestion workloads must run as scheduled, non-interactive pipelines rather than on shared interactive development clusters.
Contoso identifies the following data ingestion and processing requirements:
* Auto-scale ingestion pipelines to handle bursty workloads.
* Handle schema drift for the maintenance and telemetry data.
* Ingest file-based telemetry data by using minimal operational effort.
* Store all the ingested data in a format that supports incremental processing.
* Support the continuous ingestion of telemetry data from the event hubs by using exactly-once semantics.
* Support the ingestion of the structured maintenance data from the Azure Database for PostgreSQL server.
* Build a new telemetry pipeline that ingests raw events from the event hubs, cleanses the data, and publishes curated tables to Unity Catalog.
* Ensure that the Apache Spark Structured Streaming pipelines reading from the event hubs write the data into a managed Delta table named telemetry.raw_events. The pipelines must support schema drift and resume processing after failures without reprocessing the data.
Contoso identifies the following data modeling and optimization requirements:
* Build curated tables that standardize business logic.
* Overwrite equipment metadata attributes, such as name, manufacturer, model, and commissioning date, when the attributes change. Historical values are NOT required.
Contoso identifies the following pipeline deployment and operation requirements: |