BTW, DOWNLOAD part of BraindumpsIT DP-100 dumps from Cloud Storage: https://drive.google.com/open?id=1KCuOzZL7yGcpwhsDjAJQnV5gowsFqHfq
BraindumpsIT's Microsoft DP-100 exam training material is the best training materials on the Internet. It is the leader in all training materials. It not only can help you to pass the exam, you can also improve your knowledge and skills. Help you in your career in your advantage successfully. As long as you have the Microsoft DP-100 Certification, you will be treated equally by all countries.
| Section | Weight | Objectives |
|---|---|---|
| Explore data and run experiments | 20-25% | - Explore and visualize data
|
| Optimize language models for AI applications | 25-30% | - Optimize with Retrieval Augmented Generation
|
| Design and prepare a machine learning solution | 20-25% | - Manage compute resources
|
| Train and deploy models | 25-30% | - Monitor and maintain models
|
The Designing and Implementing a Data Science Solution on Azure (DP-100) practice questions give you a feeling of a real exam which boost confidence. Practice under real Designing and Implementing a Data Science Solution on Azure (DP-100) exam situations is an excellent way to learn more about the complexity of the Microsoft DP-100 Exam Dumps. You can learn from your Designing and Implementing a Data Science Solution on Azure (DP-100) practice test mistakes and overcome them before the actual DP-100 exam.
NEW QUESTION # 390
You need to define an evaluation strategy for the crowd sentiment models.
Which three actions should you perform in sequence? To answer, move the appropriate actions from the list of actions to the answer area and arrange them in the correct order.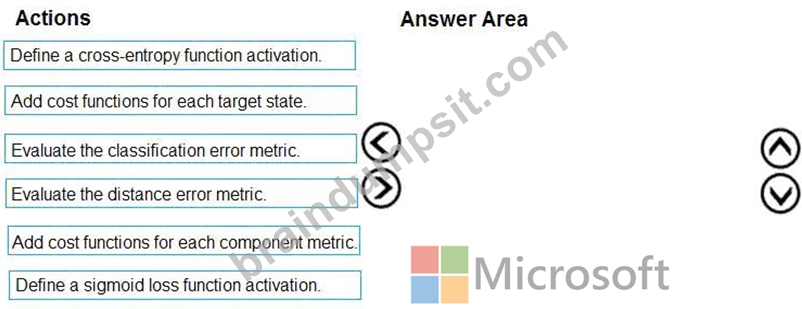
Answer:
Explanation: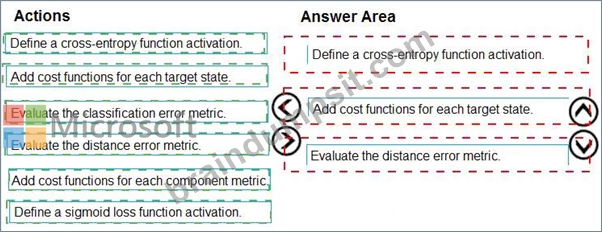
Explanation: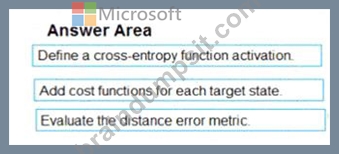
Step 1: Define a cross-entropy function activation
When using a neural network to perform classification and prediction, it is usually better to use cross-entropy error than classification error, and somewhat better to use cross-entropy error than mean squared error to evaluate the quality of the neural network.
Step 2: Add cost functions for each target state.
Step 3: Evaluated the distance error metric.
References:
https://www.analyticsvidhya.com/blog/2018/04/fundamentals-deep-learning-regularization-techniques/
NEW QUESTION # 391
You need to implement a feature engineering strategy for the crowd sentiment local models.
What should you do?
Answer: B
Explanation:
The linear discriminant analysis method works only on continuous variables, not categorical or ordinal variables.
Linear discriminant analysis is similar to analysis of variance (ANOVA) in that it works by comparing the means of the variables.
Scenario:
Data scientists must build notebooks in a local environment using automatic feature engineering and model building in machine learning pipelines.
Experiments for local crowd sentiment models must combine local penalty detection data.
All shared features for local models are continuous variables.
Topic 2, Case Study 2
Case study
Overview
You are a data scientist for Fabrikam Residences, a company specializing in quality private and commercial property in the United States. Fabrikam Residences is considering expanding into Europe and has asked you to investigate prices for private residences in major European cities. You use Azure Machine Learning Studio to measure the median value of properties. You produce a regression model to predict property prices by using the Linear Regression and Bayesian Linear Regression modules.
Datasets
There are two datasets in CSV format that contain property details for two cities, London and Paris, with the following columns: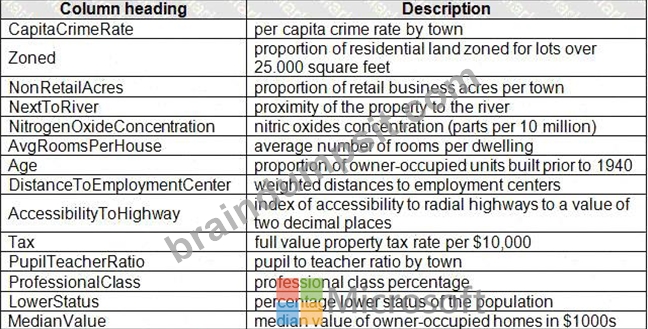
The two datasets have been added to Azure Machine Learning Studio as separate datasets and included as the starting point of the experiment.
Dataset issues
The AccessibilityToHighway column in both datasets contains missing values. The missing data must be replaced with new data so that it is modeled conditionally using the other variables in the data before filling in the missing values.
Columns in each dataset contain missing and null values. The dataset also contains many outliers. The Age column has a high proportion of outliers. You need to remove the rows that have outliers in the Age column.
The MedianValue and AvgRoomsinHouse columns both hold data in numeric format. You need to select a feature selection algorithm to analyze the relationship between the two columns in more detail.
Model fit
The model shows signs of overfitting. You need to produce a more refined regression model that reduces the overfitting.
Experiment requirements
You must set up the experiment to cross-validate the Linear Regression and Bayesian Linear Regression modules to evaluate performance.
In each case, the predictor of the dataset is the column named MedianValue. An initial investigation showed that the datasets are identical in structure apart from the MedianValue column. The smaller Paris dataset contains the MedianValue in text format, whereas the larger London dataset contains the MedianValue in numerical format. You must ensure that the datatype of the MedianValue column of the Paris dataset matches the structure of the London dataset.
You must prioritize the columns of data for predicting the outcome. You must use non-parameters statistics to measure the relationships.
You must use a feature selection algorithm to analyze the relationship between the MedianValue and AvgRoomsinHouse columns.
Model training
Given a trained model and a test dataset, you need to compute the permutation feature importance scores of feature variables. You need to set up the Permutation Feature Importance module to select the correct metric to investigate the model's accuracy and replicate the findings.
You want to configure hyperparameters in the model learning process to speed the learning phase by using hyperparameters. In addition, this configuration should cancel the lowest performing runs at each evaluation interval, thereby directing effort and resources towards models that are more likely to be successful.
You are concerned that the model might not efficiently use compute resources in hyperparameter tuning. You also are concerned that the model might prevent an increase in the overall tuning time. Therefore, you need to implement an early stopping criterion on models that provides savings without terminating promising jobs.
Testing
You must produce multiple partitions of a dataset based on sampling using the Partition and Sample module in Azure Machine Learning Studio. You must create three equal partitions for cross-validation. You must also configure the cross-validation process so that the rows in the test and training datasets are divided evenly by properties that are near each city's main river. The data that identifies that a property is near a river is held in the column named NextToRiver. You want to complete this task before the data goes through the sampling process.
When you train a Linear Regression module using a property dataset that shows data for property prices for a large city, you need to determine the best features to use in a model. You can choose standard metrics provided to measure performance before and after the feature importance process completes. You must ensure that the distribution of the features across multiple training models is consistent.
Data visualization
You need to provide the test results to the Fabrikam Residences team. You create data visualizations to aid in presenting the results.
You must produce a Receiver Operating Characteristic (ROC) curve to conduct a diagnostic test evaluation of the model. You need to select appropriate methods for producing the ROC curve in Azure Machine Learning Studio to compare the Two-Class Decision Forest and the Two-Class Decision Jungle modules with one another.
NEW QUESTION # 392
You manage are Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an auto scaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? to answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.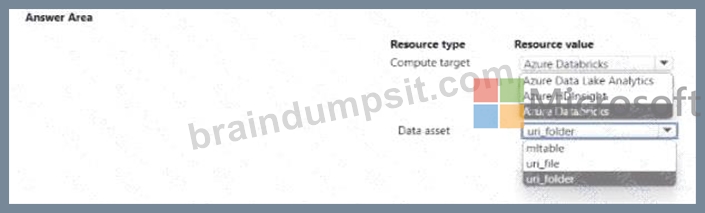
Answer:
Explanation: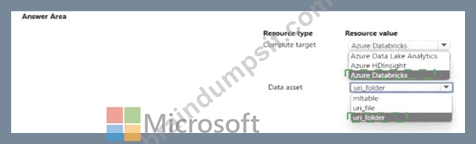
Explanation: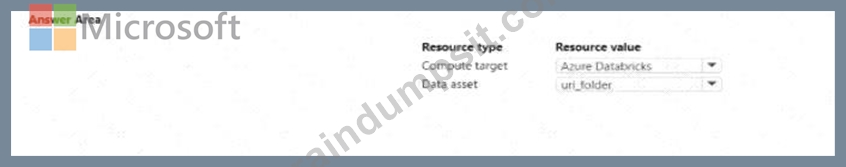
NEW QUESTION # 393
You have a binary classifier that predicts positive cases of diabetes within two separate age groups.
The classifier exhibits a high degree of disparity between the age groups.
You need to modify the output of the classifier to maximize its degree of fairness across the age groups and meet the following requirements:
* Eliminate the need to retrain the model on which the classifier is based.
* Minimize the disparity between true positive rates and false positive rates across age groups.
Which algorithm and panty constraint should you use? To answer, select the appropriate options in the answer are a. NOTE: Each correct selection is worth one point.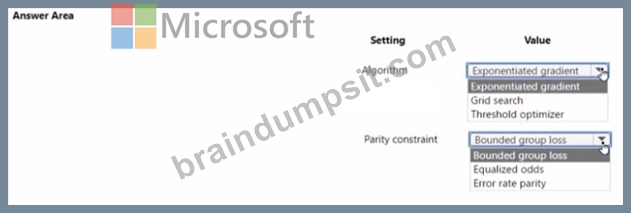
Answer:
Explanation: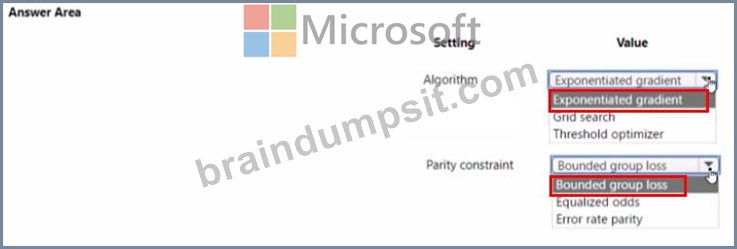
NEW QUESTION # 394
You manage an Azure Machine Learning workspace.
You train a model interactively with a Jupyter Notebook in the workspace During training, a dataset is created with accuiacy and loss metrics for each epoch.
You need to configure model tracking with MLflow to log the dataset created during the training.
How should you complete the code segment? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.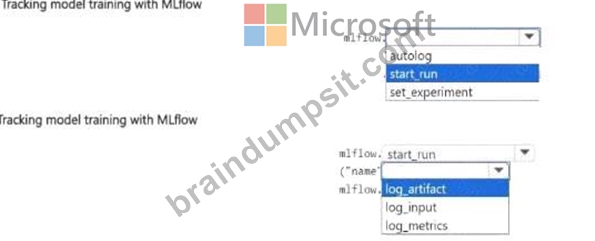
Answer:
Explanation: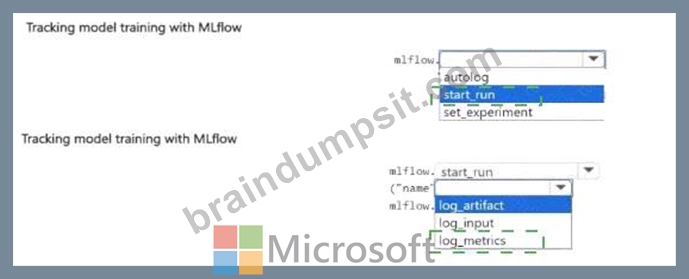
Explanation: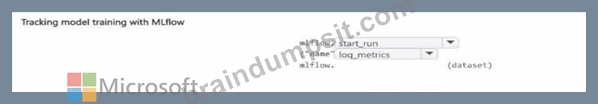
NEW QUESTION # 395
......
In order to help customers solve problems, our company always insist on putting them first and providing valued service. We deeply believe that our DP-100 question torrent will help you pass the exam and get your certification successfully in a short time. Maybe you cannot wait to understand our DP-100 Guide questions; we can promise that our products have a higher quality when compared with other study materials. At the moment I am willing to show our DP-100 guide torrents to you, and I can make a bet that you will be fond of our products if you understand it.
Valid DP-100 Test Forum: https://www.braindumpsit.com/DP-100_real-exam.html
P.S. Free & New DP-100 dumps are available on Google Drive shared by BraindumpsIT: https://drive.google.com/open?id=1KCuOzZL7yGcpwhsDjAJQnV5gowsFqHfq