P.S. Kostenlose und neue Professional-Machine-Learning-Engineer Prüfungsfragen sind auf Google Drive freigegeben von ITZert verfügbar: https://drive.google.com/open?id=1W3qTBXSsRtY1QvUUQSk24qCBX3WmcmEl
Die Ausbildungsmaterialien zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung aus ITZert sind nicht nur der Grundstein auf dem Weg zu Ihrem Erfolg, sie können Ihnen auch dabei helfen, Ihre Fähigkeiten in der IT-Branche effektiver zu entfalten. Nach mehrjährigen Bemühungen beträgt die Hit-Rate von Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung von ITZert bereits 100%. Wenn Sie die Zertifizierungsprüfung nicht bestehen, nachdem Sie unsere Fragenpool gekauft haben, werden wir alle Ihre bezahlten Summe zurückgeben.
| Thema | Einzelheiten |
|---|---|
| Thema 1 |
|
| Thema 2 |
|
| Thema 3 |
|
>> Professional-Machine-Learning-Engineer Zertifizierungsfragen <<
In der Gesellschaft, wo es so viele Talent gibt, stehen Sie unter dem Druck? Egal welche hohe Qualifikation Sie besitzen, kann die Qualifikation doch Ihre Fähigkeiten nicht bedeuten. Qualifikationen ist nur ein Sprungbrett und Stärke ist der Eckpfeiler, der Ihre Position verstärkt. Die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung ist eine beliebte IT-Zertifizierung. Viele Leute wollen das Professional-Machine-Learning-Engineer Zertifikat bekommen, so dass sie ihre Karriere machen können. Die Schulungsunterlagen zur Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung von ITZert sind ein gutes Schulungsinstrument, das Ihnen hilft, die Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung zu bestehen. Mit diesem Zertifikat können Sie international akzeptiert werden. Dann brauchen Sie sich nicht mehr zu fürchten, vom Boss gekündigt zu werden.
165. Frage
You work for a global footwear retailer and need to predict when an item will be out of stock based on historical inventory data. Customer behavior is highly dynamic since footwear demand is influenced by many different factors. You want to serve models that are trained on all available data, but track your performance on specific subsets of data before pushing to production. What is the most streamlined and reliable way to perform this validation?
Antwort: B
Begründung:
* TFX ModelValidator is a tool that allows you to compare new models against a baseline model and evaluate their performance on different metrics and data slices1. You can use this tool to validate your models before deploying them to production and ensure that they meet your expectations and requirements.
* k-fold cross-validation is a technique that splits the data into k subsets and trains the model on k-1 subsets while testing it on the remaining subset. This is repeated k times and the average performance is reported2. This technique is useful for estimating the generalization error of a model, but it does not account for the dynamic nature of customer behavior or the potential changes in data distribution over time.
* Using the last relevant week of data as a validation set is a simple way to check the model's performance on recent data, but it may not be representative of the entire data or capture the long-term trends and patterns. It also does not allow you to compare the model with a baseline or evaluate it on different data slices.
* Using the entire dataset and treating the AUC ROC as the main metric is not a good practice because it does not leave any data for validation or testing. It also assumes that the AUC ROC is the only metric that matters, which may not be true for your business problem. You may want to consider other metrics such as precision, recall, or revenue.
166. Frage
You developed a Vertex Al pipeline that trains a classification model on data stored in a large BigQuery table.
The pipeline has four steps, where each step is created by a Python function that uses the KubeFlow v2 API The components have the following names: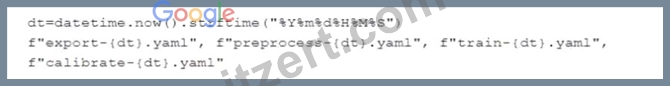
You launch your Vertex Al pipeline as the following: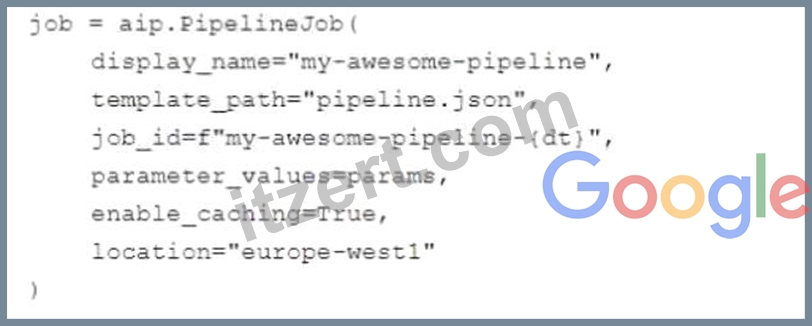
You perform many model iterations by adjusting the code and parameters of the training step. You observe high costs associated with the development, particularly the data export and preprocessing steps. You need to reduce model development costs. What should you do?




Antwort: C
Begründung:
According to the official exam guide1, one of the skills assessed in the exam is to "automate and orchestrate ML pipelines using Cloud Composer". Vertex AI Pipelines2 is a service that allows you to orchestrate your ML workflows using Kubeflow Pipelines SDK v2 or TensorFlow Extended. Vertex AI Pipelines supports execution caching, which means that if you run a pipeline and it reaches a component that has already been run with the same inputs and parameters, the component does not run again. Instead, the component uses the output from the previous run. This can save you time and resources when you are iterating on your pipeline.
Therefore, option A is the best way to reduce model development costs, as it enables execution caching for the data export and preprocessing steps, which are likely to be the same for each model iteration. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* Vertex AI Pipelines
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
167. Frage
You are developing an ML model that predicts the cost of used automobiles based on data such as location, condition, model type, color, and engine/battery efficiency. The data is updated every night. Car dealerships will use the model to determine appropriate car prices. You created a Vertex AI pipeline that reads the data splits the data into training/evaluation/test sets performs feature engineering trains the model by using the training dataset and validates the model by using the evaluation dataset. You need to configure a retraining workflow that minimizes cost.
What should you do?
Antwort: D
168. Frage
You need to develop an image classification model by using a large dataset that contains labeled images in a Cloud Storage Bucket. What should you do?
Antwort: C
Begründung:
The best option for developing an image classification model by using a large dataset that contains labeled images in a Cloud Storage bucket is to import the labeled images as a managed dataset in Vertex AI and use AutoML to train the model. This option allows you to leverage the power and simplicity of Google Cloud to create and deploy a high-quality image classification model with minimal code and configuration. Vertex AI is a unified platform for building and deploying machine learning solutions on Google Cloud. Vertex AI can create a managed dataset from a Cloud Storage bucket that contains labeled images, which can be used to train an AutoML model. AutoML is a service that can automatically build and optimize machine learning models for various tasks, such as image classification, object detection, natural language processing, and tabular data analysis. AutoML can handle the complex aspects of machine learning, such as feature engineering, model architecture, hyperparameter tuning, and model evaluation. AutoML can also evaluate, deploy, and monitor the image classification model, and provide online or batch predictions. By using Vertex AI and AutoML, users can develop an image classification model by using a large dataset with ease and efficiency.
The other options are not as good as option C, for the following reasons:
* Option A: Using Vertex AI Pipelines with the Kubeflow Pipelines SDK to create a pipeline that reads the images from Cloud Storage and trains the model would require more skills and steps than using
* Vertex AI and AutoML. Vertex AI Pipelines is a service that can orchestrate machine learning workflows using Vertex AI. Vertex AI Pipelines can run preprocessing and training steps on custom Docker images, and evaluate, deploy, and monitor the machine learning model. Kubeflow Pipelines SDK is a Python library that can create and run pipelines on Vertex AI Pipelines or on Kubeflow, an open-source platform for machine learning on Kubernetes. However, using Vertex AI Pipelines and Kubeflow Pipelines SDK would require writing code, building Docker images, defining pipeline components and steps, and managing the pipeline execution and artifacts. Moreover, Vertex AI Pipelines and Kubeflow Pipelines SDK are not specialized for image classification, and users would need to use other libraries or frameworks, such as TensorFlow or PyTorch, to build and train the image classification model.
* Option B: Using Vertex AI Pipelines with TensorFlow Extended (TFX) to create a pipeline that reads the images from Cloud Storage and trains the model would require more skills and steps than using Vertex AI and AutoML. TensorFlow Extended (TFX) is a framework that can create and run end-to-end machine learning pipelines on TensorFlow, a popular library for building and training deep learning models. TFX can preprocess the data, train and evaluate the model, validate and push the model, and serve the model for online or batch predictions. However, using Vertex AI Pipelines and TFX would require writing code, building Docker images, defining pipeline components and steps, and managing the pipeline execution and artifacts. Moreover, TFX is not optimized for image classification, and users would need to use other libraries or tools, such as TensorFlow Data Validation, TensorFlow Transform, and TensorFlow Hub, to handle the image data and the model architecture.
* Option D: Converting the image dataset to a tabular format using Dataflow, loading the data into BigQuery, and using BigQuery ML to train the model would not handle the image data properly and could result in a poor model performance. Dataflow is a service that can create scalable and reliable pipelines to process large volumes of data from various sources. Dataflow can preprocess the data by using Apache Beam, a programming model for defining and executing data processing workflows.
BigQuery is a serverless, scalable, and cost-effective data warehouse that can perform fast and interactive queries on large datasets. BigQuery ML is a service that can create and train machine learning models by using SQL queries on BigQuery. However, converting the image data to a tabular format would lose the spatial and semantic information of the images, which are essential for image classification. Moreover, BigQuery ML is not specialized for image classification, and users would need to use other tools or techniques, such as feature hashing, embedding, or one-hot encoding, to handle the categorical features.
169. Frage
You are an ML engineer at a global car manufacturer. You need to build an ML model to predict car sales in different cities around the world. Which features or feature crosses should you use to train city-specific relationships between car type and number of sales?
Antwort: D
Begründung:
A feature cross is a synthetic feature that is obtained by combining two or more existing features, usually by taking their product or concatenation. A feature cross can help to capture the nonlinear and interaction effects between the original features, and improve the predictive performance of themodel. A feature cross can be applied to different types of features, such as numeric, categorical, or geospatial features1.
For the use case of building an ML model to predict car sales in different cities around the world, the best option is to use one feature obtained as an element-wise product between binned latitude, binned longitude, and one-hot encoded car type. This option involves creating a feature cross that combines three individual features: binned latitude, binned longitude, and one-hot encoded car type. Binning is a technique that transforms a continuous numeric feature into a discrete categorical feature by dividing its range into equal intervals, or bins. One-hot encoding is a technique that transforms a categorical feature into a binary vector, where each element corresponds to a possible category, and has a value of 1 if the feature belongs to that category, and 0 otherwise. By applying binning and one-hot encoding to the latitude, longitude, and car type features, the feature cross can capture the city-specific relationships between car type and number of sales, as each combination of bins and car types can represent a different city and its preference for a certain car type.
For example, the feature cross can learn that a city with a latitude bin of [40, 50], a longitude bin of [-80, -70], and a car type of SUV has a higher number of sales than a city with a latitude bin of [-10, 0], a longitude bin of
[10, 20], and a car type of sedan. Therefore, using one feature obtained as an element-wise product between binned latitude, binned longitude, and one-hot encoded car type is the best option for this use case.
References:
* Feature Crosses | Machine Learning Crash Course
170. Frage
......
Wenn Sie Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung ablegen, ist es nötig für Sie, die richtigen Google Professional-Machine-Learning-Engineer Prüfungsunterlagen zu benutzen. Wenn Sie irgendwo die Unterlagen suchen, stoppen Sie jetzt bitte. Wenn Sie keine richtigen Unterlagen haben, probieren Sie bitte Google Professional-Machine-Learning-Engineer Dumps von ITZert. Die Hitrate der Dumps ist so hoch, dass sie Ihnen den einmaligen Erfolg garantieren. Im Verglich zu anderen Prüfungsunterlagen können diese Dumps die Prüfungsinhalte ganz richtig greifen. Damit können Sie Ihre Lerneffektivität erhöhen und sich besser auf Google Professional-Machine-Learning-Engineer Zertifizierungsprüfung vorbereiten.
Professional-Machine-Learning-Engineer Buch: https://www.itzert.com/Professional-Machine-Learning-Engineer_valid-braindumps.html
Laden Sie die neuesten ITZert Professional-Machine-Learning-Engineer PDF-Versionen von Prüfungsfragen kostenlos von Google Drive herunter: https://drive.google.com/open?id=1W3qTBXSsRtY1QvUUQSk24qCBX3WmcmEl