As long as you are willing to buy our AI-300 preparation exam, coupled with your careful preparation, we can guarantee that you will get the AI-300 certification for sure for we have been the brand in this field and welcomed by tens of thousands of our customers. Not only save you a lot of time and energy, but also can make your mood no longer anxious on the coming AI-300 Exam. So, for your future development, please don't hesitate to use our AI-300 actual exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Optimize generative AI systems and model performance | 15–20% | - Optimize model selection and configuration
|
| Topic 2: Implement generative AI quality assurance and observability | 10–15% | - Monitor generative AI systems
|
| Topic 3: Design and implement a GenAIOps infrastructure | 20–25% | - Implement infrastructure for generative AI workloads
|
| Topic 4: Implement machine learning model lifecycle and operations | 25–30% | - Orchestrate model training and experimentation
|
| Topic 5: Design and implement an MLOps infrastructure | 15–20% | - Create and manage Machine Learning workspace resources and assets
|
>> Test AI-300 Simulator Online <<
Maybe you are still worried about how to prepare for AI-300 exam. You will stop worrying when you read this entry, because you have found the most authoritative professional provider of IT exam dumps. Our exam software has helped a lot of IT workers successfully get AI-300 Exam Certification. The reason why they pass the exam easily is very simple. They all make use of our most complete and latest dumps. We will provide on-year free update service after you purchased AI-300 exam software.
NEW QUESTION # 112
A team manages an Azure Machine Learning workspace where they deploy models to online endpoints.
The team needs to introduce a new version of a model to production without disrupting existing users.
The team must validate the new version before full rollout.
You need to reduce risk during deployment.
What should you do?
Answer: C
Explanation:
According to Microsoft ' s Azure Machine Learning documentation on managed online endpoints, a single endpoint can host multiple named deployments simultaneously, and you can control what percentage of incoming traffic each deployment receives. This traffic-splitting capability is the foundation of blue/green and canary deployment strategies. When you route 10% of traffic to a new deployment and 90% to the existing one, you can monitor error rates, latency, and output quality of the new version under real production load without risking the majority of users. Microsoft explicitly recommends this pattern for safe rollouts. Option A (batch endpoint) is inappropriate for real-time serving. Option C (replacing the endpoint) is high-risk with no validation window. Option D (routing all traffic to the new deployment) provides zero protection if the new version has issues.
Microsoft Learn Reference Topic: Safe rollout of machine learning models - Traffic splitting on managed online endpoints
NEW QUESTION # 113
You manage an Azure Machine Learning workspace. You have an environment for training jobs which uses an existing Docker image.
A new version of the Docker image is available.
You need to use the latest version of the Docker image for the environment configuration by using the Azure Machine Learning SDK v2.
What should you do?
Answer: D
Explanation:
To use a new version of the Docker image for an environment using the Azure Machine Learning SDK v2, you must instantiate an Environment class object with the new image parameter and then use the ml_client.environments.create_or_update() method.
Required Steps
1. Define the updated Environment: Use the Environment entity from the azure.ai.ml.entities package. Set the image parameter to the URI of the new Docker image version.
2. Register or update the asset: Pass the environment instance into
ml_client.environments.create_or_update() to create a new version of that environment asset within your workspace.
Reference:
https://github.com/Azure/azureml-examples/blob/main/sdk/python/assets/environment/environment-with-private- packages/environment-with-private-package-docker-image.ipynb
NEW QUESTION # 114
During training, pipelines occasionally fail due to schema mismatch caused by upstream data changes. You need a robust and automated solution that prevents invalid data from reaching training steps. What is the BEST approach?
Answer: C
Explanation:
A data validation component ensures that incoming data matches the expected schema before training begins. This prevents pipeline failures and avoids training on corrupted or incomplete data. Ignoring schema mismatches can introduce silent errors, making debugging difficult and compromising model quality.
NEW QUESTION # 115
Hotspot Question
A team is preparing a generative AI application for production deployment. The application generates structured responses that must be evaluated for quality before each release.
The organization requires repeatable evaluation results that can be compared across builds and environments.
You need to configure evaluation inputs so quality metrics can be reliably calculated across test runs.
How should you prepare the evaluation inputs? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.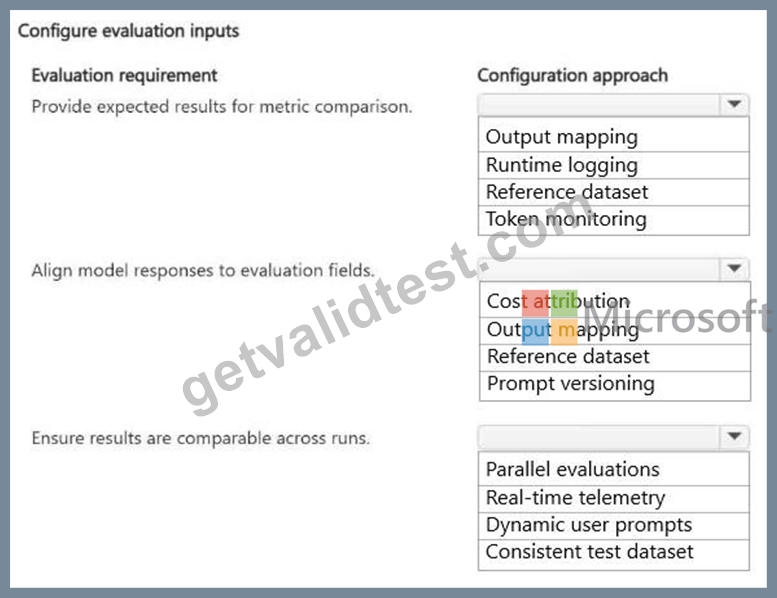
Answer:
Explanation: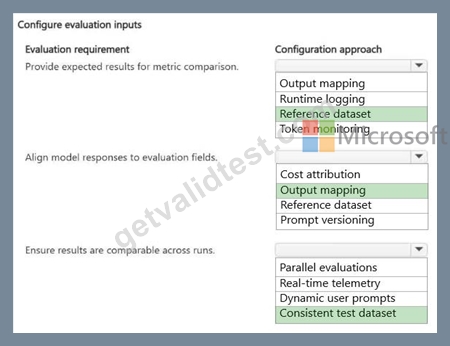
Explanation:
Box 1: Reference dataset
Provide expected results for metric comparison.
A reference dataset contains predefined input prompts matched with ground-truth "expected results" (or golden outputs). To calculate quality metrics reliably and compare them across builds and environments, the evaluation framework needs this baseline data to score the generated outputs against a consistent benchmark.
Box 2: Output mapping
Align model responses to evaluation fields.
Output mapping is the process of aligning generative model responses to specific evaluation fields. For structured outputs, your evaluation dataset needs to know exactly which part of the generated response corresponds to the ground truth or target metrics. Configuring output mapping ensures that data fields are aligned consistently across different test runs, making the evaluation repeatable and comparable across builds and environments.
Box 3: Consistent test dataset
Ensure results are comparable across runs.
A consistent test dataset is used to reliably compare evaluation metrics across different builds and environments, you must test the application using the exact same inputs each time. A fixed, high-quality test dataset ensures that changes in metrics reflect changes in the model or application logic rather than variations in the test data itself.
Reference:
https://testquality.com/llm-evaluation-metrics-testing-strategies/
https://www.freecodecamp.org/news/how-to-evaluate-and-select-the-right-llm-for-your-genai-application/
NEW QUESTION # 116
You deploy a new model version to a managed online endpoint. You must test it with 10% traffic and automatically roll back if latency or error rate increases beyond threshold. What should you configure?
Answer: C
NEW QUESTION # 117
......
If you download our study materials successfully, you can print our study materials on pages by the PDF version of our AI-300 exam torrent. We believe these special functions of the PDF version will be very useful for you to prepare for your exam. We hope that you will like the PDF version of our AI-300 question torrent. If you try to get the Operationalizing Machine Learning and Generative AI Solutions certification that you will find there are so many chances wait for you. You can get a better job; you can get more salary. But if you are trouble with the difficult of Operationalizing Machine Learning and Generative AI Solutions exam, you can consider choose our AI-300 Exam Questions to improve your knowledge to pass Operationalizing Machine Learning and Generative AI Solutions exam, which is your testimony of competence.
AI-300 Training Courses: https://www.getvalidtest.com/AI-300-exam.html