2026 Latest PracticeMaterial MLA-C01 PDF Dumps and MLA-C01 Exam Engine Free Share: https://drive.google.com/open?id=1W2k95IQx9moJCkMYKEoIKhDRNdn9fEJu
We can provide absolutely high quality guarantee for our MLA-C01 practice materials, for all of our MLA-C01 learning materials are finalized after being approved by industry experts. Without doubt, you will get what you expect to achieve, no matter your satisfied scores or according MLA-C01certification file. As long as you choose our MLA-C01 exam questions, you will get the most awarded.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer - Associate |
| Exam Number: | MLA-C01 |
| Exam Price: | 150 USD |
| Exam Duration: | 130 minutes |
| Exam Format: | Case study, Matching, Multiple choice, Multiple response, Ordering |
| Related Certifications: | AWS Certified Machine Learning - Specialty AWS Certified AI Practitioner |
| Real Exam Qty: | 65 (50 scored, 15 unscored) |
| Certificate Validity Period: | 3 years |
| Passing Score: | 720 (scaled score 100–1000) |
| Available Languages: | Korean, English, Japanese, Simplified Chinese |
| Recommended Training: | AWS Certified Machine Learning Engineer - Associate Official Exam Guide AWS Training and Certification |
| Exam Registration: | Pearson VUE Registration AWS Certification Portal |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or onsite at Pearson VUE testing centers |
| Pre Condition: | Recommended: 1+ year hands-on experience with AWS services and machine learning engineering; familiarity with Amazon SageMaker and related ML services. No mandatory prerequisite exams. |
| Official Syllabus URL: | https://docs.aws.amazon.com/aws-certification/latest/machine-learning-engineer-associate-01/machine-learning-engineer-associate-01.html |
To make this task easier for you, Amazon provides you with the most reliable and concise practice material, to pass the Amazon MLA-C01 in the first go. We make sure that a more confident and well-prepared student enters the Amazon MLA-C01. This is a convenient and manageable e-book format that contains actual Amazon MLA-C01 questions.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 49
A company is setting up a system to manage all of the datasets it stores in Amazon S3. The company would like to automate running transformation jobs on the data and maintaining a catalog of the metadata concerning the datasets. The solution should require the least amount of setup and maintenance.
Which solution will allow the company to achieve its goals?
Answer: D
Explanation:
AWS Glue is the correct answer because this option requires the least amount of setup and maintenance since it is serverless, and it does not require management of the infrastructure.
NEW QUESTION # 50
A company needs to update the model definition of an existing Amazon SageMaker Al endpoint.
Select and order the correct steps from the following list to update the model definition settings with the LEAST interruption of inferences. Select each step one time or not at all. (Select and order THREE.)
* Create a new endpoint configuration that uses the new model definition.
* Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
* Delete the endpoint that needs to be updated and recreate the endpoint with the new endpoint configuration.
* Delete the IAM role and permissions for the ExecutionRoleArn parameter.
* Update the endpoint with the new endpoint configuration.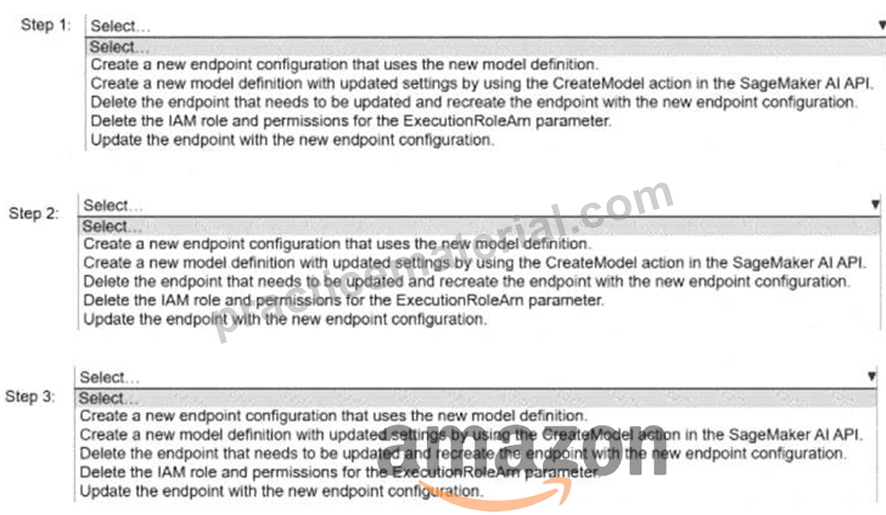
Answer:
Explanation: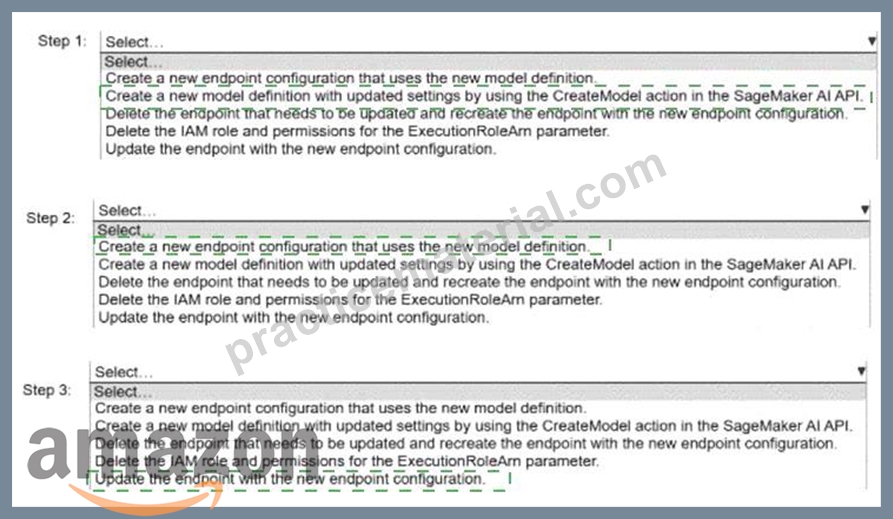
Explanation:
Step 1: Create a new model definition with updated settings by using the CreateModel action in the SageMaker AI API.
Step 2: Create a new endpoint configuration that uses the new model definition.
Step 3: Update the endpoint with the new endpoint configuration.
Do not delete and recreate the endpoint. That causes unnecessary inference interruption. SageMaker endpoint updates are designed to use a new EndpointConfig; AWS explicitly states that to update an endpoint, you must create a new endpoint configuration, then call UpdateEndpoint on the existing endpoint. During the update, SageMaker changes the endpoint to Updating and then back to InService.
NEW QUESTION # 51
A company stores training data as a .csv file in an Amazon S3 bucket. The company must encrypt the data and must control which applications have access to the encryption key.
Which solution will meet these requirements?
Answer: C
Explanation:
AWS Key Management Service (AWS KMS) is the recommended service for encryption and key access control. By creating a customer-managed KMS key, the company can define granular IAM policies that control which applications and roles can use the key.
The AWS Encryption CLI integrates directly with KMS and enables client-side encryption of files before storing them in Amazon S3. This approach ensures data is encrypted at rest and that only authorized principals can decrypt it.
SSH keys and API keys are not designed for data encryption. IAM roles alone do not create or manage encryption keys-they only grant permissions.
AWS documentation explicitly states that KMS customer-managed keys provide centralized key management, auditing, and access control.
Therefore, Option D is the correct and AWS-aligned solution.
NEW QUESTION # 52
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token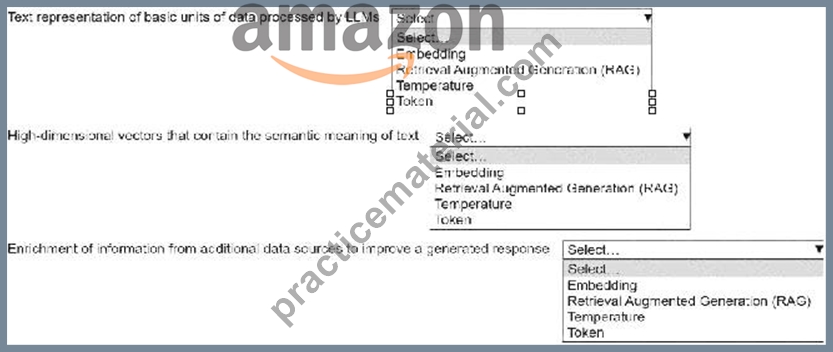
Answer:
Explanation: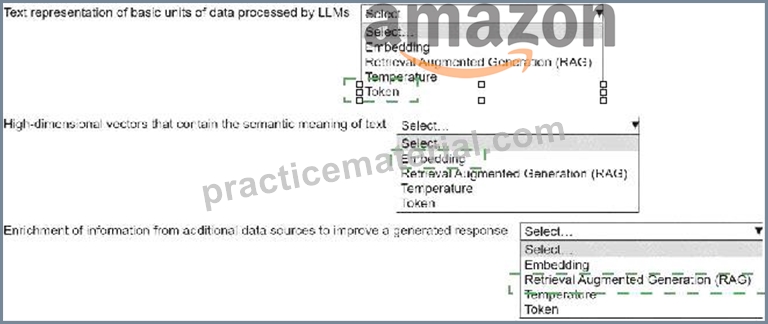
Explanation: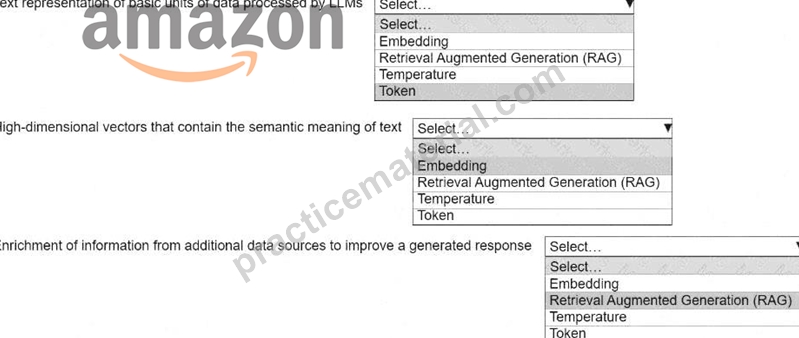
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 53
An ML engineer needs to deploy a trained model based on a genetic algorithm. Predictions can take several minutes, and requests can include up to 100 MB of data.
Which deployment solution will meet these requirements with the LEAST operational overhead?
Answer: B
Explanation:
SageMaker Asynchronous Inference is designed for long-running inference workloads and large payloads (up to 1 GB). Requests are queued, processed asynchronously, and results are written to Amazon S3.
Real-time endpoints have payload and timeout limits. EC2 and ECS require infrastructure management, increasing operational overhead.
AWS documentation explicitly recommends asynchronous inference for workloads with large inputs and long execution times.
Therefore, Option C is the correct and most efficient solution.
NEW QUESTION # 54
......
Exam MLA-C01 Review: https://www.practicematerial.com/MLA-C01-exam-materials.html
BONUS!!! Download part of PracticeMaterial MLA-C01 dumps for free: https://drive.google.com/open?id=1W2k95IQx9moJCkMYKEoIKhDRNdn9fEJu