無料でクラウドストレージから最新のJPNTest SOL-C01 PDFダンプをダウンロードする:https://drive.google.com/open?id=1bAbjxLuwxrinfqYbK1-5WCXqFw1-yXnt
我々の商品を利用して力の限りまで勉強して、合格しやすいです。万が一失敗したら、弊社は全額返金を承諾いたします。返金を選ぶ場合には、お客様は失敗したSOL-C01の成績書のスキャンを弊社に送付して、弊社は確認のあとお客様にSOL-C01問題集の費用を全額で返金いたします。お客様は自分の需要によって選ぶことができます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
多くのサイトの中で、どこかのSnowflakeのSOL-C01試験問題集は最も正確性が高いですか。無論JPNTestのSnowflakeのSOL-C01問題集が一番頼りになります。JPNTestには専門的なエリート団体があります。認証専門家や技術者及び全面的な言語天才がずっと最新のSnowflakeのSOL-C01試験を研究していて、最新のSnowflakeのSOL-C01問題集を提供します。ですから、君はうちの学習教材を安心で使って、きみの認定試験に合格することを保証します。
質問 # 72
You are loading data from a CSV file stored in an AWS S3 bucket into a Snowflake table. The CSV file uses a custom delimiter and contains a date field that needs to be explicitly formatted during the load. Which combination of 'COPY INTO* options BEST addresses these requirements? Assume an existing stage named 's3_stage'.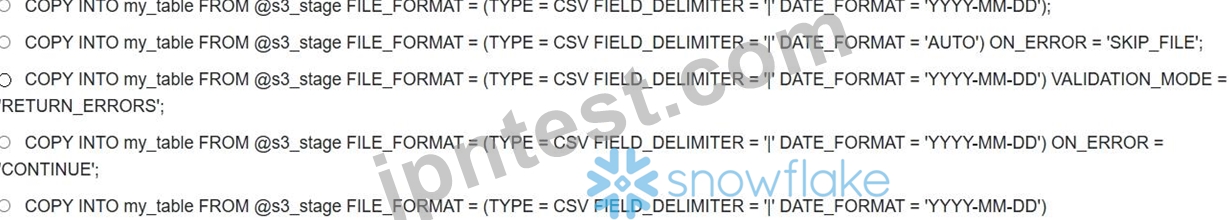
正解:D
解説:
Option A correctly specifies the custom field delimiter (FIELD DELIMITER = and the explicit date format (DATE FORMAT = 'YYYY-MM-DD") to handle the CSV loading and date transformation requirements effectively. Option B uses 'DATE_FORMAT = 'AUTO" , which might not correctly parse the date if it's not in a standard format. Options C, D and E don't contain 'ON ERROR to ensure that, in case of error the load continues
質問 # 73
A data team is designing a data pipeline that loads data from S3 into Snowflake. The raw data in S3 is compressed using gzip and stored in multiple files. They want to use a Snowflake virtual warehouse to perform the data loading. Which of the following COPY INTO command options would be MOST appropriate to optimize the data loading process?
正解:D
解説:
ERROR = CONTINUE (A) skips errors but doesn't address decompression. 'VALIDATION MODE' (B) is helpful for debugging but doesn't directly optimize the loading process. (C) can ease development but has nothing to do with compression. Specifying = (TYPE = CSV COMPRESSION = GZIP)' (D) allows Snowflake to handle gzip decompression automatically.
'MAX FILE_SIZE (E) can be useful in certain scenarios but is not related to compressed files directly. Splitting the warehouse is not a COPY INTO option, but rather a high-level architecture decision.
質問 # 74
What is a primary function of a view in Snowflake?
正解:A
解説:
A view in Snowflake represents avirtual tablewhose contents are defined by a stored SQL query. Views allow users to encapsulate transformation logic, simplify complex joins, enforce column-level security, and provide curated datasets for downstream consumers.
Views donotstore data themselves; the underlying tables store the data, and Snowflake executes the view's query each time the view is referenced. This makes views ideal for abstraction layers, semantic modeling, and separating compute costs across user groups.
Incorrect options:
* Snowflake views do not store raw data.
* Views have no role in authentication or network configuration.
Views help streamline business logic and control data access efficiently.
質問 # 75
You are using a Snowflake Notebook to perform data analysis on a large dataset. As part of your analysis, you need to create a custom Python function that calculates a complex metric based on multiple columns in a Snowflake table.
You want to apply this function to each row of the table and store the results in a new column.
Which of the following approaches is the MOST efficient and scalable way to achieve this using Snowflake and Python?
正解:B
解説:
Option C, creating a Snowflake Python IJDF and using it in a `SELECT statement within a
`CREATE TABLE AS SELECT statement, is the most efficient and scalable approach. Snowflake IJDFs allow you to execute Python code directly within the Snowflake engine, leveraging Snowflake's distributed processing capabilities. This avoids the overhead of transferring large amounts of data between Snowflake and the Python environment in the Notebook. Loading the entire table into a Pandas DataFrame (A) is not scalable for large datasets and can lead to memory issues. Using `%%osql' with `UPDATE statements (B) would be very slow due to the row-by-row updates. Iterating over rows using the Snowflake Connector (D) is also inefficient and not scalable. Option E is incorrect because it doesn't directly use Python code from the Notebook.
質問 # 76
What is the primary purpose of the COPY INTO command in Snowflake for data loading?
正解:C
解説:
COPY INTO <table> bulk-loads data from internal or external stages into Snowflake tables. It supports transformations, validation, and multiple file formats.
It does not replicate databases, manage roles, or create warehouses.
質問 # 77
......
我々のソフトを利用してSnowflakeのSOL-C01試験失敗したら全額で返金するという承諾は不自信ではなく、我々のお客様への誠な態度を表わしたいです。我々はあなたに試験に安心させます。それだけでなく、あなたに我々のアフターサービスに安心させます。
SOL-C01日本語関連対策: https://www.jpntest.com/shiken/SOL-C01-mondaishu
2026年JPNTestの最新SOL-C01 PDFダンプおよびSOL-C01試験エンジンの無料共有:https://drive.google.com/open?id=1bAbjxLuwxrinfqYbK1-5WCXqFw1-yXnt