BTW, DOWNLOAD part of Exam4PDF SPS-C01 dumps from Cloud Storage: https://drive.google.com/open?id=1X3yLCmMZ5ADYo5ODZrS_ICWcZprvtvx5
Exam4PDF has made the Snowflake Certified SnowPro Specialty - Snowpark (SPS-C01) exam dumps after consulting with professionals and getting positive feedback from customers. The team of Exam4PDF has worked hard in making this product a successful Snowflake SPS-C01 Study Material. So we guarantee that you will not face issues anymore in passing the Snowflake SPS-C01 certification test with good grades.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Performance Optimization and Best Practices | 20% | - Vectorized UDFs - Warehouse sizing for Snowpark - Query pushdown and optimization - Caching strategies - Debugging and explain plans - Minimizing data transfer |
| Topic 2: Snowpark API for Python | 30% | - Reading and writing data - User-Defined Functions (UDFs) and Stored Procedures - DataFrame creation and manipulation - Establishing connections and session management - Working with Semi-structured data |
| Topic 3: Data Transformations and DataFrame Operations | 35% | - Filtering, Aggregating, and Joining DataFrames - Complex data pipelines - Persisting transformed data - Window functions - Using built-in functions |
| Topic 4: Snowpark Concepts | 15% | - Client-side vs. Server-side execution - Stored procedures and conditional logic - Snowpark DataFrames and query plans - Snowpark Sessions and connection management - Transformations vs. Actions - Snowpark architecture and core concepts |
For candidates who are going to attend the exam, some practice is necessary, for the practice can build up the confidence. SPS-C01 exam torrent of us can help you pass the exam successfully. SPS-C01 exam braindumps are edited by professional experts, and the quality can be guaranteed. In addition, SPS-C01 exam materials cover most knowledge points for the exam, and you can master the major knowledge points for the exam, therefore your confidence for the exam will be strengthened. We provide you with free demo for you to have a try before buying SPS-C01 Exam Braindumps, so that you can know what the complete version is like.
NEW QUESTION # 121
You are developing a Snowpark application that uses a Python UDF to perform geocoding operations. This UDF relies on a third-party geocoding library and a large dataset of geographical data stored in a file named 'geodata.db'. The UDF needs to be operationalized with minimal latency. Which of the following strategies will result in the FASTEST execution of the UDF and optimal resource utilization?
Answer: B
Explanation:
Option E is the most efficient strategy. Packaging the library and data file in a ZIP, referencing it with 'imports' , and using a global variable with caching within the UDF minimizes latency by loading the data only once per worker. It also benefits from utilizing the parallel processing capabilities of Snowpark. Using Java UDF's (C) is less efficient, unless it is highly optimized since java conversion can happen and adds overhead . Relying on external geocoding services (D) introduces network latency and is not ideal for performance. While a custom Anaconda channel (B) can simplify dependency management, it does not address the issue of loading the large 'geodata.db' file efficiently. Option A addresses the dependency managment but performance is not addressed.
NEW QUESTION # 122
You have a Python dictionary 'data' representing configuration settings for your Snowpark application. You need to convert this dictionary into a Snowpark DataFrame with a single row and two columns named 'Setting' and 'Value'. The 'Setting' column should contain the keys from the dictionary, and the 'Value' column should contain the corresponding values. The DataFrame needs to be created efficiently and ensure string representation of both the setting and value. Which approach is most suitable, ensuring correctness and conciseness?
Answer: B
Explanation:
Option D is the most suitable approach. Here's why: Correctness: It correctly transforms the dictionary into a list of lists, where each inner list contains the key and its corresponding value. The 'str(vy ensures all values are converted to strings, meeting the requirement. Efficiency: It directly creates a Snowpark DataFrame without unnecessary intermediate conversions (e.g., to Pandas DataFrame). Clarity: It clearly defines the schema using a list of column names, making the code easy to understand. Option A is not correct, you need list of list for each row, the schema is not correct for dictionary structure Option B introduces Pandas dependency and incurs the overhead of converting to Pandas DataFrame and then to a Snowpark DataFrame. Option C creates a list of dictionaries, where each dictionary has the keys 'Setting' and Value'. This creates as many rows as items in the 'data' dictionary and not a single row, but each config, thus wrong. Option E is nearly correct, but the problem is 'str(v)' which ensure string type casting is missing
NEW QUESTION # 123
You need to perform a set difference operation between two DataFrames in Snowpark Python. 'dfl' contains customer IDs from a marketing campaign, and 'df2 contains customer IDs from a recent purchase event. You want to identify customers who were targeted in the campaign but did not make a recent purchase. Both DataFrames have a column named 'customer id'. Which of the following approaches provides the most efficient way to accomplish this task in Snowpark?





Answer: B
Explanation:
Option C, using a 'left_anti' join, is the most efficient way to perform a set difference operation between two DataFrames in Snowpark. A join returns only the rows from the left DataFrame Cdfl s) where the join condition is not met in the right DataFrame Cdf2). This leverages Snowflake's query optimizer for optimal performance. Option A, 'subtract(df2)' , is equivalent to 'exceptAll(df2)' (Option B) and removes duplicate rows. While functionally correct, join is often more performant, especially for larger datasets. Option D is highly inefficient as it collects the 'customer_id' from 'df2 to the driver, it should be avoided. Option E calculates intersection, not difference.
NEW QUESTION # 124
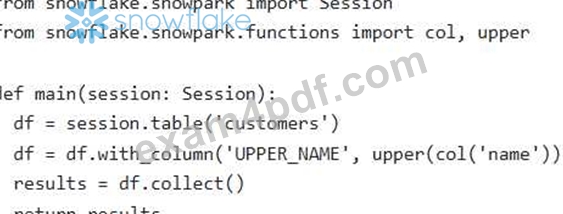
Consider the following Snowpark Python code snippet:
Answer: A,D
Explanation:
Options A and D are correct. Snowpark leverages Snowflake's compute resources by translating DataFrame operations (like 'with_column' and 'upper') into SQL that is executed within the data warehouse. Only the 'collect()' action materializes the results and brings them back to the client. B is wrong because the upper function executes on the server side and is translated into SQL. C is wrong because collect happens at the end after 'upper' is calculated in Snowflake. E is incorrect as the core Snowpark functionality does not require a full Anaconda environment setup - dependencies can be configured otherwise.
NEW QUESTION # 125
You are working with a Snowpark DataFrame containing customer data'. One of the columns, 'phone number', contains phone numbers in various formats (e.g., '123-456-7890', '(123) 456-7890', '1234567890'). You need to standardize all phone numbers to the format '+1-123-456-7890' using Snowpark for Python. You also want to handle cases where the phone number is NULL gracefully, replacing them with '+1-000-000-0000'. Which of the following Snowpark code snippets is the most efficient and correct way to achieve this?

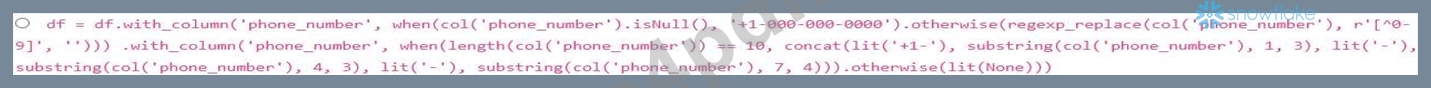



Answer: B
Explanation:
Option C is the most efficient because it uses built-in Snowpark functions (when, regexp_replace, substring, concat, length, and lit) to perform the transformation directly on the server-side. It first handles NULL values. It then removes non-numeric characters. Finally, it checks the length of the remaining digits before formatting, ensuring only valid 10-digit numbers are transformed, setting others to NULL. Options A, D, and E do not handle the case where after removing non-numeric characters, the length of phone number is not 10. Option B uses a UDF, which is generally less efficient than using built-in functions as it involves serialization/deserialization overhead .
NEW QUESTION # 126
......
Maybe this is the first time you choose our SPS-C01 practice materials, so it is understandable you may wander more useful information of our SPS-C01 exam dumps. Those free demos give you simple demonstration of our SPS-C01 study guide. It is unquestionable necessary for you to have an initial look of them before buying any. They are some brief introductions and basic information but also impressive. Just have a try and you will be interested in them!
Trustworthy SPS-C01 Exam Content: https://www.exam4pdf.com/SPS-C01-dumps-torrent.html
DOWNLOAD the newest Exam4PDF SPS-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1X3yLCmMZ5ADYo5ODZrS_ICWcZprvtvx5