To attain all these you just need to enroll in the Databricks Databricks-Certified-Professional-Data-Engineer certification exam and put in all your efforts and prepare well to crack the Databricks Databricks-Certified-Professional-Data-Engineer exam easily. For the perfect and instant Databricks Databricks-Certified-Professional-Data-Engineer preparation, you can get help from Databricks Databricks-Certified-Professional-Data-Engineer Questions. The ValidBraindumps Databricks-Certified-Professional-Data-Engineer exam questions are real and will entirely assist you in Databricks-Certified-Professional-Data-Engineer exam preparation and you can easily pass the final Databricks Databricks-Certified-Professional-Data-Engineer certification exam.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Delta Lake | 20-25% | - Delta Lake operations
|
| Topic 2: Data Ingestion | 15-20% | - Streaming ingestion
|
| Topic 3: Data Warehouse and Lakehouse Architecture | 15-20% | - Lakehouse architecture principles
|
| Topic 4: Data Processing with Spark | 25-30% | - Python and SQL for data engineering
|
| Topic 5: Pipeline Development and Orchestration | 10-15% | - Databricks workflows
|
>> Valid Databricks-Certified-Professional-Data-Engineer Test Papers <<
When you are struggling with those troublesome reference books; when you feel helpless to be productive during the process of preparing different exams; when you have difficulty in making full use of your sporadic time and avoiding procrastination. No other Databricks-Certified-Professional-Data-Engineer study materials or study dumps can bring you the knowledge and preparation that you will get from the Databricks-Certified-Professional-Data-Engineer Study Materials available only from ValidBraindumps. Not only will you be able to pass any Databricks-Certified-Professional-Data-Engineer test, but will gets higher score, if you choose our Databricks-Certified-Professional-Data-Engineer study materials.
NEW QUESTION # 151
An upstream system has been configured to pass the date for a given batch of data to the Databricks Jobs API as a parameter. The notebook to be scheduled will use this parameter to load data with the following code:
df = spark.read.format("parquet").load(f"/mnt/source/(date)")
Which code block should be used to create the date Python variable used in the above code block?
Answer: A
Explanation:
The code block that should be used to create the date Python variable used in the above code block is:
dbutils.widgets.text("date", "null") date = dbutils.widgets.get("date") This code block uses the dbutils.widgets API to create and get a text widget named "date" that can accept a string value as a parameter1. The default value of the widget is "null", which means that if no parameter is passed, the date variable will be "null". However, if a parameter is passed through the Databricks Jobs API, the date variable will be assigned the value of the parameter. For example, if the parameter is "2021-11-01", the date variable will be "2021-11-01". This way, the notebook can use the date variable to load data from the specified path.
The other options are not correct, because:
* Option A is incorrect because spark.conf.get("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The spark.conf API is used to get or set Spark configuration properties, not notebook parameters2.
* Option B is incorrect because input() is not a valid way to get a parameter passed through the Databricks Jobs API. The input() function is used to get user input from the standard input stream, not from the API request3.
* Option C is incorrect because sys.argv1 is not a valid way to get a parameter passed through the Databricks Jobs API. The sys.argv list is used to get the command-line arguments passed to a Python script, not to a notebook4.
* Option D is incorrect because dbutils.notebooks.getParam("date") is not a valid way to get a parameter passed through the Databricks Jobs API. The dbutils.notebooks API is used to get or set notebook parameters when running a notebook as a job or as a subnotebook, not when passing parameters through the API5.
References: Widgets, Spark Configuration, input(), sys.argv, Notebooks
NEW QUESTION # 152
In order to use Unity catalog features, which of the following steps needs to be taken on man-aged/external tables in the Databricks workspace?
Answer: C
Explanation:
Explanation
Upgrade tables and views to Unity Catalog - Azure Databricks | Microsoft Docs Managed table: Upgrade a managed to Unity Catalog External table: Upgrade an external table to Unity Catalog
NEW QUESTION # 153
Which statement regarding spark configuration on the Databricks platform is true?
Answer: C
Explanation:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
:
Databricks documentation on configuring clusters: https://docs.databricks.com/clusters/configure.html
NEW QUESTION # 154
A data engineer is using Lakeflow Declarative Pipelines Expectations feature to track the data quality of their incoming sensor data. Periodically, sensors send bad readings that are out of range, and they are currently flagging those rows with a warning and writing them to the silver table along with the good data. They've been given a new requirement - the bad rows need to be quarantined in a separate quarantine table and no longer included in the silver table.
This is the existing code for their silver table:
@dlt.table
@dlt.expect( " valid_sensor_reading " , " reading < 120 " )
def silver_sensor_readings():
return spark.readStream.table( " bronze_sensor_readings " )
What code will satisfy the requirements?
Answer: B
Explanation:
Lakeflow Declarative Pipelines (DLT) supports data quality enforcement using @dlt.expect, @dlt.
expect_or_drop, and @dlt.expect_all.
* @dlt.expect applies a rule and records whether rows pass or fail the condition but does not drop failing rows . Instead, failing rows can be written to a quarantine table.
* @dlt.expect_or_drop enforces that only rows passing the condition flow downstream, dropping bad records automatically.
In this case, the requirement is:
* Good rows (reading < 120) go to the silver table .
* Bad rows (reading > = 120) go to a quarantine table .
* Bad rows should not be included in silver.
The correct implementation is Option A , where:
* The silver table uses @dlt.expect to validate reading < 120. These rows flow normally.
* The quarantine table applies an expectation for reading > = 120, ensuring bad records are captured separately.
Other options are incorrect:
* Option B/D: These either use expect_or_drop incorrectly or apply wrong conditions, leading to dropped rows without quarantining properly.
* Option C: Uses expect_or_drop for both tables, which would discard bad rows instead of persisting them into a quarantine table.
Thus, Option A meets the business requirement to split good and bad data streams while ensuring both are captured for auditing and processing.
Reference: Databricks Documentation - Delta Live Tables (DLT) Expectations: @dlt.expect, @dlt.
expect_or_drop, and Quarantine Tables.
NEW QUESTION # 155
The data science team has created and logged a production model using MLflow. The following code correctly imports and applies the production model to output the predictions as a new DataFrame namedpredswith the schema "customer_id LONG, predictions DOUBLE, date DATE".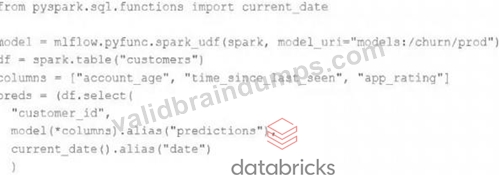
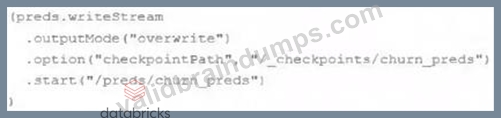
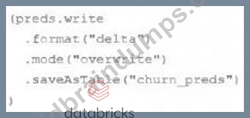
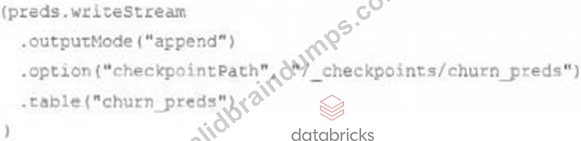
The data science team would like predictions saved to a Delta Lake table with the ability to compare all predictions across time. Churn predictions will be made at most once per day.
Which code block accomplishes this task while minimizing potential compute costs?
Answer: C
Explanation:
Explanation
This is the correct answer because it will save the predictions to a Delta Lake table with the ability to compare all predictions across time. The code uses the mergeInto method to perform an upsert operation, which means it will insert new records or update existing records based on the customer_id and date columns. This way, the table will always contain the latest predictions for each customer and date, and also keep the history of previous predictions. The code also uses a new job cluster to run the job, which will minimize the compute costs as it will be created and terminated for each run. Verified References: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "Upsert into a table using merge" section.
NEW QUESTION # 156
......
The Databricks-Certified-Professional-Data-Engineer Exam software’s user-friendly interface is made to uproot potential problems. Once you will try the demo of Databricks-Certified-Professional-Data-Engineer exam questions, you will be well- acquainted with the software and its related features. Also Databricks-Certified-Professional-Data-Engineer exam comes with various self-assessment features like timed exam, randomization questions, and multiple questions types, test history and score etc. Which means it enables you to customize the question type and you may practice random questions in order to enhance your skills and expertise. You may keep attempting the same questions many a time also.
Databricks-Certified-Professional-Data-Engineer Dumps Questions: https://www.validbraindumps.com/Databricks-Certified-Professional-Data-Engineer-exam-prep.html