We declare that we can ensure you 100% pass, because we have the real exam questions for the Certified-Data-Engineer-Professional actual test. All the questions of Databricks Certified-Data-Engineer-Professional test pdf are taken from current pool of actual test, then after refined and checked, compiled into the complete dumps. Furthermore, the answers are correct and verified by our IT experts with decades of hands-on experience. So the high quality and accuracy of Certified-Data-Engineer-Professional Cert Guide are without any doubt. With our 100 % pass rate history & money back guarantee, you can rest assured to choose our Certified-Data-Engineer-Professional vce files.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Sharing and Federation | ~8% | - Configure Delta Sharing and Lakehouse Federation |
| Topic 2: Security and Governance | ~10% | - Implement row-level security, column masking, and compliance - Manage Unity Catalog permissions and ACLs |
| Topic 3: Cost and Performance Optimization | ~13% | - Optimize queries, clusters, and storage - Leverage system tables and observability tools |
| Topic 4: Developing Code for Data Processing using Python and SQL | ~22% | - Manage dependencies, libraries, and UDFs - Implement scalable Python/SQL code and project structures - Build pipelines with Lakeflow Spark Declarative Pipelines and Auto Loader |
| Topic 5: Data Modeling | ~10% | - Design scalable Delta Lake schemas and clustering - Apply dimensional modeling techniques |
| Topic 6: Monitoring, Logging, and Troubleshooting | ~8% | - Diagnose common pipeline and job failures - Use Spark UI, Query Profiler, and system tables |
| Topic 7: Data Transformation, Cleansing, and Quality | ~12% | - Enforce data quality and quarantine bad data - Apply advanced Spark transformations |
| Topic 8: CI/CD, Testing, and Deployment | ~6% | - Implement testing and deployment pipelines - Deploy with Declarative Automation Bundles, CLI, and REST API |
| Topic 9: Streaming Workloads and Change Data Capture | ~11% | - Apply AUTO CDC APIs and exactly-once semantics - Implement reliable streaming pipelines |
>> Valid Certified-Data-Engineer-Professional Torrent <<
Our Certified-Data-Engineer-Professional free demo provides you with the free renewal in one year so that you can keep track of the latest points happening in the world. As the questions of our Certified-Data-Engineer-Professional exam dumps are involved with heated issues and customers who prepare for the Certified-Data-Engineer-Professional Exams must haven’t enough time to keep trace of Certified-Data-Engineer-Professional exams all day long. In this way, there is no need for you to worry about that something important have been left behind. Therefore, you will have more confidence in passing the exam.
NEW QUESTION # 40
The data engineering team is migrating an enterprise system with thousands of tables and views into the Lakehouse. They plan to implement the target architecture using a series of bronze, silver, and gold tables. Bronze tables will almost exclusively be used by production data engineering workloads, while silver tables will be used to support both data engineering and machine learning workloads. Gold tables will largely serve business intelligence and reporting purposes. While personal identifying information (PII) exists in all tiers of data, pseudonymization and anonymization rules are in place for all data at the silver and gold levels.
The organization is interested in reducing security concerns while maximizing the ability to collaborate across diverse teams.
Which statement exemplifies best practices for implementing this system?
Answer: B
Explanation:
This is the correct answer because it exemplifies best practices for implementing this system. By isolating tables in separate databases based on data quality tiers, such as bronze, silver, and gold, the data engineering team can achieve several benefits. First, they can easily manage permissions for different users and groups through database ACLs, which allow granting or revoking access to databases, tables, or views. Second, they can physically separate the default storage locations for managed tables in each database, which can improve performance and reduce costs. Third, they can provide a clear and consistent naming convention for the tables in each database, which can improve discoverability and usability.
NEW QUESTION # 41
A Databricks job has been configured with 3 tasks, each of which is a Databricks notebook. Task A does not depend on other tasks. Tasks B and C run in parallel, with each having a serial dependency on Task A.
If task A fails during a scheduled run, which statement describes the results of this run?
Answer: D
Explanation:
When a Databricks job runs multiple tasks with dependencies, the tasks are executed in a dependency graph. If a task fails, the downstream tasks that depend on it are skipped and marked as Upstream failed. However, the failed task may have already committed some changes to the Lakehouse before the failure occurred, and those changes are not rolled back automatically. Therefore, the job run may result in a partial update of the Lakehouse. To avoid this, you can use the transactional writes feature of Delta Lake to ensure that the changes are only committed when the entire job run succeeds. Alternatively, you can use the Run if condition to configure tasks to run even when some or all of their dependencies have failed, allowing your job to recover from failures and continue running.
NEW QUESTION # 42
To identify the top users consuming compute resources, a data engineering team needs to monitor usage within their Databricks workspace for better resource utilization and cost control.
The team decided to use Databricks system tables, available under the System catalog in Unity Catalog, to gain detailed visibility into workspace activity. Which SQL query should the team run from the System catalog to achieve this?
Answer: B
Explanation:
The system.billing.usage table in the Unity Catalog System schema provides detailed usage metrics for each workload in the workspace. The field identity_metadata.run_as identifies the user or service principal under which the job or query executed. Summing usage_quantity provides total DBU (Databricks Unit) consumption per user. According to Databricks documentation, this table is the authoritative source for monitoring workspace cost drivers, showing compute SKU, user, and DBU consumption over time. Grouping by identity_metadata.run_as and summing usage_quantity produces the correct aggregation to determine top users. Other queries use non- existent or incorrect fields (created_by, run_name, or multiplied usage quantities), which do not reflect actual billing metrics.
NEW QUESTION # 43
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table: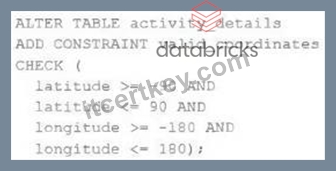
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
Answer: D
Explanation:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
NEW QUESTION # 44
Incorporating unit tests into a PySpark application requires upfront attention to the design of your jobs, or a potentially significant refactoring of existing code.
Which statement describes a main benefit that offset this additional effort?
Answer: C
Explanation:
Unit tests are small, isolated tests that are used to check specific parts of the code, such as functions or classes.
NEW QUESTION # 45
......
Are you still feeling uncomfortable about giving up a lot of time to entertain, work or accompany your family and friends in preparation for the exam? Using Certified-Data-Engineer-Professional quiz torrent, you can spend less time and effort reviewing and preparing, which will help you save a lot of time and energy. Whether you are a worker or student, you will save much time to do something whatever you want. It only needs 5-10 minutes after you pay for our Certified-Data-Engineer-Professional learn torrent that you can learn it to prepare for your exam. Actually, if you can guarantee that your effective learning time with Certified-Data-Engineer-Professional test preps are up to 20-30 hours, you can pass the exam.
New Certified-Data-Engineer-Professional Braindumps Pdf: https://www.itcertkey.com/Certified-Data-Engineer-Professional_braindumps.html