P.S. JapancertがGoogle Driveで共有している無料かつ新しいDY0-001ダンプ:https://drive.google.com/open?id=1NMi5SyrlhYqjVDDJ-SaHmthZuf4n4b2n
「今の生活と仕事は我慢できない。他の仕事をやってみたい。」このような考えがありますか。しかし、どのようにより良い仕事を行うことができますか。ITが好きですか。ITを通して自分の実力を証明したいのですか。IT業界に従事したいなら、IT認定試験を受験して認証資格を取得することは必要になります。あなたが今しなければならないのは、広く認識された価値があるIT認定試験を受けることです。そうすれば、新たなキャリアへの扉を開くことができます。CompTIAのDY0-001認定試験というと、きっとわかっているでしょう。この資格を取得したら、新しい仕事を探す時、あなたが大きなヘルプを得ることができます。何ですか。自信を持っていないからDY0-001試験を受けるのは無理ですか。それは問題ではないですよ。あなたはJapancertのDY0-001問題集を利用することができますから。
| Certification Vendor: | CompTIA |
|---|---|
| Exam Name: | CompTIA DataAI Certification Exam |
| Exam Number: | DY0-001 |
| Exam Price: | $544 USD |
| Certificate Validity Period: | 3 years |
| Exam Format: | Performance-Based Questions (PBQs), Multiple Choice |
| Available Languages: | Japanese, English |
| Exam Duration: | 165 minutes |
| Related Certifications: | CompTIA AI Essentials CompTIA Data+ |
| Passing Score: | Pass/Fail (no numerical score) |
| Real Exam Qty: | Up to 90 |
| Recommended Training: | CompTIA Official Study Guide CompTIA CertMaster Learn for DataAI |
| Exam Registration: | Pearson VUE Scheduling CompTIA Official Registration |
| Sample Questions: | CompTIA DY0-001 Sample Questions |
| Exam Way: | Online proctored or in-person at Pearson VUE test centers |
| Pre Condition: | No mandatory prerequisites; recommended 5+ years of experience in data science, analytics, or related fields |
| Official Syllabus URL: | https://www.comptia.org/certifications/dataai |
弊社のCompTIAのDY0-001試験問題集を買うかどうかまだ決めていないなら、弊社のデモをやってみよう。使用してから、あなたは弊社の商品でCompTIAのDY0-001試験に合格できるということを信じています。我々Japancertの専門家たちのCompTIAのDY0-001試験問題集への更新と改善はあなたに試験の準備期間から成功させます。
| トピック | 出題範囲 |
|---|---|
| トピック 1 |
|
| トピック 2 |
|
| トピック 3 |
|
| トピック 4 |
|
| トピック 5 |
|
質問 # 43
A data analyst is examining the correlation matrix of a new data set to identify issues that could adversely impact model performance. Which of the following is the analyst most likely checking for?
正解:A
解説:
# Multicollinearity occurs when independent variables are highly correlated with each other. This can distort coefficient estimates and reduce model interpretability. A correlation matrix is the primary tool used to detect it.
Why the other options are incorrect:
* A & C: Under/oversampling relate to class imbalance, not variable correlation.
* D: Overfitting is related to model complexity, not directly observable via a correlation matrix.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Correlation matrices are used to detect multicollinearity - high correlations among predictors that may destabilize models."
質問 # 44
Which of the following is the naive assumption in Bayes' rule?
正解:A
解説:
Naive Bayes assumes that all predictor variables are conditionally independent of each other given the class label, dramatically simplifying the joint probability calculation in Bayes' rule.
質問 # 45
A data scientist is developing a model to predict the outcome of a vote for a national mascot. The choice is between tigers and lions. The full data set represents feedback from individuals representing 17 professions and 12 different locations. The following rank aggregation represents 80% of the data set: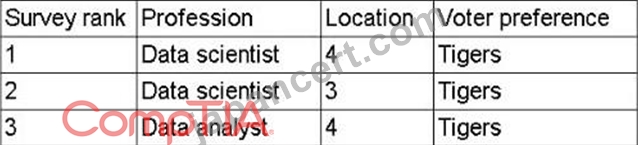
(Screenshot shows survey rankings for just two professions and a few locations, all voting for "Tigers") Which of the following is the most likely concern about the model's ability to predict the outcome of the vote?
正解:A
解説:
# Extrapolated data refers to making predictions about data points that fall outside the observed range or distribution. Since the sample data (80%) is heavily skewed toward a small subset of professions and locations, predicting results for the remaining, unrepresented professions and regions involves extrapolation.
Why the other options are incorrect:
* A: Interpolation occurs within the bounds of observed data - not the issue here.
* C: In-sample data refers to training data, which is overrepresented in this case.
* D: Out-of-sample data is a concern in generalization but extrapolation is more specific here.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.2:"Extrapolation introduces risk when models are used outside the range of data they were trained on, especially if certain subgroups are underrepresented."
-
質問 # 46
A data analyst is analyzing data and would like to build conceptual associations. Which of the following is the best way to accomplish this task?
正解:D
解説:
# n-grams (bigrams, trigrams, etc.) are sequences of N words used to analyze co-occurrences and build conceptual or contextual associations between terms in natural language processing (NLP). This helps in understanding the semantic structure of language and is ideal for finding relationships between words.
Why the other options are incorrect:
* B: NER (Named Entity Recognition) identifies entities like names or dates; it doesn't focus on conceptual associations.
* C: TF-IDF scores term importance relative to documents, not associations.
* D: POS (Part of Speech) tagging identifies word roles (noun, verb, etc.), not direct associations.
Official References:
* CompTIA DataX (DY0-001) Official Study Guide - Section 6.3:"n-gram analysis is useful for discovering common patterns and associations in unstructured text data."
* Natural Language Processing with Python (NLTK Book), Chapter 3:"N-grams help capture collocations and associations between words that often co-occur, essential for understanding context."
-
質問 # 47
Given a logistics problem with multiple constraints (fuel, capacity, speed), which of the following is the most likely optimization technique a data scientist would apply?
正解:C
解説:
# This is a classic constrained optimization problem: the boats have fuel, volume, and speed constraints. The goal is to maximize box transport within the fixed limits (e.g., fuel). Constrained optimization methods are explicitly designed to handle such problems.
Why other options are incorrect:
* B: Unconstrained methods do not account for fuel or capacity limits - inappropriate.
* C: Most real-world constrained problems require iterative approaches for convergence.
* D: Iterative may be part of solving, but it's not a type of optimization - constrained is the category.
Official References:
* CompTIA DataX (DY0-001) Study Guide - Section 3.4:"Constrained optimization is used when variables must meet certain limitations or bounds."
-
質問 # 48
......
DY0-001シュミレーション問題集: https://www.japancert.com/DY0-001.html
BONUS!!! Japancert DY0-001ダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1NMi5SyrlhYqjVDDJ-SaHmthZuf4n4b2n