CCAR-Pクイズトレントブースト3バージョンには、PDFバージョン、PCバージョン、アプリオンラインバージョンが含まれます。バージョンが異なると、機能や使用方法が異なります。たとえば、PDFバージョンは、CCAR-P試験トレントをダウンロードして印刷するのに便利で、学習を閲覧するのに簡単で適しています。また、CCAR-PクイズトレントのPCバージョンは、実際の試験のシナリオを刺激することができ、Windowsオペレーティングシステムで停止します。Anthropic独自のClaude Certified Architect - Professional試験刺激テストのスコアと、CCAR-P試験トレントをマスターしたかどうかをいつでもテストできます。
| Section | Objectives |
|---|---|
| Topic 1: Solution Design | - Claude platform and solution architecture - Model, architecture, context, and deployment strategy selection |
| Topic 2: Stakeholder Engagement and Solution Lifecycle | - Stakeholder discovery and architectural trade-off communication - Solution lifecycle, handoff, adoption, and operational enablement |
| Topic 3: Governance, Safety, and Risk | - Security, compliance, risk management, and governance - Safety controls and fail-closed system design |
| Topic 4: Evaluation and Optimization | - Evaluation design and acceptance criteria - Model and architecture optimization |
| Topic 5: Enterprise Integration and Production | - Enterprise integration architecture and production readiness - Cost, latency, reliability, and operational design |
最新の状態に保つだけによって最前線に滞在するのは我々CertJukenのアイデアです。だから我々は常に更新を定期的にAnthropicのCCAR-P試験を確認しています。更新されたら、当社製品を使用しているお客様を通知して彼らに最新の情報を理解させます。すべての更新サービスは弊社のAnthropicのCCAR-Pソフトを購入した後の一年間で無料です。
質問 # 95
An architect is reviewing a Claude-based candidate-screening tool prior to deployment. A stakeholder asserts that because the model was not trained on company data, no bias evaluation is necessary.
Which two responses most accurately challenge this assertion? (Select two.)
正解:A、E
解説:
The absence of company-specific training does not establish unbiased behavior. A foundation model may reflect demographic associations or unequal treatment patterns originating from pretraining data, model behavior, prompt framing, retrieval content, or the surrounding decision workflow. Because candidate screening can materially affect employment opportunities, the complete system must be evaluated across relevant protected groups before deployment. Appropriate measures include selection-rate differences, false- positive and false-negative rates, calibration, intersectional slices, and human override patterns. Disclosure that AI is used does not replace empirical fairness testing. Protected-class labels need not have been explicit in training data for proxy variables or inferred attributes to produce disparities. Provider policies similarly do not validate a customer's specific implementation. Anthropic system cards document discriminatory-bias evaluations, reinforcing the need for application-level testing. Claude model system card
質問 # 96
You are reviewing a peer's end-to-end design for a Claude-based platform expected to scale to thousands of concurrent users.
For each statement, indicate Yes if it reflects sound architectural practice. Otherwise, select No.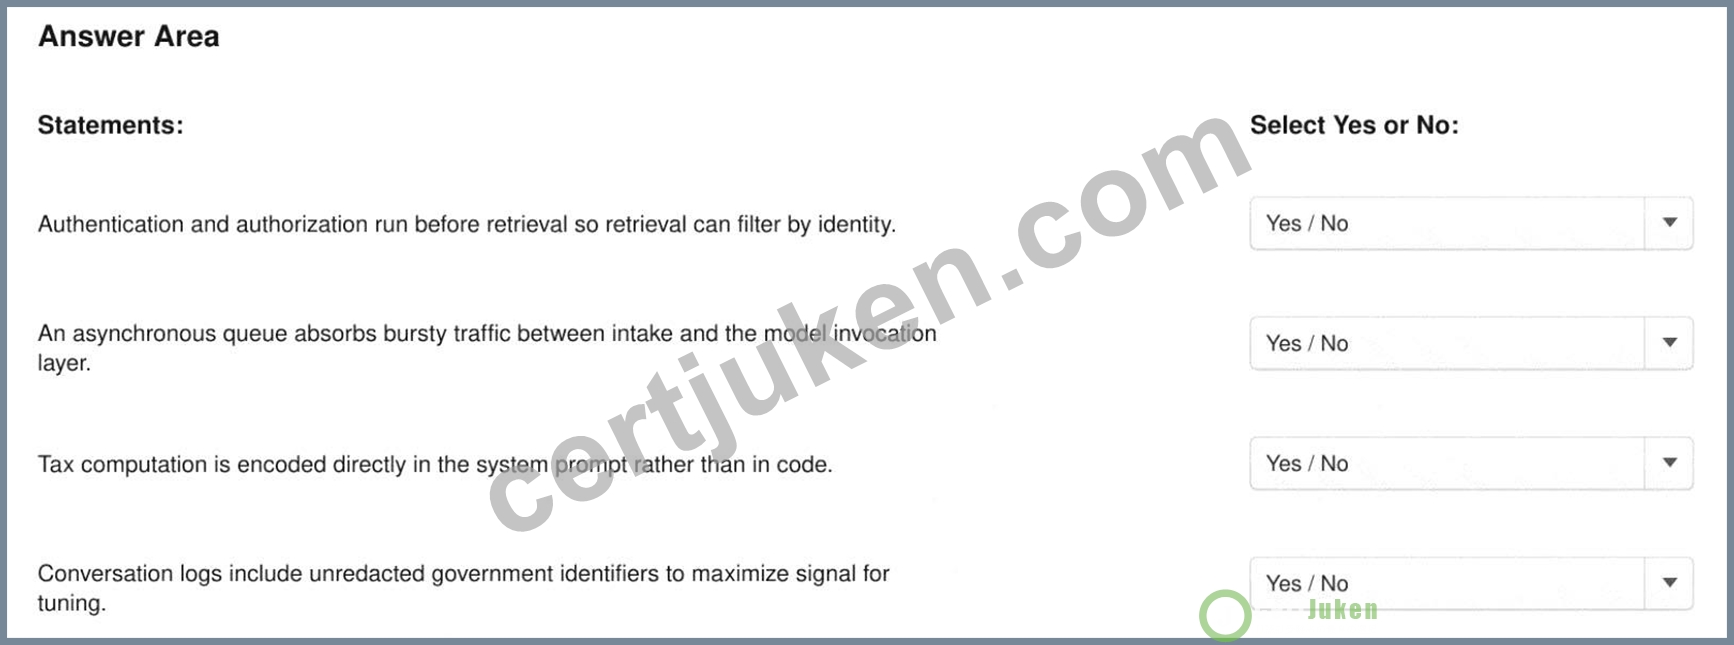
正解:
解説: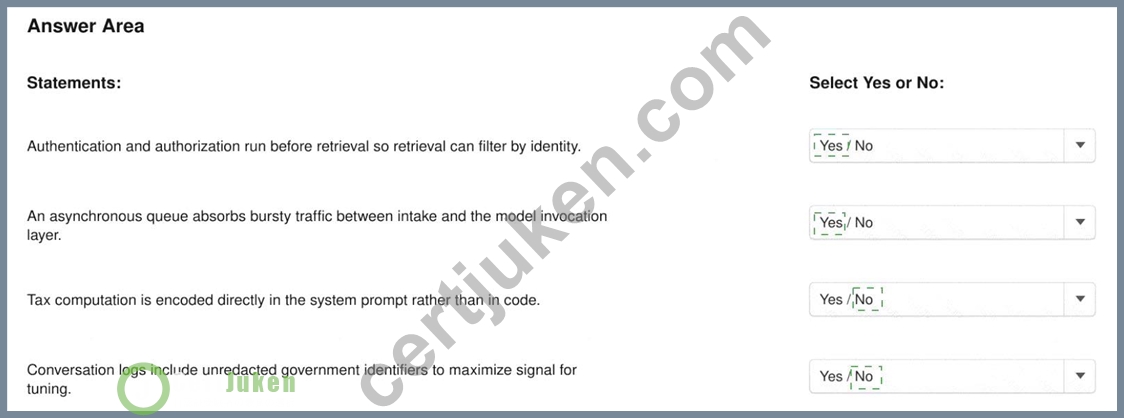
Explanation:
* Authentication and authorization run before retrieval so retrieval can filter by identity - Yes
* An asynchronous queue absorbs bursty traffic between intake and the model-invocation layer - Yes
* Tax computation is encoded directly in the system prompt rather than in code - No
* Conversation logs include unredacted government identifiers to maximize tuning signal - No Authentication and authorization must precede retrieval so unauthorized information never enters model context. An asynchronous queue is appropriate for burst absorption, backpressure, controlled concurrency, and retry management at scale. Deterministic tax computation should be implemented in validated code or a controlled calculation tool, not delegated to probabilistic prompt interpretation. Including unredacted government identifiers in conversation logs violates data-minimization principles and creates unnecessary privacy, security, and regulatory exposure. Sensitive fields should be removed, tokenized, or redacted before logging or model use unless specifically required and authorized. The resulting design separates deterministic computation, access control, scalable orchestration, and language reasoning into appropriate architectural layers.
質問 # 97
You are classifying chunking strategies by the corpus type each is best suited to.
For each chunking strategy, select the appropriate corpus type: "Long Structured Documents,"
"Heterogeneous Short Records," or "Code or Hierarchical Specifications."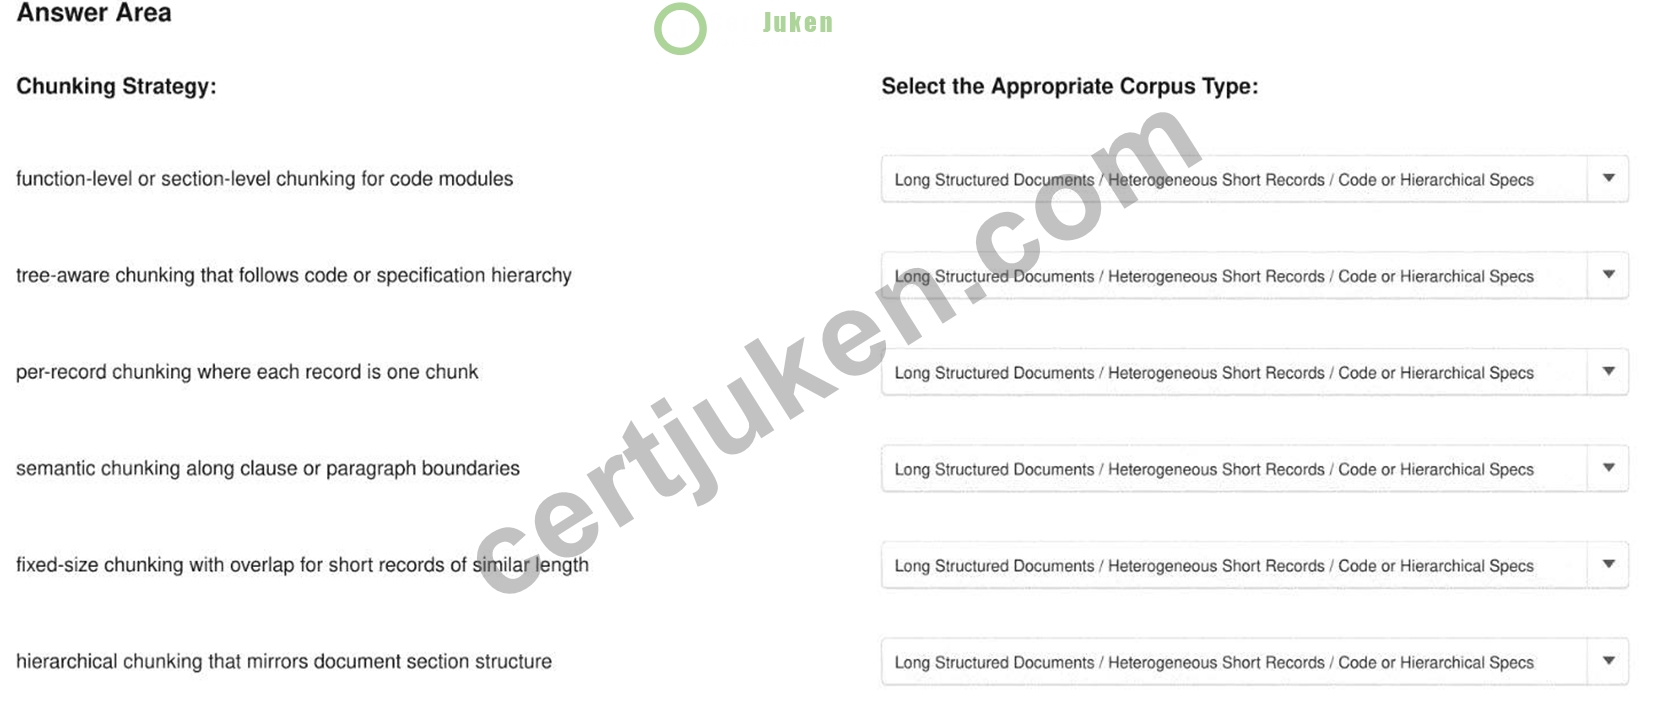
正解:
解説: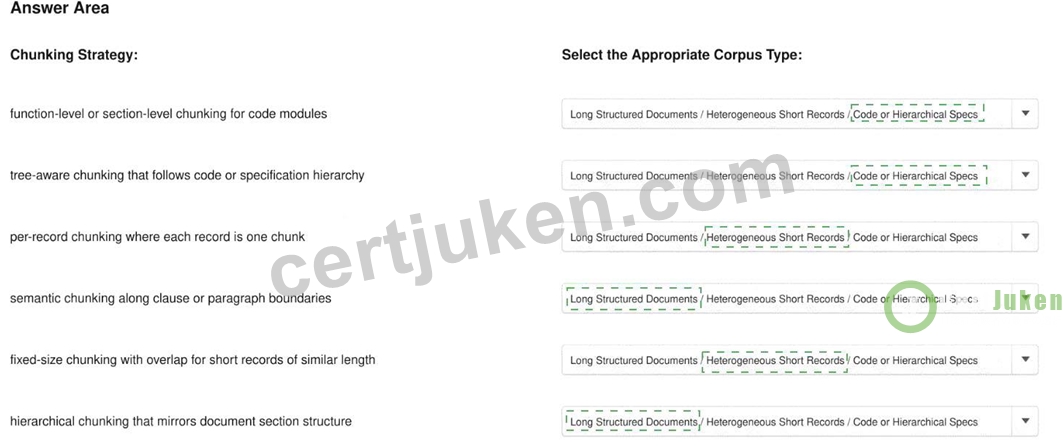
Explanation:
* Function-level or section-level chunking for code modules - Code or Hierarchical Specifications
* Tree-aware chunking that follows code or specification hierarchy - Code or Hierarchical Specifications
* Per-record chunking where each record is one chunk - Heterogeneous Short Records
* Semantic chunking along clause or paragraph boundaries - Long Structured Documents
* Fixed-size chunking with overlap for short records of similar length - Heterogeneous Short Records
* Hierarchical chunking that mirrors document section structure - Long Structured Documents Chunking must preserve the structural unit that carries meaning in the source corpus. Code and hierarchical specifications are best divided at function, module, class, or tree boundaries because arbitrary token cuts can separate definitions from their implementation or parent context. Heterogeneous short-record collections should generally preserve each record as an independent chunk. Fixed-size overlapping chunks are also effective when records have broadly similar lengths and lack meaningful internal hierarchy. Long structured documents benefit from semantic boundaries such as clauses and paragraphs, while hierarchical chunking preserves relationships among sections, subsections, and parent headings. Anthropic notes that chunk size, boundaries, and overlap materially affect retrieval performance; therefore, one universal chunking method is inappropriate. Anthropic Contextual Retrieval
質問 # 98
You are compiling factors that should drive the choice between Model Context Protocol (MCP), direct API integration, and agent-to-agent handoff.
Which two factors belong on the list? (Select two.)
Each correct answer presents a complete solution.
正解:B、D
解説:
The interaction model and portability requirement are architectural decision drivers. MCP is appropriate when tools or data sources must be exposed through a standardized interface reusable across compatible AI clients.
Direct API integration is often preferable for a narrow, stateless, latency-sensitive call where the application already owns the integration logic. Agent-to-agent handoff is better suited to stateful or longer-running delegation between independently responsible agents. Documentation quality and team familiarity influence implementation effort but do not determine the correct integration pattern. Encryption in transit is a mandatory security property for production integration rather than a differentiating architectural requirement; each viable approach must provide it. Anthropic distinguishes direct Messages access from stateful managed- agent infrastructure, while MCP supplies a standardized tool integration layer. Claude Platform documentation
質問 # 99
You are diagnosing a Claude Code session whose subagent uses 50,000 tokens of context before the engineer types a single message.
Which root cause is most likely?
正解:C
解説:
Claude Code constructs the model context before the first user message. That initial context can include the system prompt, project instructions, subagent configuration, MCP server instructions, and tool definitions expressed as JSON schemas. When numerous MCP servers expose many tools and Tool Search is disabled, those schemas must be loaded upfront. A large collection of verbose tool descriptions and parameter schemas can therefore consume tens of thousands of tokens before the engineer enters any text.
Tool Search is specifically designed to prevent this form of context inflation. With Tool Search enabled, Claude initially receives only server instructions and compact tool-identification information; full tool schemas are deferred until a relevant tool is discovered and required. Anthropic consequently describes Tool Search as the mechanism for keeping MCP context consumption low as integrations scale.
Keyboard layouts, font rendering, and display scaling operate outside the language-model context and cannot generate API input tokens. Likewise, model behavior does not silently reserve 50,000 tokens for personal preferences. The diagnostic action is to inspect configured MCP servers and tool counts, determine whether Tool Search has been disabled, and remove or defer unnecessary definitions.
Study Guide references/topics: [MCP Tool Search and context scaling](https://docs.anthropic.com/en/docs
/claude-code/mcp); MCP server configuration; subagent context budgeting; tool-schema optimization.
質問 # 100
......
CCAR-Pテストトレントは好評で、すべての献身で99%の合格率に達しました。多くの労働者がより高い自己改善を進めるための強力なツールとして、当社のCCAR-P認定トレーニングは、高度なパフォーマンスと人間中心のテクノロジーに対する情熱を追求し続けました。 CCAR-P勉強のトレントを完全に理解するには、Webにアクセスするか、CCAR-P試験の質問のデモを無料でダウンロードして、CCAR-Pトレーニングの質を試すためにWebCertJukenで提供します。ガイド。
CCAR-P資格難易度: https://www.certjuken.com/CCAR-P-exam.html