P.S. Free & New AI-300 dumps are available on Google Drive shared by ActualVCE: https://drive.google.com/open?id=1u4L5KB9o5ea-HG6CbXjXjZkZBMgZoCMu
If you can obtain the job qualification AI-300 certificate, which shows you have acquired many skills. In this way, your value is greatly increased in your company. Then sooner or later you will be promoted by your boss. Our AI-300 preparation exam really suits you best. Our AI-300 Study Materials can help you get your certification in the least time with the least efforts. With our AI-300 exam questions for 20 to 30 hours, and you will be ready to take the exam confidently.
| Section | Objectives |
|---|---|
| Implement generative AI quality assurance and observability | - Implement logging, tracing, and telemetry for GenAI applications - Conduct red teaming, adversarial testing, and content filtering - Monitor latency, token usage, cost, and error rates - Evaluate generative AI outputs for quality, safety, and grounding |
| Implement machine learning model lifecycle and operations | - Deploy models to real-time and batch endpoints - Monitor model performance, data drift, and operational health - Retrain, update, and manage model versions in production - Train, register, and version models using Azure Machine Learning |
| Optimize generative AI systems and model performance | - Optimize inference performance, caching, and throughput - Tune prompts, system messages, and grounding strategies - Fine-tune and distill models for specific use cases - Implement cost management and scaling strategies for GenAI workloads |
| Design and implement a GenAIOps infrastructure | - Set up Microsoft Foundry and Azure AI services for generative AI workloads - Configure prompt orchestration, prompt flows, and agent frameworks - Manage API keys, rate limits, and responsible AI guardrails - Implement RAG (Retrieval-Augmented Generation) pipelines and vector search |
| Design and implement an MLOps infrastructure | - Implement security, governance, and compliance for MLOps - Manage environments, data stores, and model registries - Set up Azure Machine Learning workspace and compute targets - Configure source control, CI/CD pipelines, and automation for ML workflows |
>> AI-300 Reliable Exam Questions <<
Have you signed up for Microsoft AI-300 Exam? Will masses of reviewing materials and questions give you a headache? ActualVCE can help you to solve this problem. It is absolutely trustworthy website. Only if you choose to use exam dumps ActualVCE provides, you can absolutely pass your exam successfully. You spend lots of time on these reviewing materials you don't know whether it is useful to you, rather than experiencing the service ActualVCE provides for you. So, hurry to take action.
NEW QUESTION # 98
A team is building a generative AI agent by using Retrieval-Augmented Generation (RAG) in Microsoft Foundry.
The team frequently updates prompt content. The team must be able to track changes across contributors while avoiding full application redeployments.
You need to enable rapid prompt iteration with traceability. Applications consuming the agent must be able to use updated prompts without requiring redeployment.
What should you configure for each requirement? To answer, select the appropriate options in the answer area. NOTE: Each correct selection is worth one point.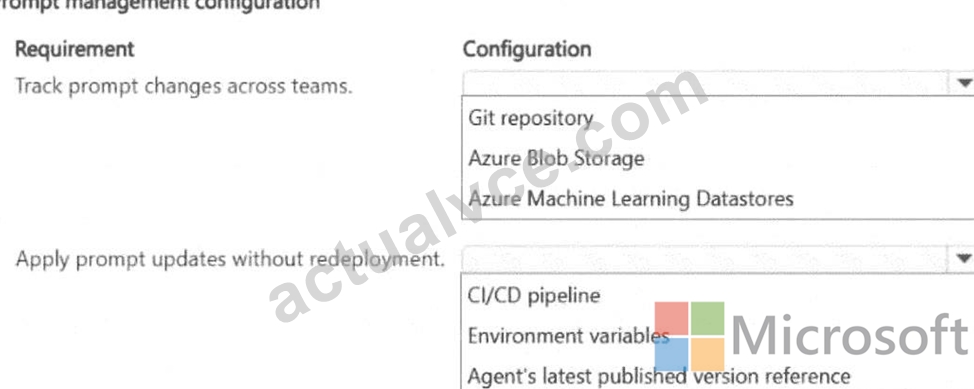
Answer:
Explanation: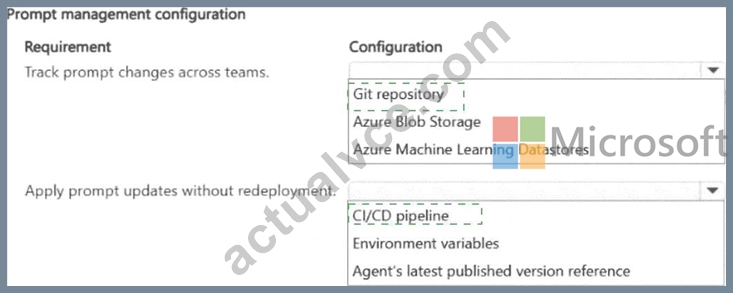
Explanation:
For tracking changes across contributors, Git integration is the answer: by connecting the Microsoft Foundry project to a Git repository, every prompt file change is tracked as a commit with author attribution, timestamp, and diff view, and pull requests enforce review before changes reach production. The Git history provides the complete audit trail and rollback capability needed for traceability. For allowing applications to consume updated prompts without requiring redeployment, Microsoft Foundry ' s prompt management feature allows prompts to be stored and versioned as named artifacts in the project. Applications reference prompts by name and load the latest approved version at inference time, rather than having prompt text hard-coded in the application deployment artifact. This decoupling means updating a prompt is a content operation - not a code deployment - so applications automatically pick up the new prompt without any redeployment.
Microsoft Learn Reference Topic: Prompt management in Microsoft Azure AI Foundry - Git integration and dynamic prompt versioning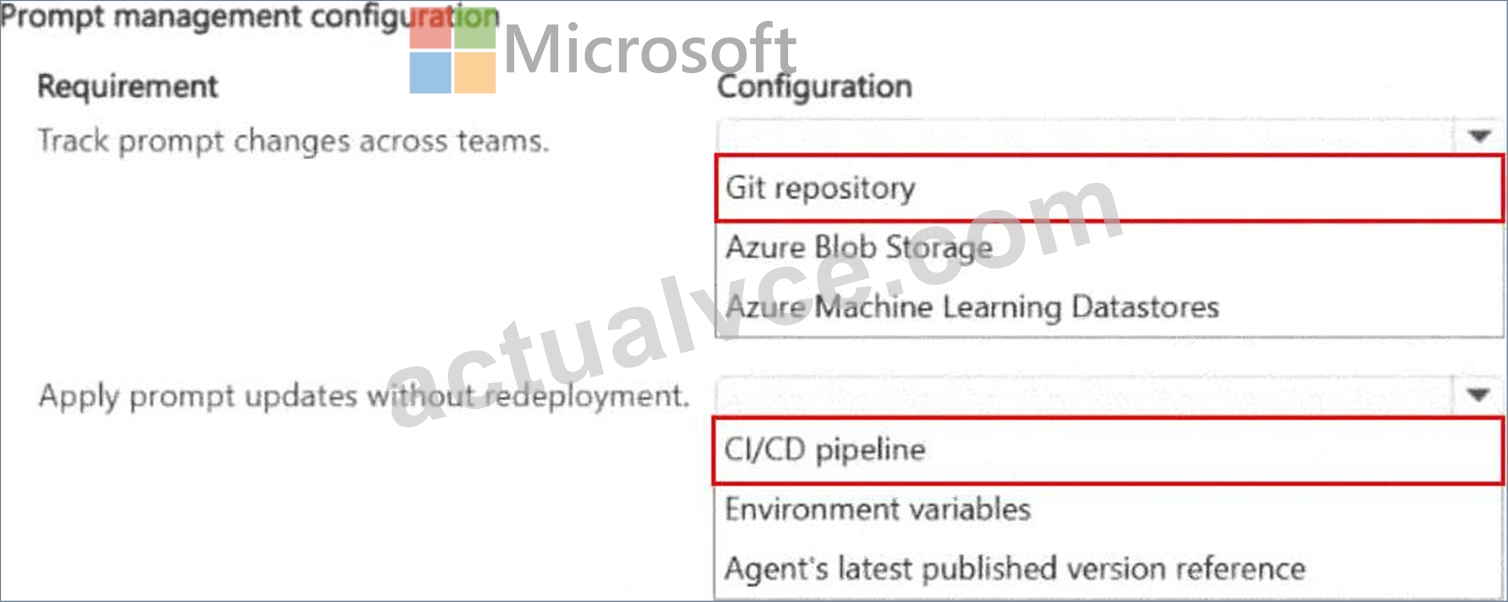
NEW QUESTION # 99
A team develops multiple AI applications in Microsoft Foundry that rely on shared prompt templates.
The team requires a centralized way to track, version, and reuse prompt content across projects.
You need to recommend a solution to track and reuse prompt content.
Which approach should you recommend?
Answer: A
Explanation:
A Git repository provides all three capabilities required: version history for every change with author attribution and timestamp, branching for experimentation, tagging for stable releases, and a single source of truth accessible to all projects via clone or submodule reference. Azure ML datasets (option B) are designed for training data, not text configuration artifacts, and lack per-line diff tracking and review workflows.
Embedding prompts in application configuration files (option C) scatters prompt content across multiple applications with no unified view, no shared versioning, and no cross-project reuse. Unstructured Blob Storage with folder organization (option D) provides no version history, no diff tracking, no review workflow, and no native tooling for comparing prompt variants. Git is the definitive answer for centralized tracking, versioning, and reuse of prompt content across Microsoft Foundry projects.
Microsoft Learn Reference Topic: Prompt engineering and version control - Managing prompts in AI applications with Git
NEW QUESTION # 100
Hotspot Question
You manage an Azure Machine Learning workspace by using the Python SDK v2.
You must create an automated machine learning job to generate a classification model by using data files stored in Parquet format. You must configure an autoscaling compute target and a data asset for the job.
You need to configure the resources for the job.
Which resource configuration should you use? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.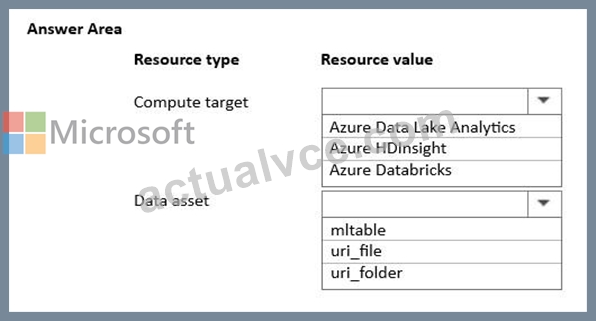
Answer:
Explanation: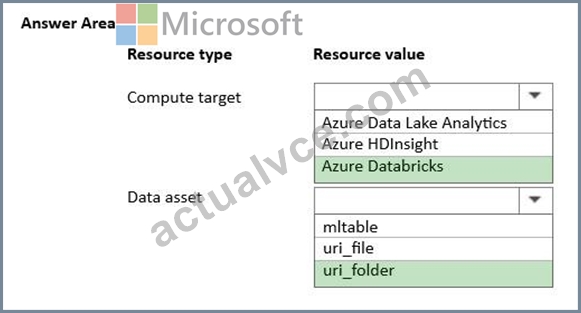
Explanation:
Box 1: Azure Databricks
Autoscaling: Out of the provided choices, Azure Databricks is the only compute target that natively supports the automated scaling up and down of worker nodes required to efficiently match the computation demands of your specific job.
Compatibility: Azure HDInsight and Azure Data Lake Analytics are legacy analytics platforms that do not offer the same direct, optimized, and auto-scaling compute integration within Azure ML SDK v2 pipelines for AutoML training.
Box 2: uri_folder
Directory access: Since your data consists of multiple data files stored in the Parquet format, pointing your asset type to a uri_folder allows the training job to automatically read and ingest all individual Parquet partition files stored inside that directory.
Reference:
https://github.com/Azure/MachineLearningNotebooks/blob/master/how-to-use-azureml/azure-databricks/automl/automl-databricks-local-01.ipynb
NEW QUESTION # 101
You are reviewing a dataset that will be used for an advanced fine-tuning job in Microsoft Foundry.
The fine-tuning job uses preference comparison data.
You review the following dataset excerpt.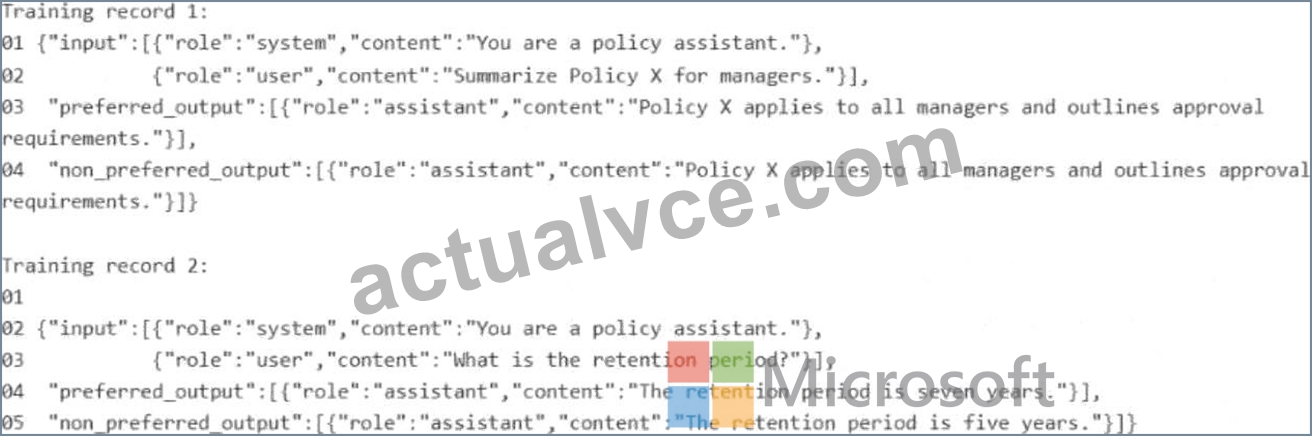
For each of the following statements, select Yes if the statement is true. Otherwise, select No . NOTE: Each correct selection is worth one point.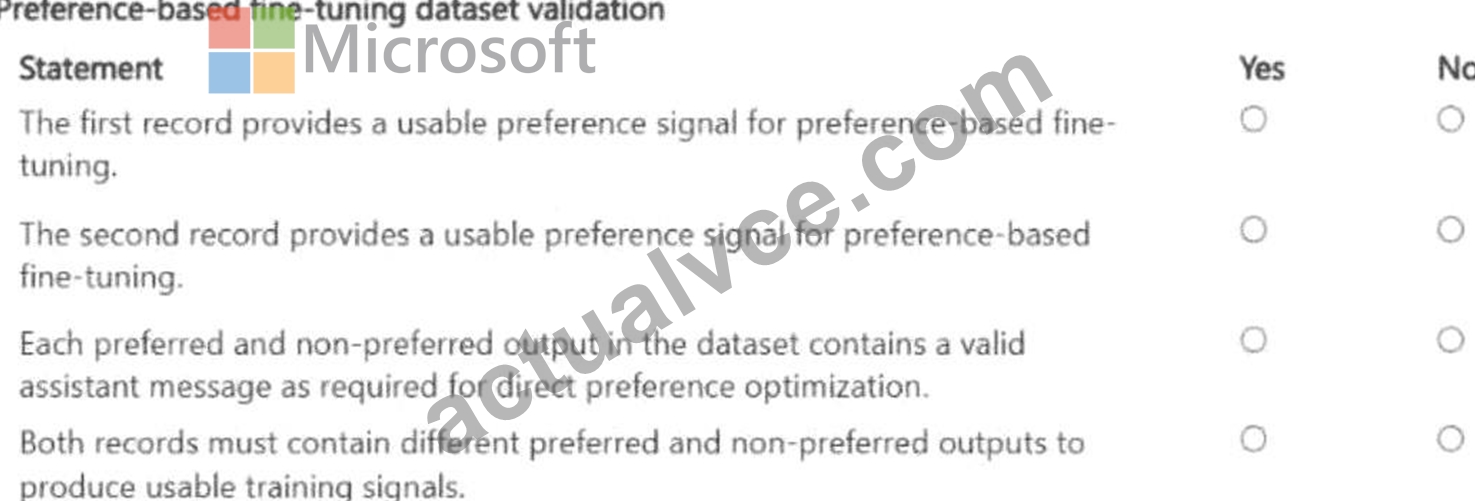
Answer:
Explanation: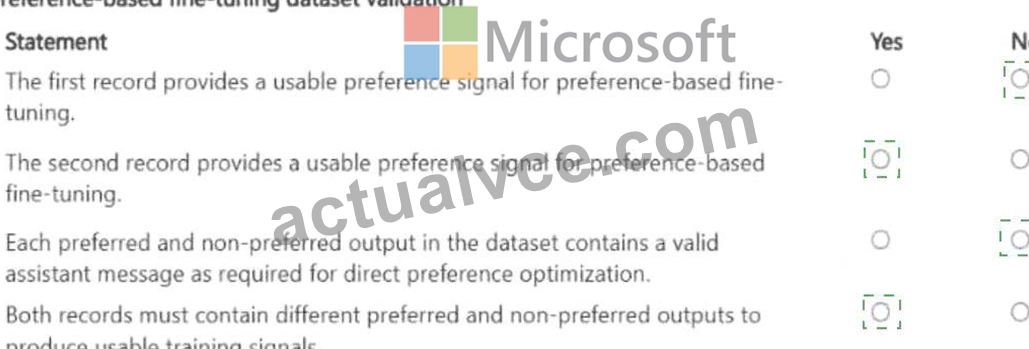
Explanation:
Preference comparison data with chosen versus rejected response pairs is the input format for Direct Preference Optimization (DPO) or RLHF-style fine-tuning - an advanced fine-tuning technique available in Microsoft Foundry. A valid DPO dataset record must have three fields: a prompt as the input, a chosen field containing the preferred response, and a rejected field containing the less preferred response. The file must be in JSONL format with UTF-8 encoding, where each line represents one complete preference pair. When evaluating statements about this dataset, mark True if the dataset contains all three required fields and chosen responses represent higher-quality outputs than rejected ones. Mark False if the format is incompatible with DPO requirements, if the required rejected field is missing, or if the chosen and rejected responses appear to be of equivalent quality with no clear preference signal.
Microsoft Learn Reference Topic: Advanced fine-tuning with preference data in Microsoft Foundry - DPO dataset format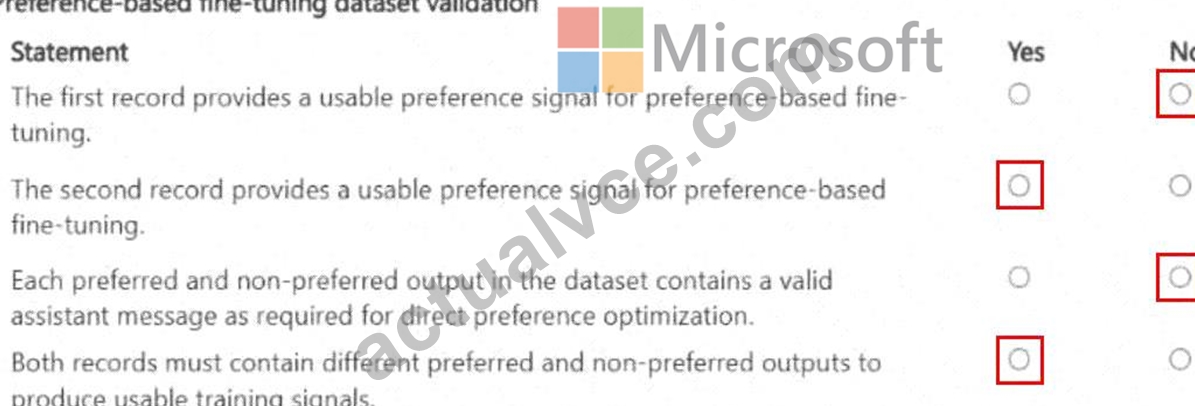
NEW QUESTION # 102
Note: This question is part of a series of questions that present the same scenario. Each question in the series contains a unique solution that might meet the stated goals. Some question sets might have more than one correct solution, while others might not have a correct solution.
After you answer a question in this section, you will NOT be able to return to it. As a result, these questions will not appear on the review screen.
You manage an Azure Machine Learning workspace. The Python script named script.py reads an argument named training_data.
The training_data argument specifies the path to the training data in a file named dataset 1. csv.
You plan to run the script.py Python script as a command job that trains a machine learning model.
You need to provide the command to pass the path for the dataset as a parameter value when you submit the script as a training job.
Solution: python train.py --training_data training_data
Does the solution meet the goal?
Answer: B
Explanation:
This solution fails for two reasons. First, the script filename is wrong: the scenario specifies script.py, but the proposed solution calls train.py. This alone disqualifies the solution. Second, the input reference syntax is incorrect. In Azure ML SDK v2 command jobs, input values are injected into the command string using a placeholder syntax with double curly braces around inputs.name. The value training_data without the placeholder is just a string literal and is not resolved to the actual file path of the input data asset. The correct command syntax uses the proper placeholder so Azure ML can resolve the registered data asset and provide its local path to the script at runtime. Both errors - wrong script name and missing placeholder syntax - make this solution non-functional.
Microsoft Learn Reference Topic: Submit training jobs as command jobs in Azure Machine Learning Python SDK v2
NEW QUESTION # 103
......
IT industry is growing very rapidly in the past few years, so a lot of people start to learn IT knowledge, so that keep them for future success efforts. Microsoft AI-300 certification exam is essential certification of the IT industry, many people frustrated by this certification. Today, I will tell you a good way to pass the exam which is to choose ActualVCE Microsoft AI-300 Exam Training materials. It can help you to pass the exam, and we can guarantee 100% pass rate. If you do not pass, we will guarantee to refund the full purchase cost. So you will have no losses.
AI-300 Reliable Practice Questions: https://www.actualvce.com/Microsoft/AI-300-valid-vce-dumps.html
P.S. Free 2026 Microsoft AI-300 dumps are available on Google Drive shared by ActualVCE: https://drive.google.com/open?id=1u4L5KB9o5ea-HG6CbXjXjZkZBMgZoCMu