P.S. Free & New Professional-Machine-Learning-Engineer dumps are available on Google Drive shared by GetValidTest: https://drive.google.com/open?id=13jSAJNFdPKcEzajC3eYj0hwajZcImCwJ
The Google Professional-Machine-Learning-Engineer PDF dumps format is the most simple and easy version, specially designed by the GetValidTest to provide value to its consumers. It is also compatible with all smart devices. Thus it is portable, which will help you practice the Google Professional-Machine-Learning-Engineer Exam without the barrier of time and place.
| Certification Vendor: | Google Cloud |
|---|---|
| Exam Name: | Google Cloud Professional Machine Learning Engineer Certification Exam |
| Exam Number: | Professional-Machine-Learning-Engineer |
| Exam Format: | Multiple select, Multiple choice |
| Available Languages: | English, Japanese |
| Passing Score: | Not officially published, approximately 70% |
| Exam Duration: | 120 minutes |
| Real Exam Qty: | 50-60 |
| Exam Price: | $200 USD (plus tax where applicable) |
| Certificate Validity Period: | 2 years |
| Related Certifications: | Google Cloud Professional Cloud Architect Google Cloud Professional Data Engineer |
| Recommended Training: | Official Exam Guide Google Cloud Skills Boost - Professional Machine Learning Engineer Learning Path |
| Exam Registration: | Google Cloud Certification Registration |
| Sample Questions: | Google Professional-Machine-Learning-Engineer Sample Questions |
| Exam Way: | Online-proctored remote exam or onsite-proctored exam at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended 3+ years industry experience including 1+ year designing/managing Google Cloud solutions |
| Official Syllabus URL: | https://cloud.google.com/learn/certification/machine-learning-engineer |
>> Professional-Machine-Learning-Engineer Real Exam Questions <<
Our GetValidTest can help you realize your dream to pass Professional-Machine-Learning-Engineer certification exam by providing Professional-Machine-Learning-Engineer test training materials. Because it concludes all training materials you need to Pass Professional-Machine-Learning-Engineer Exam. Choosing our GetValidTest can absolutely help you pass Professional-Machine-Learning-Engineer test easily, and make you become a member of elite in IT. What are you waiting for? Hurry up!
Passing the Google Professional Machine Learning Engineer certification exam can bring several benefits to your career. Firstly, it demonstrates to potential employers that you have a deep understanding of machine learning concepts and can apply them to real-world problems. Secondly, it can open up new job opportunities and increase your earning potential. Finally, it can give you the confidence to take on more complex machine learning projects and advance your career to new heights.
Earning the Google Professional Machine Learning Engineer certification demonstrates to employers and clients that an individual has the skills and knowledge to design, build, and deploy machine learning models using Google Cloud technologies. It also opens up opportunities for career growth and advancement in the field of machine learning.
NEW QUESTION # 156
You are pre-training a large language model on Google Cloud. This model includes custom TensorFlow operations in the training loop Model training will use a large batch size, and you expect training to take several weeks You need to configure a training architecture that minimizes both training time and compute costs What should you do?

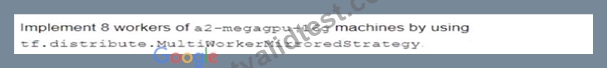


Answer: C
Explanation:
According to the official exam guide1, one of the skills assessed in the exam is to "design, build, and productionalize ML models to solve business challenges using Google Cloud technologies". TPUs2 are Google's custom-developed application-specific integrated circuits (ASICs) used to accelerate machine learning workloads. TPUs are designed to handle large batch sizes, high dimensional data, and complex computations. TPUs can significantly reduce the training time and compute costs of large language models, especially when used with distributed training strategies, such as MultiWorkerMirroredStrategy3. Therefore, option D is the best way to configure a training architecture that minimizes both training time and compute costs for the given use case. The other options are not relevant or optimal for this scenario. References:
* Professional ML Engineer Exam Guide
* TPUs
* MultiWorkerMirroredStrategy
* Google Professional Machine Learning Certification Exam 2023
* Latest Google Professional Machine Learning Engineer Actual Free Exam Questions
NEW QUESTION # 157
You work at a retail company, and are tasked with developing an ML model to predict product sales. Your company's historical sales data is stored in BigQuery and includes features such as date, store location, product category, and promotion details. You need to choose the most effective combination of a BigQuery ML model and feature engineering to maximize prediction accuracy. What should you do?
Answer: B
Explanation:
Linear regression model: This is a suitable choice for predicting continuous variables like product sales. BigQuery ML supports linear regression, making it a practical option for this use case.
One-hot encoding on categorical features: This encoding method is effective for handling categorical variables (e.g., store location, product category) without imposing an ordinal relationship that doesn't exist.
Feature engineering for date-related features: Creating features like "day of the week" or
"month" helps the model capture temporal patterns in the sales data, which are often significant predictors in retail.
NEW QUESTION # 158
You recently joined an enterprise-scale company that has thousands of datasets. You know that there are accurate descriptions for each table in BigQuery, and you are searching for the proper BigQuery table to use for a model you are building on AI Platform. How should you find the data that you need?
Answer: C
Explanation:
Data Catalog is a fully managed and scalable metadata management service that allows you to quickly discover, manage, and understand your data in Google Cloud. You can use Data Catalog to search the BigQuery datasets by using keywords in the table description, as well as other metadata attributes such as table name, column name, labels, tags, and more. Data Catalog also provides a rich browsing experience that lets you explore the schema, preview the data, and access the BigQuery console directly from the Data Catalog UI. Data Catalog helps you find the data that you need for your model building on AI Platform without writing any code or queries.
References:
* [Data Catalog documentation]
* [Data Catalog overview]
* [Searching for data assets]
NEW QUESTION # 159
You work for a telecommunications company You're building a model to predict which customers may fail to pay their next phone bill. The purpose of this model is to proactively offer at-risk customers assistance such as service discounts and bill deadline extensions. The data is stored in BigQuery, and the predictive features that are available for model training include
- Customer_id -Age
- Salary (measured in local currency) -Sex
-Average bill value (measured in local currency)
- Number of phone calls in the last month (integer) -Average duration of phone calls (measured in minutes) You need to investigate and mitigate potential bias against disadvantaged groups while preserving model accuracy What should you do?
Answer: D
Explanation:
* A fairness metric is a way to measure how well a machine learning model treats different groups of customers, such as by sex or age. A common fairness metric is accuracy, which is the proportion of correct predictions among all predictions. Accuracy across the sensitive features means calculating the accuracy for each group separately, and then comparing them. For example, if the model has 90% accuracy for male customers and 80% accuracy for female customers, there is a 10% accuracy gap that indicates potential bias against female customers.
* To investigate and mitigate potential bias, it is important to define a fairness metric and evaluate it on a test set. A test set is a subset of the data that is not used for training the model, but only for evaluating its performance. By joining the test set predictions with the sensitive features, you can calculate the fairness metric and see if it meets your requirements. For example, you may require that the accuracy gap between any two groups is less than 5%. If the fairness metric does not meet your requirements, you may need to adjust the model or the data to reduce bias.
* Option A is not the best answer because excluding the sensitive features and any meaningfully correlated features may not eliminate bias. For example, if salary is correlated with sex, and salary is also a predictive feature for the target variable, excluding both features may reduce the model accuracy and still leave some residual bias. Moreover, excluding features based on correlation may not capture the complex interactions and dependencies among the features that may affect bias.
* Option B is not the best answer because using the global attribution values for each feature of the model may not reflect the individual-level impact of the features on the predictions. Global attribution values are calculated by averaging the attribution values across all the data points, and they indicate how important each feature is for the overall model performance. However, they do not show how each feature affects each customer's prediction, which may vary depending on the values of the other features. For example, sex may have a low global attribution value, but it may have a high impact on some customers' predictions, especially if it interacts with other features such as salary or age.
* Option C is not the best answer because discarding the model and training the model again without a feature based on a single customer's attribution value may not be a robust or scalable way to mitigate bias. Attribution values are calculated by measuring how much each feature contributes to the prediction for a given data point, and they indicate how sensitive the prediction is to the feature value.
However, they do not show how the feature affects the overall fairness metric or the model accuracy.
For example, sex may have a high attribution value for a customer, but it may not affect the accuracy gap between the groups. Moreover, discarding and retraining the model based on a single customer's attribution value may not be feasible if there are many customers with high attribution values for different features.
NEW QUESTION # 160
You are working on a binary classification ML algorithm that detects whether an image of a classified scanned document contains a company's logo. In the dataset, 96% of examples don't have the logo, so the dataset is very skewed. Which metrics would give you the most confidence in your model?
Answer: B
Explanation:
* Option A is correct because using F-score where recall is weighed more than precision is a suitable metric for binary classification with imbalanced data. F-score is a harmonic mean of precision and recall, which are two metrics that measure the accuracy and completeness of the positive class 1
. Precision is the fraction of true p ositives among all predicted positives, while recall is the fraction of true positives among all actual positives 1 . When the data is imbalanced, the positive class is the minority class, which is usually the class of interest. For example, in this case, the positive class is the images that contain the company's logo, which are rare but important to detect. By weighing recall more than precision, we can emphasize the importance of finding all the positive examples, even if some false positives are included 2 .
* Option B is incorrect because using RMSE (root mean squared error) is not a valid metric for binary classification with imbalanced data. RMSE is a metric that measures the average magnitude of the errors between the predicted and actual values 3 . RMSE is suitable for regression problems, where the target variable is continuous, not for classification problems, where the target variable is discrete 4 .
* Option C is incorrect because using F1 score is not the best metric for binary classification with imbalanced data. F1 score is a special case of F-score where precision and recall are equally weighted
1 . F1 score is suitable for balanced data, where the positive and negative classes are equally important and frequent 5 . However, for imbalanced data, the positive class is more important and less frequent than the negative class, so F1 sc ore may not reflect the performance of the model well 2 .
* Option D is incorrect because using F-score where precision is weighed more than recall is not a good metric for binary classification with imbalanced data. By weighing precision more than recall, we can emphasize the impo rtance of minimizing the false positives, even if some true positives are missed 2
. However, for imbalanced data, the true positives are more important and less frequent than the false positives, so this metric may not reflect the performance of the model well 2 .
References:
Precision, recall, an d F-measure
F-score for imbalanced data
RMSE
Regression vs classification
F1 score
[Imbalanced classification]
[Binary classification]
NEW QUESTION # 161
......
Reliable Professional-Machine-Learning-Engineer Test Duration: https://www.getvalidtest.com/Professional-Machine-Learning-Engineer-exam.html
BTW, DOWNLOAD part of GetValidTest Professional-Machine-Learning-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=13jSAJNFdPKcEzajC3eYj0hwajZcImCwJ