BONUS!!! Download part of Pass4training MLA-C01 dumps for free: https://drive.google.com/open?id=1T3ubEcERJVykjgJcXAPjMZ41eB8jmJ-V
The Amazon MLA-C01 certification is on trending nowadays, and many Amazon aspirants are trying to get it. Success in the AWS Certified Machine Learning Engineer - Associate (MLA-C01) test helps you land well-paying jobs. Additionally, the Amazon MLA-C01 certification exam is also beneficial to get promotions in your current company. But the main problem that every applicant faces while preparing for the MLA-C01 Certification test is not finding updated Amazon MLA-C01 practice questions.
| Certification Vendor: | Amazon Web Services (AWS) |
|---|---|
| Exam Name: | AWS Certified Machine Learning Engineer – Associate (MLA-C01) |
| Exam Number: | MLA-C01 |
| Exam Format: | Ordering, Multiple choice, Matching, Multiple response |
| Passing Score: | 720/1000 |
| Available Languages: | English, Japanese, Korean, Simplified Chinese |
| Exam Price: | USD 150 |
| Real Exam Qty: | 65 scored questions + 15 unscored questions |
| Certificate Validity Period: | 3 years |
| Exam Duration: | 130 minutes |
| Related Certifications: | AWS Certified Solutions Architect – Associate AWS Certified AI Practitioner AWS Certified DevOps Engineer – Professional AWS Certified Data Engineer – Associate |
| Recommended Training: | Amazon SageMaker Documentation AWS Skill Builder - ML Engineer Associate Exam Prep |
| Exam Registration: | AWS Certification Registration |
| Sample Questions: | Amazon MLA-C01 Sample Questions |
| Exam Way: | Online proctored or test center exam |
| Pre Condition: | Recommended: ~1 year experience with Amazon SageMaker and AWS-based ML or data engineering roles |
| Official Syllabus URL: | https://aws.amazon.com/certification/certified-machine-learning-engineer-associate/ |
The Amazon MLA-C01 exam questions are being offered in three different formats. The names of these formats are Amazon MLA-C01 PDF dumps file, desktop practice test software, and web-based practice test software. All these three Amazon MLA-C01 Exam Questions formats are easy to use and assist you in Amazon MLA-C01 exam preparation.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
| Topic 4 |
|
NEW QUESTION # 60
A company has a large, unstructured dataset. The dataset includes many duplicate records across several key attributes.
Which solution on AWS will detect duplicates in the dataset with the LEAST code development?
Answer: D
Explanation:
Scenario:The dataset contains duplicate records that need to be detected with minimal code development.
Why FindMatches in AWS Glue?
* Purpose-Built for Deduplication:The FindMatches transform in AWS Glue is specifically designed to identify duplicate records in structured or semi-structured datasets.
* Machine Learning-Based:It uses ML to identify duplicates based on configurable thresholds and provides flexibility for tuning accuracy.
* Low Code Overhead:Minimal development effort is required as Glue provides an interactive console for configuring and running FindMatches transforms.
Steps to Implement:
* Prepare the Data:Upload the unstructured dataset to an S3 bucket and define a schema if needed.
* Create a Glue Job:
* Use the AWS Glue Studio to create a job and select the FindMatches transform.
* Specify key attributes for deduplication.
* Run and Evaluate:Execute the Glue job, and review the results for duplicates.
* Resolve Duplicates:Export results to an S3 bucket or process them as needed.
References:
* AWS Glue FindMatches Documentation
* FindMatches Transform Example
NEW QUESTION # 61
An ML engineer is building a generative AI application on Amazon Bedrock by using large language models (LLMs).
Select the correct generative AI term from the following list for each description. Each term should be selected one time or not at all. (Select three.)
* Embedding
* Retrieval Augmented Generation (RAG)
* Temperature
* Token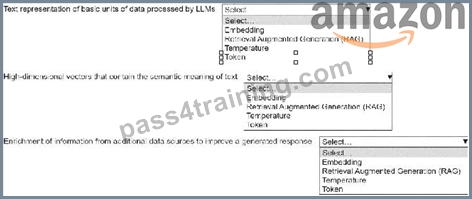
Answer:
Explanation: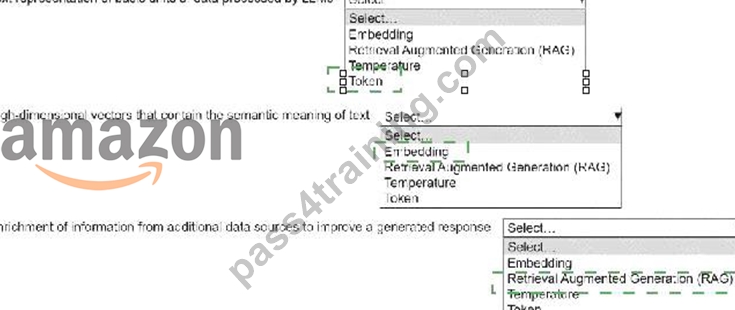
Explanation: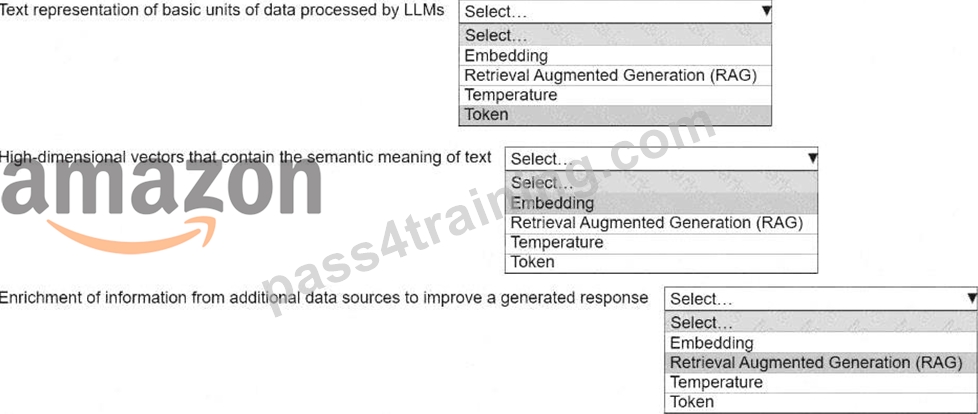
Text representation of basic units of data processed by LLMs: Token
High-dimensional vectors that contain the semantic meaning of text: Embedding Enrichment of information from additional data sources to improve a generated response: Retrieval Augmented Generation (RAG) Comprehensive Detailed Explanation Token:
Description: A token represents the smallest unit of text (e.g., a word or part of a word) that an LLM processes. For example, " running " might be split into two tokens: " run " and " ing. " Why? Tokens are the fundamental building blocks for LLM input and output processing, ensuring that the model can understand and generate text efficiently.
Embedding:
Description: High-dimensional vectors that encode the semantic meaning of text. These vectors are representations of words, sentences, or even paragraphs in a way that reflects their relationships and meaning.
Why? Embeddings are essential for enabling similarity search, clustering, or any task requiring semantic understanding. They allow the model to " understand " text contextually.
Retrieval Augmented Generation (RAG):
Description: A technique where information is enriched or retrieved from external data sources (e.g., knowledge bases or document stores) to improve the accuracy and relevance of a model ' s generated responses.
Why? RAG enhances the generative capabilities of LLMs by grounding their responses in factual and up-to- date information, reducing hallucinations in generated text.
By matching these terms to their respective descriptions, the ML engineer can effectively leverage these concepts to build robust and contextually aware generative AI applications on Amazon Bedrock.
NEW QUESTION # 62
An ML engineer needs to implement a solution to host a trained ML model. The rate of requests to the model will be inconsistent throughout the day.
The ML engineer needs a scalable solution that minimizes costs when the model is not in use. The solution also must maintain the model's capacity to respond to requests during times of peak usage.
Which solution will meet these requirements?
Answer: C
NEW QUESTION # 63
A company uses Amazon SageMaker for its ML workloads. The company's ML engineer receives a 50 MB Apache Parquet data file to build a fraud detection model. The file includes several correlated columns that are not required.
What should the ML engineer do to drop the unnecessary columns in the file with the LEAST effort?
Answer: A
NEW QUESTION # 64
A company has a large collection of chat recordings from customer interactions after a product release. An ML engineer needs to create an ML model to analyze the chat data. The ML engineer needs to determine the success of the product by reviewing customer sentiments about the product.
Which action should the ML engineer take to complete the evaluation in the LEAST amount of time?
Answer: D
Explanation:
Amazon Comprehend is a fully managed natural language processing (NLP) service that includes a built-in sentiment analysis feature. It can quickly and efficiently analyze text data to determine whether the sentiment is positive, negative, neutral, or mixed. Using Amazon Comprehend requires minimal setup and provides accurate results without the need to train and deploy custom models, making it the fastest and most efficient solution for this task.
NEW QUESTION # 65
......
MLA-C01 PDF Download: https://www.pass4training.com/MLA-C01-pass-exam-training.html
DOWNLOAD the newest Pass4training MLA-C01 PDF dumps from Cloud Storage for free: https://drive.google.com/open?id=1T3ubEcERJVykjgJcXAPjMZ41eB8jmJ-V