P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=12O7Lpv-aYzJ_uZK0-8DWgDoSuI7cQE7u
In this rapid rhythm society, the competitions among talents are growing with each passing day, some job might ask more than one's academic knowledge it might also require the professional Microsoft certification and so on. It can't be denied that professional certification is an efficient way for employees to show their personal Implementing Data Engineering Solutions Using Azure Databricks abilities. In order to get more chances, more and more people tend to add shining points, for example a certification to their resumes. What you need to do first is to choose a right DP-750 Exam Material, which will save your time and money in the preparation of the DP-750 exam. Our DP-750 latest questions is one of the most wonderful reviewing Implementing Data Engineering Solutions Using Azure Databricks study training dumps in our industry, so choose us, and together we will make a brighter future.
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Configure and manage Azure Databricks environments | 15-20% | - Security and authentication setup
|
| Topic 2: Deploy and manage data pipelines and workloads | 30-35% | - Pipeline design and orchestration
|
| Topic 3: Secure and govern data using Unity Catalog | 15-20% | - Data governance fundamentals
|
| Topic 4: Prepare and process data | 30-35% | - Data quality and validation
|
>> Microsoft DP-750 Practice Engine <<
With the DP-750 exam, you will harvest many points of theories that others ignore and can offer strong prove for managers. So the DP-750 exam is a great beginning. However, since there was lots of competition in this industry, the smartest way to win the battle is improving the quality of our DP-750 Learning Materials, which we did a great job. With passing rate up to 98 to 100 percent, you will get through the DP-750 exam with ease.
NEW QUESTION # 12
Hotspot Question
You have an Azure Databricks workspace that is enabled for Unity Catalog and contains a managed Delta table named Table1.
Table1 is written by batch jobs every hour and is queried frequently by filtering two columns named Customerid and EventDate.
You expect Table1 to grow significantly over time.
The rows in Table1 are frequently updated and deleted to support compliance requests.
You need to keep query performance consistent as Table1 grows. The solution must minimize update and deletion effort.
What should you include in the solution? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.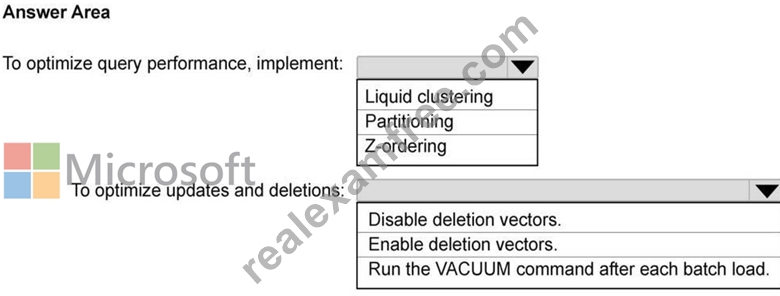
Answer:
Explanation: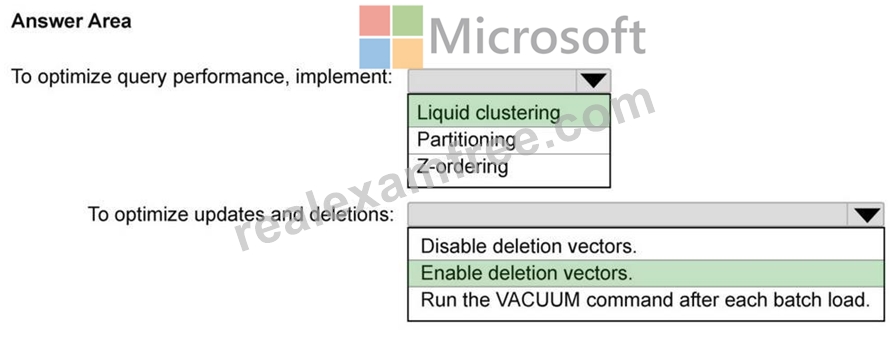
NEW QUESTION # 13
You have an Azure Databricks workspace that is enabled for Unity Catalog.
You need to implement a daily batch data process that requires complex and highly customized Python transformations. The solution must minimize additional complexity.
What should you include in the solution?
Answer: A
Explanation:
A Databricks notebook provides the flexibility required to implement complex, highly customized Python and PySpark transformations. Scheduling that notebook as a Lakeflow Jobs task supplies native daily orchestration, monitoring, retries, and compute management without introducing another service. Azure Data Factory data flows are oriented toward visually designed transformations and would add external orchestration complexity for logic already implemented most naturally in Python. A continuous job is inappropriate because the workload runs once per day rather than continuously. Spark Declarative Pipelines is effective for declarative batch and streaming ETL, but it is less direct when the core requirement emphasizes highly customized procedural Python transformations. A notebook task therefore provides the necessary programming freedom while keeping scheduling and operation inside Azure Databricks.
NEW QUESTION # 14
Hotspot Question
You have an Azure Databricks workspace that contains a job in Lakeflow Jobs named Job1.
Job1 contains three tasks named Task1, Task2, and Task3.
If Task1 fails, Task2 and Task3 must be prevented from running. Successfully completed tasks must NOT rerun during recovery.
You need to configure Job1 to support controlled failure handling and recovery.
What should you configure? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.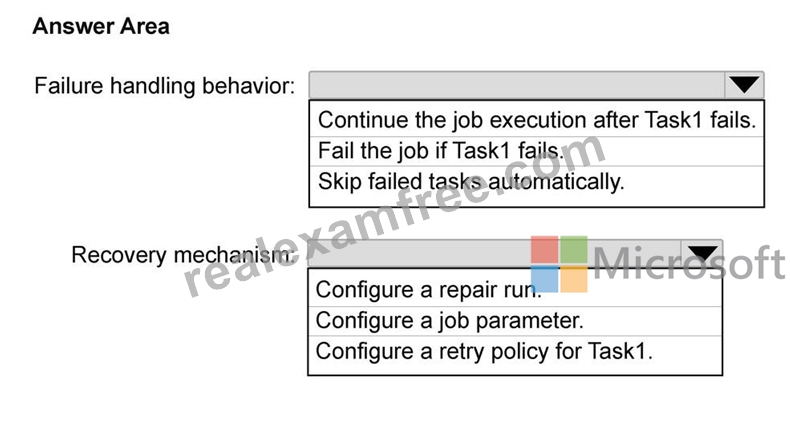
Answer:
Explanation: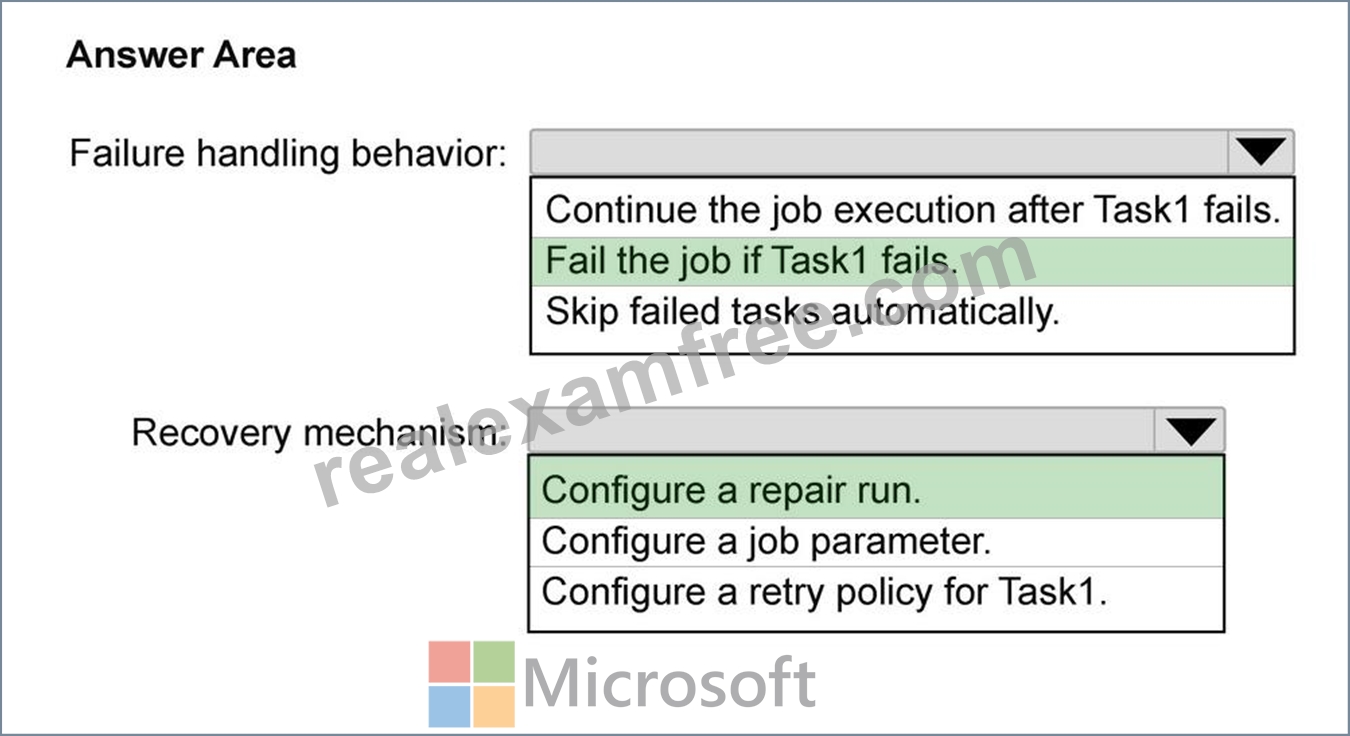
NEW QUESTION # 15
What improves join performance for small lookup tables?
Answer: B
Explanation:
Broadcast joins send the small table to all worker nodes, avoiding expensive shuffling. This significantly improves performance. Shuffle and sort merge joins are heavier. Cartesian joins are inefficient and generally avoided.
NEW QUESTION # 16
You manage Declarative Automation Bundles by using the Databricks CLI.
You run the following command in a terminal window.
databricks bundle init
What occurs when you run the command?
Answer: D
Explanation:
The databricks bundle init command initializes a new bundle project from a selected default or custom project template. It prompts for relevant project values and creates the local project structure and starter configuration files. It does not deploy resources; deployment is performed with databricks bundle deploy. It does not merely validate an existing configuration, because validation uses databricks bundle validate. Running deployed bundle resources requires databricks bundle run followed by the resource key. The distinction matters in an automated bundle lifecycle: initialization scaffolds the project, validation checks configuration, deployment creates or updates workspace resources, and run starts a configured job or pipeline. Therefore, option A accurately describes the initialization command's function. Microsoft Learn
NEW QUESTION # 17
......
You will obtain these updates entirely free if the Microsoft DP-750 certification authorities issue fresh updates. RealExamFree ensures that you will hold the prestigious Microsoft DP-750 certificate on the first endeavor if you work consistently, taking help from our remarkable, up-to-date, and competitive Microsoft DP-750 dumps.
Valid DP-750 Exam Test: https://www.realexamfree.com/DP-750-real-exam-dumps.html
P.S. Free 2026 Microsoft DP-750 dumps are available on Google Drive shared by RealExamFree: https://drive.google.com/open?id=12O7Lpv-aYzJ_uZK0-8DWgDoSuI7cQE7u