2026 Latest Actual4Labs ARA-C01 PDF Dumps and ARA-C01 Exam Engine Free Share: https://drive.google.com/open?id=16Ycl93FQPETODBzmdGUGlJ5gPytjIpe3
The desktop software Snowflake ARA-C01 practice exam format can be used easily used on your Windows system. Customers can use it without the internet. Actual4Labs have made all of the different formats so the students won't face any extra issues and crack ARA-C01 Certification exams for the betterment of their futures.
| Section | Weight | Objectives |
|---|---|---|
| Snowflake Architecture | 30% | - Platform Architecture Design
|
| Accounts and Security | 25% | - Governance and Compliance
|
| Data Engineering | 25% | - Data Loading and Pipelines
|
| Performance Optimization | 20% | - Cost and Resource Optimization
|
Our PDF version of ARA-C01 training materials is legible to read and remember, and support printing request. Software version of ARA-C01 practice materials supports simulation test system, and give times of setup has no restriction. Remember this version support Windows system users only. App online version of ARA-C01 Exam Questions is suitable to all kinds of equipment or digital devices and supportive to offline exercise on the condition that you practice it without mobile data.
NEW QUESTION # 148
Why might a Snowflake Architect use a star schema model rather than a 3NF model when designing a data architecture to run in Snowflake? (Select TWO).
Answer: A,B
NEW QUESTION # 149
Which query will identify the specific days and virtual warehouses that would benefit from a multi-cluster warehouse to improve the performance of a particular workload?

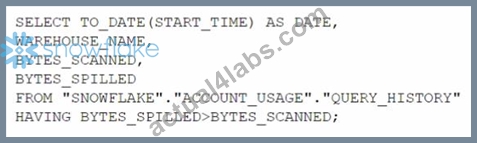
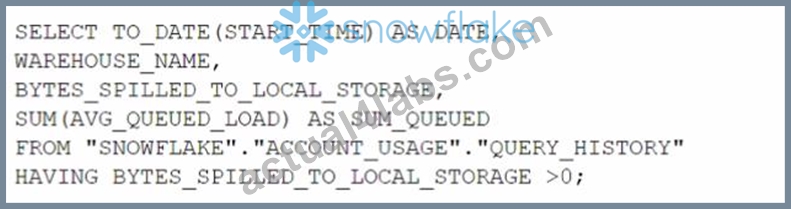
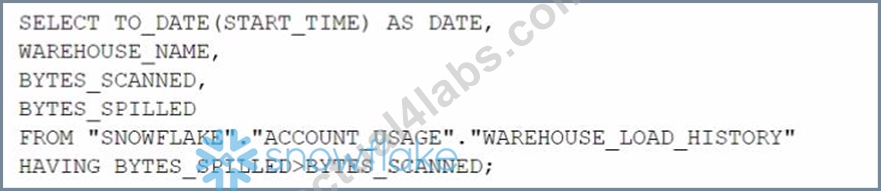
Answer: A
Explanation:
The correct answer is option B. This query is designed to assess the need for a multi-cluster warehouse by examining the queuing time (AVG_QUEUED_LOAD) on different days and virtual warehouses. When the AVG_QUEUED_LOAD is greater than zero, it suggests that queries are waiting for resources, which can be an indicator that performance might be improved by using a multi-cluster warehouse to handle the workload more efficiently. By grouping by date and warehouse name and filtering on the sum of the average queued load being greater than zero, the query identifies specific days and warehouses where the workload exceeded the available compute resources. This information is valuable when considering scaling out warehouses to multi-cluster configurations for improved performance.
NEW QUESTION # 150
Data is being imported and stored as JSON in a VARIANT column. Query performance was fine, but most recently, poor query performance has been reported.
What could be causing this?
Answer: A
Explanation:
Data is being imported and stored as JSON in a VARIANT column. Query performance was fine, but most recently, poor query performance has been reported. This could be caused by the following factors:
The order of the keys in the JSON was changed. Snowflake stores semi-structured data internally in a column- like structure for the most common elements, and the remainder in a leftovers-like column. The order of the keys in the JSON affects how Snowflake determines the common elements and how it optimizes the query performance. If the order of the keys in the JSON was changed, Snowflake might have to re-parse the data and re-organize the internal storage, which could result in slower query performance.
There were variations in string lengths for the JSON values in the recent data imports. Non-native values, such as dates and timestamps, are stored as strings when loaded into a VARIANT column. Operations on these values could be slower and also consume more space than when stored in a relational column with the corresponding data type. If there were variations in string lengths for the JSON values in the recent data imports, Snowflake might have to allocate more space and perform more conversions, which could also result in slower query performance.
The other options are not valid causes for poor query performance:
There were JSON nulls in the recent data imports. Snowflake supports two types of null values in semi- structured data: SQL NULL and JSON null. SQL NULL means the value is missing or unknown, while JSON null means the value is explicitly set to null. Snowflake can distinguish between these two types of null values and handle them accordingly. Having JSON nulls in the recent data imports should not affect the query performance significantly.
The recent data imports contained fewer fields than usual. Snowflake can handle semi-structured data with varying schemas and fields. Having fewer fields than usual in the recent data imports should not affect the query performance significantly, as Snowflake can still optimize the data ingestion and query execution based on the existing fields.
Considerations for Semi-structured Data Stored in VARIANT
Snowflake Architect Training
Snowflake query performance on unique element in variant column
Snowflake variant performance
NEW QUESTION # 151
Why might a Snowflake Architect use a star schema model rather than a 3NF model when designing a data architecture to run in Snowflake? (Select TWO).
Answer: A,B
Explanation:
A star schema model is a type of dimensional data model that consists of a single fact table and multiple dimension tables. A 3NF model is a type of relational data model that follows the third normal form, which eliminates data redundancy and ensures referential integrity. A Snowflake Architect might use a star schema model rather than a 3NF model when designing a data architecture to run in Snowflake for the following reasons:
* A star schema model is more suitable for analytical queries that require aggregating and slicing data across different dimensions, such as those performed by a BI tool. A 3NF model is more suitable for transactional queries that require inserting, updating, and deleting individual records.
* A star schema model is simpler and faster to query than a 3NF model, as it involves fewer joins and less complex SQL statements. A 3NF model is more complex and slower to query, as it involves more joins and more complex SQL statements.
* A star schema model can provide a simple flattened single view of the data to a particular group of end
* users, such as business analysts or data scientists, who need to explore and visualize the data. A 3NF model can provide a more detailed and normalized view of the data to a different group of end users, such as application developers or data engineers, who need to maintain and update the data.
The other options are not valid reasons for choosing a star schema model over a 3NF model in Snowflake:
* Snowflake can handle the joins implied in a 3NF data model, as it supports ANSI SQL and has a powerful query engine that can optimize and execute complex queries efficiently.
* The Architect can use both star schema and 3NF models to remove data duplication from the data stored in Snowflake, as both models can enforce data integrity and avoid data anomalies. However, the trade-off is that a star schema model may have more data redundancy than a 3NF model, as it denormalizes the data for faster query performance, while a 3NF model may have less data redundancy than a star schema model, as it normalizes the data for easier data maintenance.
* The Architect can use both star schema and 3NF models to design a landing zone to receive raw data into Snowflake, as both models can accommodate different types of data sources and formats. However, the choice of the model may depend on the purpose and scope of the landing zone, such as whether it is a temporary or permanent storage, whether it is a staging area or a data lake, and whether it is a single source or a multi-source integration.
References:
* Snowflake Architect Training
* Data Modeling: Understanding the Star and Snowflake Schemas
* Data Vault vs Star Schema vs Third Normal Form: Which Data Model to Use?
* Star Schema vs Snowflake Schema: 5 Key Differences
* Dimensional Data Modeling - Snowflake schema
* Star schema vs Snowflake Schema
NEW QUESTION # 152
How can an Architect enable optimal clustering to enhance performance for different access paths on a given table?
Answer: A
Explanation:
According to the SnowPro Advanced: Architect documents and learning resources, the best way to enable optimal clustering to enhance performance for different access paths on a given table is to create multiple materialized views with different cluster keys. A materialized view is a pre-computed result set that is derived from a query on one or more base tables. A materialized view can be clustered by specifying a clustering key, which is a subset of columns or expressions that determines how the data in the materialized view is co- located in micro-partitions. By creating multiple materialized views with different cluster keys, an Architect can optimize the performance of queries that use different access paths on the same base table. For example, if a base table has columns A, B, C, and D, and there are queries that filter on A and B, or on C and D, or on A and C, the Architect can create three materialized views, each with a different cluster key: (A, B), (C, D), and (A, C). This way, each query can leverage the optimal clustering of the corresponding materialized view and achieve faster scan efficiency and better compression.
Snowflake Documentation: Materialized Views
Snowflake Learning: Materialized Views
https://www.snowflake.com/blog/using-materialized-views-to-solve-multi-clustering-performance-problems/
NEW QUESTION # 153
......
To pass the certification exam, you need to select right ARA-C01 study guide and grasp the overall knowledge points of the real exam. The test questions from our ARA-C01 dumps collection cover almost content of the exam requirement and the real exam. Trying to download the free demo in our website and check the accuracy of ARA-C01 Test Answers and questions. Getting certification will be easy for you with our materials.
ARA-C01 Reliable Exam Cost: https://www.actual4labs.com/Snowflake/ARA-C01-actual-exam-dumps.html
BTW, DOWNLOAD part of Actual4Labs ARA-C01 dumps from Cloud Storage: https://drive.google.com/open?id=16Ycl93FQPETODBzmdGUGlJ5gPytjIpe3