よくできたDatabricks-Certified-Data-Engineer-Professional資格専門知識 &資格試験におけるリーダーオファー &正確的なDatabricks-Certified-Data-Engineer-Professional試験関連赤本

2026年PassTestの最新Databricks-Certified-Data-Engineer-Professional PDFダンプおよびDatabricks-Certified-Data-Engineer-Professional試験エンジンの無料共有:https://drive.google.com/open?id=1c066Kf9by37UCJP5tHtKl4dPBxmE4ZrW
弊社のPassTestはDatabricksのDatabricks-Certified-Data-Engineer-Professional試験を準備している人々に保障を提供しています。我々はあなたのDatabricksのDatabricks-Certified-Data-Engineer-Professional試験のための必要がある資料を提供いたします。あなたが商品を購入してから、あなたが試験に合格するまで弊社は力を尽くしてあなたを助けます。一年間のソフト無料更新も失敗して全額での返金も我々の誠のアフターサービスでございます。
Databricks Databricks-Certified-Data-Engineer-Professional Exam Syllabus Topics:
| Section | Objectives |
|---|
| Data Ingestion and Processing | - ETL pipeline design patterns
- Batch and streaming ingestion with Auto Loader
- Structured Streaming fundamentals
|
| Delta Lake and Data Management | - Time travel and versioning
- Delta Lake transactions and ACID properties
- Schema evolution and enforcement
|
| Databricks Lakehouse Platform Architecture | - Data governance concepts (Unity Catalog basics)
- Medallion architecture (Bronze, Silver, Gold)
- Workspace and cluster architecture
|
| Production Pipelines and Orchestration | - Error handling and recovery strategies
- Job scheduling and monitoring
- Databricks Workflows
|
| Data Modeling and Transformation | - Spark SQL transformations
- Performance optimization techniques
- Dimensional modeling concepts
|
>> Databricks-Certified-Data-Engineer-Professional資格専門知識 <<
Databricks-Certified-Data-Engineer-Professional試験関連赤本、Databricks-Certified-Data-Engineer-Professional試験復習
この情報の時代の中に、たくさんのIT機構はDatabricksのDatabricks-Certified-Data-Engineer-Professional認定試験に関する教育資料がありますけれども、受験生がこれらのサイトを通じて詳細な資料を調べられなくて、対応性がなくて受験生の注意 に惹かれなりません。
Databricks Certified Data Engineer Professional Exam 認定 Databricks-Certified-Data-Engineer-Professional 試験問題 (Q48-Q53):
質問 # 48
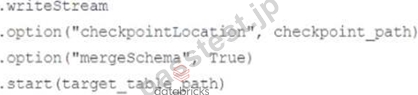
In order to facilitate near real-time workloads, a data engineer is creating a helper function to Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from leverage the schema detection and evolution functionality of Databricks Auto Loader. The desired function will automatically detect the schema of the source directly, incrementally process JSON files as they arrive in a source directory, and automatically evolve the schema of the table when new fields are detected.
The function is displayed below with a blank:
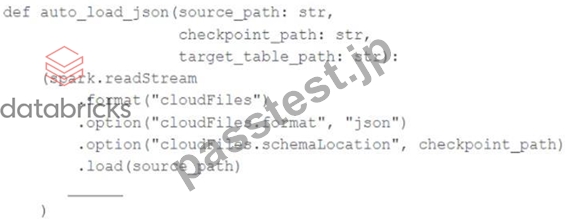
Which response correctly fills in the blank to meet the specified requirements?
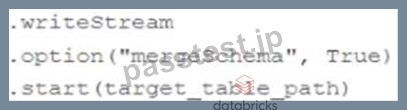
- A.
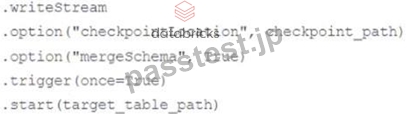
- B. Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
- C.
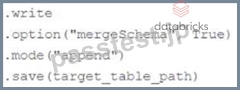
- D.
- E.

正解:D
解説:
https://docs.databricks.com/en/ingestion/auto-loader/schema.html
質問 # 49
Which statement regarding spark configuration on the Databricks platform is true?
- A. When the same spar configuration property is set for an interactive to the same interactive cluster.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from - B. Spark configuration properties set for an interactive cluster with the Clusters UI will impact all notebooks attached to that cluster.
- C. Spark configuration set within an notebook will affect all SparkSession attached to the same interactive cluster
- D. Spark configuration properties can only be set for an interactive cluster by creating a global init script.
- E. The Databricks REST API can be used to modify the Spark configuration properties for an interactive cluster without interrupting jobs.
正解:B
解説:
When Spark configuration properties are set for an interactive cluster using the Clusters UI in Databricks, those configurations are applied at the cluster level. This means that all notebooks attached to that cluster will inherit and be affected by these configurations. This approach ensures consistency across all executions within that cluster, as the Spark configuration properties dictate aspects such as memory allocation, number of executors, and other vital execution parameters. This centralized configuration management helps maintain standardized execution environments across different notebooks, aiding in debugging and performance optimization.
質問 # 50
A data engineer needs to capture pipeline settings from an existing in the workspace, and use them to create and version a JSON file to create a new pipeline. Which command should the data engineer enter in a web terminal configured with the Databricks CLI?
- A. Use list pipelines to get the specs for all pipelines; get the pipeline spec from the return results parse and use this to create a pipeline
- B. Use the get command to capture the settings for the existing pipeline; remove the pipeline_id and rename the pipeline; use this in a create command
- C. Stop the existing pipeline; use the returned settings in a reset command
- D. Use the alone command to create a copy of an existing pipeline; use the get JSON command to get the pipeline definition; save this to git
正解:B
解説:
The Databricks CLI provides a way to automate interactions with Databricks services. When dealing with pipelines, you can use the databricks pipelines get --pipeline-id command to capture the settings of an existing pipeline in JSON format. This JSON can then be modified by removing the pipeline_id to prevent conflicts and renaming the pipeline to create a new pipeline. The modified JSON file can then be used with the databricks pipelines create command to create a new pipeline with those settings.
Get Latest & Actual Certified-Data-Engineer-Professional Exam's Question and Answers from
質問 # 51
The downstream consumers of a Delta Lake table have been complaining about data quality issues impacting performance in their applications. Specifically, they have complained that invalid latitude and longitude values in the activity_details table have been breaking their ability to use other geolocation processes.
A junior engineer has written the following code to add CHECK constraints to the Delta Lake table:
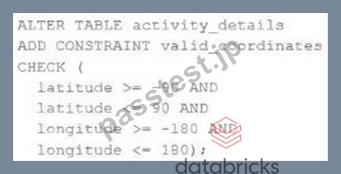
A senior engineer has confirmed the above logic is correct and the valid ranges for latitude and longitude are provided, but the code fails when executed.
Which statement explains the cause of this failure?
- A. The activity details table already exists; CHECK constraints can only be added during initial table creation.
- B. The activity details table already contains records that violate the constraints; all existing data must pass CHECK constraints in order to add them to an existing table.
- C. The activity details table already contains records; CHECK constraints can only be added prior to inserting values into a table.
- D. Because another team uses this table to support a frequently running application, two-phase locking is preventing the operation from committing.
- E. The current table schema does not contain the field valid coordinates; schema evolution will need to be enabled before altering the table to add a constraint.
正解:B
解説:
The failure is that the code to add CHECK constraints to the Delta Lake table fails when executed. The code uses ALTER TABLE ADD CONSTRAINT commands to add two CHECK constraints to a table named activity_details. The first constraint checks if the latitude value is between -90 and 90, and the second constraint checks if the longitude value is between -180 and
180. The cause of this failure is that the activity_details table already contains records that violate these constraints, meaning that they have invalid latitude or longitude values outside of these ranges. When adding CHECK constraints to an existing table, Delta Lake verifies that all existing data satisfies the constraints before adding them to the table. If any record violates the constraints, Delta Lake throws an exception and aborts the operation.
質問 # 52
A large company seeks to implement a near real-time solution involving hundreds of pipelines with parallel updates of many tables with extremely high volume and high velocity data.
Which of the following solutions would you implement to achieve this requirement?
- A. Store all tables in a single database to ensure that the Databricks Catalyst Metastore can load balance overall throughput.
- B. Isolate Delta Lake tables in their own storage containers to avoid API limits imposed by cloud vendors.
- C. Configure Databricks to save all data to attached SSD volumes instead of object storage, increasing file I/O significantly.
- D. Partition ingestion tables by a small time duration to allow for many data files to be written in parallel.
- E. Use Databricks High Concurrency clusters, which leverage optimized cloud storage connections to maximize data throughput.
正解:E
解説:
High Concurrency clusters in Databricks are designed for multiple concurrent users and workloads. They provide fine-grained sharing of cluster resources and are optimized for operations such as running multiple parallel queries and updates. This would be suitable for a solution that involves many pipelines with parallel updates, especially with high volume and high velocity data.
質問 # 53
......
PassTestに提供されている資料はIT認定試験に対して10年過ぎの経験を持っているプロフェッショナルによって研究と実践を通じて作成し出されたものです。PassTestは最新かつ最も正確な試験Databricks-Certified-Data-Engineer-Professional問題集を用意しておきます。PassTestは皆さんの成功のために存在しているものですから、PassTestを選択することは成功を選択するのと同じです。順調にIT認定試験に合格したいなら、PassTestはあなたの唯一の選択です。
Databricks-Certified-Data-Engineer-Professional試験関連赤本: https://www.passtest.jp/Databricks/Databricks-Certified-Data-Engineer-Professional-shiken.html
- Databricks Databricks-Certified-Data-Engineer-Professional資格専門知識: Databricks Certified Data Engineer Professional Exam - www.passtest.jp 確実に合格するのを助ける 🟡 ➥ www.passtest.jp 🡄から簡単に{ Databricks-Certified-Data-Engineer-Professional }を無料でダウンロードできますDatabricks-Certified-Data-Engineer-Professional試験解答
- 権威のあるDatabricks-Certified-Data-Engineer-Professional資格専門知識 - 合格スムーズDatabricks-Certified-Data-Engineer-Professional試験関連赤本 | 100%合格率のDatabricks-Certified-Data-Engineer-Professional試験復習 🏬 ▛ www.goshiken.com ▟を開き、➤ Databricks-Certified-Data-Engineer-Professional ⮘を入力して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional赤本勉強
- Databricks-Certified-Data-Engineer-Professional試験解答 🏫 Databricks-Certified-Data-Engineer-Professional試験解答 🛺 Databricks-Certified-Data-Engineer-Professional試験解答 🧽 時間限定無料で使える▛ Databricks-Certified-Data-Engineer-Professional ▟の試験問題は➤ www.topexam.jp ⮘サイトで検索Databricks-Certified-Data-Engineer-Professional認定資格試験
- Databricks-Certified-Data-Engineer-Professional認定資格試験 🤔 Databricks-Certified-Data-Engineer-Professionalファンデーション ⏲ Databricks-Certified-Data-Engineer-Professional専門トレーリング 💍 《 www.goshiken.com 》で使える無料オンライン版☀ Databricks-Certified-Data-Engineer-Professional ️☀️ の試験問題Databricks-Certified-Data-Engineer-Professional日本語版参考書
- Databricks-Certified-Data-Engineer-Professional日本語版テキスト内容 ⏯ Databricks-Certified-Data-Engineer-Professional実際試験 🥗 Databricks-Certified-Data-Engineer-Professional学習資料 🤰 「 www.xhs1991.com 」は、☀ Databricks-Certified-Data-Engineer-Professional ️☀️を無料でダウンロードするのに最適なサイトですDatabricks-Certified-Data-Engineer-Professional学習資料
- Databricks-Certified-Data-Engineer-Professional最速合格 🧱 Databricks-Certified-Data-Engineer-Professional実際試験 🌏 Databricks-Certified-Data-Engineer-Professional赤本勉強 🧽 ▷ www.goshiken.com ◁で「 Databricks-Certified-Data-Engineer-Professional 」を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語版参考書
- Databricks-Certified-Data-Engineer-Professional専門トレーリング 📘 Databricks-Certified-Data-Engineer-Professional専門トレーリング 🤡 Databricks-Certified-Data-Engineer-Professionalファンデーション ☁ ⏩ www.shikenpass.com ⏪サイトで➡ Databricks-Certified-Data-Engineer-Professional ️⬅️の最新問題が使えるDatabricks-Certified-Data-Engineer-Professional試験解答
- Databricks-Certified-Data-Engineer-Professional勉強の資料 ⛄ Databricks-Certified-Data-Engineer-Professional出題内容 🐞 Databricks-Certified-Data-Engineer-Professional試験解答 🔖 ➥ Databricks-Certified-Data-Engineer-Professional 🡄を無料でダウンロード( www.goshiken.com )ウェブサイトを入力するだけDatabricks-Certified-Data-Engineer-Professional受験対策解説集
- Databricks-Certified-Data-Engineer-Professional復習資料 🌵 Databricks-Certified-Data-Engineer-Professional専門トレーリング 👕 Databricks-Certified-Data-Engineer-Professional学習資料 🌇 ➥ www.xhs1991.com 🡄サイトにて最新[ Databricks-Certified-Data-Engineer-Professional ]問題集をダウンロードDatabricks-Certified-Data-Engineer-Professional日本語版テキスト内容
- Databricks-Certified-Data-Engineer-Professionalファンデーション ⛄ Databricks-Certified-Data-Engineer-Professional科目対策 🕝 Databricks-Certified-Data-Engineer-Professional勉強の資料 🤝 ウェブサイト✔ www.goshiken.com ️✔️を開き、▶ Databricks-Certified-Data-Engineer-Professional ◀を検索して無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional専門トレーリング
- Databricks-Certified-Data-Engineer-Professional専門トレーリング 😮 Databricks-Certified-Data-Engineer-Professional日本語版テキスト内容 🔌 Databricks-Certified-Data-Engineer-Professional出題内容 🛩 今すぐ《 www.mogiexam.com 》で➽ Databricks-Certified-Data-Engineer-Professional 🢪を検索して、無料でダウンロードしてくださいDatabricks-Certified-Data-Engineer-Professional日本語問題集
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S.PassTestがGoogle Driveで共有している無料の2026 Databricks Databricks-Certified-Data-Engineer-Professionalダンプ:https://drive.google.com/open?id=1c066Kf9by37UCJP5tHtKl4dPBxmE4ZrW