P.S. Free 2026 Microsoft DP-600 dumps are available on Google Drive shared by TorrentVCE: https://drive.google.com/open?id=1uz4WfpzRxkQxWzWt1M8heyyPYYdF8Fe6
To give you an idea about the top features of TorrentVCE Microsoft exam questions, a free demo of TorrentVCE Implementing Analytics Solutions Using Microsoft Fabric (DP-600) exam dumps is being offered free of cost. Just download TorrentVCE DP-600 Exam Questions demo and checks out the top features of TorrentVCE DP-600 exam dumps.
| Certification Vendor: | Microsoft |
|---|---|
| Exam Name: | Implementing Analytics Solutions Using Microsoft Fabric |
| Exam Number: | DP-600 |
| Real Exam Qty: | 40–60 |
| Exam Duration: | 100 minutes |
| Exam Price: | USD 165 |
| Exam Format: | Multiple choice, Case study, Scenario-based |
| Passing Score: | 700 / 1000 |
| Certificate Validity Period: | 2 years |
| Available Languages: | Portuguese (Brazil), French, Spanish, Chinese (Simplified), English, Japanese, German |
| Recommended Training: | Microsoft Learn: DP-600 Learning Path |
| Exam Registration: | Microsoft Certification Exam Registration |
| Sample Questions: | Microsoft DP-600 Sample Questions |
| Exam Way: | Online proctored or onsite at authorized test centers |
| Pre Condition: | No mandatory prerequisites; recommended experience with data modeling, SQL, DAX, and Microsoft Fabric components |
| Official Syllabus URL: | https://learn.microsoft.com/en-us/credentials/certifications/resources/study-guides/dp-600 |
How can our DP-600 practice materials become salable products? Their quality with low prices is unquestionable. There are no better or cheaper practice materials can replace our DP-600 exam questions as alternatives while can provide the same functions. The accomplished DP-600 Guide exam is available in the different countries around the world and being testified over the customers around the different countries. They are valuable acquisitions to the filed.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
NEW QUESTION # 85
You have a Microsoft Fabric tenant that contains a dataflow.
You are exploring a new semantic model.
From Power Query, you need to view column information as shown in the following exhibit.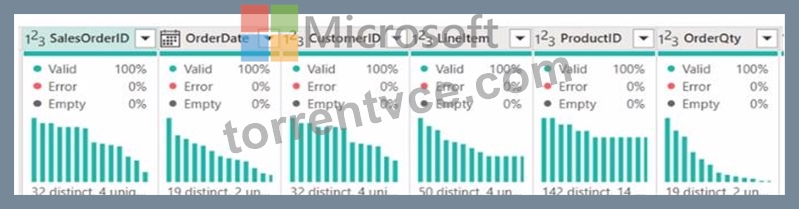
Which three Data view options should you select? Each correct answer presents part of the solution. NOTE: Each correct answer is worth one point.
Answer: A,B,D
Explanation:
To view column information like the one shown in the exhibit in Power Query, you need to select the options that enable profiling and display quality and distribution details.
These are: A. Enable column profile - This option turns on profiling for each column, showing statistics such as distinct and unique values. B. Show column quality details - It displays the column quality bar on top of each column showing the percentage of valid, error, and empty values. E. Show column value distribution - It enables the histogram display of value distribution for each column, which visualizes how often each value occurs.
NEW QUESTION # 86
You are analyzing the data in a Fabric notebook.
You have a Spark DataFrame assigned to a variable named df.
You need to use the Chart view in the notebook to explore the data manually.
Which function should you run to make the data available in the Chart view?
Answer: C
Explanation:
The display function is the correct choice to make the data available in the Chart view within a Fabric notebook. This function is used to visualize Spark DataFrames in various formats including charts and graphs directly within the notebook environment. References = Further explanation of the display function can be found in the official documentation on Azure Synapse Analytics notebooks.
NEW QUESTION # 87
You have a Microsoft Fabric tenant that contains a dataflow.
You are exploring a new semantic model.
From Power Query, you need to view column information as shown in the following exhibit.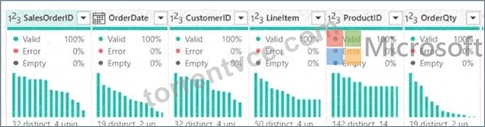
Which three Data view options should you select? Each correct answer presents part of the solution. NOTE:
Each correct answer is worth one point.
Answer: A,B,D
Explanation:
To view column information like the one shown in the exhibit in Power Query, you need to select the options that enable profiling and display quality and distribution details. These are: A. Enable column profile - This option turns on profiling for each column, showing statistics such as distinct and unique values. B. Show column quality details - It displays the column quality bar on top of each column showing the percentage of valid, error, and empty values. E. Show column value distribution - It enables the histogram display of value distribution for each column, which visualizes how often each value occurs.
References: These features and their descriptions are typically found in the Power Query documentation, under the section for data profiling and quality features.
NEW QUESTION # 88
You have a Fabric tenant that contains a data pipeline.
You need to ensure that the pipeline runs every four hours on Mondays and Fridays.
To what should you set Repeat for the schedule?
Answer: D
Explanation:
The only way to do this is to set the schedule to ''Weekly'', set the days on Monday and Friday and add manually 6 Time of 4 hour intervals.
NEW QUESTION # 89
You have a Fabric eventhouse that contains a KQL database. The database contains a table named TaxiData that stores the following data.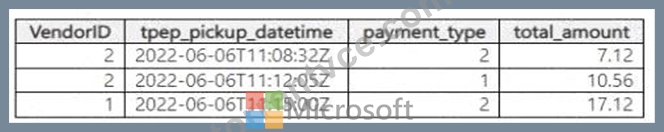
You need to create a column named FirstPickupDateTime that will contain the first value of each hour from tpep_pickup_datetime partitioned by payment_type.
NOTE: Each correct selection is worth one point.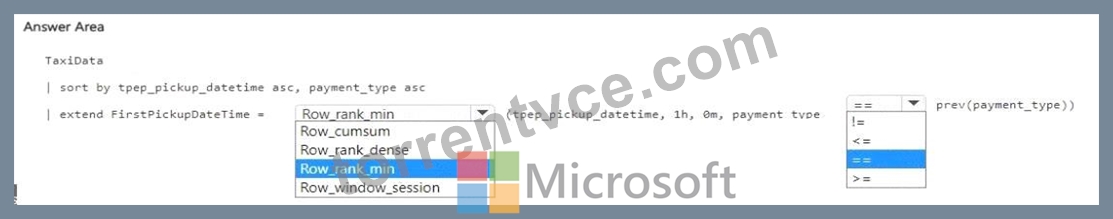
Answer:
Explanation: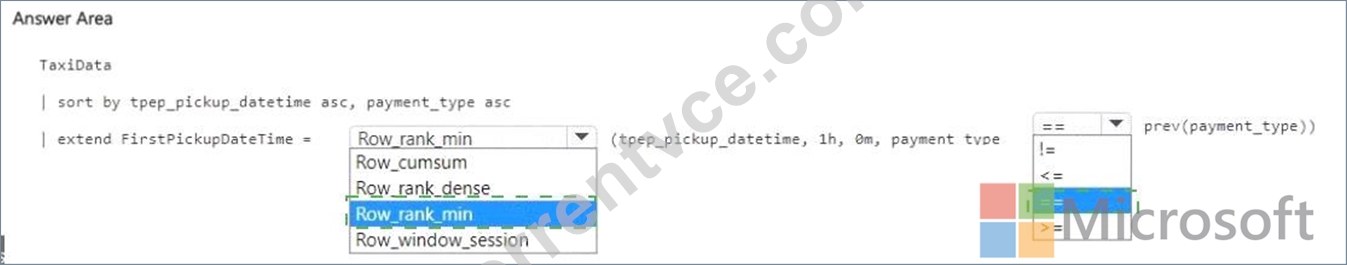
Explanation: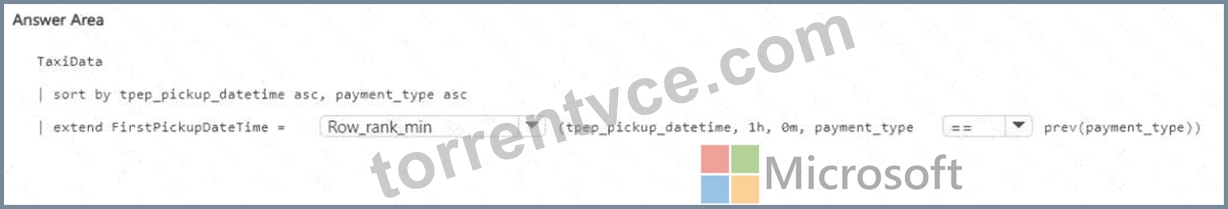
Comprehensive Detailed Explanation
We have a KQL table (TaxiData) with columns:
VendorID
tpep_pickup_datetime (timestamp)
payment_type
total_amount
The requirement:
Create a new column FirstPickupDateTime
It should contain the first pickup timestamp per hour
Partitioning should be done by payment_type
Step 1: Which windowing function?
row_cumsum # running cumulative sum (not needed here).
row_rank_dense # assigns ranks without gaps, but does not guarantee minimum value only.
row_rank_min # gives the first/minimum value in each window partition. # Correct.
row_window_session # sessionization of events, not required.
So, the correct function is row_rank_min .
Step 2: Which comparison operator?
We need to select the row where the rank = 1 (the first per partition).
So the correct operator is == (equals).
Step 3: Partitioning
The KQL query should partition by:
bin(tpep_pickup_datetime, 1h) # buckets data into 1-hour windows
payment_type # partitions further by payment type
Completed KQL Query
TaxiData
| sort by tpep_pickup_datetime asc, payment_type asc
| extend FirstPickupDateTime = row_rank_min(tpep_pickup_datetime, 1h, 0m, payment_type)
| where FirstPickupDateTime == 1
This assigns a rank within each 1-hour, per-payment-type window, then keeps the first pickup timestamp .
Why This Works
row_rank_min # ensures we capture the first occurrence in each hour.
== # filters only the first row per partition.
bin(..., 1h) ensures grouping is by hour.
References
Kusto row_rank_min() function
KQL window functions
NEW QUESTION # 90
......
DP-600 Downloadable PDF: https://www.torrentvce.com/DP-600-valid-vce-collection.html
What's more, part of that TorrentVCE DP-600 dumps now are free: https://drive.google.com/open?id=1uz4WfpzRxkQxWzWt1M8heyyPYYdF8Fe6