NVIDIA AI Operations Testking Cram & NCP-AIO Prep Vce & NVIDIA AI Operations Free Pdf

2026 Latest TestInsides NCP-AIO PDF Dumps and NCP-AIO Exam Engine Free Share: https://drive.google.com/open?id=1I7K4Du-HWtCtrtqtvpHDKXWjQ-ZnffI6
First of all, we have the best and most first-class operating system, in addition, we also solemnly assure users that users can receive the information from the NCP-AIO learning material within 5-10 minutes after their payment. Second, once we have written the latest version of the NCP-AIO learning material, our products will send them the latest version of the NCP-AIO Training Material free of charge for one year after the user buys the product. Last but not least, our perfect customer service staff will provide users with the highest quality and satisfaction in the hours.
| Topic | Details |
|---|
| Topic 1 | - Administration: This section of the exam measures the skills of system administrators and covers essential tasks in managing AI workloads within data centers. Candidates are expected to understand fleet command, Slurm cluster management, and overall data center architecture specific to AI environments. It also includes knowledge of Base Command Manager (BCM), cluster provisioning, Run.ai administration, and configuration of Multi-Instance GPU (MIG) for both AI and high-performance computing applications.
|
| Topic 2 | - Installation and Deployment: This section of the exam measures the skills of system administrators and addresses core practices for installing and deploying infrastructure. Candidates are tested on installing and configuring Base Command Manager, initializing Kubernetes on NVIDIA hosts, and deploying containers from NVIDIA NGC as well as cloud VMI containers. The section also covers understanding storage requirements in AI data centers and deploying DOCA services on DPU Arm processors, ensuring robust setup of AI-driven environments.
|
| Topic 3 | - Workload Management: This section of the exam measures the skills of AI infrastructure engineers and focuses on managing workloads effectively in AI environments. It evaluates the ability to administer Kubernetes clusters, maintain workload efficiency, and apply system management tools to troubleshoot operational issues. Emphasis is placed on ensuring that workloads run smoothly across different environments in alignment with NVIDIA technologies.
|
| Topic 4 | - Troubleshooting and Optimization: NVIThis section of the exam measures the skills of AI infrastructure engineers and focuses on diagnosing and resolving technical issues that arise in advanced AI systems. Topics include troubleshooting Docker, the Fabric Manager service for NVIDIA NVlink and NVSwitch systems, Base Command Manager, and Magnum IO components. Candidates must also demonstrate the ability to identify and solve storage performance issues, ensuring optimized performance across AI workloads.
|
>> Exam NCP-AIO Revision Plan <<
HOT Exam NCP-AIO Revision Plan: NVIDIA AI Operations - High-quality NVIDIA NCP-AIO Valid Dumps Ebook
If you can possess the certification, your competitive force in the job market will be improved, and you can also improve your salary. NCP-AIO exam dumps can help you pass the exam and obtain the certification successfully. With a professional team to edit and verify, NCP-AIO exam materials are high quality and accuracy. In addition, we offer you free demo to have a try, so that you can know what the complete version is like. We have online and offline chat service, and the service staff possess the professional knowledge for NCP-AIO Exam Materials, if you have any questions, you can consult us.
NVIDIA AI Operations Sample Questions (Q30-Q35):
NEW QUESTION # 30
Describe a scenario where using MIG (Multi-lnstance GPU) on an NVIDIAAI 00 GPU within a Kubernetes cluster would be most beneficial. Explain why MIG is advantageous in that specific use case.
- A. Executing a computationally intensive scientific simulation that benefits from high GPU memory bandwidth.
- B. Hosting a large number of small, independent AI inference services, each with modest GPU requirements.
- C. Distributing a single large training job across multiple GPUs on different nodes.
- D. Running a virtual desktop infrastructure (VDI) environment where each user requires dedicated GPU resources.
- E. Running a single, large deep learning training job that requires the full resources of the A100 GPU.
Answer: B,D
Explanation:
The correct answers are B and D. MIG is most advantageous when you have many smaller workloads that can each benefit from a dedicated, isolated GPU instance. For inference services (B), MIG allows you to efficiently pack multiple services onto a single A100. And also for VDI use-case (D) where each user expects to have assigned dedicated GPU resources for graphics rendering, video encoding, or other GPU accelerated operations for their VM. For option A, a single large training job needs the entire GPU's resources and wouldn't benefit from partitioning. Options C and E are more about compute power/scale than isolation and efficient resource sharing.
NEW QUESTION # 31
An instance of NVIDIA Fabric Manager service is running on an HGX system with KVM. A System Administrator is troubleshooting NVLink partitioning.
By default, what is the GPU polling subsystem set to?
- A. Every 30 seconds
- B. Every 60 seconds
- C. Every 10 seconds
- D. Every 1 second
Answer: A
Explanation:
Comprehensive and Detailed Explanation From Exact Extract:
In NVIDIA AI infrastructure, theNVIDIA Fabric Managerservice is responsible for managing GPU fabric features such as NVLink partitioning on HGX systems. This service periodically polls the GPUs to monitor and manage NVLink states. By default, the GPU polling subsystem is set toevery 30 secondsto balance timely updates with system resource usage.
This polling interval allows the Fabric Manager to efficiently detect and respond to changes or issues in the NVLink fabric without excessive overhead or latency. It is a standard default setting unless specifically configured otherwise by system administrators.
This default behavior aligns with NVIDIA's system management guidelines for HGX platforms and is referenced in NVIDIA AI Operations materials concerning fabric management and troubleshooting of NVLink partitions.
NEW QUESTION # 32
A new researcher needs access to GPU resources but should not have permission to modify cluster settings or manage other users.
What role should you assign them in Run:ai?
- A. L1 Researcher
- B. Application Administrator
- C. Research Manager
- D. Department Administrator
Answer: A
NEW QUESTION # 33
A user reports slow performance when running a CUDA application within a Docker container. You suspect the container is not properly utilizing the GPU. How can you quickly verify that the container has access to the NVIDIA GPU?
- A. Inspect the Dockerfile to ensure that the 'nvidia/cuda' base image or appropriate NVIDIA drivers are installed.
- B. Execute 'docker inspect and look for the 'NVIDIA VISIBLE DEVICES environment variable.
- C. Check the Docker container logs for any NVIDIA-related error messages.
- D. Restart the Docker daemon.
- E. Run 'nvidia-smr inside the container. If it shows GPU information, the container has access.
Answer: B,C,E
Explanation:
Running 'nvidia-smr inside the container (A) is the quickest way to verify GPU access. Checking container logs (B) can reveal errors related to GPU initialization. Inspecting the container (D) for 'NVIDIA VISIBLE DEVICES' shows which GPUs are exposed to the container. Inspecting the Dockerfile (C) is useful for understanding the image's configuration, but it doesn't confirm runtime access. Restarting Docker (E) might resolve transient issues, but it's not a diagnostic step.
NEW QUESTION # 34
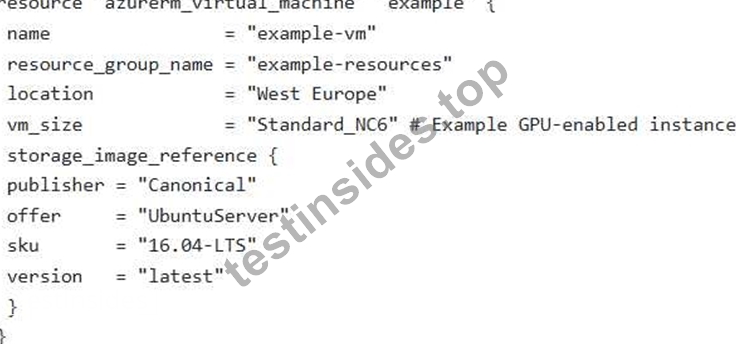
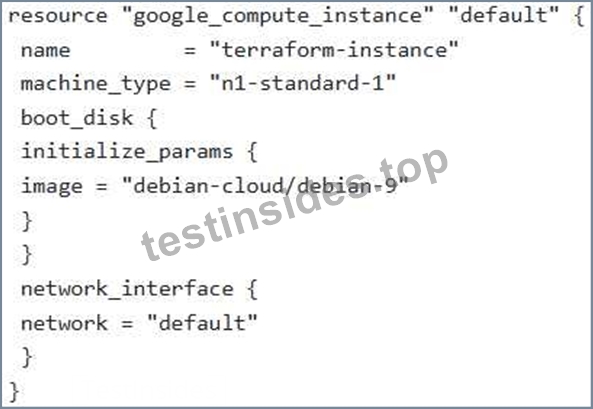
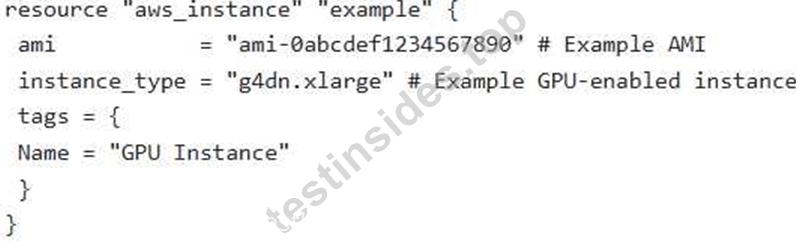
You are deploying a cloud VMI container using Terraform. How would you define a resource to provision an NVIDIA GPU-enabled instance on AWS?
- A.
- B.
- C. Terraform cannot be used to provision GPU-enabled instances.
- D.
- E. Use packer instead of Terraform.
Answer: D
Explanation:
Option A provides the correct Terraform configuration for provisioning a GPU-enabled instance on AWS. It uses the 'aws_instance' resource, specifies a GPU-enabled instance type (e.g., 'g4dn.xlarge'), and includes necessary tags. Other options are not valid or not correct syntax.
NEW QUESTION # 35
......
These NVIDIA NCP-AIO dumps are real, updated, and error-free. It provides you with the essential NVIDIA NCP-AIO exam knowledge that you need to prepare and pass the NVIDIA NCP-AIO certification test with high scores. You can easily use all these three NVIDIA NCP-AIO Exam Questions format. These formats are compatible with all devices, operating systems, and the latest browsers.
NCP-AIO Valid Dumps Ebook: https://www.testinsides.top/NCP-AIO-dumps-review.html
- 2026 Accurate Exam NCP-AIO Revision Plan | NCP-AIO 100% Free Valid Dumps Ebook 🎍 Copy URL ✔ www.practicevce.com ️✔️ open and search for ➤ NCP-AIO ⮘ to download for free 🐊Test NCP-AIO Simulator Online
- New NCP-AIO Exam Pattern 🕓 New NCP-AIO Test Fee 🐟 NCP-AIO Key Concepts 🏭 Easily obtain free download of ▛ NCP-AIO ▟ by searching on ➥ www.pdfvce.com 🡄 🎅Test NCP-AIO Simulator Online
- NVIDIA - Newest Exam NCP-AIO Revision Plan 🎳 Search for 【 NCP-AIO 】 on 「 www.vceengine.com 」 immediately to obtain a free download 🦰NCP-AIO Discount
- Top Exam NCP-AIO Revision Plan | Pass-Sure NCP-AIO Valid Dumps Ebook: NVIDIA AI Operations 100% Pass 😕 Open website ✔ www.pdfvce.com ️✔️ and search for ▶ NCP-AIO ◀ for free download 🎧NCP-AIO Test Dumps Demo
- 2026 Accurate Exam NCP-AIO Revision Plan | NCP-AIO 100% Free Valid Dumps Ebook 🏆 Download ⇛ NCP-AIO ⇚ for free by simply searching on ➽ www.examdiscuss.com 🢪 😶NCP-AIO Key Concepts
- Valid Study NCP-AIO Questions 🦲 Test NCP-AIO Cram Pdf 🧇 NCP-AIO Excellect Pass Rate 🦀 Open website { www.pdfvce.com } and search for ⏩ NCP-AIO ⏪ for free download 👓NCP-AIO Standard Answers
- NVIDIA - Newest Exam NCP-AIO Revision Plan 👿 Open ⇛ www.exam4labs.com ⇚ enter 【 NCP-AIO 】 and obtain a free download 💋NCP-AIO Exam Assessment
- NVIDIA - Newest Exam NCP-AIO Revision Plan 😅 Search on ( www.pdfvce.com ) for { NCP-AIO } to obtain exam materials for free download 🟦NCP-AIO Latest Exam Test
- 2026 High hit rate Exam NCP-AIO Revision Plan Help You Pass NCP-AIO Easily 🆖 Easily obtain free download of ⮆ NCP-AIO ⮄ by searching on ⏩ www.pass4test.com ⏪ 🔯Test NCP-AIO Cram Pdf
- NVIDIA AI Operations Exam Dumps Get Success With Minimal Effort 🍤 Search for { NCP-AIO } on 《 www.pdfvce.com 》 immediately to obtain a free download 🌍NCP-AIO Sample Exam
- 2026 High hit rate Exam NCP-AIO Revision Plan Help You Pass NCP-AIO Easily ⚫ Search for ➡ NCP-AIO ️⬅️ and obtain a free download on ⇛ www.exam4labs.com ⇚ ☣NCP-AIO Exam Assessment
- www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, myportal.utt.edu.tt, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes
P.S. Free & New NCP-AIO dumps are available on Google Drive shared by TestInsides: https://drive.google.com/open?id=1I7K4Du-HWtCtrtqtvpHDKXWjQ-ZnffI6