2026 Latest Lead1Pass DP-600 PDF Dumps and DP-600 Exam Engine Free Share: https://drive.google.com/open?id=1JDMyLer7G8k_p0U6NTEJgF2k2ZHytLcx
Under the dominance of knowledge-based economy, we should keep pace with the changeable world and renew our knowledge in pursuit of a decent job and higher standard of life. In this circumstance, possessing a DP-600 certification in your pocket can totally increase your competitive advantage in the labor market and make yourself distinguished from other job-seekers. Therefore our DP-600 Study Guide can help you with dedication to realize your dream. And only after studying with our DP-600 exam questions for 20 to 30 hours, you will be able to pass the DP-600 exam.
| Topic | Details |
|---|---|
| Topic 1 |
|
| Topic 2 |
|
| Topic 3 |
|
>> New DP-600 Test Discount <<
Our DP-600 practice dumps compiled by the most professional experts can offer you with high quality and accuracy practice materials for your success. Up to now, we have more than tens of thousands of customers around the world supporting our DP-600 Exam Questions. If you are unfamiliar with our DP-600 study materials, please download the free demos for your reference, and to some unlearned exam candidates, you can master necessities by our DP-600 training guide quickly.
NEW QUESTION # 22
You have a Microsoft Power B1 report and a semantic model that uses Direct Lake mode. From Power Si Desktop, you open Performance analyzer as shown in the following exhibit.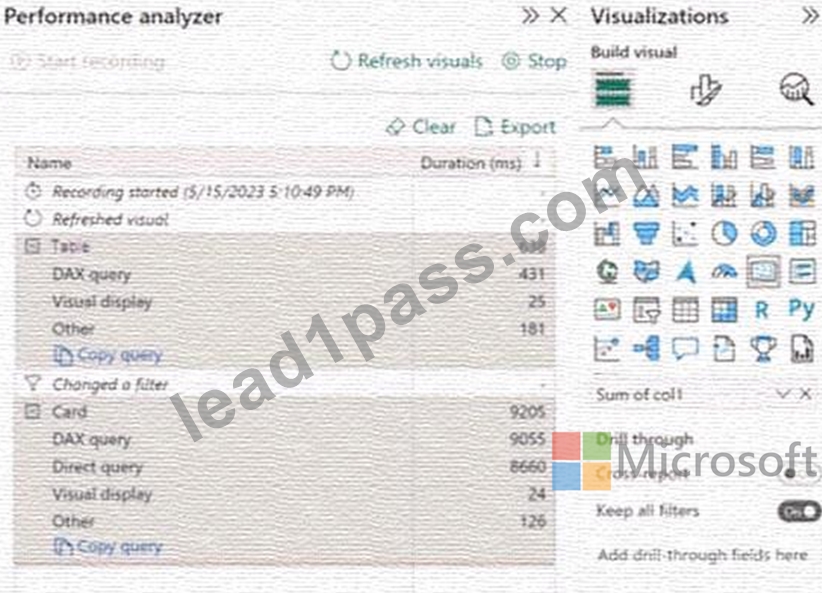
Use the drop-down menus to select the answer choice that completes each statement based on the information presented in the graphic. NOTE: Each correct selection is worth one point.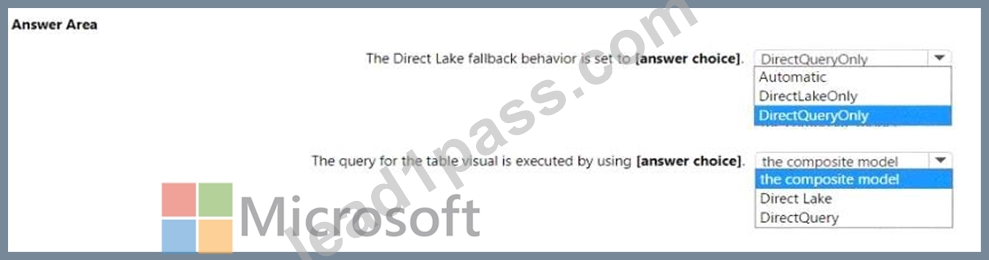
Answer:
Explanation: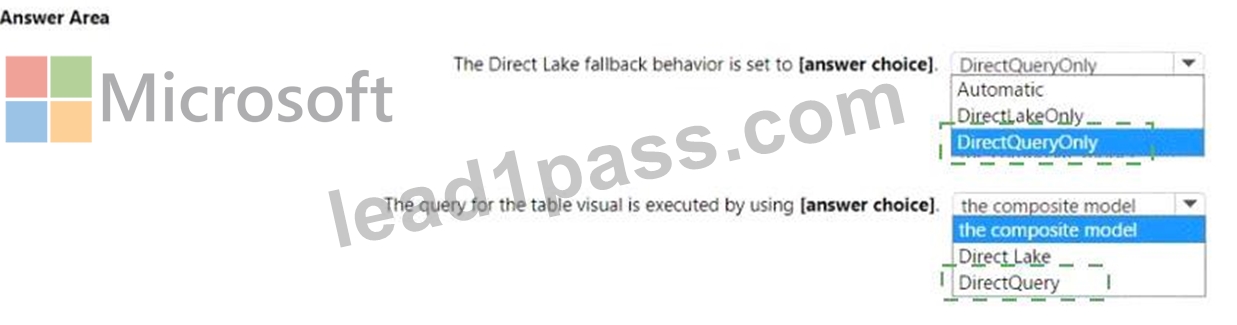
Explanation:
* The Direct Lake fallback behavior is set to: DirectQueryOnly
* The query for the table visual is executed by using: DirectQuery
In the context of Microsoft Power BI, when using DirectQuery in Direct Lake mode, there is no caching of data and all queries are sent directly to the underlying data source. The Performance Analyzer tool shows the time taken for different operations, and from the options provided, it indicates that DirectQuery mode is being used for the visuals, which is consistent with the Direct Lake setting. DirectQueryOnly as the fallback behavior ensures that only DirectQuery will be used without reverting to import mode.
NEW QUESTION # 23
Your company has a finance department.
You have a Fabric tenant, an Azure Storage account named storagel, and a Microsoft Entra group named Groupl. Groupl contains the users in the finance department.
You need to create a new workspace named Workspacel in the tenant. The solution must meet the following requirements:
* Ensure that the finance department users can create and edit items in Workspace"!.
* Ensure that Workspacel can securely access storagel to read and write data.
* Ensure that you are the only admin of Workspacel.
* Minimize administrative effort.
You create Workspacel.
Which two actions should you perform next? Each correct answer presents part of the solution. NOTE: Each correct selection is worth one point.
Answer: A,C
Explanation:
Finance department users can create and edit items in Workspace1 #
The correct role is Contributor.
To minimize effort, assign this role to the Microsoft Entra group (Group1) instead of assigning it to each user individually.
So answer A is correct, not B.
Workspace1 can securely access storagel (Azure Storage) to read and write data # To connect a Fabric workspace to external resources securely, you use a Workspace identity (a managed identity for the workspace).
This allows Fabric items to authenticate to Azure Storage without embedding credentials.
So answer D is correct.
You are the only admin of Workspace1 #
By default, the workspace creator (you) is the admin. You do not need to explicitly reassign the admin role to yourself (so C is unnecessary).
Minimize administrative effort #
Assigning Contributor role to the group (A) is minimal effort compared to assigning it individually to each user (B).
Final Answer:
A). Assign the Contributor role to Group1
D). Create a workspace identity
References:
Workspace roles in Microsoft Fabric
Workspace identity for secure data access
NEW QUESTION # 24
You have a Fabric warehouse that contains a table named Sales.Products. Sales.Products contains the following columns.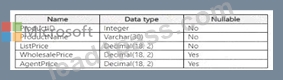
You need to write a T-SQL query that will return the following columns.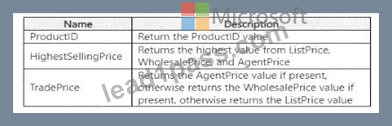
How should you complete the code? To answer, select the appropriate options in the answer area.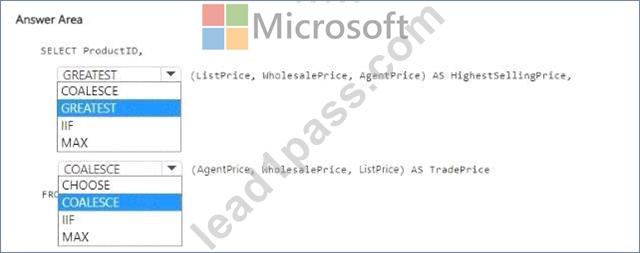
Answer:
Explanation: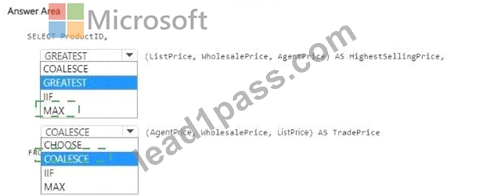
Explanation:
* For the HighestSellingPrice, you should use the GREATEST function to find the highest value from the given price columns. However, T-SQL does not have a GREATEST function as found in some other SQL dialects, so you would typically use a CASE statement or an IIF statement with nested MAX functions. Since neither of those are provided in the options, you should select MAX as a placeholder to indicate the function that would be used to find the highest value if combining multiple MAX functions or a similar logic was available.
* For the TradePrice, you should use the COALESCE function, which returns the first non-null value in a list. The COALESCE function is the correct choice as it will return AgentPrice if it's not null; if AgentPrice is null, it will check WholesalePrice, and if that is also null, it will return ListPrice.
The complete code with the correct SQL functions would look like this:
SELECT ProductID,
MAX(ListPrice, WholesalePrice, AgentPrice) AS HighestSellingPrice, -- MAX is used as a placeholder COALESCE(AgentPrice, WholesalePrice, ListPrice) AS TradePrice FROM Sales.Products Select MAX for HighestSellingPrice and COALESCE for TradePrice in the answer area.
NEW QUESTION # 25
You have an Amazon Web Services (AWS) subscription that contains an Amazon Simple Storage Service (Amazon S3) bucket named bucketl.
You have a Fabric tenant that contains a lakehouse named LH1.
In LH1, you plan to create a OneLake shortcut to bucketl.
You need to configure authentication for the connection.
Which two values should you provide? Each correct answer presents part of the solution.
NOTE: Each correct selection is worth one point.
Answer: A,D
Explanation:
When creating a OneLake shortcut to Amazon S3, authentication uses the standard AWS access key ID + secret access key pair.
SAS token is for Azure Storage, not AWS.
Certificate thumbprint is not used for S3.
Access ID is incorrect naming; the correct term is access key ID.
Correct answers: B and D.
Reference: Create shortcuts to Amazon S3 in OneLake
NEW QUESTION # 26
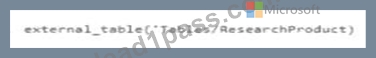
Which syntax should you use in a notebook to access the Research division data for Productlinel?



Answer: C
Explanation:
Comprehensive Detailed Explanation
The question asks: Which syntax should you use in a Fabric notebook to access the Research division data for Productline1?
Key Background from the Case
In Productline1ws, a lakehouse named Lakehouse1 is created.
In Lakehouse1, a shortcut is created to storage1, named ResearchProduct.
Storage1 contains the Research division data for Productline1 in Delta format.
Requirement: All data in lakehouses must be presented as managed tables in Lakehouse explorer.
Analyzing the Syntax Options
Option A:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
This syntax directly queries the ResearchProduct shortcut within Lakehouse1 using Spark SQL.
Since the shortcut points to Delta data, Spark can directly query it.
This is the correct way to retrieve Productline1 data from Lakehouse1.
Option B:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
This introduces an extra schema-like path (productline1) that is not part of the shortcut name.
Incorrect, because the shortcut was created as ResearchProduct inside Lakehouse1, not under another schema.
Option C:
external_table( ' Tables/ResearchProduct ' )
external_table is not the correct way to access a Lakehouse shortcut.
Shortcuts in Lakehouses appear as tables and can be queried using Spark SQL directly.
Option D:
spark.sql( " SELECT * FROM Lakehouse1.productline1.ResearchProduct " )
Same issue as Option B, includes a schema path that does not exist.
Correct Choice
Since the shortcut to ResearchProduct was created inside Lakehouse1, and Spark SQL can query it directly, the correct syntax is:
spark.sql( " SELECT * FROM Lakehouse1.ResearchProduct " )
That matches Option A.
References
Microsoft Fabric Lakehouse - Shortcuts
Query data in a lakehouse using Spark SQL
Delta format support in Microsoft Fabric
NEW QUESTION # 27
......
DP-600 practice materials can expedite your review process, inculcate your knowledge of the exam and last but not the least, speed up your pace of review dramatically. The finicky points can be solved effectively by using our DP-600 practice materials. Some practice materials keep droning on the useless points of knowledge. In contrast, being venerated for high quality and accuracy rate, our DP-600 practice materials received high reputation for their efficiency and accuracy rate originating from your interests, and the whole review process may cushier than you have imagined before.
Valid DP-600 Braindumps: https://www.lead1pass.com/Microsoft/DP-600-practice-exam-dumps.html
P.S. Free & New DP-600 dumps are available on Google Drive shared by Lead1Pass: https://drive.google.com/open?id=1JDMyLer7G8k_p0U6NTEJgF2k2ZHytLcx