BONUS!!! Download part of ActualtestPDF DP-600 dumps for free: https://drive.google.com/open?id=1KMSZ7NgEMcc4jjNQz572u-K9ax6IH0wa
If you want to be a part of a great company, such as DP-600, preparing and taking the exam with DP-600 study guide will be your best choice, because there have been more and more big companies to pay real attention to these people who have passed the DP-600 Exam and have got the related certification in the past years. It is a generally accepted fact that the DP-600 exam has attracted more and more attention and become widely acceptable in the past years.
| Section | Objectives |
|---|---|
| Real-time analytics | - Streaming and event processing
|
| Get data into Microsoft Fabric | - Data ingestion and integration
|
| Manage and secure Microsoft Fabric | - Governance and administration
|
| Implement analytics solutions | - Data warehousing and modeling
|
| Implement data engineering solutions | - Lakehouse architecture
|
>> Reliable DP-600 Exam Registration <<
It doesn't matter if it is the first time you participate in the c online training or if you prepare this exam for some time. It is a simple and smart way to prepare the DP-600 practice exam with our latest learning materials. There are free demo and valid questions and answers in our DP-600 Pass Guide. If you spend some time and pay attention to DP-600 test answers, there is no reason to not pass test and get the certification.
NEW QUESTION # 161
You have a Fabric tenant that contains a new semantic model in OneLake.
You use a Fabric notebook to read the data into a Spark DataFrame.
You need to evaluate the data to calculate the min, max, mean, and standard deviation values for all the string and numeric columns.
Solution: You use the following PySpark expression:
df.show()
Does this meet the goal?
Answer: B
Explanation:
The df.show() method also does not meet the goal. It is used to show the contents of the DataFrame, not to compute statistical functions. Reference = The usage of the show() function is documented in the PySpark API documentation.
NEW QUESTION # 162
You are analyzing customer purchases in a Fabric notebook by using PySpark.
You have the following DataFrames:
- transactions: Contains five columns named transaction_id,
customer_id, product_id, amount, and date and has 10 million rows, with each row representing a transaction.
- customers: Contains customer details in 1,000 rows and three columns
named customer_id, name, and country.
You need to join the DataFrames on the customer_id column. The solution must minimize data shuffling.
You write the following code.
from pyspark.sql import functions as F
results =
Which code should you run to populate the results DataFrame?
Answer: B
Explanation:
https://sparkbyexamples.com/spark/broadcast-join-in-spark/"
NEW QUESTION # 163
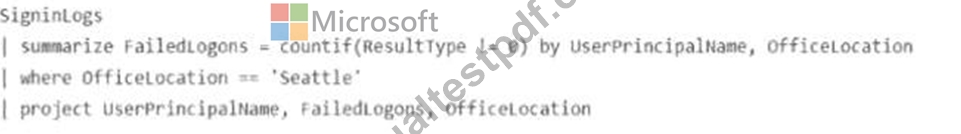
You have the following KQL query named Query1.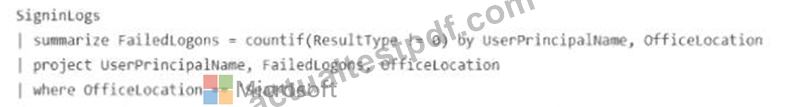
You need to improve the performance of Query1.
The solution must minimize resource use How should you restructure Query1?
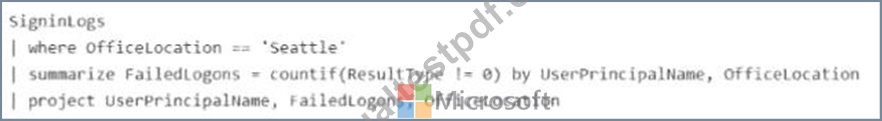
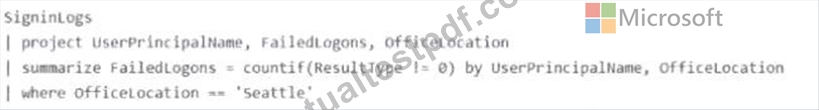
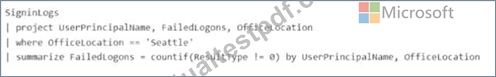
Answer: A
NEW QUESTION # 164
You have a Fabric tenant that contains a workspace named Workspace1. Workspace1 contains a lakehouse named Lakehouse1 and a warehouse named Warehouse1.
You need to create a new table in Warehouse1 named POSCustomers by querying the customer table in Lakehouse1.
How should you complete the T-SQL statement? To answer, select the appropriate options in the answer area.
NOTE: Each correct selection is worth one point.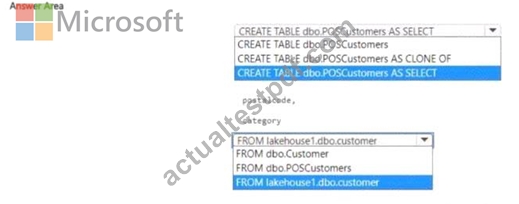
Answer:
Explanation: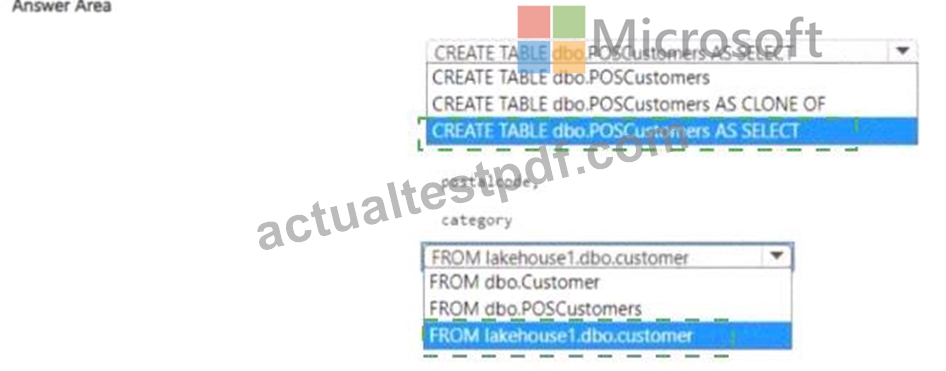
Explanation: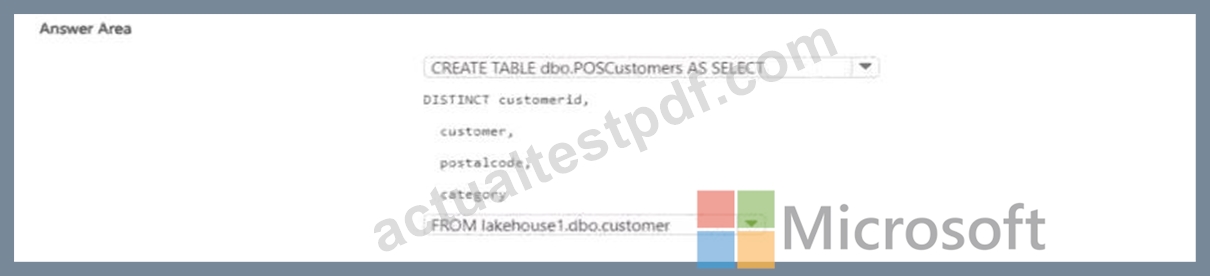
Step 1 - Creating the new table from a query
To create a table in a SQL warehouse using a query, the correct syntax is:
CREATE TABLE < table_name > AS SELECT ...
So we must select:
CREATE TABLE dbo.POSCustomers AS SELECT
Step 2 - Selecting the source table
Since the data source is the Lakehouse1 table Customer , the fully qualified name is:
lakehouse1.dbo.Customer
CREATE TABLE dbo.POSCustomers AS SELECT
postalcode,
category
FROM lakehouse1.dbo.Customer;
References:
CREATE TABLE AS SELECT (CTAS) in Fabric Warehouse
Fabric Lakehouse and Warehouse interoperability
NEW QUESTION # 165
You have a Fabric tenant that contains a lakehouse.
You plan to query sales data files by using the SQL endpoint. The files will be in an Amazon Simple Storage Service (Amazon S3) storage bucket.
You need to recommend which file format to use and where to create a shortcut.
Which two actions should you include in the recommendation? Each correct answer presents part of the solution.
NOTE: Each correct answer is worth one point.
Answer: A,B
NEW QUESTION # 166
......
It is our aspiration to help candidates get certification in their first try with our latest DP-600 exam prep and valid pass guide. We know the difficulty of DP-600 real exam so our IT experts written the best quality exam answers for our customers who didn't get good result. By using our DP-600 pass review, you will grasp the overall key points of the test content and solve the difficult questions easier.
DP-600 Test Cram: https://www.actualtestpdf.com/Microsoft/DP-600-practice-exam-dumps.html
BONUS!!! Download part of ActualtestPDF DP-600 dumps for free: https://drive.google.com/open?id=1KMSZ7NgEMcc4jjNQz572u-K9ax6IH0wa