BTW, DOWNLOAD part of Dumpexams Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1nRYrn8uIkla6_Pb44XXJvpMGQjM5wNQt
What you can get from the Databricks-Certified-Professional-Data-Engineer certification? Of course, you can get a lot of opportunities to enter to the bigger companies. After you get more opportunities, you can make full use of your talents. You will also get more salary, and then you can provide a better life for yourself and your family. Databricks-Certified-Professional-Data-Engineer Exam Preparation is really good helper on your life path. Quickly purchase Databricks-Certified-Professional-Data-Engineer study guide and go to the top of your life!
| Section | Weight | Objectives |
|---|---|---|
| Data Sharing and Federation | 5% | - Unity Catalog data sharing - Cross-workspace and cross-cloud access |
| Ensuring Data Security and Compliance | 10% | - Access control and permissions - Data encryption and masking - Compliance standards implementation |
| Data Modelling | 6% | - Schema design and management - Delta Lake table design - Medallion Architecture implementation |
| Data Ingestion & Acquisition | 7% | - Auto Loader and streaming ingestion - Connecting to diverse data sources - Schema inference and evolution |
| Debugging and Deploying | 10% | - CI/CD and DevOps practices - Deployment using bundles, CLI, and APIs - Troubleshooting pipelines and errors |
| Monitoring and Alerting | 10% | - Pipeline observability and logging - Setting up alerts and notifications - Performance and health monitoring |
| Data Transformation, Cleansing, and Quality | 10% | - Data validation and quality checks - Handling missing or inconsistent data - Standardization and normalization |
| Developing Code for Data Processing using Python and SQL | 22% | - Integration with Databricks APIs and tools - Data transformation and aggregation - Batch and incremental processing logic |
| Cost & Performance Optimisation | 13% | - Storage optimization (partitioning, Z-order, indexing) - Cluster configuration and scaling - Query optimization and caching |
| Data Governance | 7% | - Data lineage and metadata tracking - Policy enforcement - Unity Catalog management |
>> Databricks-Certified-Professional-Data-Engineer PDF Question <<
Similarly, Dumpexams provides you 1 year free updates after your purchase of Databricks Databricks-Certified-Professional-Data-Engineer practice tests. These updates will help you prepare well if the content of the exam changes. The Databricks Certified Professional Data Engineer Exam (Databricks-Certified-Professional-Data-Engineer) demo of the practice exams is totally free and it helps you in examining the Databricks-Certified-Professional-Data-Engineer study materials.
NEW QUESTION # 37
A Delta Lake table was created with the below query: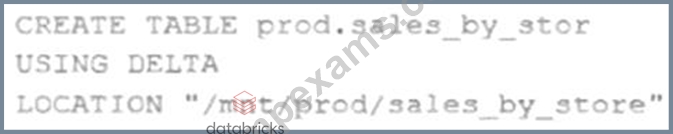
Realizing that the original query had a typographical error, the below code was executed:
ALTER TABLE prod.sales_by_stor RENAME TO prod.sales_by_store
Which result will occur after running the second command?
Answer: C
Explanation:
The query uses the CREATE TABLE USING DELTA syntax to create a Delta Lake table from an existing Parquet file stored in DBFS. The query also uses the LOCATION keyword to specify the path to the Parquet file as /mnt/finance_eda_bucket/tx_sales.parquet. By using the LOCATION keyword, the query creates an external table, which is a table that is stored outside of the default warehouse directory and whose metadata is not managed by Databricks. An external table can be created from an existing directory in a cloud storage system, such as DBFS or S3, that contains data files in a supported format, such as Parquet or CSV.
The result that will occur after running the second command is that the table reference in the metastore is updated and no data is changed. The metastore is a service that stores metadata about tables, such as their schema, location, properties, and partitions. The metastore allows users to access tables using SQL commands or Spark APIs without knowing their physical location or format. When renaming an external table using the ALTER TABLE RENAME TO command, only the table reference in the metastore is updated with the new name; no data files or directories are moved or changed in the storage system. The table will still point to the same location and use the same format as before. However, if renaming a managed table, which is a table whose metadata and data are both managed by Databricks, both the table reference in the metastore and the data files in the default warehouse directory are moved and renamed accordingly. Verified References:
[Databricks Certified Data Engineer Professional], under "Delta Lake" section; Databricks Documentation, under "ALTER TABLE RENAME TO" section; Databricks Documentation, under "Metastore" section; Databricks Documentation, under "Managed and external tables" section.
NEW QUESTION # 38
You were asked to identify number of times a temperature sensor exceed threshold temperature (100.00) by each device, each row contains 5 readings collected every 5 minutes, fill in the blank with the appropriate functions.
Schema: deviceId INT, deviceTemp ARRAY<double>, dateTimeCollected TIMESTAMP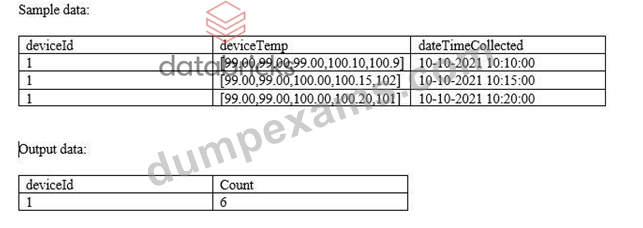
SELECT deviceId, __ (__ (__(deviceTemp], i -> i > 100.00)))
FROM devices
GROUP BY deviceId
Answer: E
Explanation:
Explanation
FILER function can be used to filter an array based on an expression
SIZE function can be used to get size of an array
SUM is used to calculate to total by device
Diagram Description automatically generated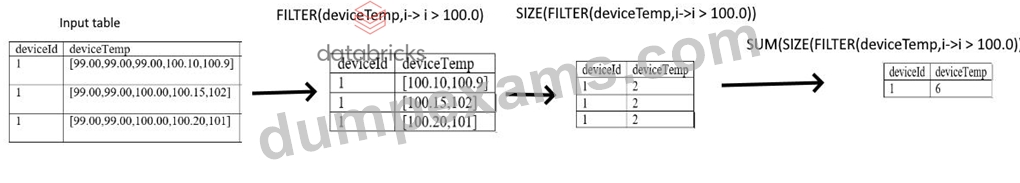
NEW QUESTION # 39
A data pipeline uses Structured Streaming to ingest data from kafka to Delta Lake. Data is being stored in a bronze table, and includes the Kafka_generated timesamp, key, and value. Three months after the pipeline is deployed the data engineering team has noticed some latency issued during certain times of the day.
A senior data engineer updates the Delta Table's schema and ingestion logic to include the current timestamp (as recoded by Apache Spark) as well the Kafka topic and partition. The team plans to use the additional metadata fields to diagnose the transient processing delays:
Which limitation will the team face while diagnosing this problem?
Answer: A
Explanation:
When adding new fields to a Delta table's schema, these fields will not be retrospectively applied to historical records that were ingested before the schema change. Consequently, while the team can use the new metadata fields to investigate transient processing delays moving forward, they will be unable to apply this diagnostic approach to past data that lacks these fields.
:
Databricks documentation on Delta Lake schema management: https://docs.databricks.com/delta/delta-batch.
html#schema-management
NEW QUESTION # 40
Data engineering team is required to share the data with Data science team and both the teams are using different workspaces in the same organizationwhich of the following techniques can be used to simplify sharing data across?
*Please note the question is asking how data is shared within an organization across multiple workspaces.
Answer: E
Explanation:
Explanation
The answer is the Unity catalog.
Diagram Description automatically generated
Unity Catalog works at the Account level, it has the ability to create a meta store and attach that meta store to many workspaces see the below diagram to understand how Unity Catalog Works, as you can see a metastore can now be shared with both workspaces using Unity Catalog, prior to Unity Catalog the options was to use single cloud object storage manually mount in the second databricks workspace, and you can see here Unity Catalog really simplifies that.
Diagram Description automatically generated with medium confidence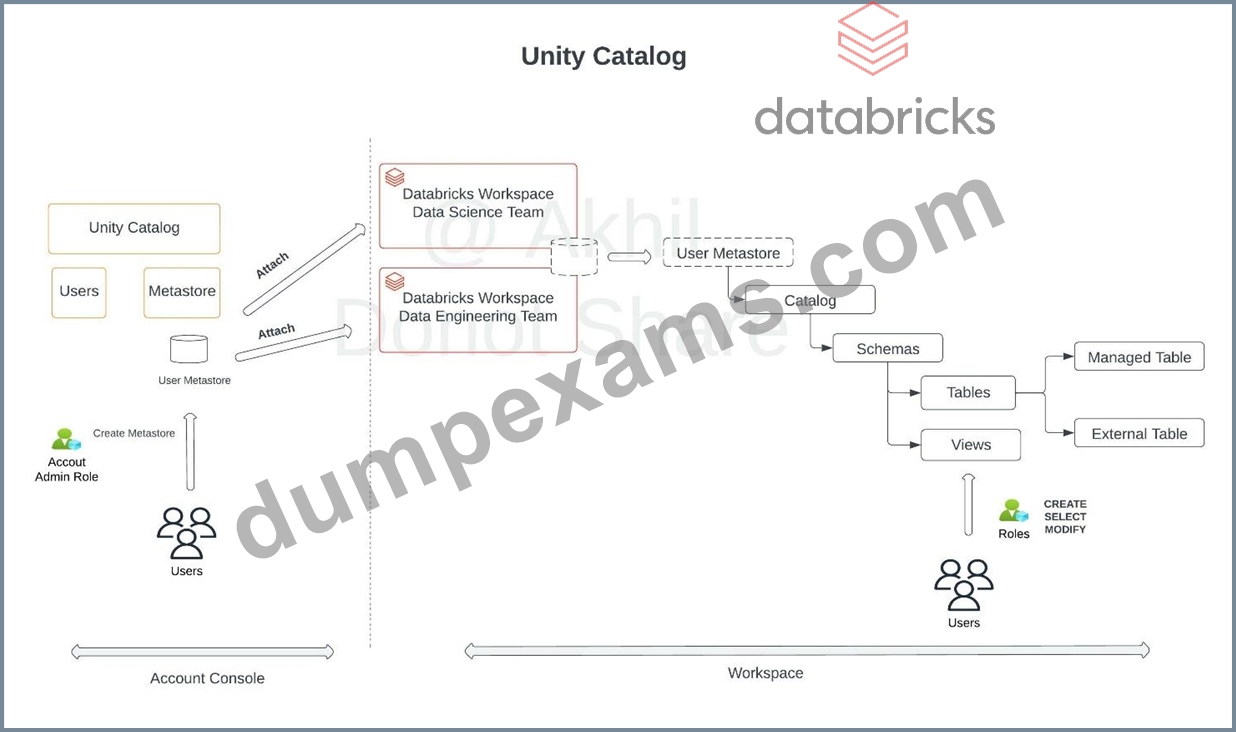
sorry for the inconvenience watermark was added because other people on Udemy are copying my questions and images.
duct features
https://databricks.com/product/unity-catalog
NEW QUESTION # 41
Which statement describes the correct use of pyspark.sql.functions.broadcast?
Answer: D
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
Thepyspark.sql.functions.broadcastfunction in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation.
In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
References:
* Databricks Documentation on Broadcast Joins: Databricks Broadcast Join Guide
* PySpark API Reference: pyspark.sql.functions.broadcast
NEW QUESTION # 42
......
We can promise that you would like to welcome this opportunity to kill two birds with one stone. If you choose our Databricks-Certified-Professional-Data-Engineer test questions as your study tool, you will be glad to study for your exam and develop self-discipline, our Databricks-Certified-Professional-Data-Engineer latest question adopt diversified teaching methods, and we can sure that you will have passion to learn by our Databricks-Certified-Professional-Data-Engineer learning braindump. We believe that our Databricks-Certified-Professional-Data-Engineer exam questions will help you successfully pass your Databricks-Certified-Professional-Data-Engineer exam and hope you will like our Databricks-Certified-Professional-Data-Engineer practice engine.
Databricks-Certified-Professional-Data-Engineer Detailed Study Plan: https://www.dumpexams.com/Databricks-Certified-Professional-Data-Engineer-real-answers.html
BTW, DOWNLOAD part of Dumpexams Databricks-Certified-Professional-Data-Engineer dumps from Cloud Storage: https://drive.google.com/open?id=1nRYrn8uIkla6_Pb44XXJvpMGQjM5wNQt