
BONUS!!! MogiExam Data-Engineer-Associateダンプの一部を無料でダウンロード:https://drive.google.com/open?id=1jlnBIznjX0ZBShbhRS8zi3baktPqp_6R
弊社のIT業で経験豊富な専門家たちが正確で、合理的なAmazon Data-Engineer-Associate認証問題集を作り上げました。 弊社の勉強の商品を選んで、多くの時間とエネルギーを節約こともできます。
| Section | Weight | Objectives |
|---|---|---|
| Topic 1: Data Store Management | 26% | - Optimize storage performance and cost - Manage data lifecycle and storage tiers - Design and implement data storage solutions
|
| Topic 2: Data Operations and Support | 22% | - Ensure reliability and scalability - Monitor and troubleshoot data pipelines
- Backup, restore, and disaster recovery |
| Topic 3: Data Ingestion and Transformation | 34% | - Implement data quality and validation - Transform and enrich data
|
| Topic 4: Data Security and Governance | 18% | - Enforce compliance and data governance
- Implement access control and authentication
|
>> Amazon Data-Engineer-Associate復習テキスト <<
MogiExamは客様の要求を満たせていい評判をうけいたします。たくさんのひとは弊社の商品を使って、試験に順調に合格しました。そして、かれたちがリピーターになりました。MogiExamが提供したAmazonのData-Engineer-Associate試験問題と解答が真実の試験の練習問題と解答は最高の相似性があり、一年の無料オンラインの更新のサービスがあり、100%のパス率を保証して、もし試験に合格しないと、弊社は全額で返金いたします。
質問 # 28
A company needs to set up a data catalog and metadata management for data sources that run in the AWS Cloud. The company will use the data catalog to maintain the metadata of all the objects that are in a set of data stores. The data stores include structured sources such as Amazon RDS and Amazon Redshift. The data stores also include semistructured sources such as JSON files and .xml files that are stored in Amazon S3.
The company needs a solution that will update the data catalog on a regular basis. The solution also must detect changes to the source metadata.
Which solution will meet these requirements with the LEAST operational overhead?
正解:C
解説:
This solution will meet the requirements with the least operational overhead because it uses the AWS Glue Data Catalog as the central metadata repository for data sources that run in the AWS Cloud. The AWS Glue Data Catalog is a fully managed service that provides a unified view of your data assets across AWS and on-premises data sources. It stores the metadata of your data in tables, partitions, and columns, and enables you to access and query your data using various AWS services, such as Amazon Athena, Amazon EMR, and Amazon Redshift Spectrum. You can use AWS Glue crawlers to connect to multiple data stores, such as Amazon RDS, Amazon Redshift, and Amazon S3, and to update the Data Catalog with metadata changes.
AWS Glue crawlers can automatically discover the schema and partition structure of your data, and create or update the corresponding tables in the Data Catalog. You can schedule the crawlers to run periodically to update the metadata catalog, and configure them to detect changes to the source metadata, such as new columns, tables, or partitions12.
The other options are not optimal for the following reasons:
A: Use Amazon Aurora as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the Aurora data catalog. Schedule the Lambda functions to run periodically. This option is not recommended, as it would require more operational overhead to create and manage an Amazon Aurora database as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
C: Use Amazon DynamoDB as the data catalog. Create AWS Lambda functions that will connect to the data catalog. Configure the Lambda functions to gather the metadata information from multiple sources and to update the DynamoDB data catalog. Schedule the Lambda functions to run periodically. This option is also not recommended, as it would require more operational overhead to create and manage an Amazon DynamoDB table as the data catalog, and to write and maintain AWS Lambda functions to gather and update the metadata information from multiple sources. Moreover, this option would not leverage the benefits of the AWS Glue Data Catalog, such as data cataloging, data transformation, and data governance.
D: Use the AWS Glue Data Catalog as the central metadata repository. Extract the schema for Amazon RDS and Amazon Redshift sources, and build the Data Catalog. Use AWS Glue crawlers for data that is in Amazon S3 to infer the schema and to automatically update the Data Catalog. This option is not optimal, as it would require more manual effort to extract the schema for Amazon RDS and Amazon Redshift sources, and to build the Data Catalog. This option would not take advantage of the AWS Glue crawlers' ability to automatically discover the schema and partition structure of your data from various data sources, and to create or update the corresponding tables in the Data Catalog.
References:
1: AWS Glue Data Catalog
2: AWS Glue Crawlers
3: Amazon Aurora
4: AWS Lambda
5: Amazon DynamoDB
質問 # 29
The company stores a large volume of customer records in Amazon S3. To comply with regulations, the company must be able to access new customer records immediately for the first 30 days after the records are created. The company accesses records that are older than 30 days infrequently.
The company needs to cost-optimize its Amazon S3 storage.
Which solution will meet these requirements MOST cost-effectively?
正解:D
解説:
The most cost-effective solution in this case is to apply a lifecycle policy to transition records to Amazon S3 Standard-IA storage after 30 days. Here's why:
Amazon S3 Lifecycle Policies: Amazon S3 offers lifecycle policies that allow you to automatically transition objects between different storage classes to optimize costs. For data that is frequently accessed in the first 30 days and infrequently accessed after that, transitioning from the S3 Standard storage class to S3 Standard- Infrequent Access (S3 Standard-IA) after 30 days makes the most sense. S3 Standard-IA is designed for data that is accessed less frequently but still needs to be retained, offering lower storage costs than S3 Standard with a retrieval cost for access.
Cost Optimization: S3 Standard-IA offers a lower price per GB than S3 Standard. Since the data will be accessed infrequently after 30 days, using S3 Standard-IA will lower storage costs while still allowing for immediate retrieval when necessary.
Compliance with Regulations: Since the records need to be immediately accessible for the first 30 days, the use of S3 Standard for that period ensures compliance with regulatory requirements. After 30 days, transitioning to S3 Standard-IA continues to meet access requirements for infrequent access while reducing storage costs.
Alternatives Considered:
Option B (S3 Intelligent-Tiering): While S3 Intelligent-Tiering automatically moves data between access tiers based on access patterns, it incurs a small monthly monitoring and automation charge per object. It could be a viable option, but transitioning data to S3 Standard-IA directly would be more cost-effective since the pattern of access is well-known (frequent for 30 days, infrequent thereafter).
Option C (S3 Glacier Deep Archive): Glacier Deep Archive is the lowest-cost storage class, but it is not suitable in this case because the data needs to be accessed immediately within 30 days and on an infrequent basis thereafter. Glacier Deep Archive requires hours for data retrieval, which is not acceptable for infrequent access needs.
Option D (S3 Standard-IA for all records): Using S3 Standard-IA for all records would result in higher costs for the first 30 days, as the data is frequently accessed. S3 Standard-IA incurs retrieval charges, making it less suitable for frequently accessed data.
Amazon S3 Lifecycle Policies
S3 Storage Classes
Cost Management and Data Optimization Using Lifecycle Policies
AWS Data Engineering Documentation
質問 # 30
A company needs to store semi-structured transactional data in a serverless database.
The application writes data infrequently but reads it frequently, with millisecond retrieval required.
正解:D
解説:
Amazon DynamoDB is a serverless, low-latency, NoSQL database ideal for semi-structured data.
Adding DynamoDB Accelerator (DAX) provides microsecond response times for read-heavy workloads.
"For applications requiring millisecond or sub-millisecond reads with serverless operation, use DynamoDB with DAX caching."
- Ace the AWS Certified Data Engineer - Associate Certification - version 2 - apple.pdf
質問 # 31
A data engineer uses Amazon Redshift to run resource-intensive analytics processes once every month. Every month, the data engineer creates a new Redshift provisioned cluster. The data engineer deletes the Redshift provisioned cluster after the analytics processes are complete every month. Before the data engineer deletes the cluster each month, the data engineer unloads backup data from the cluster to an Amazon S3 bucket.
The data engineer needs a solution to run the monthly analytics processes that does not require the data engineer to manage the infrastructure manually.
Which solution will meet these requirements with the LEAST operational overhead?
正解:C
解説:
Amazon Redshift Serverless is a new feature of Amazon Redshift that enables you to run SQL queries on data in Amazon S3 without provisioning or managing any clusters. You can use Amazon Redshift Serverless to automatically process the analytics workload, as it scales up and down the compute resources based on the query demand, and charges you only for the resources consumed. This solution will meet the requirements with the least operational overhead, as it does not require the data engineer to create, delete, pause, or resume any Redshift clusters, or to manage any infrastructure manually. You can use the Amazon Redshift Data API to run queries from the AWS CLI, AWS SDK, or AWS Lambda functions12.
The other options are not optimal for the following reasons:
* A. Use Amazon Step Functions to pause the Redshift cluster when the analytics processes are complete and to resume the cluster to run new processes every month. This option is not recommended, as it would still require the data engineer to create and delete a new Redshift provisioned cluster every month, which can incur additional costs and time. Moreover, this option would require the data engineer to use Amazon Step Functions to orchestrate the workflow of pausing and resuming the cluster, which can add complexity and overhead.
* C. Use the AWS CLI to automatically process the analytics workload. This option is vague and does not specify how the AWS CLI is used to process the analytics workload. The AWS CLI can be used to run queries on data in Amazon S3 using Amazon Redshift Serverless, Amazon Athena, or Amazon EMR, but each of these services has different features and benefits. Moreover, this option does not address the requirement of not managing the infrastructure manually, as the data engineer may still need to provision and configure some resources, such as Amazon EMR clusters or Amazon Athena workgroups.
* D. Use AWS CloudFormation templates to automatically process the analytics workload. This option is also vague and does not specify how AWS CloudFormation templates are used to process the analytics workload. AWS CloudFormation is a service that lets you model and provision AWS resources using templates. You can use AWS CloudFormation templates to create and delete a Redshift provisioned cluster every month, or to create and configure other AWS resources, such as Amazon EMR, Amazon Athena, or Amazon Redshift Serverless. However, this option does not address the requirement of not managing the infrastructure manually, as the data engineer may still need to write and maintain the AWS CloudFormation templates, and to monitor the status and performance of the resources.
References:
* 1: Amazon Redshift Serverless
* 2: Amazon Redshift Data API
* : Amazon Step Functions
* : AWS CLI
* : AWS CloudFormation
質問 # 32
A data engineer maintains a materialized view that is based on an Amazon Redshift database. The view has a column named load_date that stores the date when each row was loaded.
The data engineer needs to reclaim database storage space by deleting all the rows from the materialized view.
Which command will reclaim the MOST database storage space?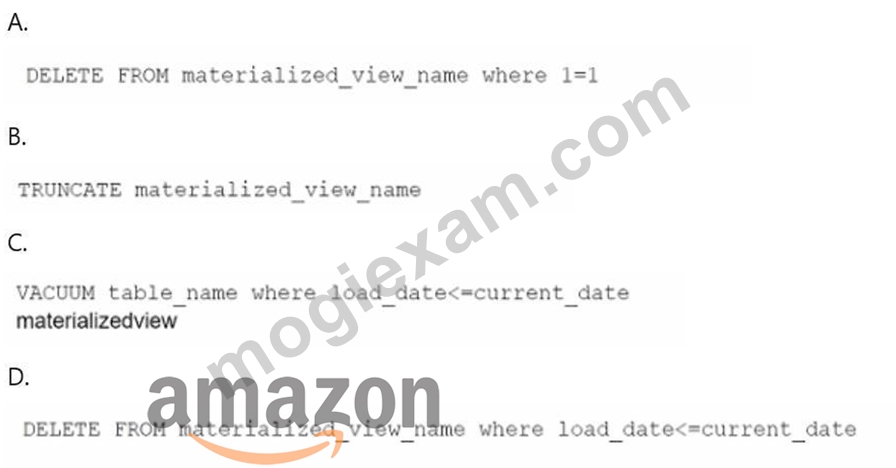
正解:B
解説:
To reclaim the most storage space from a materialized view in Amazon Redshift, you should use a DELETE operation that removes all rows from the view. The most efficient way to remove all rows is to use a condition that always evaluates to true, such as 1=1. This will delete all rows without needing to evaluate each row individually based on specific column values like load_date.
Option A: DELETE FROM materialized_view_name WHERE 1=1;This statement will delete all rows in the materialized view and free up the space. Since materialized views in Redshift store precomputed data, performing a DELETE operation will remove all stored rows.
Other options either involve inappropriate SQL statements (e.g., VACUUM in option C is used for reclaiming storage space in tables, not materialized views), or they don't remove data effectively in the context of a materialized view (e.g., TRUNCATE cannot be used directly on a materialized view).
References:
Amazon Redshift Materialized Views Documentation
Deleting Data from Redshift
質問 # 33
......
Data-Engineer-Associateの学習教材で20〜30時間準備したと主張することができます。Data-Engineer-Associate試験に簡単に合格して、期待されるスコアを取得できます。 またAmazon、Data-Engineer-Associate試験問題の無料デモを提供しており、Data-Engineer-Associateトレーニング資料の有効性と正確性を確認できます。MogiExam やって来てみてください! Data-Engineer-Associateトレーニング資料の高い精度に驚かれることでしょう。 そして、Data-Engineer-Associate練習問題集の高い合格率は99%から100%なので、AWS Certified Data Engineer - Associate (DEA-C01)試験に簡単に合格します。
Data-Engineer-Associate試験問題集: https://www.mogiexam.com/Data-Engineer-Associate-exam.html
P.S.MogiExamがGoogle Driveで共有している無料の2026 Amazon Data-Engineer-Associateダンプ:https://drive.google.com/open?id=1jlnBIznjX0ZBShbhRS8zi3baktPqp_6R