No Internet? No Problem! Prepare For Databricks Certified-Data-Engineer-Professional Exam Offline

If you can have the certification, you can enter the company you like as well as improve your salary. Certified-Data-Engineer-Professional training materials of us can offer you such opportunity, since we have a professional team to compile and verify, therefore Certified-Data-Engineer-Professional exam materials are high quality. You can pass the exam just one time. In addition, Certified-Data-Engineer-Professional Exam Dumps contain both questions and answers, so that you can have a quick check after practicing. We offer you free update for one year, and the update version for Certified-Data-Engineer-Professional exam materials will be sent to your email address automatically.
| Section | Objectives |
|---|
| Topic 1: Developing Code for Data Processing using Python and SQL | - Building and Testing an ETL Pipeline with Lakeflow Declarative Pipelines, SQL, and Apache Spark
- 1. Create pipeline components using control flow operators such as if/else and foreach
- 2. Choose appropriate configurations for environments, dependencies, high-memory notebook tasks, and retry behavior
- 3. Use APPLY CHANGES APIs to simplify CDC in Lakeflow Declarative Pipelines
- 4. Develop unit and integration tests using assertDataFrameEqual, assertSchemaEqual, DataFrame.transform, testing frameworks, and debugging tools
- 5. Compare Spark Structured Streaming and Lakeflow Declarative Pipelines to determine the optimal approach for scalable ETL pipelines
- 6. Explain the advantages and disadvantages of streaming tables compared to materialized views
- 7. Build and manage reliable, production-ready batch and streaming data pipelines using Lakeflow Declarative Pipelines and Auto Loader
- 8. Create and automate ETL workloads using Jobs through the UI, APIs, or CLI
- Using Python and Tools for Development
- 1. Develop User-Defined Functions using Pandas/Python UDF
- 2. Design and implement a scalable Python project structure optimized for Databricks Asset Bundles, enabling modular development, deployment automation, and CI/CD integration
- 3. Manage and troubleshoot external third-party library installations and dependencies, including PyPI packages, local wheels, and source archives
|
| Topic 2: Debugging and Deploying | - Debugging and Troubleshooting
- 1. Use Lakeflow Declarative Pipelines event logs and Spark UI to debug Lakeflow Declarative Pipelines and Spark pipelines
- 2. Analyze errors and remediate failed job runs using job repairs and parameter overrides
- 3. Identify diagnostic information using Spark UI, cluster logs, system tables, and query profiles to troubleshoot errors
- Deploying CI/CD
- 1. Build and deploy Databricks resources using Databricks Asset Bundles
- 2. Configure and integrate Git-based CI/CD workflows using Databricks Git folders for notebook and code deployment
|
| Topic 3: Data Governance | - Govern enterprise data
- 1. Demonstrate understanding of the Unity Catalog permission inheritance model
- 2. Create and add descriptions and metadata to enterprise data to improve discoverability
|
| Topic 4: Ensuring Data Security and Compliance | - Applying Data Security Mechanisms
- 1. Use ACLs to secure workspace objects and enforce the principle of least privilege
- 2. Apply anonymization and pseudonymization methods including hashing, tokenization, suppression, and generalization
- 3. Use row filters and column masks to protect sensitive table data
- Ensuring Compliance
- 1. Develop data purging solutions that comply with data retention policies
- 2. Implement compliant batch and streaming pipelines that detect and mask PII
|
| Topic 5: Data Sharing and Federation | - Share and federate data
- 1. Configure Lakehouse Federation with appropriate governance across supported source systems
- 2. Demonstrate secure Delta Sharing between Databricks deployments using Databricks-to-Databricks sharing or with external platforms using the open sharing protocol
- 3. Use Delta Sharing to share live data from the Lakehouse with any computing platform
|
| Topic 6: Data Transformation, Cleansing, and Quality | - Transform and validate data
- 1. Write efficient Spark SQL and PySpark code for advanced transformations including window functions, joins, and aggregations
- 2. Develop a quarantining process for bad data with Lakeflow Declarative Pipelines or Auto Loader in classic jobs
|
| Topic 7: Cost & Performance Optimization | - Optimize cost and performance
- 1. Apply Change Data Feed to address streaming table limitations and improve latency
- 2. Understand Databricks query optimization techniques for large datasets, including data skipping and file pruning
- 3. Use query profiling to identify bottlenecks such as inefficient joins and data shuffling
- 4. Understand Delta optimization techniques such as deletion vectors and liquid clustering
- 5. Understand how and why Unity Catalog managed tables reduce operational overhead and maintenance burden
|
| Topic 8: Monitoring and Alerting | - Monitoring
- 1. Use Databricks REST APIs and Databricks CLI to monitor jobs and pipelines
- 2. Use Lakeflow Declarative Pipelines event logs to monitor pipelines
- 3. Use system tables for observability of resource utilization, cost, auditing, and workloads
- 4. Use Query Profile and Spark UI to monitor workloads
- Alerting
- 1. Use the Workflows UI and Jobs API to configure notifications for job status and performance issues
- 2. Use SQL Alerts to monitor data quality
|
| Topic 9: Data Modeling | - Design and optimize data models
- 1. Simplify data layout decisions and optimize query performance using liquid clustering
- 2. Identify the benefits of liquid clustering over partitioning and Z-Ordering
- 3. Design and implement scalable data models using Delta Lake to manage large datasets
- 4. Design dimensional models for analytical workloads with efficient querying and aggregation
|
| Topic 10: Data Ingestion & Acquisition | - Design and implement data ingestion pipelines
- 1. Ingest formats including Delta Lake, Parquet, ORC, AVRO, JSON, CSV, XML, text, and binary data from sources such as message buses and cloud storage
- 2. Create an append-only data pipeline capable of handling both batch and streaming data using Delta
|
>> Certified-Data-Engineer-Professional Valid Guide Files <<
Actual Databricks Certified-Data-Engineer-Professional Exam Questions In Different Formats
Our website focus on helping candidates pass Databricks certification exams with our Valid Certified-Data-Engineer-Professional Practice Questions and detailed test answers. The most reliable Certified-Data-Engineer-Professional dumps pdf are written by our professional IT experts who have rich experience in actual test. And you will be enjoyed one-year free updating after you make payment.
Databricks Certified Data Engineer Professional Sample Questions (Q124-Q129):
NEW QUESTION # 124
The data governance team is reviewing code used for deleting records for compliance with GDPR. They note the following logic is used to delete records from the Delta Lake table named users.
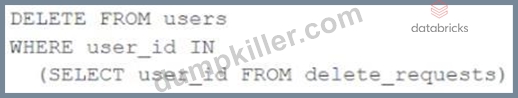
Assuming that user_id is a unique identifying key and that delete_requests contains all users that have requested deletion, which statement describes whether successfully executing the above logic guarantees that the records to be deleted are no longer accessible and why?
- A. No; the Delta Lake delete command only provides ACID guarantees when combined with the merge into command.
- B. Yes; the Delta cache immediately updates to reflect the latest data files recorded to disk.
- C. Yes; Delta Lake ACID guarantees provide assurance that the delete command succeeded fully and permanently purged these records.
- D. No; the Delta cache may return records from previous versions of the table until the cluster is restarted.
- E. No; files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files.
Answer: E
Explanation:
The code uses the DELETE FROM command to delete records from the users table that match a condition based on a join with another table called delete_requests, which contains all users that have requested deletion. The DELETE FROM command deletes records from a Delta Lake table by creating a new version of the table that does not contain the deleted records. However, this does not guarantee that the records to be deleted are no longer accessible, because Delta Lake supports time travel, which allows querying previous versions of the table using a timestamp or version number. Therefore, files containing deleted records may still be accessible with time travel until a vacuum command is used to remove invalidated data files from physical storage.
NEW QUESTION # 125
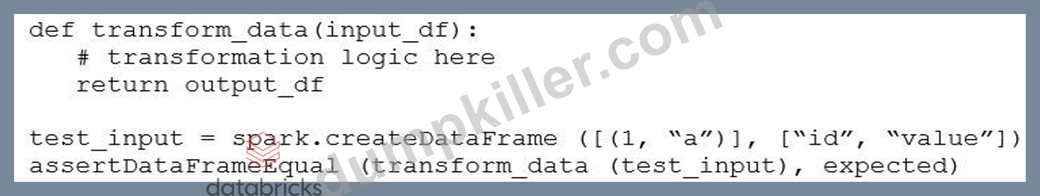
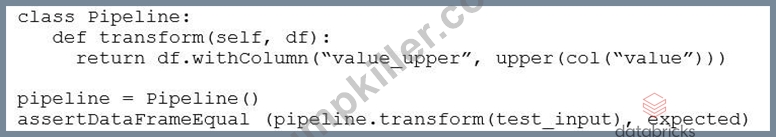
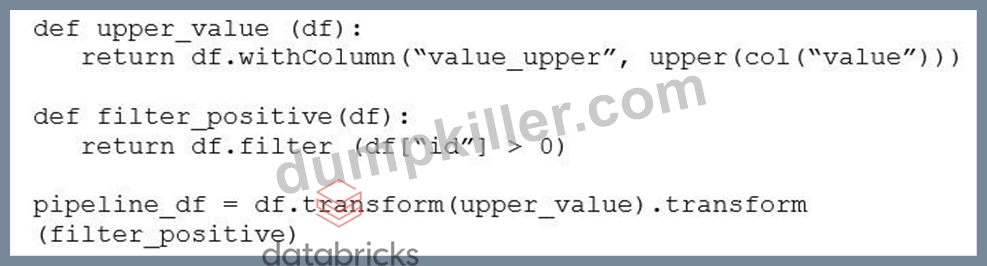
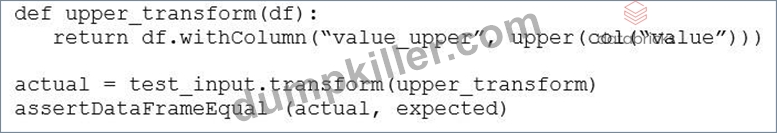
Which approach demonstrates a modular and testable way to use DataFrame transform for ETL code in PySpark?
Answer: D
Explanation:
Using DataFrame.transform with a pure transformation function promotes modular, reusable, and easily testable ETL logic. Each transformation is encapsulated as a standalone function, can be independently unit tested, and composed cleanly in a pipeline without coupling to orchestration or class state.
NEW QUESTION # 126
A Delta table of weather records is partitioned by date and has the below schema:
date DATE, device_id INT, temp FLOAT, latitude FLOAT, longitude FLOAT
To find all the records from within the Arctic Circle, you execute a query with the below filter:
latitude > 66.3
Which statement describes how the Delta engine identifies which files to load?
- A. All records are cached to attached storage and then the filter is applied
- B. The Delta log is scanned for min and max statistics for the latitude column
- C. The Hive metastore is scanned for min and max statistics for the latitude column
- D. The Parquet file footers are scanned for min and max statistics for the latitude column
- E. All records are cached to an operational database and then the filter is applied
Answer: B
Explanation:
This is the correct answer because Delta Lake uses a transaction log to store metadata about each table, including min and max statistics for each column in each data file. The Delta engine can use this information to quickly identify which files to load based on a filter condition, without scanning the entire table or the file footers. This is called data skipping and it can improve query performance significantly. Verified Reference: [Databricks Certified Data Engineer Professional], under "Delta Lake" section; [Databricks Documentation], under "Optimizations - Data Skipping" section.
In the Transaction log, Delta Lake captures statistics for each data file of the table. These statistics indicate per file:
- Total number of records
- Minimum value in each column of the first 32 columns of the table
- Maximum value in each column of the first 32 columns of the table
- Null value counts for in each column of the first 32 columns of the table When a query with a selective filter is executed against the table, the query optimizer uses these statistics to generate the query result. it leverages them to identify data files that may contain records matching the conditional filter.
For the SELECT query in the question, The transaction log is scanned for min and max statistics for the price column.
NEW QUESTION # 127
A data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs. A DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens.
Which statement describes the contents of the workspace audit logs concerning these events?
- A. Because the REST API was used for job creation and triggering runs, user identity will not be captured in the audit logs.
- B. Because User B last configured the jobs, their identity will be associated with both the job creation events and the job run events.
- C. Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events.
- D. Because the REST API was used for job creation and triggering runs, a Service Principal will be automatically used to identity these events.
- E. Because User A created the jobs, their identity will be associated with both the job creation events and the job run events.
Answer: C
Explanation:
The events are that a data engineer, User A, has promoted a new pipeline to production by using the REST API to programmatically create several jobs, and a DevOps engineer, User B, has configured an external orchestration tool to trigger job runs through the REST API. Both users authorized the REST API calls using their personal access tokens. The workspace audit logs are logs that record user activities in a Databricks workspace, such as creating, updating, or deleting objects like clusters, jobs, notebooks, or tables. The workspace audit logs also capture the identity of the user who performed each activity, as well as the time and details of the activity.
Because these events are managed separately, User A will have their identity associated with the job creation events and User B will have their identity associated with the job run events in the workspace audit logs.
NEW QUESTION # 128
Which statement describes the correct use of pyspark.sql.functions.broadcast?
- A. It caches a copy of the indicated table on all nodes in the cluster for use in all future queries during the cluster lifetime.
- B. It marks a DataFrame as small enough to store in memory on all executors, allowing a broadcast join.
- C. It caches a copy of the indicated table on attached storage volumes for all active clusters within a Databricks workspace.
- D. It marks a column as small enough to store in memory on all executors, allowing a broadcast join.
- E. It marks a column as having low enough cardinality to properly map distinct values to available partitions, allowing a broadcast join.
Answer: B
Explanation:
https://spark.apache.org/docs/3.1.3/api/python/reference/api/pyspark.sql.functions.broadcast.html The broadcast function in PySpark is used in the context of joins. When you mark a DataFrame with broadcast, Spark tries to send this DataFrame to all worker nodes so that it can be joined with another DataFrame without shuffling the larger DataFrame across the nodes. This is particularly beneficial when the DataFrame is small enough to fit into the memory of each node. It helps to optimize the join process by reducing the amount of data that needs to be shuffled across the cluster, which can be a very expensive operation in terms of computation and time.
The pyspark.sql.functions.broadcast function in PySpark is used to hint to Spark that a DataFrame is small enough to be broadcast to all worker nodes in the cluster. When this hint is applied, Spark can perform a broadcast join, where the smaller DataFrame is sent to each executor only once and joined with the larger DataFrame on each executor. This can significantly reduce the amount of data shuffled across the network and can improve the performance of the join operation. In a broadcast join, the entire smaller DataFrame is sent to each executor, not just a specific column or a cached version on attached storage. This function is particularly useful when one of the DataFrames in a join operation is much smaller than the other, and can fit comfortably in the memory of each executor node.
NEW QUESTION # 129
......
Our Certified-Data-Engineer-Professional training prep was produced by many experts, and the content was very rich. At the same time, the experts constantly updated the contents of the Certified-Data-Engineer-Professional study materials according to the changes in the society. The content of our Certified-Data-Engineer-Professional learning guide is definitely the most abundant. Before you go to the exam, our Certified-Data-Engineer-Professional exam questions can provide you with the simulating exam environment.
Certified-Data-Engineer-Professional Reliable Exam Tutorial: https://www.dumpkiller.com/Certified-Data-Engineer-Professional_braindumps.html
- Certified-Data-Engineer-Professional Hot Spot Questions ⬆ Free Certified-Data-Engineer-Professional Updates ↔ Free Certified-Data-Engineer-Professional Updates 🍯 Open website 《 www.troytecdumps.com 》 and search for ➥ Certified-Data-Engineer-Professional 🡄 for free download 👨Free Certified-Data-Engineer-Professional Updates
- Databricks Certified-Data-Engineer-Professional Exam Questions Updates Are Free For 1 year 🌹 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ⇛ www.pdfvce.com ⇚ ✔Valid Certified-Data-Engineer-Professional Exam Vce
- Pass Guaranteed 2026 Databricks Fantastic Certified-Data-Engineer-Professional Valid Guide Files 💛 Open website ✔ www.verifieddumps.com ️✔️ and search for ➤ Certified-Data-Engineer-Professional ⮘ for free download 🍔Certified-Data-Engineer-Professional PDF Cram Exam
- Reliable Certified-Data-Engineer-Professional Exam Book 🐙 Valid Braindumps Certified-Data-Engineer-Professional Sheet 🔲 Reliable Certified-Data-Engineer-Professional Exam Book 🧩 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and obtain a free download on 【 www.pdfvce.com 】 ⛽Valid Braindumps Certified-Data-Engineer-Professional Sheet
- 2026 100% Free Certified-Data-Engineer-Professional –High Pass-Rate 100% Free Valid Guide Files | Certified-Data-Engineer-Professional Reliable Exam Tutorial 🐡 Open 【 www.prep4sures.top 】 enter ⮆ Certified-Data-Engineer-Professional ⮄ and obtain a free download 🗓Certified-Data-Engineer-Professional Official Cert Guide
- Reliable Certified-Data-Engineer-Professional Exam Tutorial 🤚 Reliable Certified-Data-Engineer-Professional Exam Book 🦅 Certified-Data-Engineer-Professional Official Cert Guide 🦟 Search for ☀ Certified-Data-Engineer-Professional ️☀️ and easily obtain a free download on ▷ www.pdfvce.com ◁ 🦖Reliable Certified-Data-Engineer-Professional Exam Book
- Exam Certified-Data-Engineer-Professional Simulator Fee 📷 Certified-Data-Engineer-Professional Hot Spot Questions 🏖 Certified-Data-Engineer-Professional Latest Braindumps Ppt 🚕 Open 【 www.exam4labs.com 】 and search for ⇛ Certified-Data-Engineer-Professional ⇚ to download exam materials for free 🦝Certified-Data-Engineer-Professional Official Cert Guide
- Fantastic Certified-Data-Engineer-Professional Valid Guide Files by Pdfvce 🤙 ▶ www.pdfvce.com ◀ is best website to obtain ➤ Certified-Data-Engineer-Professional ⮘ for free download 🍷Certified-Data-Engineer-Professional Test Dumps Demo
- Databricks Certified-Data-Engineer-Professional Exam Questions Updates Are Free For 1 year 🦢 Go to website ⇛ www.troytecdumps.com ⇚ open and search for ➥ Certified-Data-Engineer-Professional 🡄 to download for free 🐧Certified-Data-Engineer-Professional PDF Cram Exam
- 2026 100% Free Certified-Data-Engineer-Professional –High Pass-Rate 100% Free Valid Guide Files | Certified-Data-Engineer-Professional Reliable Exam Tutorial ▛ The page for free download of 「 Certified-Data-Engineer-Professional 」 on ( www.pdfvce.com ) will open immediately 🌑Trustworthy Certified-Data-Engineer-Professional Exam Content
- Reliable Certified-Data-Engineer-Professional Test Syllabus ❔ Certified-Data-Engineer-Professional Practice Exams Free 🍅 Certified-Data-Engineer-Professional Official Cert Guide 🛬 Simply search for ➥ Certified-Data-Engineer-Professional 🡄 for free download on ▛ www.troytecdumps.com ▟ 📫Reliable Certified-Data-Engineer-Professional Exam Book
- www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, www.stes.tyc.edu.tw, Disposable vapes